 :::note TL;DR
- There are three main methods to query blockchain data: running your own node, using an RPC provider, or using a blockchain indexer.
- Self-hosted nodes offer full control but carry significant hardware, maintenance, and engineering costs.
- RPC providers handle infrastructure but are slow and request-heavy for complex or multichain queries.
- Blockchain indexers like Envio HyperIndex are the standard choice for production dApps, with customisable event handling, multichain support in a single indexer, and sync speeds up to 2000x faster than standard RPC via HyperSync.
:::
Getting data out of a blockchain is harder than it looks. The chain stores everything, but it is designed for sequential writes, not efficient reads. Querying a single balance is a round trip to a node. Querying thousands of events across multiple contracts requires hundreds of round trips, significant processing logic, and a lot of waiting.
Developers building production dApps hit this wall quickly. There are three main approaches: run your own node, use an RPC node provider, or use a blockchain indexer. Each one works. Each one has real trade-offs. The right choice depends on what you are building.
## The three methods at a glance
| | Self-Hosted Node | RPC Provider | Blockchain Indexer |
|---|---|---|---|
| **Infrastructure** | You manage | Provider manages | Provider manages |
| **Complex query speed** | Slow | Slow | Fast |
| **Historical data** | Full (archive node required) | Limited | Full |
| **multichain support** | Manual per chain | Manual per chain | Single indexer, multiple chains |
| **Custom query logic** | Build it yourself | No | Yes (TypeScript / JavaScript) |
| **Cost model** | Hardware and engineering | Per-call or subscription | Free tier and managed plans |
## Method 1: Self-hosting your own node
Hosting a node yourself means running an Ethereum client (or the equivalent for your chain) on your own hardware or a cloud provider. The client downloads, verifies, and propagates blocks across the network and exposes a JSON-RPC interface you can query directly.
Some teams prefer this for full control: custom node configuration, increased security, and system-level optimisations that are not possible on a shared provider.
### Trade-offs
- **Hardware**: A full node requires significant dedicated hardware (RAM, storage, bandwidth) to download, validate, and store transaction data. Scaling to match product usage adds ongoing operational overhead.
- **Engineering time**: Maintaining blockchain nodes involves continuous technical work. For teams with limited resources, this comes at the direct cost of building the core product.
- **Reliability**: When your node is down, your product is down. Users cannot interact with your dApp and will look elsewhere.
> In today's fast-paced Web3 environment, time is of the essence to stand out in a crowded space. With an endless stream of innovative products being released daily, reducing time-to-market is critical to success. - [Sven](https://twitter.com/svenmuller95), BD at Envio.
## Method 2: Using an RPC node provider
RPC node providers manage all the infrastructure and expose an endpoint your application calls to request blockchain data. Node setup and maintenance is handled by the provider, not your team.
Endpoints come in two types:
- **Public RPC endpoints**: Shared, rate-limited APIs, free to use. Suitable for development and testing, not for production.
- **Private RPC endpoints**: Dedicated APIs with consistent performance and explicit SLAs, used for production applications.
### Trade-offs
Private RPC endpoints solve the reliability and scalability problems, but fall short on everything else:
| Criteria | Self-Hosted Node | RPC Provider | Blockchain Indexer |
|---|---|---|---|
| Speed (complex queries) | Slow | Slow | Fast |
| Reliability | You manage | Provider SLA | Provider SLA |
| Scalability | Manual | Yes | Yes |
| Customisability | Yes (build it yourself) | No | Yes |
| multichain aggregation | No | No | Yes |
| Full historical data | Yes (archive node required) | No | Yes |
RPC nodes are request-heavy by design. If a user holds one hundred tokens, reading their balances requires one hundred requests. More complex queries (aggregations, historical ranges, cross-contract data) multiply this further. Applications built entirely on RPC calls are slow to respond, expensive at scale, and difficult to maintain.
Public RPC endpoints also rarely include full transaction history, so getting a complete historical dataset requires additional workarounds and infrastructure.
## Method 3: Using a blockchain indexer (recommended for most dApps)
Most production blockchain applications use some form of indexing. In practice, developers should only call an RPC node directly when absolutely necessary (for example, to deploy a smart contract). For reading and querying data, a blockchain indexer is almost always the better approach.
A blockchain indexer is a backend that continuously reads onchain data, organises it into structured tables, and exposes it via a queryable API such as GraphQL. Indexing frameworks like [Envio HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) abstract the complexity of infrastructure management, letting developers define what data to index and how to store it, while the indexer handles the rest.
Envio HyperIndex is powered by [HyperSync](https://docs.envio.dev/docs/HyperSync/overview), a purpose-built data engine that delivers up to 2000x faster sync speeds than traditional RPC endpoints. Rather than making one request per block or event, HyperSync batches and optimises data retrieval, reducing historical syncs from days to minutes.
HyperIndex also supports multichain indexing from a single indexer instance. Define all your networks in one config file and query everything through a single GraphQL endpoint, with no separate deployments per chain.
### Trade-offs
- **Customisability**: Some indexing solutions offer pre-built plug-and-play APIs (NFT API, Token API, Balance API). Others, like Envio HyperIndex, are fully customisable frameworks where you define your own schema and event handling logic for any smart contract on any supported chain.
- **Centralisation**: Teams looking to fully decentralise their stack beyond smart contracts may want to evaluate decentralised indexing networks. Centralised managed indexers like Envio Cloud use production-grade cloud infrastructure with redundancy and no single point of failure.
## Which method should you use?
Self-hosted nodes give you the most control but require significant ongoing investment in hardware and engineering. RPC providers reduce infrastructure burden but are not designed for complex queries or historical data at scale. Blockchain indexers address all of these gaps and are the standard approach for production dApps.
For most teams building on EVM chains, Envio HyperIndex is the fastest path from onchain events to a queryable API. Get started in under 5 minutes:
```bash
pnpx envio init
```
## Frequently asked questions
### What is the most efficient way to query blockchain data?
For production dApps and data pipelines, a blockchain indexer is the most efficient method. Rather than making individual RPC calls for every piece of data, an indexer processes events in bulk, applies custom logic, and serves the result via a fast API. Envio HyperIndex, powered by HyperSync, syncs historical data up to 2000x faster than standard RPC endpoints.
### What is the difference between an RPC node and a blockchain indexer?
An RPC node is the base-level interface to a blockchain. It answers individual data requests but requires many round trips for complex queries and cannot aggregate or filter data efficiently. A blockchain indexer sits above this layer, processing events in bulk, transforming them into a structured database, and exposing the result via a GraphQL API. For most dApp backends, an indexer replaces direct RPC calls almost entirely.
### Where does HyperSync fit in the comparison of blockchain query methods?
HyperSync is a high-performance data engine that sits underneath the indexer method described above. While self-hosted nodes and RPC providers expose data via JSON-RPC, HyperSync exposes a purpose-built data API that powers HyperIndex and can also be queried directly via client libraries in Python, Rust, Node.js, and Go. For applications that need historical sync at production speed, HyperSync delivers up to 2000x faster data retrieval than standard RPC.
### Can I query data from multiple blockchains in a single indexer?
Yes. Envio HyperIndex supports multichain indexing from a single indexer instance. You define all your networks in one config file and query everything through a single GraphQL endpoint, rather than deploying and maintaining separate API instances per chain.
### Is a blockchain indexer free to use?
Envio offers free options for local development. For production deployments, Envio Cloud provides managed hosting with guaranteed uptime across multiple plan tiers. HyperIndex can also be self-hosted via Docker for full infrastructure control. See the [Envio Cloud docs](https://docs.envio.dev/docs/HyperIndex/hosted-service) for details.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Blockchain Indexing Challenges and How to Solve Them
> The most common blockchain indexing challenges explained: slow syncs, chain reorgs, multichain complexity, and how Envio HyperIndex solves each one.
 :::note TL;DR
- Slow sync speeds, chain reorgs, multichain complexity, and poor error visibility are the most common blockchain indexing challenges in production.
- Envio HyperIndex addresses all of them: HyperSync delivers up to 2000x faster sync than RPC, reorg handling is built-in and enabled by default, and multichain indexing runs from a single config file.
- Most issues developers hit during indexing have well-defined fixes. Knowing what to look for saves hours of debugging.
:::
Blockchains produce data continuously, but that data is not designed to be queried. It is written sequentially, scattered across millions of blocks, and retrieving it at any scale requires infrastructure that most development teams did not sign up to build themselves.
This article covers the most common challenges developers face when building and maintaining blockchain indexers, and how Envio HyperIndex is built to handle each one.
## Challenge 1: Slow sync speeds
Getting a full historical sync of a contract can take hours or days when indexing via standard RPC endpoints. RPC nodes process requests individually, which means syncing millions of events requires millions of round trips. Any rate limiting from the RPC provider makes this worse.
This is one of the most frustrating bottlenecks in blockchain development. Slow syncs extend development cycles, delay production deployments, and make iteration painful.
### How Envio solves it
HyperIndex is powered by [HyperSync](https://docs.envio.dev/docs/HyperSync/overview), a purpose-built data engine that replaces standard RPC for data retrieval. HyperSync batches requests at a much lower level than JSON-RPC allows, delivering up to 2000x faster sync speeds. Historical syncs that take days via RPC take minutes with HyperSync.
HyperSync is the default data source for all supported networks and requires no extra configuration. Setting `start_block: 0` in your config is enough. HyperSync automatically detects your contract's deployment block and begins from there.
## Challenge 2: Chain reorganizations
A chain reorganization (reorg) happens when the blockchain temporarily forks and then resolves to a single canonical chain. Blocks that were previously considered confirmed get replaced, and any data indexed from those blocks becomes invalid.
For indexers, this means previously stored records may need to be rolled back and reprocessed. Ignore reorgs and your indexed data will drift from the chain's actual state, silently corrupting your application.
### How Envio solves it
HyperIndex has built-in reorg support, enabled by default. When a reorg is detected, the indexer automatically rolls back all affected database records and reprocesses the correct blocks. No manual intervention is needed.
You can configure reorg handling in `config.yaml`:
```yaml
rollback_on_reorg: true
networks:
- id: 1 # Ethereum Mainnet
confirmed_block_threshold: 250
- id: 137 # Polygon
confirmed_block_threshold: 150
```
The `confirmed_block_threshold` controls how many blocks below the chain head are considered safe from reorgs. The default is 200 blocks across all networks. Reorg detection is guaranteed when using HyperSync as your data source. For a deeper look at how reorgs work and how HyperIndex handles them, see our blog [Indexing and Reorgs](https://docs.envio.dev/blog/indexing-and-reorgs).
## Challenge 3: multichain data aggregation
Teams deploying dApps across multiple networks face a compounding infrastructure problem. Each chain needs its own indexer, its own database, and its own API. Keeping these in sync, aggregating data across them, and presenting a unified view to your frontend is a significant ongoing maintenance burden.
### How Envio solves it
HyperIndex supports multichain indexing from a single indexer instance. All networks are defined in one `config.yaml` file and all indexed data is queryable through a single GraphQL endpoint. No separate deployments, no separate databases, no cross-service joins.
```yaml
networks:
- id: 1 # Ethereum
start_block: 0
contracts:
- name: MyContract
address: "0xabc..."
handler: ./src/EventHandlers.ts
events:
- event: Transfer
- id: 8453 # Base
start_block: 0
contracts:
- name: MyContract
address: "0xdef..."
handler: ./src/EventHandlers.ts
events:
- event: Transfer
```
HyperSync natively supports
 :::note TL;DR
- Building a blockchain dApp requires three layers. A frontend for the UI, smart contracts for onchain logic, and a data layer for reading events efficiently.
- The core stack is Solidity for smart contracts, TypeScript for frontends and event handlers, and Hardhat or Foundry for testing and deployment.
- Envio HyperIndex handles the data layer. Index any smart contract's events, query results via GraphQL, and get started in under 5 minutes with `pnpx envio init`.
:::
This guide covers the key concepts and tools needed to start building blockchain applications. It walks through the full stack from smart contracts to frontend to data layer, with practical tool recommendations at each step.
## What is a Decentralized Application (dApp)?
A decentralized application, or dApp, combines a frontend user interface with smart contracts running on a blockchain. Unlike a traditional web app where the backend runs on servers controlled by a single company, a dApp's core logic lives on a decentralised network that no single party controls.
Popular examples include [Uniswap](https://uniswap.org/), a decentralized exchange deployed across many EVM chains, [Aave](https://aave.com/), a borrowing and lending protocol, and [OpenSea](https://opensea.io/), an NFT marketplace.
### What is a Smart Contract?
Smart contracts are self-executing programs that run on a blockchain. They enforce rules and conditions in code, without relying on an intermediary. Once deployed, they run exactly as written on every node in the network.
This is the fundamental difference between a dApp and a traditional app. There is no server to take down, no database to tamper with, and no central authority that can change the rules after the fact.
### What is a Frontend?
The frontend of a dApp looks like any other web application. The key difference is that instead of calling a backend API, it communicates with smart contracts on the blockchain via a wallet and an RPC node.
### How the Frontend Connects to the Blockchain
Frontends talk to smart contracts through a node. Blockchain networks are made up of nodes that all run the same software and store a copy of the full chain state, including every deployed contract. On Ethereum and EVM-compatible chains, this is the Ethereum Virtual Machine (EVM).
Rather than running your own node, most teams connect via an RPC provider like [Infura](https://www.infura.io/) or [Alchemy](https://www.alchemy.com/). These expose a standard JSON-RPC interface your frontend can call to read contract data or submit signed transactions.
To write to the chain, users sign transactions with a private key held in their wallet. The wallet handles signing and submits the transaction to the network.
## Programming Languages
Three languages come up most often in blockchain development.
### TypeScript
TypeScript is the primary language for building dApps. It is used for frontend development, for interacting with smart contracts via libraries like ethers.js, and for writing event handler logic in indexers like Envio HyperIndex. If you are coming from a web development background, TypeScript is where to start.
### Solidity
Solidity is the standard language for writing smart contracts on Ethereum and EVM-compatible chains. It is statically typed and compiled, and it runs inside the EVM. Most smart contract tooling, documentation, and community knowledge is built around Solidity.
### Rust
Rust is used in blockchain infrastructure rather than dApp development directly. It powers non-EVM chains like Solana and Polkadot, and is used in high-performance tooling like [Foundry](https://github.com/foundry-rs/foundry). Envio uses Rust for its CLI for the same reason. It is not a priority for most EVM dApp developers starting out.
## Building a dApp
A dApp is built across three layers. Smart contracts handle onchain logic, a frontend handles the UI, and a data layer reads onchain events. Here is what each involves.
### Setting up your development environment
Before building, you need the right tools in place:
- **IDE**: [VS Code](https://code.visualstudio.com/) works well for blockchain development and has extensions for Solidity, Hardhat, and TypeScript.
- **Node.js**: [Node.js](https://nodejs.org/en/download/current) is required to run development tools and local servers.
- **Smart contract framework**: [Hardhat](https://hardhat.org/) and [Foundry](https://book.getfoundry.sh/) both handle compiling, testing, deploying, and debugging smart contracts. Hardhat is TypeScript-native. Foundry is Rust-based and faster for test-heavy workflows.
- **Local network**: [Hardhat Network](https://hardhat.org/hardhat-network/docs/overview) and Foundry's [Anvil](https://github.com/foundry-rs/foundry/tree/master/crates/anvil) both provide a local blockchain for testing without spending real gas.
### Writing, deploying, and testing smart contracts
Smart contracts are written in Solidity and deployed to the blockchain. Once deployed, they are live and immutable. Thorough testing before deployment is critical. If your contracts handle user funds, a third-party security audit is strongly recommended.
### Interfacing with smart contracts
Frontend code communicates with smart contracts via [ethers.js](https://docs.ethers.org/v5/) or [web3.js](https://web3js.readthedocs.io/en/v1.10.0/#). These libraries send JSON-RPC requests to an Ethereum node, allowing your frontend to read contract state and submit transactions.
### Transactions and wallet integration
To sign and submit transactions, users need a wallet. Integrating [MetaMask](https://metamask.io/) or [Rabby](https://rabby.io/) into your frontend is the standard approach. The wallet holds the user's private key and handles signing without exposing it to your application.
### Security and best practices
Smart contracts cannot be updated once deployed, so security has to be right before launch. Common practices include peer code review, automated testing, and a formal audit from a specialist firm, particularly for contracts that hold user funds.
## Reading onchain data with Envio HyperIndex
Querying smart contract data directly via RPC breaks down quickly. Reading one user's token balance is one request. Reading balances for a thousand users, or the full history of a contract, means thousands of round trips to a node. RPC endpoints are rate-limited, return raw block data, and have no support for aggregations or complex queries.
A blockchain indexer solves this. It listens to events emitted by your smart contracts, processes them through custom handler logic, and stores the results in a structured database. Your frontend queries that database via a fast GraphQL API instead of hammering an RPC node.
[Envio HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) is built for this. It is powered by HyperSync, a data engine that delivers up to 2000x faster historical sync than standard RPC endpoints. You define your schema and event handlers. HyperIndex manages ingestion, storage, and the API layer.
Key features:
- **Auto-generation**: Run `pnpx envio init` and point it at any deployed contract address. HyperIndex generates the config, schema, and handler stubs automatically
- **HyperSync**: Delivers up to 2000x faster historical sync than standard RPC endpoints
- **TypeScript handlers**: Write event logic in the same language as your frontend
- **Multichain**: Index multiple networks in one indexer and query everything through one GraphQL endpoint
- **Managed hosting**: Deploy to [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service) for production, or self-host via Docker
Get started in under 5 minutes:
```bash
pnpx envio init
```
For a deeper look at how blockchain indexers work, see [What is a Blockchain Indexer?](https://docs.envio.dev/blog/what-is-a-blockchain-indexer).
## Frequently asked questions
### What programming language should I learn first for blockchain development?
TypeScript is the most practical starting point. It covers frontend development, smart contract interactions via ethers.js, and event handler logic for indexers like Envio HyperIndex. Solidity is essential for writing smart contracts. Learning both covers the full dApp stack.
### What is the difference between a dApp and a traditional web app?
A traditional web app stores data on servers controlled by a single company. A dApp stores its core logic and state in smart contracts on a decentralised blockchain, so no single party can alter or censor it. The frontend looks similar to a standard web app but connects to the blockchain via a wallet and RPC provider rather than a standard API.
### What tools do blockchain developers use?
The most common tools are Hardhat or Foundry for smart contract development and testing, ethers.js for frontend-to-blockchain communication, MetaMask for wallet integration, and a blockchain indexer like Envio HyperIndex for querying onchain data efficiently. Most teams also use an RPC provider like Infura or Alchemy for node access.
### How do I read and query data from my smart contract?
Use a blockchain indexer. An indexer listens to the events emitted by your smart contract, stores them in a structured database, and exposes the data via a GraphQL API. This is far more efficient than querying an RPC node directly for anything beyond simple reads. Envio HyperIndex gets you from contract address to running indexer in under 5 minutes with `pnpx envio init`.
### How long does it take to become a blockchain developer?
It depends on your background. Developers with TypeScript experience can typically build and deploy a basic dApp within a few weeks. Getting comfortable with Solidity, security best practices, and production-grade data infrastructure takes several months. The fastest path is to build something real. Pick a protocol you use, try to index its events with HyperIndex, and work outward from there.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Benchmarking Blockchain Indexer Sync Speeds
> Benchmarking results comparing Envio against Subsquid, The Graph, Ponder, and Substreams across 5 million events on the Uniswap V3 ETH-USDC pool.
 :::note TL;DR
- Envio ranked fastest across 6 indexing solutions tested on the Uniswap V3 ETH-USDC pool on Ethereum Mainnet, syncing 5.3 million events in 9.67 minutes.
- The next fastest competitor took 20.5 minutes. The slowest took 1,529 minutes.
- All benchmark code is publicly available. These results reflect Envio v0.0.20. Performance has improved significantly since with HyperSync.
:::
Sync speed is how long it takes an indexer to catch up to the chain head from a historical starting block. It sounds like a narrow metric, but it shapes the entire development loop. Every time you change handler logic, update a schema, or debug an issue on a live contract, you are waiting for a sync before you can see the result. Slow syncs mean slow iteration. Fast syncs mean teams ship faster.
This article presents the findings from benchmarking tests conducted at Envio, comparing six blockchain indexing solutions on a standardised scenario.
## Methodology
To make results as comparable as possible, all indexers were configured identically:
- **Start block:** 12,376,729 (deployment block of the Uniswap V3 ETH-USDC pool)
- **End block:** 18,342,024 (chain head at time of testing)
- **Total events:** approximately 5,395,050 raw events (0.9044 events per block)
- Same schema across all implementations
- Same event handler logic across all implementations
The Uniswap V3 ETH-USDC pool was chosen for its high event density, making it a strong stress test for indexer performance. You can view the contract on [Etherscan](https://etherscan.io/address/0x88e6A0c2dDD26FEEb64F039a2c41296FcB3f5640).
### Schema
```graphql
type Swap {
id: Bytes!
sender: Bytes! # address
recipient: Bytes! # address
amount0: BigInt! # int256
amount1: BigInt! # int256
sqrtPriceX96: BigInt! # uint160
liquidity: BigInt! # uint128
tick: Int! # int24
blockNumber: BigInt!
blockTimestamp: BigInt!
transactionHash: Bytes!
}
```
### Event handler logic
The handler logic was kept lightweight. Each indexer listened for the `Swap` event and appended event details to the `Swap` entity table. No complex joins or derived fields.
## Indexers Tested
Six indexing solutions were included:
- [Envio](https://envio.dev/) v0.0.20
- [Envio](https://envio.dev/) v0.0.19
- [Subsquid](https://subsquid.io/)
- Subgraph on [The Graph](https://thegraph.com/) hosted service
- [Ponder](https://ponder.sh/)
- [Substreams-powered Subgraph](https://thegraph.com/docs/en/cookbook/substreams-powered-subgraphs/) on The Graph hosted service
### Benchmark repositories
All implementations are publicly available for review and reproduction:
- Envio: [uniV3-swaps](https://github.com/enviodev/uniV3-swaps)
- Ponder: [univ3-ponder](https://github.com/enviodev/univ3-ponder)
- Subsquid: [univ3-sqd](https://github.com/enviodev/univ3-sqd)
- Substreams-powered Subgraph: [univ3-substreams](https://github.com/enviodev/univ3-substreams)
## Results
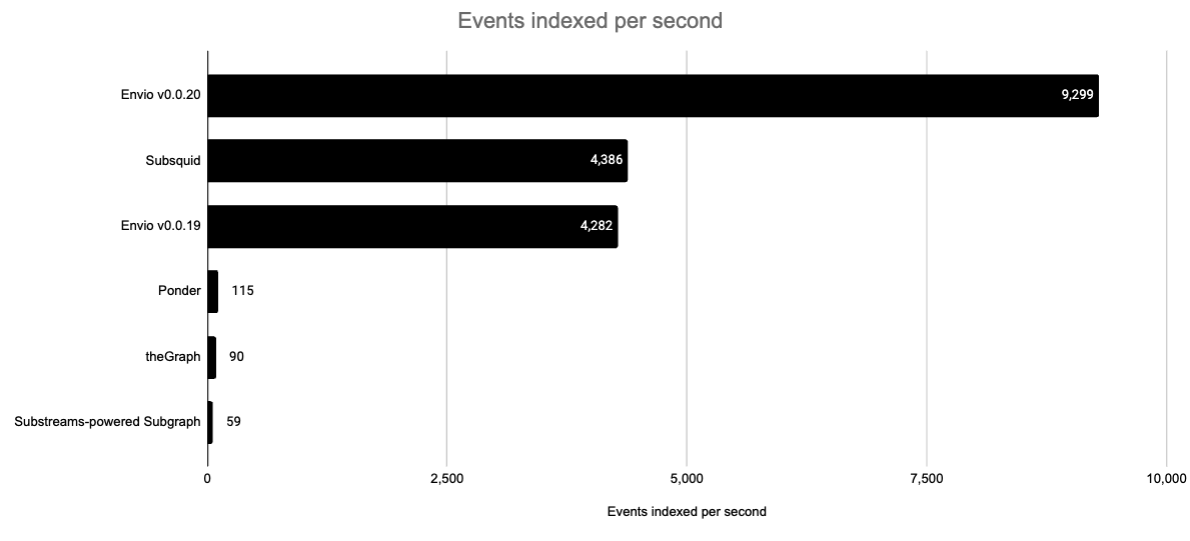 Total sync times in minutes, sorted fastest to slowest:
| Indexer | Total sync time (mins) |
|---|---|
| Envio v0.0.20 | 9.67 |
| Subsquid | 20.50 |
| Envio v0.0.19 | 21.00 |
| Ponder | 780.37 |
| The Graph | 1,000.00 |
| Substreams-powered Subgraph | 1,529.33 |
### Key takeaways
Envio v0.0.20 ranked fastest across all solutions tested:
- 2.12x faster than Subsquid
- 80.6x faster than Ponder
- 103x faster than The Graph
- 157x faster than Substreams-powered Subgraph
> **Disclaimer:** These results are specific to the Uniswap V3 ETH-USDC pool scenario. Relative performance between indexers will vary by use case.
### Caveats
- Envio and Subsquid were run on local machines. Subgraphs were deployed on a hosted service, which introduces potential variance.
- Ponder was deployed on a virtual machine with 4GB RAM and 80GB disk.
- Ponder's sync time was extrapolated from initial indexing progress rather than measured to completion.
## Performance since these benchmarks
These benchmarks reflect Envio v0.0.20 from late 2023. Since then, Envio has shipped [HyperSync](https://docs.envio.dev/docs/HyperSync/overview), a purpose-built data engine that replaces RPC for historical data retrieval entirely. The 2000x faster figure referenced in Envio's documentation refers to HyperSync vs standard RPC endpoints, not this indexer-to-indexer comparison. Real-world sync times with HyperSync are faster than what these numbers show.
The benchmark data and repositories remain public. We encourage the community to run the tests independently and share results.
## Frequently asked questions
### What was being benchmarked?
Sync speed across six blockchain indexing solutions, using the Uniswap V3 ETH-USDC pool on Ethereum Mainnet as the test contract. All indexers used the same schema, start block, end block, and handler logic.
### How does Envio compare to The Graph?
In this benchmark, Envio v0.0.20 synced in 9.67 minutes vs approximately 1,000 minutes for The Graph's hosted subgraph, roughly 103x faster. These results reflect a specific high event-density scenario and the versions available at the time of testing.
### Are these benchmarks still current?
These benchmarks were run on Envio v0.0.20 in late 2023. Performance has improved significantly since with the introduction of HyperSync. Updated benchmarks covering more indexers and scenarios are planned.
### Where can I verify the results?
All benchmark implementations are publicly available on GitHub. Links to each repository are in the [Benchmark repositories](#benchmark-repositories) section above.
### What scenarios will future benchmarks cover?
Planned variations include different numbers of contracts and events, varying event density per block, more complex schema structures, and handler logic that involves loading and updating existing entities.
## Build With Envio
Envio was the fastest EVM blockchain indexer in the 2023 benchmark above, and more recent independent tests run by Sentio in May 2025 show HyperIndex is still the fastest blockchain indexer available ([Sentio benchmark, May 2025](https://github.com/enviodev/open-indexer-benchmark)). If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Dedicated Hosting for Blockchain Indexers
> What dedicated hosting means for blockchain indexer developers, how Envio Cloud handles infrastructure, and why managed hosting reduces development overhead.
 :::note TL;DR
- Running a blockchain indexer in production requires a database, a GraphQL API layer, uptime monitoring, and infrastructure that scales with your data.
- Envio Cloud handles all of this as a managed service, so teams can focus on handler logic rather than infrastructure.
- Self-hosting via Docker is also supported for teams that want full infrastructure control.
:::
Deploying a blockchain indexer locally is straightforward. Keeping one running reliably in production is a different problem. You need a database, a GraphQL API layer, uptime guarantees, and a deployment process that does not require manual intervention every time your handler logic changes.
This article covers what a dedicated hosted indexer service provides, how Envio Cloud works, and how to decide between managed hosting and self-hosting.
## What a Hosted Indexer Service Provides
A hosted indexer service takes your indexer configuration, schema, and handler code and runs the full stack for you. This includes:
- **Database**: Storing indexed events and entity tables
- **GraphQL API**: Auto-generated from your schema via Hasura, queryable by your frontend
- **Uptime**: The service monitors availability and handles restarts automatically
- **Deployment**: Syncing from your repository so new versions deploy without manual steps
Without a hosted service, each of these components needs to be provisioned, maintained, and scaled independently. For teams focused on building a product rather than managing infrastructure, this is significant overhead.
## How Envio Cloud Works
[Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service) is the managed hosting option for HyperIndex. It runs on AWS infrastructure with Kubernetes orchestration and Hasura for the GraphQL layer.
Deployment is integrated with GitHub. An Envio GitHub bot monitors your repository and triggers new deployments when changes land in your specified branch. There is no manual deploy step once the integration is configured.
The stack Envio Cloud manages:
- **AWS**: Cloud infrastructure and compute
- **Kubernetes**: Container orchestration and scaling
- **Hasura**: Real-time GraphQL API generation from your schema
- **HyperSync**: The data engine powering historical sync, up to 2000x faster than standard RPC
For local development, the full stack runs with a single `pnpm dev` command using Docker Desktop. The same handler logic runs locally and in production without modification.
## Managed Hosting vs Self-Hosting
HyperIndex supports both options:
| | Envio Cloud | Self-hosted (Docker) |
|---|---|---|
| Infrastructure setup | Handled by Envio | You manage |
| Uptime monitoring | Included | You manage |
| Deployment | GitHub bot auto-deploy | Manual or custom CI |
| Cost | Free tier and paid plans | Your infrastructure costs |
| Control | Standard configuration | Full control |
For most teams, Envio Cloud is the faster path to production. For teams with specific compliance requirements or existing infrastructure preferences, self-hosting via Docker gives full control without changing any handler code.
## Getting Started
Deploy to Envio Cloud from the [hosted service docs](https://docs.envio.dev/docs/HyperIndex/hosted-service). If you do not have an indexer yet, the contract import quickstart generates a working indexer from any deployed contract address in under 5 minutes:
```bash
pnpx envio init
```
## Frequently asked questions
### What infrastructure does Envio Cloud run on?
Envio Cloud uses AWS for compute, Kubernetes for orchestration, and Hasura for the GraphQL API layer. HyperSync powers historical data retrieval for all supported networks.
### How does deployment work with Envio Cloud?
Envio Cloud integrates with GitHub via a bot that monitors your repository. When changes land in your configured branch, a new deployment is triggered automatically.
### Can I self-host HyperIndex instead of using Envio Cloud?
Yes. HyperIndex can be self-hosted using Docker. The same handler logic and schema work identically in both environments. See the [hosting docs](https://docs.envio.dev/docs/HyperIndex/hosted-service) for setup instructions.
### What is included in the free tier?
See the [Envio Cloud docs](https://docs.envio.dev/docs/HyperIndex/hosted-service) for current plan details and limits.
### Does Envio Cloud support multichain indexers?
Yes. A single HyperIndex instance can index multiple networks and all data is queryable through one GraphQL endpoint, whether hosted on Envio Cloud or self-hosted.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How Envio Simplifies Data Retrieval for Multichain dApps
> How multichain indexing works with Envio HyperIndex, with a practical walkthrough of config, schema, and event handlers for indexing across multiple EVM chains.
 :::note TL;DR
- Deploying a dApp across multiple chains creates a fragmented data problem. Each chain has its own events, its own state, and no native way to query across them together.
- Envio HyperIndex solves this with a single indexer instance that reads events from multiple networks and exposes everything through one GraphQL endpoint.
- Configuration is a single `config.yaml` file. No separate deployments, no cross-service data joins.
:::
The multichain future is already here. Protocols like [Uniswap](https://app.uniswap.org/), [Aave](https://aave.com/), and [Compound](https://compound.finance/) are deployed across Ethereum, Arbitrum, Optimism, Base, Polygon, and more. Reaching users on multiple chains means accepting the data fragmentation that comes with it.
For developers, this fragmentation is a real infrastructure problem. Traditional indexing approaches require a separate indexer and database per chain. Aggregating that data in your frontend means either stitching together multiple API calls or building additional backend logic to consolidate it. Both approaches add complexity and maintenance overhead.
## The Multichain Data Problem
When a dApp is deployed across multiple chains, every interaction that matters (swaps, transfers, liquidations, mints) is emitted as an event on each respective chain. There is no native cross-chain view of this data.
The conventional approach requires:
- One indexer deployment per chain
- One database per chain
- Custom aggregation logic in the frontend or a separate backend layer
This compounds quickly. A protocol on five chains needs five indexer deployments to maintain, five databases to keep in sync, and aggregation logic that breaks every time a new chain is added.
## Multichain Indexing with Envio HyperIndex
[Envio HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) handles multichain indexing from a single indexer instance. All networks are defined in one `config.yaml`. All indexed data lands in one database. Everything is queryable through one GraphQL endpoint.
Other indexers require a separate subgraph or pipeline per chain. With Envio, adding a new chain is a config change, not a new deployment.
## Example: Greeter Contract on Polygon and Linea
The following example walks through a multichain Greeter indexer that listens for `NewGreeting` events from contracts deployed on both Polygon and Linea.
### config.yaml
```yaml
name: Greeter
description: Greeter indexer
networks:
- id: 137 # Polygon
start_block: 45336336
contracts:
- name: Greeter
abi_file_path: ./abis/greeter-abi.json
handler: ./src/EventHandlers.ts
events:
- event: NewGreeting
- id: 59144 # Linea
start_block: 367801
contracts:
- name: Greeter
abi_file_path: ./abis/greeter-abi.json
handler: ./src/EventHandlers.ts
events:
- event: NewGreeting
```
Both networks share the same handler and ABI. Adding a third chain means adding another network block. The handler logic stays unchanged.
### schema.graphql
```graphql
type User {
id: ID!
greetings: [String!]!
latestGreeting: String!
numberOfGreetings: Int!
}
```
### Event handler
A single TypeScript handler processes `NewGreeting` events from both chains:
```typescript
import { Greeter } from "generated";
Greeter.NewGreeting.handler(async ({ event, context }) => {
const currentUser = await context.User.get(event.params.user.toString());
context.User.set({
id: event.params.user.toString(),
latestGreeting: event.params.greeting,
numberOfGreetings: (currentUser?.numberOfGreetings ?? 0) + 1,
greetings: [...(currentUser?.greetings ?? []), event.params.greeting],
});
});
```
The handler runs identically for events from any network in the config. Chain-specific context (like `event.chainId`) is available if you need it for cross-chain logic.
For the full multichain indexing documentation, see the [Envio docs](https://docs.envio.dev/docs/HyperIndex/multichain-indexing). For a more complex multichain example, see the [Uniswap V4 Multichain Indexer](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer).
## Frequently asked questions
### How does Envio handle events from multiple chains in one indexer?
All networks are defined in a single `config.yaml`. HyperIndex processes events from each network in parallel and writes them to a shared database. Your GraphQL API reflects the combined state of all indexed chains.
### Do I need separate deployments for each chain?
No. A single HyperIndex instance handles all configured networks. One deployment, one database, one GraphQL endpoint.
### Can the same handler logic run across different chains?
Yes. A single handler function processes matching events from all networks in your config. If you need to apply chain-specific logic, `event.chainId` is available in the handler context.
### How many chains does Envio support?
HyperSync natively supports
 :::note TL;DR
- LUKSO developers need fast, reliable access to real-time and historical onchain data for dApps built on the EVM-compatible LUKSO network.
- Envio HyperIndex supports LUKSO with HyperSync-powered sync speeds up to 2000x faster than standard RPC, plus a no-code contract import quickstart.
- A single config.yaml covers all chains, giving Envio a structural advantage over The Graph and Goldsky, which require separate subgraphs or pipelines per network.
:::
Envio HyperIndex fully supports developers and analysts building on LUKSO. It provides hyper-performant query speeds and a robust solution to efficiently organize and query real-time and historical onchain data for dApps and data-driven use cases on LUKSO.
## How to index data on LUKSO using Envio
[Envio](https://envio.dev/) is a dev-friendly EVM-compatible blockchain indexing solution that lets developers reliably read and process real-time and historical smart contract events through a [GraphQL](https://graphql.org/) API.
Envio supports indexing on LUKSO and any EVM-compatible blockchain, enabling developers to:
- **Flexible language support**: Configure your event handling in JavaScript, TypeScript, or ReScript.
- **Contract import**: Autogenerate a basic indexer and queryable GraphQL API for a single or multiple smart contracts in less than 5 minutes.
- **HyperSync**: Envio's proprietary data layer delivers up to 2000x faster indexing than standard RPC for historical onchain data.
- **Multichain indexing**: Aggregate data from multiple networks into a single database with a unified GraphQL API.
- **Join onchain and off-chain data**: Connect indexed blockchain data with external sources to create a flexible API for rich data beyond onchain events.
## What Envio supports on LUKSO
Envio HyperIndex equips LUKSO developers with a feature-rich data indexing framework that goes beyond what traditional indexing solutions offer. Envio serves as the data access layer for developers, analysts, and applications built on LUKSO to access, transform, and store real-time or historical data from any EVM-compatible smart contracts.
Envio supports various EVM blockchains, including Polygon, Avalanche, Linea, Arbitrum, Base, ZkSync, and LUKSO. This enables developers building on LUKSO to sync millions of events in minutes instead of hours. Compared to alternatives like The Graph (which requires a separate subgraph per chain) or Goldsky (which requires separate pipelines), Envio uses a single `config.yaml` to cover all chains and exposes a single GraphQL endpoint.
### Getting started
Initialize a new indexer with:
```bash
pnpx envio init
```
A minimal `config.yaml` for a LUKSO contract looks like:
```yaml
name: LuksoIndexer
networks:
- id: 42
start_block: 0
contracts:
- name: MyContract
abi_file_path: ./abis/my-contract-abi.json
handler: ./src/EventHandlers.ts
events:
- event: Transfer
```
And a basic event handler in TypeScript:
```typescript
import { MyContract } from "generated";
MyContract.Transfer.handler(async ({ event, context }) => {
context.Transfer.set({
id: event.transaction.hash,
from: event.params.from,
to: event.params.to,
value: event.params.value,
});
});
```
## Relevant links
- [Envio Quickstart](https://docs.envio.dev/docs/HyperIndex/getting-started)
- [Envio HyperSync](https://docs.envio.dev/docs/HyperSync/overview)
- [Contract Import](https://docs.envio.dev/docs/HyperIndex/contract-import)
- [Envio Hosted Service](https://docs.envio.dev/docs/HyperIndex/hosted-service)
- [LUKSO Docs](https://docs.lukso.tech/)
## About LUKSO
[LUKSO](https://lukso.network/) is a Layer 1 blockchain network built using the Ethereum EVM stack and is compatible with any other EVM-based blockchain, including other platforms or protocols built on Ethereum.
LUKSO is dedicated to digital lifestyles and creative use cases, revolutionizing how people interact with blockchain technology. The heart of LUKSO's innovation is the Universal Profile (UP) system: next-generation smart contract accounts designed to streamline and humanize blockchain interactions.
[Website](https://lukso.network/) | [X](https://twitter.com/lukso_io) | [Discord](https://discord.com/invite/lukso)
## Frequently asked questions
### Does Envio support LUKSO mainnet and testnet?
Yes. Envio HyperIndex and HyperSync support LUKSO mainnet. You configure which network to index in your `config.yaml` using the LUKSO chain ID. Testnet support follows the same pattern.
### How fast is Envio HyperSync on LUKSO compared to standard RPC?
HyperSync can deliver up to 2000x faster historical sync than standard RPC endpoints by bypassing the RPC layer entirely and using a purpose-built binary data format. This means syncing millions of events in minutes rather than hours.
### Do I need to manage my own infrastructure to index LUKSO with Envio?
No. Envio's hosted service manages all infrastructure on AWS with Kubernetes and Hasura. You push code to GitHub and the Envio Deployments bot handles deployment automatically. A free tier is available.
### How does Envio compare to The Graph for LUKSO indexing?
The Graph requires you to deploy a separate subgraph for each chain, with separate endpoints per network. Envio uses a single `config.yaml` to define all networks and exposes a single GraphQL endpoint across all of them, simplifying multichain data access significantly.
### Can I run an Envio LUKSO indexer locally before deploying?
Yes. Run `pnpm dev` to start the indexer locally using Docker. The same handler code runs locally and in production without any changes.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How GBlast Eliminated Data Latency in Their GambleFi Platform
> How GBlast integrated Envio to eliminate real-time data latency, power their points system, and deliver a responsive GambleFi experience on Blast.
 :::note TL;DR
- GBlast, a GambleFi platform on Blast, integrated Envio to eliminate real-time data synchronization delays that were causing laggy user experiences in their PvP and house-banked games.
- HyperSync replaced JSON-RPC for data ingestion, delivering faster historical sync and enabling GBlast to join onchain and off-chain data in a single custom GraphQL API.
- GBlast deployed without managing any backend infrastructure, using Envio's hosted service via their existing GitHub push workflow.
:::
[GBlast](https://gblast.gg/), a GambleFi platform on [Blast](https://blast.io/en), integrated Envio's blockchain indexer to resolve real-time data synchronization delays that were causing laggy user experiences in their luck-based games. The integration eliminated data latency issues and removed the need for GBlast to deploy or maintain any backend infrastructure.
## What is GBlast?
[GBlast](https://gblast.gg/) is an innovative GambleFi platform on [Blast](https://blast.io/en) that offers a unique blend of player-versus-player (PvP) competitions and house-banked games. Designed to provide an exhilarating gaming experience, GBlast allows users to engage in competitive PvP matches and enjoy a variety of house-banked games, all within a secure and transparent environment.
Key features include:
- **PvP Competitions**: Experience adrenaline-pumping PvP matches where players compete against each other in various games of skill and chance.
- **House-Banked Games**: Enjoy a range of traditional and innovative games where the platform acts as the house, providing diverse gaming options.
- **Secure and Transparent**: Built on robust blockchain technology, GBlast ensures security through battle-tested smart contracts, and transparency on in-game outcomes.
## About the Integration
Before integrating with [Envio](https://envio.dev/), GBlast struggled with real-time data synchronization for their luck-based games. Previous indexing solutions failed to meet their needs, leading to delays between player activities occurring on the blockchain and what was being presented in the front-end.
Envio transformed GBlast's operations by providing real-time smart contract data to the front-end, supporting their points reward system, and facilitating operator actions. By eliminating data latency issues and enhancing real-time data accessibility, GBlast improved its overall user experience, fostering higher engagement and satisfaction among players.
Efficient historical data retrieval capabilities have also empowered GBlast to gain deeper operational insights and optimize decision-making processes, enhancing operational efficiency and resource utilization. Envio's blazing-fast indexing instantly makes all historical data available for querying via a custom [GraphQL](https://graphql.org/) API.
By leveraging [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) for data ingestion instead of JSON-RPC, GBlast has drastically improved its syncing performance and future-proofed their application, so that even the largest datasets only take a few minutes to index.
GBlast has further enriched its custom API by utilizing Envio's support for asynchronous operations in its event handlers, enabling the addition of any data available on the internet to the indexer and storing it in a backend database for querying purposes. Simply put, this involves joining onchain and off-chain data for a more flexible API.
Moreover, GBlast did not have to deploy or maintain any backend infrastructure, simply leveraging their existing development workflows, such as pushing code to a specific branch, to deploy their indexer to Envio's hosted service.
Envio's responsive support and customizable features facilitated seamless integration and ongoing optimization. This support ensured that GBlast could focus on innovating and expanding its gaming offerings while relying on a robust and scalable infrastructure.
## Challenges Faced
Specializing in real-time luck-based games on blockchain platforms, GBlast relies on smart contracts to ensure fairness and transparency for players. Accessing real-time game states and historical data efficiently is critical to delivering a seamless and engaging user experience.
GBlast encountered significant challenges with their previous data management solutions:
- **Real-Time Data Accessibility**: Existing solutions failed to deliver timely updates of smart contract states to the front-end, resulting in laggy user experiences.
- **Operational Monitoring**: Monitoring and managing operator actions, vital for game integrity, required a more responsive and scalable data infrastructure.
- **Historical Data Analysis**: Extracting and analyzing historical data for insights and auditing purposes was cumbersome and resource-intensive.
## How Envio Solved this Problem
Envio's [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) and [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) technologies provided flexible solutions to GBlast's challenges. The HyperIndex framework integrated with GBlast's application, enabling real-time updates of smart contract states to the front-end, significantly reducing latency and ensuring smooth gameplay interactions.
HyperSync accelerated the retrieval of historical blockchain data, allowing GBlast to perform comprehensive data analysis swiftly and efficiently. Envio's detailed logging was instrumental in monitoring and logging operator actions in real-time, improving transparency and operational oversight.
Envio's hosted service also eliminated the need for manual indexer deployment, allowing for quick setup and reducing operational overhead. Once configured, Envio's hosted service streamlines development and deployment. Simply push your latest indexer version to Envio's GitHub repository to auto-deploy your indexer to the hosted service. Developers can easily manage and configure their indexers through the Envio Deployments GitHub app.
This approach allows developers to focus on their application's core functionality while ensuring Indexers deliver guaranteed performance with production-grade infrastructure.
For more information on how to deploy an indexer to Envio's hosted service visit our [developer docs](https://docs.envio.dev/docs/HyperIndex/hosted-service).
> *"The Envio team is really based, they respond to messages in no time, fix all the issues as soon as they appear (I assume they do not sleep), and can provide custom features for you. Envio is truly from devs for devs!"*
>
> CTO at GBlast
## Why Envio?
Envio is a developer-first, modern blockchain data indexing solution that lets developers and data analysts reliably read and process any real-time and historic smart contract data served via query-rich GraphQL API.
Envio supports the Blast Mainnet, Blast Sepolia and 70+ other EVM blockchain networks with:
- **Flexible language support:** Configure your event handling in familiar and widely supported languages, such as [JavaScript](https://www.javascript.com/), [TypeScript](https://www.typescriptlang.org/), or [ReScript](https://rescript-lang.org/).
- **[HyperSync](https://docs.envio.dev/docs/HyperSync/overview):** To ensure blazing-fast retrieval of historical onchain data and a seamless developer experience, Envio's HyperSync endpoint allows up to 2000x faster indexing than standard RPC (use of RPC is optional).
- **[No-code Quickstart](https://docs.envio.dev/docs/HyperIndex/contract-import):** Autogenerate the key boilerplate for an entire Indexer project off single or multiple smart contracts. Deploy within minutes.
- **[Multichain Support](https://docs.envio.dev/docs/HyperIndex/multichain-indexing):** Aggregate data across multiple networks into a single database. Query all your data with a unified GraphQL API.
- **[Join onchain and off-chain data](https://docs.envio.dev/docs/async-mode):** Connect indexed blockchain data as well as ingest off-chain data to create flexible API for rich data beyond just what is emitted simply from events onchain. e.g. modules that efficiently index off-chain NFT metadata.
- **[Factory Contracts](https://docs.envio.dev/docs/dynamic-contracts)**: Automatically register and process events emitted by all child contracts that are created by the specified factory / dynamic contract.
- **[Hosted Service](https://docs.envio.dev/docs/HyperIndex/hosted-service)**: A managed service platform for building, hosting and querying Envio's Indexers with guaranteed uptime and performance service level agreements.
## Relevant Links
- [GBlast Hosted Indexer](https://envio.dev/app/gblastgg/boss-indexer123)
- [Envio HyperIndex Quickstart](https://docs.envio.dev/docs/HyperIndex/contract-import)
- [Envio HyperSync](https://docs.envio.dev/docs/HyperSync/overview)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Fast Data Indexing on Fuel using Envio
> Learn how Envio brings fast data indexing to Fuel Network so developers can query real-time and historical onchain data with speed and simplicity.
 :::note TL;DR
- The Fuel Network is a high-performance Ethereum rollup OS with the FuelVM and the Sway programming language, purpose-built for parallel execution and scalable dApps.
- Envio supports Fuel with two products: HyperFuel (fast raw data access) and HyperIndex (full GraphQL indexing framework with hosted deployment).
- Unlike The Graph (EVM-only, separate subgraph per chain), Envio's single-config approach supports both Fuel and EVM chains from one indexer.
:::
The [Fuel Network](https://fuel.network/) addresses Ethereum's scalability challenges with a parallelized execution environment and state-minimized architecture. Envio provides the data infrastructure layer for Fuel, giving developers and data analysts efficient access to real-time and historical onchain data through a modular indexing stack.
In this blog, we explore how developers and data analysts can leverage Envio's data stack to index and query data on the Fuel Network.
## What is the Fuel Network?
The [Fuel Network](https://fuel.network/) is a high-performance, modular blockchain infrastructure designed to support scalable and efficient dApps. It combines the Fuel Virtual Machine ([FuelVM](https://docs.fuel.network/docs/intro/what-is-fuel/)) with Optimistic Rollup technology to achieve high transaction throughput and low fees. Fuel also introduces [Sway](https://docs.fuel.network/docs/sway/), a strongly-typed language inspired by Rust designed for smart contract development.
At the heart of Fuel is the FuelVM: an execution environment parallelized for maximum throughput and state-minimized for sustainable state growth. For a technical deep dive into Fuel's architecture, see the [Fuel blog](https://fuel.mirror.xyz/uQxyb1o_Gu4oBSyT1ULuqRu7ffmIXuZtx9ux8ndFMXs).
## What Envio supports on the Fuel Network
### HyperFuel
Envio's [HyperFuel](https://docs.envio.dev/docs/HyperSync/hyperfuel) is a version of [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) specifically adapted for the Fuel Network. It provides a low-level API for developers and data analysts to run flexible, filtered, high-speed queries for smart contract data and large datasets.
HyperFuel acts as a high-performance real-time data archive that accelerates data retrieval on Fuel, enabling efficient parsing, querying, and analysis of Fuel data.
Developers and data analysts can interact with the HyperFuel API using JavaScript, Python, or Rust [clients](https://github.com/enviodev/hyperfuel-json-api), and choose to output data in JSON, Arrow, and Parquet formats.
With HyperFuel, developers can sync large datasets in minutes, eliminating the need to use slow or rate-limited node endpoints. HyperFuel is ideal for developers building dApps, block explorers, wallets, analytics tools, and other data-heavy use cases on Fuel.
### HyperIndex
Envio's [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) is a developer-first, real-time data indexing framework for rapidly building custom GraphQL APIs for smart contract data on Fuel.
[Contract Import](https://docs.envio.dev/docs/HyperIndex/contract-import) is the fastest starting point for most Fuel developers: supply your contract ABI, select the events you want to index, and follow the CLI prompts to generate your first indexer in under a minute.
For a detailed tutorial, see the [Sway Farm indexer tutorial](https://docs.envio.dev/docs/HyperIndex/tutorial-indexing-fuel), which walks through creating an indexer for a real-world onchain farming game on Fuel.
Fuel teams can host their indexer on [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service), a managed platform with guaranteed uptime, so teams can focus on their application rather than infrastructure.
Unlike The Graph (which supports EVM chains only and requires a separate subgraph per network) or Goldsky (which requires separate pipelines), Envio uses a single `config.yaml` for all networks and exposes a single GraphQL endpoint across all chains.
## Data indexer use cases on Fuel using Envio
- [Data Indexer](https://github.com/compolabs/spark-envio-indexer) for [Spark](https://sprk.fi/), a DeFi super app with perpetual contracts, an orderbook, and lending and borrowing features.
- [Data Indexer](https://github.com/enviodev/fuel-thunder-exchange/tree/main) for [Thunder](https://thundernft.market/), an NFT marketplace allowing multiple NFT purchases in a single transaction thanks to Fuel's parallel execution.
## Relevant resources
- [Envio Tutorial: Indexing Sway Farm on the Fuel Network](https://docs.envio.dev/docs/HyperIndex/tutorial-indexing-fuel)
- [Envio HyperIndex Quickstart](https://docs.envio.dev/docs/HyperIndex/getting-started)
- [Envio HyperFuel](https://docs.envio.dev/docs/HyperSync/hyperfuel)
- [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service)
## Frequently asked questions
### What is the difference between HyperFuel and HyperIndex for Fuel development?
HyperFuel is a low-level raw data API for fetching large volumes of Fuel data quickly, suited for custom pipelines and analytics. HyperIndex is a full indexing framework that transforms onchain events into a structured database with a GraphQL API, suited for dApp backends. Many Fuel developers use both.
### Can I use TypeScript to write my Fuel indexer with Envio?
Yes. HyperIndex event handlers are written in TypeScript (JavaScript is also supported). You define your schema in `schema.graphql`, your network config in `config.yaml`, and your handler logic in TypeScript files.
### Does Envio support the Fuel Sway programming language?
Envio indexes the events and logs emitted by Sway contracts on Fuel. You provide the contract ABI (which represents the contract interface) and Envio handles the rest. Sway-specific data types are supported through the HyperFuel and HyperIndex ABIs.
### How does Envio compare to other indexing options for Fuel?
The Graph does not support Fuel. Envio is purpose-built for Fuel with HyperFuel for raw data access and HyperIndex for GraphQL indexing. Envio Cloud includes GitHub-based auto-deployment and managed infrastructure, which is not available from alternatives.
### Is Envio free to use for Fuel indexers?
Envio offers a free development tier for hosted indexers. You can also run indexers locally for free using Docker and `pnpm dev`. Production tiers are available for teams that need guaranteed uptime SLAs.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How Sablier Streams Tokens Across 27+ Chains with One Envio Indexer
> How Sablier replaced 12 separate indexer deployments with one Envio multichain indexer, now spanning 27 chains, cutting costs and accelerating feature delivery.
 :::note TL;DR
- Sablier replaced 12 separate indexer deployments with a single Envio HyperIndex deployment, now spanning 27 chains, eliminating fragmented data and per-chain infrastructure overhead.
- Envio's multichain indexing consolidates all token streaming data into one PostgreSQL database accessible through a single GraphQL API, with HyperSync reducing sync times from hours or days to minutes.
- The migration cut infrastructure costs, accelerated Sablier's development lifecycle, and enabled chain-abstracted dashboards for improved UX.
:::
[Sablier](https://sablier.com/), a next-generation token streaming and distribution platform, transitioned to Envio's HyperIndex to replace 12 separate indexer deployments. The single indexer now covers 27 chains, eliminating infrastructure complexity, cutting costs, and significantly reducing data sync times.
## What is Sablier?
Sablier is a DeFi platform offering real-time, blockchain-based money-streaming services. Specializing in onchain token distribution for DAOs, businesses, and individual users, Sablier enables flexible vesting, payroll, airdrops, and grants. Operating through smart contracts on EVM-compatible networks, the Sablier platform facilitates continuous streams of ERC-20 tokens over scheduled periods (seconds, minutes, etc.), enhancing financial efficiency, transparency, and security without intermediaries.
Sablier also integrates seamlessly with other DeFi protocols, providing programmable and scalable payment solutions within the DeFi ecosystem, making it a part of the broader DeFi landscape by enabling real-time, trustless, and automated payment flows.
## Deep Dive into the Integration
Before integrating with Envio HyperIndex, Sablier grappled with the complexity of managing and maintaining 12 separate deployments of indexers across multiple mainnets, including [Optimism](https://www.optimism.io/), [Gnosis](https://www.gnosis.io/), [Polygon](https://polygon.technology/), [zkSync](https://zksync.io/), [Base](https://www.base.org/), [Scroll](https://scroll.io/), and more. With an ambitious growth trajectory and a commitment to providing a seamless user experience while scaling across a diverse array of EVM blockchain networks, Sablier needed to re-evaluate its infrastructure to optimize and support its growth strategy.
With the launch of their new product, Airstreams, in Sablier V2.1 and more recently the introduction of [Sablier V2.2](https://blog.sablier.com/q3-2024-release-notes/) with a specialized contract called LockupTranched, the prospect of updating and re-indexing 12 indexers, or deploying 12 new ones, was daunting. This process would be extremely resource-intensive, both in terms of infrastructure and cost.
In their search for alternatives, Envio stood out due to its robust multichain support, lightning-fast indexing times for fetching historical data, and real-time data synchronization capabilities. Envio's developer-friendly and flexible architecture allows for quick adaptation and support for a wide range of blockchains, perfectly aligning with Sablier's goal of becoming a truly multichain token streaming platform.
> *"Envio has significantly streamlined our workflow, enabling us to build, index, and release new features to our customers faster than ever before. Not only that, but through their multichain querying architecture, they've empowered us to prepare for a future where Sablier could offer chain-abstracted dashboards, paving the way for a vastly improved and less technical UX."*
>
> [Razvan Gabriel](https://x.com/razgraf), Co-founder and CPO at Sablier
## Challenges Faced
- **Operational Complexity**: Managing 12 separate indexer deployments significantly increased the operational burden and introduced numerous potential points of failure. This required meticulous monitoring and proactive infrastructure maintenance to ensure stability and performance.
- **Data Fragmentation**: Sablier had to query data from multiple endpoints and incorporate additional code to aggregate cross-chain data, creating a unified view of activity and analytics. This data fragmentation added complexity to their operations.
- **Sync times:** The lengthy sync and re-sync times for datasets meant that product features and updates took longer to develop and deploy. This hindered Sablier's ability to accelerate its development cycles and respond swiftly to market demands.
- **Scalability Issues**: As Sablier added new networks, the need for additional indexers complicated the infrastructure and increased maintenance costs. This scalability issue posed a significant challenge to their growth strategy.
- **Cost Inefficiencies**: Higher infrastructure maintenance and update costs due to multiple indexers diverted resources from core development activities, reducing overall efficiency.
## Envio as Sablier's new Data API
### Multichain Efficiency
One of the standout features of Envio's SDK that greatly benefited Sablier was its multichain support. This feature eliminated the need for Sablier to deploy separate indexers for each chain and allowed them to write data to a single database for unified data access. Other indexers require a separate deployment per chain. With Envio, all networks are configured in a single config.yaml.
Envio's multichain capability provides developers with an efficient way to access fragmented data across multiple chains. Builders can specify their event handler to operate against a common schema. For Sablier, they could collect and transform data from various sources and aggregate it into a single PostgreSQL database. With all cross-chain data consolidated, Sablier could query this data via a unified GraphQL API instead of requesting the same data via multiple endpoints. This streamlined their operations, making it easier to manage and utilize data from multiple blockchain networks.
 When indexing multichain, Envio's SDK offers two options:
1. **Default Mode:** This mode preserves ordering across chains and ensures that events from all chains are ingested and processed in sequence. It is essential if you need to maintain the order across chains and are handling the same data from multiple chains.
2. **Unordered Head Mode:** This mode indexes each chain quickly without preserving order across chains. It is useful if you are indexing at the head and do not want the slow block time of one chain to hinder the optimistic processing of events on other chains.
 For more information on Envio's multichain indexing capabilities, view our dev docs [here](https://docs.envio.dev/docs/HyperIndex/multichain-indexing).
### Simplified Infrastructure Management
Sablier chose to leverage TypeScript, offering a more straightforward development experience, and once developed and tested, proceeded to deploy their [multichain indexer](https://envio.dev/app/sablier-labs/merkle-envio) to Envio's hosted service. Builders can easily manage and configure their indexers through the Envio Deployments GitHub app, streamlining development and deployment by pushing the latest indexer version to a preconfigured branch to auto-deploy the indexer to the hosted service.
Envio's hosted service allows you to have a static production deployment URL. By pushing your latest project code to a pre-configured GitHub repository, your indexer will be auto-deployed to the hosted service, ensuring a consistent and static URL for your production deployment.
For more information on deploying an indexer to Envio's hosted service, view our dev docs [here](https://docs.envio.dev/docs/HyperIndex/hosted-service).
### Speeding up the Development Lifecycle
Sablier's next major optimization aims to enhance its development workflow, enabling quicker development and testing of new product features while improving reliability by minimizing application downtime. Previously, syncing datasets with their current indexing solution took considerable time, sometimes requiring several hours or even days to fully sync the data.
Envio's indexing framework, HyperIndex, automatically leverages HyperSync for data ingestion as an alternative to RPC. [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) is a specialized data node built in Rust that allows querying historical blockchain data up to 2000x faster than a standard JSON-RPC node. This approach significantly improves over traditional RPC methods, as it retrieves multiple blocks simultaneously, dramatically speeding up the process. Additionally, HyperSync's low-level API enables users to request specific data fields without fetching the entire block. This selective approach reduces the data processing load, making the system more efficient and responsive.
By integrating Envio's HyperIndex, Sablier can significantly reduce data sync times, allowing for faster iteration and deployment of new features. This improvement not only accelerates the development lifecycle but also enhances the reliability and efficiency of their operations across multiple blockchain networks.
> *"At Sablier, we're always striving to enhance UX and ensure maximum uptime. When we integrated Envio's indexing services, we expected improvements, but the results exceeded our expectations. Not only did our app's UX significantly improve, but our development team and integrators also benefited from an incredibly clear, more powerful and efficient development experience (DX). Envio has been a game-changer for us in more ways than one."*
>
> [Paul R Berg](https://x.com/PaulRBerg), Co-Founder and CEO at Sablier
For more information on indexing performance, view the blog article on Envio's performance benchmark [here](https://docs.envio.dev/blog/indexer-benchmarking-results).
Other noticeable features that Sablier has implemented to create a data-rich API:
### Reading Contract Data
Ideally, smart contracts emit event logs containing all the data needed to build your application. However, in practice, developers often forget to include certain event logs or omit them for gas optimization purposes. In most cases, these gaps can be addressed by reading data directly from a contract.
For Sablier's V2 core contracts, a singleton-style architecture is used, where all money streams are managed within the LockupLinear, LockupDynamic, and LockupTranched contracts. Sablier's flagship model, the linear stream, distributes assets on a continuous, by-the-second basis. The sender deposits a specific amount of ERC-20 tokens into a contract, which then progressively allocates these tokens to recipients. The recipients can access their tokens as they become available over time.
To determine the ERC-20 token details, such as its symbol and decimals, Sablier customized their event handlers to perform asynchronous contract calls to smart contract view functions. This retrieves the necessary contract state. Recognizing that contract calls can slow down the indexing process, Sablier decided to cache these requests. Then, the event handler simply loads the information from the cache instead of performing repeated contract calls for the same data.
This approach not only ensures that Sablier can access the required contract state efficiently but also optimizes the indexing process by minimizing redundant contract calls, thereby improving overall performance and responsiveness.
## Conclusion
As Sablier continues to evolve, our collaboration remains a cornerstone of their multichain strategy. We eagerly anticipate how this integration will further their mission and set new standards in the blockchain space. If you want to take a look at Sablier's indexer implementation or their data API, you can view their information in the Sablier developer API docs [here](https://docs.sablier.com/api/overview).
## Relevant Links
- [Sablier Hosted Indexer](https://envio.dev/app/sablier-labs/merkle-envio)
- [Envio HyperIndex Quickstart](https://docs.envio.dev/docs/HyperIndex/contract-import)
- [Envio HyperSync](https://docs.envio.dev/docs/HyperSync/overview)
- [Envio's Multichain Indexing](https://docs.envio.dev/docs/HyperIndex/multichain-indexing)
- [Envio Hosted Service](https://docs.envio.dev/docs/HyperIndex/hosted-service)
## Why Envio?
Envio is a developer-first, modern blockchain data indexing solution that lets developers and data analysts reliably read and process any real-time and historic smart contract data.
Envio supports the [Fuel Network](https://fuel.network/) and any EVM-compatible blockchain network with:
- **Flexible language support:** Configure your event handling in familiar and widely supported languages, such as [JavaScript](https://www.javascript.com/), [TypeScript](https://www.typescriptlang.org/), or [ReScript](https://rescript-lang.org/).
- [**HyperSync**](https://docs.envio.dev/docs/HyperSync/overview): To ensure blazing-fast retrieval of historical onchain data and a seamless developer experience, Envio's HyperSync endpoint allows up to 2000x faster indexing than standard RPC (use of RPC is optional).
- [**No-code Quickstart**](https://docs.envio.dev/docs/HyperIndex/contract-import): Autogenerate the key boilerplate for an entire Indexer project off single or multiple smart contracts. Deploy within minutes.
- [**Multichain Support**](https://docs.envio.dev/docs/HyperIndex/multichain-indexing): Aggregate data across multiple networks into a single database. Query all your data with a unified GraphQL API.
- [**Join onchain and off-chain data**](https://docs.envio.dev/docs/async-mode): Connect indexed blockchain data as well as ingest off-chain data to create flexible API for rich data beyond just what is emitted simply from events onchain. e.g. modules that efficiently index off-chain NFT metadata.
- [**Factory Contracts**](https://docs.envio.dev/docs/dynamic-contracts): Automatically register and process events emitted by all child contracts that are created by the specified factory / dynamic contract.
- [**Hosted Service**](https://docs.envio.dev/docs/HyperIndex/hosted-service): A managed service platform for building, hosting, and querying Envio's Indexers with guaranteed uptime and performance service level agreements.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Building ChainDensity with HyperSync
> How Envio's HyperSync powers ChainDensity to visualize blockchain event and transaction density across 70+ chains, processing millions of events in seconds.
 :::note TL;DR
- ChainDensity is an open-source tool that visualizes event and transaction density for any address across Ethereum and 70+ EVM chains, built on top of Envio's HyperSync Python client.
- HyperSync replaces thousands of `eth_getLogs` RPC calls with a single efficient query, enabling ChainDensity to process 9+ million events in under 32 seconds.
- The tool helps developers planning indexing projects estimate event volumes and distribution before committing to an indexing approach.
:::
[ChainDensity](https://chaindensity.xyz/) is a tool that visualizes event and transaction density for any address across Ethereum and any EVM-compatible blockchain. Built using Envio's HyperSync Python client, it processes millions of events in seconds by replacing traditional RPC calls with a single efficient query.
ChainDensity transforms raw data into clear visualizations, empowering developers, data analysts, and researchers to uncover trends, optimize performance, and harness the full potential of blockchain technology. By creating density plots that span the entire length of a chain, ChainDensity allows users to quickly grasp when an address is most active and assess its total activity over time.
Explore the tool yourself [here](https://chaindensity.xyz).
Consider, for instance, the 'Banana Gun: Router' address on Ethereum. ChainDensity reveals all 5.7 million events emitted by the address, providing a clear distribution of activity of the protocol across the chain's lifespan.
 ### The Dual Lens: Event and Transaction Density
ChainDensity operates in two distinct modes:
1. **Event Density**: This mode illuminates the volume of events emitted by a contract address over time. It's particularly valuable for data indexing projects, as most smart contracts emit events for significant actions like swaps, transfers, mints, or burns.
2. **Transaction Density**: This view showcases the volume of transactions an address participates in over time, offering insights into overall account activity.
### The Data Indexing Dilemma
Event density analysis is very insightful for blockchain data indexing. Traditionally, retrieving event data has been the Achilles' heel of indexing projects. The process of scanning through hundreds of millions of blocks for events is notoriously slow and resource-intensive.
ChainDensity addresses this challenge head-on. It provides a rapid assessment of the volume of events to be indexed and their distribution across the chain. This information is invaluable for planning indexing projects, estimating timelines, and determining the most appropriate indexing methodologies.
:::tip
Have an indexer and syncing millions of events?
Consider using [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) (which leverages [HyperSync](https://docs.envio.dev/docs/HyperIndex/hypersync) under the hood as an alternative data source to RPC) to significantly speed up the process.
:::
## The Blockchain Data Retrieval Challenge
The conventional approach to blockchain data retrieval involves running a node and using RPC methods to extract data. This method, while functional, is far from efficient:
* It's a slow process that consumes significant resources.
* Nodes are optimized for maintaining blockchain functionality, not for rapid and flexible data retrieval.
* Replicating ChainDensity's functionality using traditional methods would require tens of thousands of `eth_getLogs` calls, a time-consuming and resource-intensive endeavour.
This inefficiency isn't unique to ChainDensity's use case. It's a common hurdle in various blockchain data applications, from analytics to protocol development.
## Enter HyperSync: Modern Blockchain Data Retrieval
[HyperSync](https://docs.envio.dev/docs/HyperSync/overview) emerges as a game-changing solution in the blockchain data retrieval landscape. This highly specialized data node, built with Rust, offers a quantum leap in data retrieval speeds while providing unparalleled flexibility.
### Key Features of HyperSync
* A powerful API that is capable of filtering blocks, transactions, logs, and traces.
* Granular control over data retrieval.
* Support for [Python](https://github.com/enviodev/hypersync-client-python), [Rust](https://github.com/enviodev/hypersync-client-rust), and [NodeJs](https://github.com/enviodev/hypersync-client-node) clients.
* Compatibility with 70+ EVM chains and [Fuel](https://github.com/enviodev/hyperfuel-json-api).
### HyperSync in Action: The ChainDensity Example
ChainDensity leverages the Python client to interact with HyperSync. This integration transforms what would typically require thousands of `eth_getLogs` calls into a single, efficient query to the HyperSync node.
Moreover, HyperSync's flexibility allows for precise data selection. In ChainDensity's case, we're only interested in the block number associated with each log or transaction. By specifying this in the query, we drastically reduce the data transfer volume, further enhancing performance.
```93:119:app.py
def create_query(address, start_block, request_type):
if request_type == "event":
query = hypersync.Query(
from_block=start_block,
logs=[LogSelection(
address=[address],
)],
field_selection=FieldSelection(
log=[
LogField.BLOCK_NUMBER,
],
),
)
else:
query = hypersync.Query(
from_block=start_block,
transactions=[
TransactionSelection(from_=[address]),
TransactionSelection(to=[address]),
],
field_selection=FieldSelection(
transaction=[
TransactionField.BLOCK_NUMBER,
],
),
)
return query
```
This code snippet demonstrates the elegant simplicity of creating HyperSync queries for both event and transaction data. The queries are concise yet powerful, filtering for specific addresses and selecting only the necessary field (block number) for our density analysis.
## Scalability and Performance: HyperSync's True Power
The true prowess of HyperSync becomes evident when dealing with large-scale data retrieval. Consider the [Aave: Pool V3 on Arbitrum](https://arbiscan.io/address/0x794a61358d6845594f94dc1db02a252b5b4814ad):
* 244,532,390 blocks processed.
* 9,108,786 events processed.
* All accomplished in just 31.51 seconds.
This translates to an impressive processing rate of 7,761,296 blocks per second and 289,107 events per second. This level of performance is achievable "cold" (without caching) for any address across more than 70 different chains. Such speed and efficiency open up new possibilities for all kinds of applications previously impossible due to data retrieval limitations.
 ## Visualizing Blockchain Activity
ChainDensity's visualization capabilities bring blockchain data to life. The density plots offer intuitive insights into address activity patterns, allowing users to identify:
* Periods of high activity.
* Dormant phases.
* Overall transaction or event volume trends.
Consider this interesting event density plot for the [Mutant Ape Yacht Club](https://opensea.io/collection/mutant-ape-yacht-club) collection. One can see a massive initial spike in activity (minting) before relatively little activity as users presumably held their NFTs. One can start to see a second spike in activity as users likely started to sell their NFTs. Today activity is minimal as the collection is less popular.
 ## Future Horizons for ChainDensity
While ChainDensity already offers powerful insights, there's potential for even more advanced features:
* **Multi-address analysis**: Comparing activity patterns across multiple addresses on a single plot.
* **Cross-chain comparisons**: Visualizing how an address or contract behaves across different networks.
Why not head over to the [repo](https://github.com/enviodev/chain-density) and make a pull request?
## Use HyperSync yourself
Explore [ChainDensity](https://chaindensity.xyz) to experience the power of [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) firsthand. If you're looking to leverage HyperSync for your project, visit our documentation or hop in our [Discord](https://discord.gg/envio) for support.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How Limitless Built a Real-Time Prediction Market Feed on Base
> How Limitless Exchange uses Envio to power a daily prediction market on Base with real-time onchain data, custom GraphQL APIs, and a seamless transaction feed.
 :::note TL;DR
- Limitless Exchange, a daily prediction market on Base, selected Envio as its data indexer to power real-time onchain data feeds, transaction history, and market analytics through a custom GraphQL API.
- Envio's HyperIndex handles market data, volume tracking, oracle price feeds, winning shares, and a live "Limitless Feed" transaction stream that updates as events occur onchain.
- The integration enables Limitless to scale new market types (customizable markets, enhanced rewards) without rebuilding data infrastructure for each feature.
:::
[Limitless Exchange](https://limitless.exchange/), a daily prediction market built on Base, selected Envio as its blockchain data indexer to power real-time onchain data and application analytics. Envio's HyperIndex handles market creation data, volume tracking, oracle feeds, and the platform's live transaction feed.
## What is a Prediction Market?
Prediction markets allow participants to buy and sell shares based on the outcome of future events, such as crypto prices, sporting events, or political elections. In decentralized finance, these markets operate transparently using smart contracts to ensure trustless participation and automatic settlement. By leveraging crowd wisdom, prediction markets provide a collective forecast of future events, allowing users to earn rewards based on accurate predictions.
## How do Prediction Markets work?
Prediction markets rely on smart contracts and oracles to function securely and transparently. Smart contracts are self-executing programs on the blockchain that automate the trading process, manage payouts, and ensure trustless execution. Oracles serve as bridges between the blockchain and the real world by providing accurate, tamper-resistant data regarding the outcome of events.
Prediction markets allow you to bet on whether an event will occur, with financial rewards for correct predictions. You can buy shares in an event's outcome, and if the event happens, you can redeem your shares for a profit.
When the event's outcome is determined, the oracle sends the information to the smart contract, which then automatically distributes the rewards to participants based on their positions. This combination of blockchain technology ensures that prediction markets are decentralized, secure, and resistant to manipulation.
## Overview of Prediction Markets
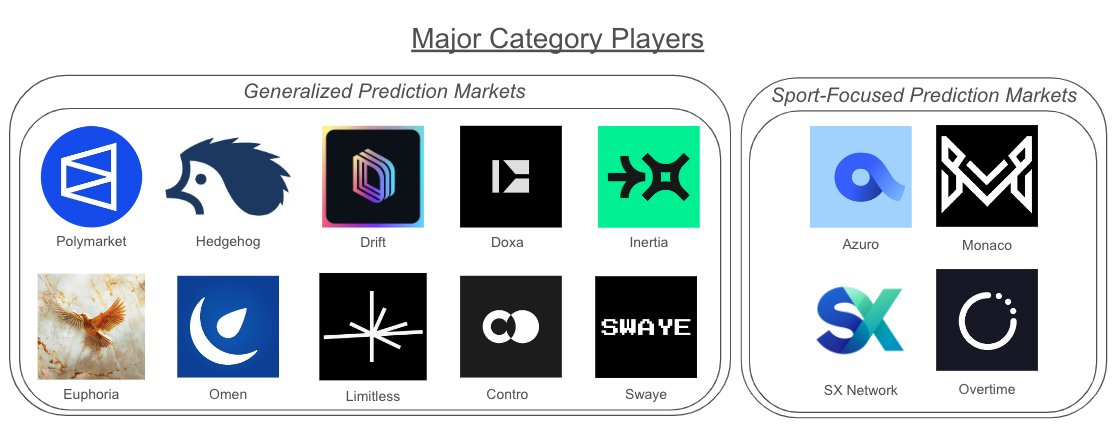 Currently, Polymarket is the world's largest prediction market. Deployed on Polygon, Polymarket has experienced exponential growth, with elections accounting for 85% of its total volume. In July 2024, the platform generated an impressive $137.3 million in weekly trading volume. Data also suggests that non-election prediction markets have been increasing, such as betting on crypto prices, sports results, or social events.
Azuro Protocol stands out for its sports betting markets, which provide the tooling, oracle, and liquidity solution for EVM chains to host sports-specific prediction markets. B.E.T. built on top of the Drift Protocol, and Hedgehog, are two popular prediction markets on Solana, with B.E.T. recently reaching $20 million daily volume.
Limitless Exchange, a new daily prediction market on Base focusing on price action and sporting events, recently hit over [$9.7 million](https://dune.com/limitless_exchange/limitless) in volume. A week prior, Limitless was doing $100k in volume, suggesting its traction is growing.
Each prediction market platform aims to be capital-efficient and use different mechanisms to incentivize engagement and accuracy, integrating underlying DeFi capabilities. Some of these include, but are not limited to:
- Earning yield on your positions, integrating yield through lending/borrowing platforms
- Hedging positions, by going long on a prediction market while simultaneously shorting a cryptocurrency, such as Bitcoin.
- Utilizing different tokens as collateral, not just stablecoins. Limitless allows the use of USDC, ETH, BTC as well as any ERC-20-compliant token.
- DAO structures and governance models allow participants to stake tokens on the underlying platform token and vote in determining future markets
## What is Limitless Exchange?
Envio has had the pleasure of working closely with the team behind [Limitless Exchange](https://limitless.exchange/), a daily prediction market built on Base and coined as the "people's prediction market."
With Limitless Exchange, participants can use various tokens, take part in transparent voting for upcoming markets, and engage in opportunities created by the community. The platform promotes community involvement, allowing users to configure their own markets and share them with others.
Limitless Exchange leverages AI-driven data analytics to provide real-time insights, empowering users to make informed predictions based on the latest information. The platform supports a wide range of prediction scenarios, enhancing the overall user experience with timely and accurate data.
[](https://x.com/cjhtech/status/1829930727397290116)
## How Envio Powers Limitless's Daily Prediction Markets
While smart contracts and oracles are core infrastructure components that enable decentralized prediction markets to function securely and autonomously, another essential mission-critical infrastructure component in blockchain applications is the ability to deliver real-time updates to users, ensuring a frictionless experience. With ambitious growth objectives and a commitment to a seamless user experience, the Limitless Exchange team recognized the need to optimize its data infrastructure early on to support its expanding range of prediction markets and growth strategy.
To achieve this, Limitless Exchange selected Envio as its data indexer and accelerated data infrastructure partner. Envio provides real-time data query capabilities and blazing-fast indexing of onchain data, allowing Limitless to query its onchain data efficiently through a custom application GraphQL API.
[](https://x.com/cjhtech/status/1829132368755486735)
The introduction of new features such as customizable markets, enhanced reward systems, and a transaction feed (all of which operate onchain) requires a robust solution for handling and querying this data efficiently. Envio's feature-rich data indexing framework enables protocols like Limitless Exchange to create application-tailored APIs with ease.
Limitless Exchange is able to query information such as:
- New prediction markets and their associated contract addresses, collateral tokens, launch dates, and expiry dates
- Volume traded per market, volume per participant, total volume traded
- Price feed from Oracles as resolution source
- Winning shares and ROI for market participants
- Transaction History, such as "Limitless Feed"
 *Screenshot of https://limitless.exchange/ new transaction feed, powered by Envio.*
 *Screenshot of https://limitless.exchange/ markets overview, powered by Envio.*
 *A screenshot of https://limitless.exchange/ quick bets, powered by Envio.*
The [Limitless Exchange Indexer](https://envio.dev/app/limitless-labs-group/fork-prod) and other indexers can be viewed in the Explorer of Envio Cloud.
## Relevant Links
- [Envio HyperIndex Quickstart](https://docs.envio.dev/docs/HyperIndex/contract-import)
- [Envio HyperSync](https://docs.envio.dev/docs/HyperSync/overview)
- [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service)
## Conclusion
As Limitless Exchange continues to grow and innovate, our collaboration remains a cornerstone of their strategy. We look forward to seeing how this integration will enhance their mission and drive new developments in the prediction market space.
Prediction markets still have untapped potential, especially in Web3. While they may lose steam post-election, the innovation around social layers, permissionless markets, and AI-driven insights is setting them up for a major resurgence. Prediction markets could evolve into a mainstream tool for decision-making, gaining both users and legitimacy.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update September 2024
> What Envio shipped in September 2024: v2.3.0 with Wildcard Indexing and IPFS integration, TOKEN2049 and EthCapeTown appearances, and new HyperSync networks.
 Welcome to our September 2024 developer update.
In this update, we'll explore our recent release, V2.3.0, highlighting innovative features like [Wildcard Indexing](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing), [IPFS](https://docs.envio.dev/docs/HyperIndex/ipfs) integration, and more. We'll also recap key updates from September, including our time at [Token2049](https://www.asia.token2049.com/) and [EthCapeTown](https://www.ethcapetown.com/), upcoming events, partnerships, and other important developments.
## Version 2.3.0 is now available
We are pleased to announce that the current release is **v.2.4.1**!
**What's changed?**
- **Wildcard Indexing**: Index whole chains by event signature without specifying exact contract addresses.
- **Event Filtering**: Filter events by indexed parameters. Simplify your handler's logic or get new indexing possibilities when joined with the Wildcard Indexing feature.
- **Fuel Merge**: The [Fuel](https://fuel.network/) ecosystem indexer has been integrated into the main repository code. This huge refactoring comes with a big list of benefits and opportunities, click [here](https://x.com/envio_indexer/status/1835977029641982080).
*Both Wildcard Indexing and Event Filters are currently only supported with HyperSync. We are working on adding support for RPC mode in the following versions.*
For more information and to view the full list of current and past release notes, click [here](https://github.com/enviodev/hyperindex/releases).
To stay updated with our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)! Your support is greatly appreciated!
## Wildcard Indexing
Wildcard indexing is a powerful feature that enables you to index all events matching a specified event signature without the need to specify the contract address from which the event was emitted. This capability is particularly beneficial in scenarios where contracts are deployed through factories that do not emit events upon contract creation. Additionally, it facilitates the indexing of events from all contracts implementing a standard, such as ERC20, streamlining the process and enhancing efficiency.
Learn more [here](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing).
## IPFS Guide
Check out our new guide on IPFS, a decentralized network designed for storing and sharing data. This guide walks you through the process of fetching IPFS data into your indexer, providing you with the tools to enhance your applications and leverage the power of decentralized storage.
Learn more [here](https://docs.envio.dev/docs/HyperIndex/ipfs).
## EthGlobal Online Hackathon Winners
 We're sharing the results of our EthGlobal [EthOnline](https://ethglobal.com/events/ethonline2024/prizes#envio) Hackathon! With 40 submissions, the competition was fierce, showcasing incredible talent and creativity. A huge thank you to the EthGlobal team and all the hackers who participated, making this hackathon a remarkable success!
To learn more about the winning projects, click [here](https://x.com/envio_indexer/status/1836013244164514289).
## Blazing-fast data retrieval now supported on Zircuit, Bartio, Morph, KakarotEVM, and more!
Envio's modular stack supports developers and data analysts building on [Zircuit](https://www.zircuit.com/) - an EVM-compatible ZK rollup with AI-enabled security at the sequencer level!
With [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) integrated, applications and data analysts can now fetch their data using standard RPC, or leverage HyperSync as more performant data source for up to a 1000x speed advantage. Apps can now develop, test, and innovate faster than before and deliver cutting-edge performance to their end users.
 Other new networks that were added to HyperSync this month include:
- Berachain Bartio
- Morph Testnet
- Citrea's New Testnet
- Kakarot-EVM Tesnet (Sepolia)
- Merlin Mainnet
- Lukso Testnet
HyperSync supported networks can be viewed [here](https://docs.envio.dev/docs/HyperSync/hypersync-supported-networks).
## Our Time at Token2049 and EthCapeTown
We had an incredible experience at both Token2049 and EthCapeTown this month! At Token2049, we hosted a "[Run & Chat](https://lu.ma/5v9wgs1n)" side event that allowed us to connect with participants in a relaxed setting while soaking up Singapore's beautiful scenery. At EthCapeTown, our "[Builders' Happy Hour](https://lu.ma/ta03bb8m)" provided a great opportunity to meet and network with talented builders in the space all before the main event kicked off.
A big thank you to all the attendees, sponsors, and event organizers for making these events possible. For more upcoming events and where to catch us - be sure to check out our upcoming events below.
## Upcoming Events
- Golden Gate Promenade Run with Envio - October 16
- [EthGlobal, EthSanFransisco](https://ethglobal.com/events/sanfrancisco2024) - October 18-20
- Encode London - October 25-27
## Workshops & Developer Tutorials
- [How to Index Data on Fuel In Less Than 5 Minutes](https://www.youtube.com/watch?si=bBKbCvBPYiQzOfKs&v=IEgmHAW0S_A&feature=youtu.be)
 - [How to Index Dat on Citrea in < 5mins](https://www.youtube.com/watch?v=rPPxS6ORaEc)
 For more written tutorials visit our [docs](https://docs.envio.dev/docs/tutorial-op-bridge-deposits).
For more video tutorials visit our [YouTube](https://www.youtube.com/@envio_indexer)
## Featured Developer
 We're pleased to announce our featured developer and community member of the month, Jordan Lesich, a highly experienced builder in the DAO ecosystem. With nearly five years of expertise working on DAO platforms like [DAOhaus](https://daohaus.club/), [Nouns.build](https://nouns.build/), and [DAO Masons](https://www.daomasons.com/), Jord brings a full-stack skill set to the table, engaging in every stage of dApp development - from design and contracts to frontend, backend, and indexers. His dedication to refining the DAO landscape makes him a standout contributor to our community.
***"I have been working on DAO platforms and peripheral tooling for DAOs for nearly five years. I enjoy working in every stage of dApp development (design, contracts, frontend, backend, indexers). Envio makes that process much easier."*** – Jordan Lesich, Co-Founder at DAO Masons
Jord is currently working on [Grant Ships](https://grantships.fun/), an onchain, competitive grants platform, and Chews Protocol, a modular framework for complex voting schemes. We're thrilled to see how these projects evolve and the continued impact they will have on the DAO space, well done Jords!
Explore Jord's indexers:
- [Grant Ships](https://envio.dev/app/daomasons/grantships-envio)
- [GS Voting](https://envio.dev/app/daomasons/gs-voting-envio)
For a full list of deployed indexers visit our [explorer](https://envio.dev/explorer).
Be sure to follow Jord on [X](https://x.com/JordanLesich) and check out his work on [GitHub](https://github.com/jordanlesich) to stay up-to-date with their latest projects and contributions.
## Community Updates
New merch who dis? Check out our latest batch of merch and be sure to come and find us at our upcoming events and side events to snag one of our very snazzy caps or some of our custom stickers.
 ## Playlist of the Month
[Open Spotify](https://open.spotify.com/playlist/74X6dI8SMqdrjSl1ECKF5e?si=2d979afa6d6a46ac)
 ## Envio Freelancer Network
Need an indexer but don't have the bandwidth? Whether you're looking to find top-notch freelancers or you're a freelancer seeking new opportunities, we've got you covered. Our thriving Freelancer Network connects skilled contractors with Web3 protocols to service their data needs.
Simply fill out the [form](https://noteforms.com/forms/envio-freelancer-network-u9zqbv) to join our freelancer network.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How Bridgg Unified 12 OP Superchain Networks into One API
> How Bridgg uses Envio to aggregate deposit and withdrawal data across 12 OP Superchain networks into a single API, indexing 11 million events in one deployment.
 :::note TL;DR
- Bridgg, a bridge interface for the OP Superchain, uses Envio's HyperIndex to aggregate deposit and withdrawal data across 12 chains (11 million events) into a single unified API.
- HyperSync replaces standard RPC for data ingestion, delivering faster historical sync and enabling rapid feedback loops for Bridgg's development team.
- All multichain data is consolidated into one database with one API endpoint, eliminating the per-chain infrastructure footprint and cost that would come with separate deployments.
:::
[Brid.gg](http://brid.gg/) is a bridge interface for the OP Superchain that provides users with a unified account history view across Ethereum, OP Mainnet, Base, Zora, Mode Network, Fraxtal, RedStone, and other OP chains. The team built their data layer on Envio's HyperIndex, indexing 11 million events across 12 chains through a single deployment.
## What is the OP Superchain?
Created by [OPLabs](https://www.oplabs.co/), the OP Superchain is a movement that aims to bring native interoperability to the [OP-Stack](https://docs.optimism.io/stack/getting-started) and enhance UX across the Ethereum ecosystem by adopting standardized cross-ecosystem interfaces. Existing chains part of the OP Superchain include OP Mainnet, Base, Zora, Mode, Fraxtal, Cyber, Kroma, RedStone, Lisk, and a lot more.
OPLabs has recognized that standards and tools will also need to be provided to enable app developers to move assets and messages between interoperable chains to achieve this mission. You can read more about this [here](https://blog.oplabs.co/solving-interoperability-for-the-superchain-and-beyond/).
 The rise in the number of L2s has produced multiple co-existing chains, most of which solve for Ethereum scalability while balancing trade-offs around decentralization and security. In parallel, these networks have created and fostered diverse communities and ecosystems of applications that provide value and increase adoption.
The multichain world, however, has also brought its own set of challenges related to liquidity fragmentation and poor user experiences. From the developer's perspective, they experience the "cold start" problem of scaling and growing their app, managing costly multichain infrastructure. They also struggle to create smooth app UX due to complex network switching functionalities. Poor UX and high costs create barriers that significantly hinder the overall app adoption rate.
Cross-chain, abstraction, interoperability, and intents are the emerging approaches that aim to serve as critical pieces to solve these current problems.
## What is Brid.gg?
[Brid.gg](http://bridd.gg/) is a bridge interface that aims to revolutionize the way users interact with the OP Superchain. By simplifying access and usability, Bridgg is committed to making Ethereum's technologies more accessible and user-friendly for everyone, currently supporting transactions between Ethereum, OP Mainnet, Base, Zora, Mode Network, Fraxtal, RedStone, and future upcoming OP Chains.
With user experience as a core focus, Brid.gg allows users to view their past and current interactions with supported contracts, giving users a comprehensive single-pane view such as all deposits and withdrawals, so that users no longer need to visit each chain's block explorer.
 *Screenshot of Brid.gg's built-in account history dashboard*
Visit [Brid.gg](http://brid.gg/) directly or find them listed in the [Optimism](https://app.optimism.io/bridge/deposit) and [Base](https://docs.base.org/base-chain/network-information/ecosystem-bridges) docs.
## How Envio Supercharges Brid.gg
The team behind Brid.gg built an impressive multichain indexer using Envio [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview). An important decision in the search for a web3 backend to power their solution was performance, flexibility, and simplicity. Having compared a few solutions to their needs, the team landed on Envio as their weapon of choice.
Brid.gg wanted a solution that simplifies retrieving all the data across the growing list of multiple networks they support. Due to the vast amount of data (e.g. transaction history of deposits and withdrawals across multiple large chains), the team was also seeking a solution that allows indexing the data faster than current solutions available, such as indexers relying on RPC. Having the ability to retrieve historical data quickly, HyperIndex provides faster feedback loops for development, allowing teams to innovate and ship product updates quicker, thereby providing a pleasant developer experience.
HyperIndex has allowed Brid.gg to supercharge its data retrieval by using [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) as its data source instead of using the standard RPC option. Envio's multichain support also allows Brid.gg to aggregate all of its data into a single database, providing Brid.gg with unified data access via a single API and reducing infrastructure footprint and costs. Other indexers require a separate deployment per chain. With Envio, all networks are configured in a single config.yaml.
The Brid.gg [Indexer](https://envio.dev/app/bridgg/bridgg-indexer) currently indexes its data across 12 chains with a collection of 11 million events across the chains.
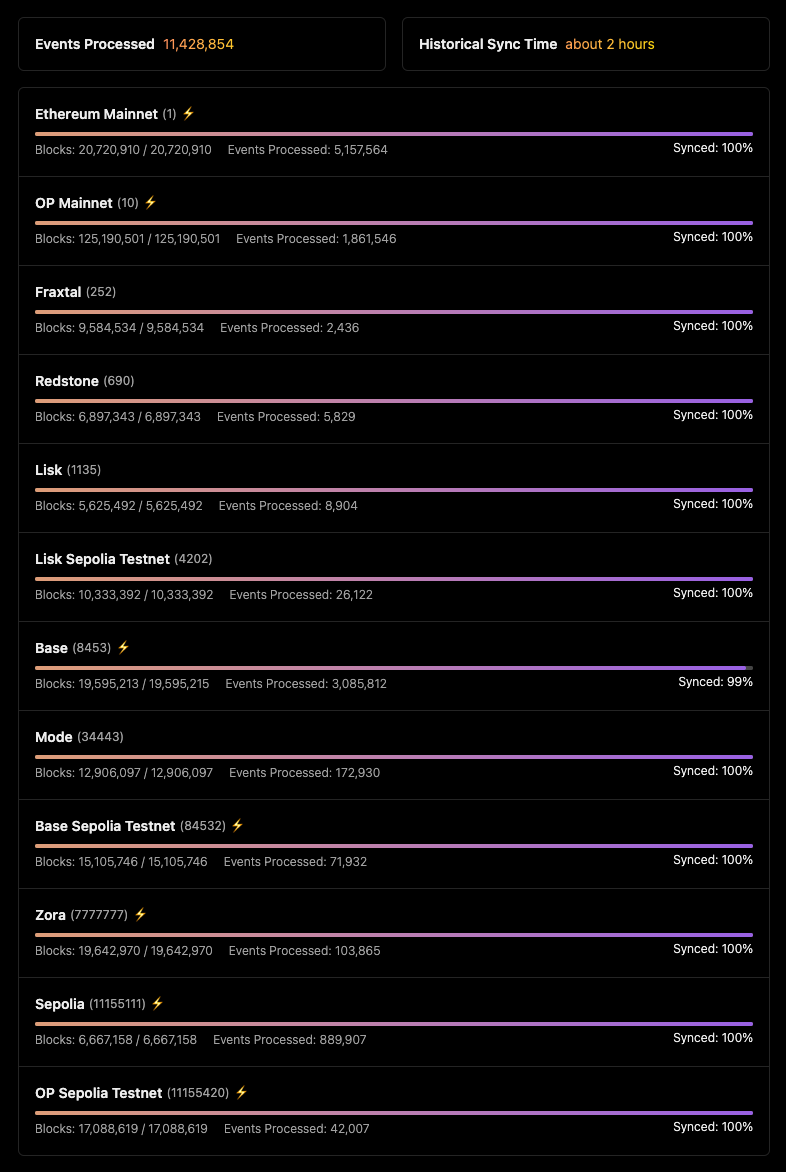 ## How Envio Powers the OP Superchain
Envio supports indexing any EVM-compatible network, using standard RPC as a data source, which means OP-stack chains can be indexed out-of-the-box. Envio has also added HyperSync to 70+ EVM networks to date, serving as an accelerated data query layer and powering many applications deployed on these chains with more performant data access than RPC.
You can see our supported networks [here](https://docs.envio.dev/docs/HyperSync/hypersync-supported-networks).
Examples of amazing applications on the OP Superchain using Envio for their data needs:
- [Velodrome Finance](https://x.com/VelodromeFi), Liquidity Layer, and Multichain Dex on OP Superchain
- [Sablier](https://x.com/Sablier), a token streaming platform on OP, Base, Celo, and more (12+ chains)
- [Limitless](https://x.com/trylimitless), prediction Markets on Base
- [Rhinestone](https://x.com/rhinestonewtf), Modular Smart Accounts on ETH, OP, Base
- [Scope](https://x.com/scope_sh), an AA Block Explorer on ETH, OP, Cyber, Base, Celo, and more (18 chains)
- [ZkPass](https://x.com/zkPass), Onchain Achievements, and Reputation Scoring
These indexers and a lot more can be viewed in the Envio [Explorer](https://envio.dev/explorer).
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# EthOnline 2024 Envio Hackathon Winners
> The winners of EthOnline 2024 where Envio supported 40+ project submissions and $5,000 in bounties for builders shipping onchain indexing solutions.
 [ETHGlobal](https://ethglobal.com/)'s highly anticipated [EthOnline Hackathon](https://ethglobal.com/events/ethonline2024/prizes#envio) has officially concluded. Here are Envio's winners of this year's hackathon. With an impressive 40 project submissions and $5,000 in bounties, selecting the winners was no easy feat. A big shout-out to all the hackers who participated. Let's take a look at our winners!
## Best Use of HyperIndex: Grail Market
[Grail Market](https://ethglobal.com/showcase/grail-market-53egz) is a decentralized, cross-chain prediction platform built on an EVM-compatible blockchain. This innovative application offers a diverse range of prediction markets, including Forex, Crypto, and Stocks. By harnessing the power of [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview), Grail Market aims to revolutionize the way users engage with prediction markets.
By [Ifeanyi Ozanu](https://x.com/iphyman).
 ## Best Use of HyperSync: Know Your Co-Signers
[Know Your Co-Signers](https://ethglobal.com/showcase/know-your-co-signers-k67wi) is an application that provides in-depth statistics and charts for any given multi-signature smart account and its signers. This tool allows users to track and analyze signer behaviors and activities, enhancing the security and transparency of multi-signature transactions.
By [Germán Martínez](https://x.com/germago).
 ## Best Runner-Up for Use of HyperIndex & HyperSync: TornadoTrack
[TornadoTrack](https://ethglobal.com/showcase/tornadotrack-pbupy) is a comprehensive dashboard that allows users to monitor Tornado Cash mixer usage across all chains, utilizing Envio's powerful data indexing capabilities. This project emphasizes the utility of [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) and [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) and showcases the potential for enhanced transparency in decentralized finance.
By [Martin Lettry](https://x.com/MartinLettry)
 ## Most Creative App of Envio's Features: Hypertui
[Hypertui](https://ethglobal.com/showcase/hypertui-dshua) is a terminal UI analytics tool that provides onchain data insights for Ethereum and EVM-compatible chains. This innovative application demonstrates the versatility of Envio's features and encourages developers to explore new ways to interact with blockchain data.
By Falco Rodenburg.
 ## Best Overall Project: ZkDNS
[ZkDNS](https://ethglobal.com/showcase/zkdns-0fo7m) is a privacy-preserving multichain domain resolver that utilizes ZkProofs for enhanced security. This project bridges the gap between Web2 and Web3 through DNS and ENS systems, offering tokenized domains and expedited queries while maintaining user privacy.
By Dhananjay Pa.
 A massive thank you to the EthGlobal team for organizing yet another incredible hackathon! The competition was fierce, with so many outstanding entries. We're grateful for all the hackers who participated and can't wait to see what innovative projects will emerge in the future. Stay tuned for our next hackathon.
## About EthOnline
[EthOnline](https://ethglobal.com/events/ethonline2024/prizes#envio) is a hackathon run by [ETHGlobal](https://ethglobal.com/), where developers dive into bounties set by leading Web3 protocols. It's an opportunity to connect with fellow builders, tackle real-world problems, and experiment with emerging decentralized tools. These bounties provide the chance to push boundaries, encouraging hackers to rethink infrastructure, enhance transparency, and contribute to the evolution of decentralized solutions. EthOnline serves as an ideal platform for collaboration and making a meaningful impact across the ecosystem.
[X](https://x.com/ETHGlobal) | [Discord](https://discord.gg/ethglobal)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update October 2024
> What Envio shipped in October 2024: new releases, platform enhancements, and community integrations across the blockchain indexing stack.
 Welcome to our October 2024 developer update. This month, we're spotlighting our integrations with MIRA Exchange and Gateway.fm, along with our recent success at the Encode hackathon, where the ModuleScan project stood out. Let's dive in!
## HyperIndex Version 2.6.0 is now available
We are pleased to announce that the current release is **v.2.6.1**!
**Improvements:**
- feat: prompt for start block on RPC URL networks in contract import
- Improve contract import to stop asking for API keys
- Improve crash error
- Add mainnet selection in Fuel contract import
- Improve Batch Set error
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) in the Envio github.
To stay updated with our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)! Your support is greatly appreciated!
## Dynamic Contract Pre-registration
You can now add the **preRegisterDynamicContracts** flag to your event configuration. For events with this flag enabled, the indexer will perform an end-to-end run specifically for these events, executing all relevant **contractRegister** functions to collect dynamic contract addresses. The indexer will then restart with these addresses from the start block configured for the network, rather than from the block where each contract is registered. This approach drastically reduces indexing time for standard factory contract setups, minimizing the need for multiple small block range queries in favor of larger, grouped queries. See the example below.
```typescript
PoolFactory.CreatePool.contractRegister(
({ event, context }) => {
context.addPool(event.params.pool);
},
{ preRegisterDynamicContracts: true },
);
```
> **Update:** The `preRegisterDynamicContracts` option was deprecated in version `2.19.0` because default contract registration became significantly faster. You no longer need to enable pre-registration explicitly.
## Envio Powers Developers on Fuel Ignition
 Envio is proud to support applications and developers with the fastest access to real-time and historical data on the [Fuel](https://fuel.network/) Network.
Learn which [Fuel applications](https://x.com/envio_indexer/status/1849103562602655890) we are supporting to date.
## Exciting DeFi Integration with MIRA
 Envio's efficient indexing solution has been integrated with [MIRA](https://mira.ly/), an open-source DeFi platform designed to match traders and liquidity providers using the most efficient AMM on the Fuel Network.
This integration enhances the capabilities of MIRA by providing faster and more reliable access to onchain data, ensuring a seamless experience for all users.
## Envio Powers GatewayFM With Efficient Indexing
 Envio's modular data indexing solution powers [Gateway](http://gateway.fm/), a pioneering Web3 infrastructure provider. With Gateway, you can deploy zkEVM app rollups in minutes, code-free! With Envio's native support for indexing any EVM-compatible chain, this makes a fruitful partnership.
## Can We Really Predict the Future?
 Congratulations to ModuleScan for winning multiple prizes at the Encode hackathon! This innovative indexer tracks historical smart account module activity, showcasing:
- Recently deployed accounts
- Installed and uninstalled modules
- Historical activity for modules and accounts
Using both [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) and [HyperSync](https://docs.envio.dev/docs/HyperSync/overview), ModuleScan delivers some seriously powerful insights.
Explore ModuleScan:
- [Codebase](https://github.com/Destiner/modulescan)
- [YouTube Demo](https://www.youtube.com/watch?v=Jp2jQOioSmk&feature=youtu.be)
We're proud to award ModuleScan:
- Best Use of HyperIndex: $1,500
- Most Creative Application of Envio's Features: $1,000
Kudos to [Timur Badretdinov](https://x.com/DestinerX)!
## Highlights from Zebu Live & Encode London
 We had a fantastic time at [Zebu Live](https://www.zebulive.xyz/) and the Encode London Hackathon & Conference! At both events, we hosted data indexing workshops where blockchain developers could explore faster, smarter ways to access their onchain data, demonstrating how alternative indexers like Envio can improve their data retrieval.
Additionally, we sponsored $4,500 in bounties at the Encode London Conference, encouraging developers to engage with our platform and showcase their skills. A massive thank you to the organizers and to everyone who attended our workshops and participated in our bounties.
For more upcoming events and where to catch us - be sure to check out our upcoming events below.
## Upcoming Events
- [DevCon](https://devcon.org/en/): 12-17 November 2024
- [EthGlobal Bangkok](https://ethglobal.com/events/bangkok): 15-17 November 2024
- [Rootstock Educate: Why Is Blockchain Data So Slow? How to Get It Fast on Rootstock](https://lu.ma/e0514_3111?tk=wnw72A&utm_source=yve8mz) - 10 December 2024
## Featured Developer
 This month's featured developer and community member of the month is [Ankush Jha](https://www.noveleader.xyz/), a dedicated developer and crypto native with three years in the space. Known for his sharp research skills and innovative approach, Ankush has made significant contributions to our community as a developer and researcher.
***"Envio is an amazing product. What I like the most about them is their blazing-fast indexing speed. I've never had an experience like this" – Ankush Jha***
Ankush developed a GMX V2 multichain indexer spanning Arbitrum and Avalanche, where GMX data can be queried via a unified API. The code repo is available on [GitHub](https://github.com/Noveleader/gmx-v2-subgraph-envio).
Be sure to check out Ankush's work on [GitHub](https://github.com/noveleader) to stay up-to-date with their latest projects and contributions.
For a full list of deployed indexers visit our [explorer](https://envio.dev/explorer).
## Playlist of the Month
[Open Spotify](https://open.spotify.com/playlist/50pryGy4bfJfqAVKZAojNh?si=19a115a6742e4292)
 ## Envio Freelancer Network
Need an indexer but don't have the bandwidth? Whether you're looking to find top-notch freelancers or you're a freelancer seeking new opportunities, we've got you covered. Our thriving Freelancer Network connects skilled contractors with Web3 protocols to service their data needs.
Simply fill out the [form](https://noteforms.com/forms/envio-freelancer-network-u9zqbv) to join our freelancer network.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Introducing Envio Cloud: 10x Faster Indexer Deployments
> Envio Cloud launched November 2024 with 10x faster build and deployment speeds, improved performance, and zero infrastructure overhead for blockchain indexers.
 :::note TL;DR
- Envio Cloud launched on November 6th, 2024, with 10x faster build and deployment times, improved UI/UX, and direct database connection access.
- All new deployments automatically route to Envio Cloud via a GitHub-push deployment model.
- This post covers the original launch. For current setup, plans, and pricing, see the [Envio Cloud docs](https://docs.envio.dev/docs/HyperIndex/hosted-service).
:::
This is the original launch announcement for Envio Cloud, published November 6th, 2024. For the most up-to-date information on getting started, plans, and pricing, see the [Envio Cloud documentation](https://docs.envio.dev/docs/HyperIndex/hosted-service).
## What launched with Envio Cloud
- 10x faster build and deployment times
- Faster indexing speeds
- Improved UI/UX
- Access to direct database connections, IP address whitelisting, and advanced analytics
- Increased flexibility, improved reliability, and reduced costs behind the scenes
## About Envio Cloud
[Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service) is the managed infrastructure layer for running HyperIndex indexers in production. With the Envio Deployments GitHub app, you configure and manage your indexers directly from your repository. Push to the `envio` branch and Envio handles the rest, including infrastructure provisioning, scaling, and uptime.
Plans range from a free development tier (3 indexers per organization) to paid production plans with static endpoints, built-in alerts, and SLA guarantees. For full pricing details, see the [Pricing and Billing page](https://docs.envio.dev/docs/HyperIndex/hosted-service-billing).
Deployment on Envio Cloud requires at least Envio version `2.21.5`. See the [deployment docs](https://docs.envio.dev/docs/HyperIndex/hosted-service-deployment) for setup steps.
## Frequently asked questions
### What is Envio Cloud?
Envio Cloud is Envio's managed hosting platform for HyperIndex indexers. It handles infrastructure, scaling, and monitoring so you can run indexers in production without managing operational overhead.
### How do I deploy to Envio Cloud?
Connect the Envio Deployments GitHub app to your repo, then push to the `envio` branch. Envio Cloud picks up the push and deploys automatically. See the [deployment guide](https://docs.envio.dev/docs/HyperIndex/hosted-service-deployment) for a full walkthrough.
### What plans are available on Envio Cloud?
Envio Cloud offers a free development plan (3 indexers per organization) for testing and development, and paid production plans with static endpoints, alerts, and SLA guarantees. See the [Pricing and Billing page](https://docs.envio.dev/docs/HyperIndex/hosted-service-billing) for a full comparison.
### What is the minimum Envio version required for Envio Cloud?
Deployment on Envio Cloud requires at least version `2.21.5`. Always check the [deployment docs](https://docs.envio.dev/docs/HyperIndex/hosted-service-deployment) for the current requirement.
### Where can I get help with Envio Cloud?
Join the [Discord](https://discord.gg/envio) for support, or reach out via an existing connection for production plan inquiries.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Optimizing Blockchain Indexers on AWS
> Learn how to optimize your blockchain indexer on AWS using smarter infrastructure planning and scaling techniques to cut costs and improve performance.
 :::note TL;DR
- Running blockchain indexers on AWS has three main cost drivers: networking (NAT Gateway, cross-AZ data transfer), compute (instance sizing, spot instances), and storage (RDS vs Aurora I/O-Optimized).
- Practical strategies like single-AZ deployment, Bottlerocket OS, and Aurora I/O-Optimized can cut costs significantly without sacrificing reliability.
- These are the same optimizations Envio uses internally to power its Hosted Service, so teams using Envio Cloud get these benefits without configuring them manually.
:::
When running any application on cloud infrastructure, one of the first questions that comes up is: where did all the money go? In the [AWS](https://aws.amazon.com/) ecosystem, expenses like hidden EC2 charges, complex data transfer costs, or the confusing [Aurora pricing model](https://aws.amazon.com/rds/aurora/pricing/) can quickly add up.
Whether you are running Envio's [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) on your own AWS setup or are curious about how Envio optimizes cloud resources to deliver its Hosted Service, this guide walks through practical techniques to maximize your blockchain indexer's performance while keeping costs as low as possible.
## Challenges of running indexers on AWS
Understanding these challenges helps you prepare and optimize your setup effectively:
- **Cost management**: Navigating AWS pricing is complex. Hidden charges, especially for data transfer and compute, can lead to unexpected bills if not carefully monitored.
- **Configuration complexity**: Setting up an efficient architecture requires a solid understanding of AWS services. Misconfigurations lead to increased costs and reduced reliability.
- **Performance tuning**: Indexers handle fluctuating workloads. Balancing performance with cost-effectiveness requires constant monitoring and adjustments.
- **High availability**: Achieving true high availability without significant costs requires careful trade-offs between cost and redundancy.
- **Data management**: As indexers scale, managing large volumes of data efficiently becomes critical for maintaining performance while keeping costs low.
## The costs of running an indexer
The cost of running an indexer breaks down into three key areas:
### 1. Networking
**Avoid NAT Gateway**
At the core of every indexer is fetching data from external sources (like HyperSync or an RPC provider) and indexing it into a storage layer (PostgreSQL). If you are running your indexer in an AWS private subnet, network traffic passes through a NAT Gateway, costing $0.045/GB (US-East) for both requests and responses.
Think of a NAT Gateway as a hotel doorman: it handles your packages and ensures your privacy, but it comes at a cost. If you have carefully assessed your security needs and set up proper security groups, running your indexer in a public subnet is a perfectly acceptable option. In that case, you can bypass the NAT Gateway entirely and use an Internet Gateway, allowing communication with the outside world without the added cost of NAT traffic.
**Transferring data within a region**
When deploying an indexer in [Kubernetes](https://kubernetes.io/) (EKS) or on an EC2 instance, it is easy for your indexer and storage layer to end up in different availability zones (AZs). AWS charges $0.01/GB (US-East) for data transferred between AZs, both in and out. To minimize costs, deploy both your indexer and storage layer within the same AZ.
You might wonder: does this compromise high availability? Somewhat. If one AZ goes down, both your indexer and storage layer go down together. But since these two components are tightly coupled, if one fails the other is effectively unusable anyway.
For true HA with low costs, consider AWS Aurora. Aurora replicates data across multiple AZs at no extra cost (baked into Aurora's pricing), and your indexer can connect to an Aurora instance within its own AZ. If one AZ fails, your indexer can redeploy in another AZ where another Aurora instance is ready.
### 2. Compute
Figuring out the right amount of compute power for your indexer requires balancing two distinct phases. When first deployed, your indexer processes historical data. Once caught up, it only needs to handle real-time indexing. The compute resources required for these two stages are quite different: historical indexing demands more resources while real-time indexing requires less.
To optimize costs, use different EC2 instance types for each stage. Start with a larger, more powerful instance to process historical data as quickly as possible, then switch to a smaller, cheaper instance once you are caught up. Since AWS charges by the hour, find the smallest instance that can sync historical data quickly enough, then downsize for real-time indexing.
**Spot instances**
[Spot instances](https://aws.amazon.com/ec2/spot/) can save up to 90% on EC2 costs. They are unused EC2 capacity offered at a discount but can be terminated when AWS needs the capacity. For HyperIndex indexers, which are stateless by nature, this is less of an issue since moving an indexer from one instance to another is straightforward. If staying close to real-time is critical, the interruptions of spot instances may be a headache.
**Using Bottlerocket OS for EC2 instances**
One way to minimize downtime when using spot instances, especially if running your indexer in [EKS](https://aws.amazon.com/eks/), is to use [Bottlerocket OS](https://aws.amazon.com/bottlerocket/) for your EC2 instances. Bottlerocket is a lightweight, container-optimized operating system that boots up much faster than Ubuntu or Amazon Linux. By using Bottlerocket, you can significantly cut downtime when a spot instance gets replaced. Since it is lightweight, more of your resources are dedicated to the indexer itself.
Tip: when using spot instances with tools like EKS and Karpenter, specify as many EC2 instance types as possible. If one type runs out of spot capacity, Karpenter can try another before falling back to an on-demand instance.
### 3. Storage
When hosting indexers on AWS, your primary options for PostgreSQL are AWS RDS and Aurora.
**IOPS**
Indexers are high-IOPS applications that handle a relentless stream of inserts and updates, meaning they need a storage solution that can support high IOPS. Serverless options will not cut it for indexers, as they cannot manage the constant load.
For indexers on Aurora, Aurora I/O-Optimized is worth considering. Released in May 2023, this configuration eliminates IOPS charges, allowing you to avoid significant I/O costs that can make up 50% of expenses on standard Aurora. By switching to Aurora I/O-Optimized, you effectively get unlimited IOPS. The higher storage costs are offset by the elimination of per-IOPS billing, making it a more predictable and potentially cheaper option for high-I/O workloads.
**Storage requirements**
With RDS, you provision storage upfront, which can lead to over-provisioning. Aurora offers a pay-as-you-go storage option that scales automatically as your data grows. This flexibility can result in significant savings, especially when dealing with historical indexing or unpredictable storage growth.
**Resource requirements**
A key component of Aurora is its separation of compute and storage. Unlike RDS, where storage is tightly coupled with compute, Aurora allows you to scale these independently. This is particularly useful when your indexer's compute and storage requirements fluctuate at different stages of the indexing process.
In short: since indexers are high-I/O applications that scale up and down over time, Aurora I/O-Optimized can provide significant cost savings while delivering the performance you need. RDS remains a more affordable option for smaller indexers or a more hands-on approach to storage management.
## Conclusion
Running indexers on AWS does not have to be expensive. By understanding the key cost drivers in networking, compute, and storage and using the right AWS tools and configurations, you can significantly reduce your cloud bill while maintaining high performance. Whether you are optimizing your network with a single-AZ setup or taking advantage of spot instances for compute savings, there is always a smart way to balance performance and cost.
These are the same optimizations Envio uses to power its Hosted Service. Teams using Envio Cloud get these benefits automatically, without needing to configure them manually.
## What is AWS?
AWS (Amazon Web Services) is a cloud computing platform providing on-demand services including computing power, storage, and networking. It allows businesses to scale their infrastructure without owning physical servers, offering flexibility and cost efficiency. Whether you are running a simple website or a complex application like a blockchain indexer, AWS helps you manage resources while paying only for what you use.
## Frequently asked questions
### Should I run my blockchain indexer in a public or private AWS subnet?
For most indexers, a public subnet with well-configured security groups is a perfectly acceptable and cost-effective option. It avoids NAT Gateway charges ($0.045/GB) while still maintaining security through security groups. Private subnets add privacy but add cost and complexity that may not be justified for an indexer.
### Is Aurora always cheaper than RDS for blockchain indexers?
Not always, but for high-IOPS indexers Aurora I/O-Optimized is typically more cost-effective. Standard Aurora and RDS charge per I/O operation, which adds up fast for indexers doing constant inserts and updates. Aurora I/O-Optimized eliminates per-IOPS billing in favor of higher storage costs, which is usually a net win for indexing workloads.
### Can I use spot instances for a production blockchain indexer?
Yes, with caveats. HyperIndex indexers are stateless, so recovering from a spot termination is straightforward. If you need to stay as close to real-time as possible, spot interruptions may cause brief gaps. Using Bottlerocket OS and specifying multiple instance types in Karpenter minimizes downtime when instances are replaced.
### How does Envio's hosted service compare to self-managing on AWS?
Envio's Hosted Service applies the same optimizations described in this post (single-AZ networking, Aurora I/O-Optimized, Bottlerocket OS on EKS) internally. Self-managing on AWS gives you more control but requires engineering time to configure and maintain these optimizations yourself. For most teams, the hosted service is faster and cheaper to operate.
### What is the biggest hidden cost when running indexers on AWS?
NAT Gateway charges and cross-AZ data transfer fees are the most commonly overlooked costs. A single indexer processing large volumes of HyperSync data through a NAT Gateway can generate hundreds of dollars per month in transfer fees. Deploying in a public subnet or consolidating your indexer and database in the same AZ eliminates most of this cost.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Indexing and Reorgs
> Learn how Envio handles blockchain reorgs to maintain data accuracy and consistency when indexing onchain events across multiple networks.
Author: [Denham Preen](https://x.com/DenhamPreen), Co-Founder at Envio
 :::note TL;DR
- Chain reorganizations (reorgs) affect any indexer processing data near the chain head. Stateful indexers (those using updates and deletes) require rollback logic. Stateless ones (create-only) just need orphaned entities deleted.
- Multichain indexers face additional complexity: a reorg on one chain may require rolling back state that was affected by events from other chains.
- Envio handles reorg detection and rollback automatically, so developers do not need to implement rollback logic themselves.
:::
In this article, we unpack the implications of chain reorganizations on consuming and aggregating onchain data, considerations in a multichain environment, and how to design for them.
We assume you have a strong understanding of what a chain reorganization is. If you want a refresher, skip to the [bottom](#what-are-chain-reorgs).
> Note: Handling reorgs is only important if you are indexing at the head, or handling data within the range of the head and the network's finalized block.
## Chain reorgs and independent data
Independent data is data that **does not require the previous state in order to process the current state**. In an indexer, this means only "create" operations. If the only CRUD operations your handlers perform are writing entities, your indexer is handling stateless data, and handling reorgs is straightforward: delete all entities from orphaned blocks and re-ingest them with the canonical block's data. This is possible because stateless data allows for parallel processing.
In practice, we usually need to perform some aggregation on data to turn it into meaningful information. In that context, our indexer is dealing with stateful data.
> Side tangent: Stateless indexing can be handled incredibly fast by parallelization, such as indexers like [Flair](https://flair.dev) that achieve impressive speed with only RPC.
## Chain reorgs and stateful data
Stateful data is data that **depends on the previous state** (think update and delete operations) in order to process the current state. When handling stateful data, your indexer needs to account for the current state of entities, and reorgs become notably more complex.
During a chain reorg, rather than simply replacing orphaned data, you need to **revert previous operations or changes** and ensure that the entity state is rolled back correctly. This requires tracking the history of changes to each entity so that when a reorg occurs, you can accurately undo or adjust state based on the adopted canonical chain's data.
> Note: We can periodically prune the entity history, retaining only the changes relevant to unfinalized blocks.
## Reorgs and multichain indexing
When it comes to multichain indexing, we face additional complexity because we process events from multiple sources that interact and update the same entity state. When one chain undergoes a reorg, we need to roll back the state to a known correct point and reprocess any events from all chains that affected the state after the reorg on the affected chain.
## Reorgs in the wild
In practice, different networks exhibit varying levels of exposure to reorgs based on their design. Some networks, like Base and the [OP stack](https://x.com/ShivanshuMadan/status/1811492866818212024), are largely reorg-resistant with block finality occurring at the head, though [exceptions](https://optimistic.etherscan.io/blocks_forked) do exist. On the other hand, networks like Polygon frequently experience deeper reorgs, where forked chains can extend over 10 blocks deep. One notable instance involved a reorg of [157 blocks](https://forum.polygon.technology/t/157-block-reorg-at-block-height-39599624/11388). Both [Etherscan](https://etherscan.io/blocks_forked) and [Blockscout](https://gnosis.blockscout.com/blocks?tab=reorgs) provide data on reorg occurrences. According to Ethereum Mainnet Etherscan, roughly 1% of blocks undergo reorgs, meaning that, assuming a 50/50 chance of a transaction being included in either the orphaned or canonical chain, about 1 in 200 transactions is likely to be in a reorged block.
## Conclusion
Reorgs are a crucial consideration in blockchain indexing. Understanding their implications and designing with flexibility allows you to properly account for them in your indexer. Envio handles reorg detection and state rollback automatically, so developers building on HyperIndex get correct data at the head without needing to implement rollback logic themselves.
 ### Chain
A series of sequential blocks.
 ### Miners
Actors that try to submit the next valid block.
 ### Chain fork
 A chain fork occurs when more than one miner submits a valid block at the same time, causing a split where two valid chains exist simultaneously.
### Orphaned chain and canonical chain
 When a chain forks, eventually one chain becomes accepted as the valid chain, known as the canonical chain. The forked chain that is not accepted becomes the orphaned chain. Orphaned blocks cease to exist, and transactions that occurred in those blocks cease to exist as well.
* **Orphaned chain**: The forked chain that is dropped
* **Canonical chain**: The chain adopted as the valid chain
> Info: We do not know which fork will be orphaned and which will become canonical until after the fact.
### Block finality
The minimum number of blocks needed to confirm that blocks will not become part of an orphaned chain.
> Info: Block finality is the reason bridges and centralized exchanges require a confirmation delay after a transaction is confirmed, to ensure blocks will not become orphaned.
### Reorg
A reorg is a set of events that results in a chain rolling back to a previous point in time.
## Frequently asked questions
### Does every blockchain indexer need to handle reorgs?
Not necessarily. If your indexer only processes finalized blocks (past the finality threshold), reorgs are not a concern. Reorg handling is only important if you are indexing at the head or within the range between the head and the network's finalized block.
### What is the difference between stateless and stateful indexing in the context of reorgs?
A stateless indexer only creates new entities. On a reorg, you delete orphaned entities and re-ingest from the canonical chain. A stateful indexer also updates and deletes entities based on previous state, which requires tracking the history of changes so that state can be accurately rolled back when a reorg occurs.
### Which networks experience the most frequent or deepest reorgs?
Polygon is known for frequent and sometimes deep reorgs (a 157-block reorg has been recorded). Base and OP stack chains are largely reorg-resistant due to single-slot finality. Ethereum mainnet sees roughly 1% of blocks affected by reorgs. Networks with faster block times and probabilistic finality tend to have more reorg activity.
### How does Envio handle reorgs automatically?
Envio HyperIndex tracks entity state history for all unfinalized blocks. When a reorg is detected, it rolls back entity state to the correct point and reprocesses events from the canonical chain. This happens automatically and does not require any custom rollback logic in your event handlers.
### How do reorgs affect multichain indexers?
In a multichain indexer, events from multiple chains may update the same entity. If one chain reorgs, any state changes that depended on post-reorg events from that chain must also be rolled back and reprocessed, even if those changes involved events from other chains. This makes multichain reorg handling significantly more complex than single-chain reorg handling.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update November 2024
> Catch the latest from Envio in November 2024 including platform enhancements, key releases, and community milestones advancing our blockchain indexing solution.
 Welcome to our November 2024 update.
This month, we rolled out v2.9.0, launched our V2 Hosted Service, and celebrated new integrations with Swaylend, Tangle, and more. We also added fresh network support to HyperSync, shared our top AWS cost-saving strategies, and published a Fuel tutorial for building production-ready apps. Plus, we'll cover some highlights of our time at DevCon and ZuThailand. Let's dive in!
## HyperIndex Version 2.9.0 is now available
We're pleased to announce the release of **v.2.9.0**!
**Environment Variables in the config file:**
The Envio config file now supports Environment Variables for greater flexibility. Instead of editing the config file every time, you can quickly switch configurations by setting Environment Variables at runtime.
Note: Hosted Service users can now set custom Environment Variables.
Example:
```
networks:
- id: ${ENVIO_CHAIN_ID:-137}
start_block: ${ENVIO_START_BLOCK:-45336336}
contracts:
- name: Greeter
address: ${ENVIO_GREETER_ADDRESSES}
```
Run the following command to set the variables:
```
ENVIO_GREETER_ADDRESSES=0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c pnpm dev
```
Alternatively, you can set values via the `.env` file or the Hosted Service indexer settings page.
**Interpolation Syntax:**
To apply interpolation, use the following formats for Environment Variables:
* Direct substitution: `${VAR}` → value of `VAR`
* Default value: `${VAR:-default}` → value of `VAR` if set, otherwise `default`
* Alternative default: `${VAR-default}` → value of `VAR` if set, otherwise `default`
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)! Your support means the world to us!
## Our V2 Hosted Service is Here!
 Our V2 Hosted Service has arrived! It's a significant upgrade that brings you faster build times, enhanced features, and an overall smoother experience.
All new deployments moving forward will now automatically use V2, offering:
* 10x faster build and deployment times
* Faster indexing speeds
* Improved UI/UX
* New features like direct database connections and advanced analytics
V2 also enhances flexibility, reliability and reduces costs. We're offering all existing V1 users a 50% discount on any production plan with a 6-month commitment to celebrate this milestone.
For more details, check out our [FAQs](https://envio-dev.notion.site/V2-Hosted-Service-Transition-and-FAQs-12faf438121380c98ec7f7626c9f9f83).
## Exciting De-Fi Integration with Swaylend
 Envio's efficient indexing solution has been integrated with Swaylend, a lightning-fast & low-cost lending platform. We're pleased to integrate and power real-time insights for the smoothest crypto lending experience on the Fuel Network.
This integration elevates Swaylend's functionality by delivering efficient access to onchain data, creating a smooth experience for their users.
## Lightning-Fast Data Retrieval Now Supported on Tangle & More!
 Build, deploy, and monetize decentralized services effortlessly with Tangle - your gateway to the next era of restaking cloud infrastructure. HyperSync enables applications and data analysts to retrieve data through standard RPC or unlock up to 1000x faster performance with its advanced capabilities. Together, this integration drives innovation, simplifies development, and delivers unmatched performance for users.
Other new networks that were added to HyperSync this month include:
* B2 Testnet
* Galadriel Devnet
* Lisk
* Morph
* opBNB
* Sophon
* Unichain Sepolia
View all current HyperSync-supported networks in our [docs](https://docs.envio.dev/docs/HyperSync/hypersync-supported-networks).
## Optimizing AWS for Indexer Performance: Strategies to Lower Cloud Costs
 Reducing AWS costs doesn't have to come at the expense of performance. By optimizing your network and fine-tuning infrastructure, you can maintain smooth indexer operations while staying within budget.
Explore our tips for smarter, more efficient AWS spending in our latest [blog](https://docs.envio.dev/blog/cut-aws-cloud-costs).
## Dev Tutorial: Building Decentralized Applications on Fuel
 In our new Fuel tutorial, we guide you through the process of building and deploying a smart contract on a testnet, starting with the fundamentals of Fuel. We then dive into Fuel's internals and show you how to use Envio to set up a backend indexer, making your app production-ready.
This tutorial is perfect for devs looking to leverage Fuel and Envio to create scalable Web3 applications - check it out on our [YouTube](https://www.youtube.com/watch?v=iikIUP-T7ro&t=13s) channel!
## Highlights from DevCon & ZuThailand
 We had an incredible time at [Devcon](https://devcon.org/en/) 2024 in Bangkok! Envio had the pleasure of co-hosting the [Data & Chill Café](https://lu.ma/w84y3q08) side event, bringing together top builders from around the world spanning data, analytics, indexing, block explorers, and more.
It was a great opportunity to network and discuss the future of blockchain data and more. Huge thanks to Noves and [growthepie](https://www.growthepie.xyz/) for being fantastic co-hosts, and to everyone who joined us.
After Devcon, the Envio team continued the momentum at [ZuThailand](https://www.zuthailand.com/), a one-month pop-up city experiment for 300+ deeply technical, curious, and self-driven builders. It was an exciting opportunity to engage with a vibrant community of innovators, share knowledge, and explore the future of decentralized technologies.
To stay updated on our upcoming events and where to find us next, check out the schedule below!
## Upcoming Events
* [Rootstock Educate: Why Is Blockchain Data So Slow? How to Get It Fast on Rootstock](https://lu.ma/e0514_3111?tk=wnw72A&utm_source=yve8mz) - 10 December 2024
## Featured Developer
 This month's featured developer and community member is Chris Koo, a talented developer and crypto enthusiast known for his contributions to the DeFi space. Chris created the [Salt Dex Indexer](https://v2.envio.dev/app/hashscape/salt-dex-indexer-prod), which indexes Uniswap V2 and V3 across all EVM chains, enabling users to easily access decentralized trading through Salt - an all-in-one trading service that connects over 30 chains and all major DEXs, allowing you to trade newly created tokens quickly and securely.
***"Envio Indexer's speed comes from its amazing team. They love solving problems and keep pushing themselves to find better solutions. That's how Envio stays the top indexer." – Chris Koo***
Explore the full list of deployed indexers in our [explorer](https://v2.envio.dev/explorer).
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/0AWh4ltYv86dIgdw44tCip?si=b2f8de47dba14ca8)
## Envio Freelancer Network
Need an indexer but don't have the bandwidth? Whether you're looking to find top-notch freelancers or you're a freelancer seeking new opportunities, we've got you covered. Our thriving Freelancer Network connects skilled contractors with Web3 protocols to service their data needs.
Simply fill out the [form](https://noteforms.com/forms/envio-freelancer-network-u9zqbv) to join our freelancer network.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data ([Sentio benchmark, May 2025](https://github.com/enviodev/open-indexer-benchmark)). If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Tokenizing Real World Assets: Real Estate on the Blockchain
> Discover how tokenized real world assets enable fractional real estate investment with lower barriers, global access, and transparent onchain ownership.
 :::note TL;DR
- Tokenized real-world assets (RWAs) convert physical property into blockchain tokens, enabling fractional ownership, global access, and liquid markets for real estate.
- Blocksquare uses Envio's indexing infrastructure to power its DeFi platform and marketplace, indexing over 400,000 Ethereum Mainnet events in under 20 minutes.
- Envio replaced The Graph for Blocksquare, delivering faster indexing, better developer experience, and a more responsive data backend for their onchain real estate platform.
:::
Real estate has long been considered a reliable investment, yet entry barriers have traditionally been high. High costs, complex ownership models, and limited liquidity have made the market inaccessible to many. Blockchain technology is changing this by enabling the tokenization of real-world assets (RWAs), making property investment more accessible, transparent, and liquid. Real estate is expected to become the largest type of tokenized asset by 2030, with the tokenized real estate sector estimated to reach close to $30 billion by 2034, according to Blocksquare.
## What is an RWA?
A Real-World Asset (RWA) refers to any physical asset with intrinsic value in the real world, such as property, commodities, or art. These assets have long been the foundation of wealth accumulation, but the traditional processes for transferring and investing in them have been complex, costly, and inefficient. Blockchain technology changes this by enabling the creation of digital representations of RWAs, making them easier to trade, fractionalize, and own.
## How do tokenized RWAs work?
Tokenization involves converting a physical asset into a digital token on a blockchain, representing a fraction of the asset's ownership. In the case of real estate, tokenized RWAs are blockchain-based tokens that represent a stake in a property or collection of properties.
This process allows investors to buy, sell, and trade ownership stakes in real estate with ease. Each token represents a specific portion of ownership in the underlying property, providing access to borderless real estate markets that were previously inaccessible due to high capital requirements or jurisdictions. These tokens can be traded on blockchain platforms, increasing liquidity and offering flexibility in a traditionally illiquid market. Protocols like Blocksquare are at the forefront of this shift, bridging traditional real estate with blockchain technology.
## What is Blocksquare?
[Blocksquare](https://blocksquare.io/) is a blockchain platform that enables businesses to tokenize real estate, bridging the gap between traditional property investment and blockchain innovation. The platform provides the tools necessary for businesses to tokenize property values, launch marketplace platforms, and connect stakeholders to opportunities in tokenized real estate.
At the heart of Blocksquare is [Oceanpoint](https://oceanpoint.fi/), a DeFi platform where users can stake real estate-backed tokens, earn rewards, and participate in a growing ecosystem of tokenized properties. Powered by the BST utility token, Oceanpoint makes property investment more accessible, transparent, and efficient.
 *Screenshot of [Oceanpoint's Real Estate Marketplace](https://marketplace.oceanpoint.fi/oceanpoint/marketplace)*
## Why RWAs matter
Tokenizing real estate brings several benefits beyond traditional property investment:
* **Lower barriers to entry**: Fractionalizing property ownership lets individuals invest with smaller amounts of capital rather than buying entire properties.
* **Liquidity**: Tokenized real estate can be traded, making it much more liquid than traditional real estate investments, which often require years to realize returns.
* **Transparency**: Ownership records are transparent, tamper-proof, and easily verifiable, reducing the risk of fraud or disputes.
* **Global access**: Investors from around the world can participate in tokenized real estate markets, democratizing access to property investments that were previously limited to local investors or large institutions.
## Envio's role in powering Blocksquare's ecosystem
Envio plays a crucial role in powering Blocksquare's infrastructure, ensuring the seamless operation and scalability of tokenized real estate. What started as a community-driven initiative for Blocksquare evolved into a strong partnership, with Envio's blockchain indexing solution now fully integrated into their ecosystem.
By leveraging Envio's indexing infrastructure, Blocksquare benefits from real-time data retrieval, enhanced data management, and improved efficiency. Envio's platform aggregates data into a unified database, streamlining the process of tracking ownership and transactions while reducing infrastructure costs and latency.
***"Envio is really onto something. Their tech is fascinating, and the developer experience is unparalleled. After years of working with The Graph, it's refreshing to see new players like Envio pushing the boundaries. The team is responsive, innovative, and a pleasure to work with."*** - Simon Kruse, Head of Web3 Development and Governance Board Member at Blocksquare
Envio optimizes performance significantly, enabling the indexing of over 400,000 Ethereum Mainnet events in under 20 minutes, a task that previously took hours with The Graph. This gives web3 developers significantly faster access to onchain data, speeding up development and testing cycles and ensuring scalable data access as applications grow.
 Envio's integration allows Blocksquare to power its DeFi platform and marketplace with a performant backend that stores important data points such as available liquidity and asset pools, token investment listings, APY calculations, token holders, transaction history, supply information, and any other data points of interest.
## Conclusion
As the industry continues to evolve, tokenized RWAs will likely become a dominant force in real estate investment, democratizing access to property markets and offering new opportunities for investors worldwide. Blocksquare demonstrates how blockchain can reshape the real estate sector, unlocking the potential of tokenized assets for a more inclusive and innovative future in property investment.
## Frequently asked questions
### What is a tokenized real-world asset (RWA)?
A tokenized RWA is a digital token on a blockchain that represents fractional ownership of a physical asset such as real estate, commodities, or art. Each token corresponds to a specific share of the underlying asset, enabling investors to buy, sell, and trade ownership stakes without needing to purchase the entire asset.
### How does Envio's indexing help a tokenized real estate platform like Blocksquare?
Envio HyperIndex processes onchain events (such as token transfers, staking actions, and liquidity updates) in real time and stores them in a structured database accessible via GraphQL. For Blocksquare, this means their DeFi platform can display live APY calculations, token holder counts, and transaction history without the latency or cost overhead of querying an RPC node directly or using a slower indexer like The Graph.
### Why did Blocksquare switch from The Graph to Envio?
The Graph requires a separate subgraph for each chain and has slower historical sync speeds. Envio uses a single config to cover all chains, delivers up to 2000x faster historical data retrieval via HyperSync, and offers a more responsive developer experience. Blocksquare's engineering team noted that the switch resulted in indexing 400,000+ events in under 20 minutes, versus hours on The Graph.
### Is tokenized real estate legally recognized?
Legal recognition varies by jurisdiction. Tokenized real estate platforms typically operate within existing securities laws, and the token usually represents an economic interest or fractional ownership right rather than direct legal title to the property. Always verify the regulatory framework applicable to the specific platform and jurisdiction.
### What types of onchain data does Envio index for a real estate tokenization platform?
Envio can index any smart contract events, including token transfers, staking and unstaking events, liquidity pool changes, governance actions, and custom application events. For Blocksquare, this includes tracking token holders, investment listings, transaction history, supply information, and APY-relevant data points, all served through a unified GraphQL API.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# zkPass: Multichain ZKP Identity Verification Powered by Envio
> How zkPass uses zero knowledge proofs with Envio to verify identity and transactions across 8 EVM networks while keeping user data private.
 :::note TL;DR
- zkPass uses Envio's HyperIndex to index and verify onchain identity data across 8 EVM networks including Optimism, BNB, Base, Arbitrum, and X Layer, through a single unified API.
- HyperSync replaces traditional RPC for data ingestion, enabling the zkPass engineering team to accelerate development cycles and test product features faster.
- The integration powers transaction count verification, wallet history checks, cross-wallet asset verification, and proof of token holdings without exposing private user data.
:::
[zkPass](https://zkpass.org/) selected [Envio](https://envio.dev/) as its blockchain indexer to power privacy-preserving identity verification across 8 EVM networks. Envio's HyperIndex consolidates onchain data from multiple chains into a single unified API, enabling zkPass to verify wallet history, asset holdings, and transaction counts without requiring users to disclose sensitive personal information.
## What are Zero-Knowledge Proofs (ZKPs)?
ZKPs allow one party (the prover) to prove to another party (the verifier) that they know a specific piece of information without revealing the actual data. It's a system based on trust but with privacy baked in. For example, you could prove your age without sharing your birthdate, or prove you have enough funds for a transaction without showing your full balance.
Although this concept has been around for decades, its practical application in blockchain and Web3 is now gaining momentum. The rise of decentralized systems has created a demand for more secure, private ways of verifying transactions, identities, and sensitive data.
## How do ZKPs Work?
In a ZKP, the prover uses complex cryptographic algorithms to generate a "proof" that can be validated without sharing the original information. Here's a simplified breakdown of how it works:
1. **Prover and Verifier**: Two parties engage in a process. The prover wants to prove they know a certain fact (like a password) without revealing it.
2. **Mathematical Proof**: The prover uses a mathematical algorithm to create a proof that is valid only if the statement is true.
3. **Verification**: The verifier checks the proof without needing to access the sensitive information itself.
This might sound complicated, but the impact is straightforward: sensitive data remains private, yet its validity is verified.
## Why is This Important for User Privacy?
Today, most systems that require identity verification ask for more data than necessary. Think about how often you're asked to provide your personal details: Name, Surname, Age, Physical Address, Identification Number, Bank Statements, Credit Score, etc. This over-sharing of data leads to higher risks of exposure, scams, and breaches.
ZKPs offer a way to get around this, allowing you to share only necessary information, and helping reduce the risk of your data falling into the wrong hands.
## ZKPs Role in Decentralized Identity
One of the biggest opportunities for ZKPs lies in decentralized identity (DID) systems. In a decentralized identity setup, you can control your own digital identity without ever having to rely on a central authority. But you'd still need a way to verify this information and that's where ZKPs come in.
With ZKPs, you can verify parts of your identity, such as age, nationality, or ownership of a digital asset, without revealing your full details to the verifier. This is especially useful in cases like age verification, voting systems, and even background checks.
## Unlocking the Full Potential of ZKPs
The potential for ZKPs extends far beyond decentralized identity systems. Here are a few other use cases where ZKPs can play a critical role:
- **Secure Transactions**: In blockchain-based financial systems, ZKPs enable privacy-preserving transactions. Users can prove they have enough balance to complete a transaction without revealing the entire wallet's contents.
- **Private Voting**: ZKPs can allow people to participate in elections or governance votes without disclosing who they voted for, ensuring privacy and integrity in democratic systems.
- **Supply Chain Verification**: In industries like pharmaceuticals or luxury goods, ZKPs can confirm the authenticity of a product's origin or lifecycle without revealing all the internal supply chain details.
For a more comprehensive look at additional and existing use cases, check out zkPass's [use cases](https://zkpass.gitbook.io/zkpass/overview/use-cases).
## What is zkPass?
[zkPass](https://zkpass.org/) is a decentralized authentication solution that verifies your legal identity without requiring file uploads or the over-disclosure of private information. Through the power of ZKPs, it allows you to selectively prove a wide array of data types without revealing any of your personal information.
At zkPass, user empowerment is at the forefront. Web3 users can manage their credentials and share only the necessary information for specific interactions, giving them greater control over their data and privacy. The platform leverages advanced cryptographic techniques to facilitate seamless and secure verification processes. This not only builds user trust but also enhances their overall experience, enabling them to engage in activities like online voting confidently, and participating with decentralized applications.
By offering a versatile solution for proving identity and qualifications, zkPass is leading the charge toward a more secure and privacy-centric future in digital identity management.
 ## How Envio Powers zkPass's Privacy Solutions
At the heart of implementing ZKP technology, zkPass recognized the critical need to optimize the data infrastructure necessary for deploying effective ZKP solutions. To achieve this, zkPass chose [Envio](https://envio.dev/) as its blockchain indexer and accelerated data infrastructure partner.
By integrating Envio's capabilities, zkPass can seamlessly operate across various EVM networks, ensuring low-latency performance and reliable access to real-time data. Envio's real-time data indexing and querying empower zkPass to scale its privacy solutions effectively.
Specifically, Envio supports zkPass in:
- **Proof of the Number of Transactions**: Envio enables zkPass to verify the total number of transactions associated with a wallet, enhancing the accuracy of transaction tracking.
- **Wallet History Verification**: With Envio's infrastructure, zkPass can efficiently verify the transaction history of wallets, ensuring integrity and transparency in user activity.
- **Cross-Wallet Asset Verification**: Envio facilitates the verification of assets across multiple wallets, allowing zkPass to confirm asset ownership without compromising user privacy.
- **Proof of Token Holdings**: Envio's capabilities enable zkPass to validate token holdings securely, ensuring that users can prove their ownership without disclosing sensitive information.
## How Envio Enhances zkPass with Multichain Support
zkPass utilizes Envio's [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) to efficiently index and aggregate data across eight EVM networks, including [Optimism](https://www.optimism.io/), [Binance Smart Chain](https://www.bnbchain.org/en), [X Layer](https://web3.okx.com/xlayer), [Base](https://www.base.org/), and [Arbitrum](https://arbitrum.io/). This enables zkPass to seamlessly query real-time and historical data from their smart contract deployments, providing a comprehensive view of their application data and user actions.
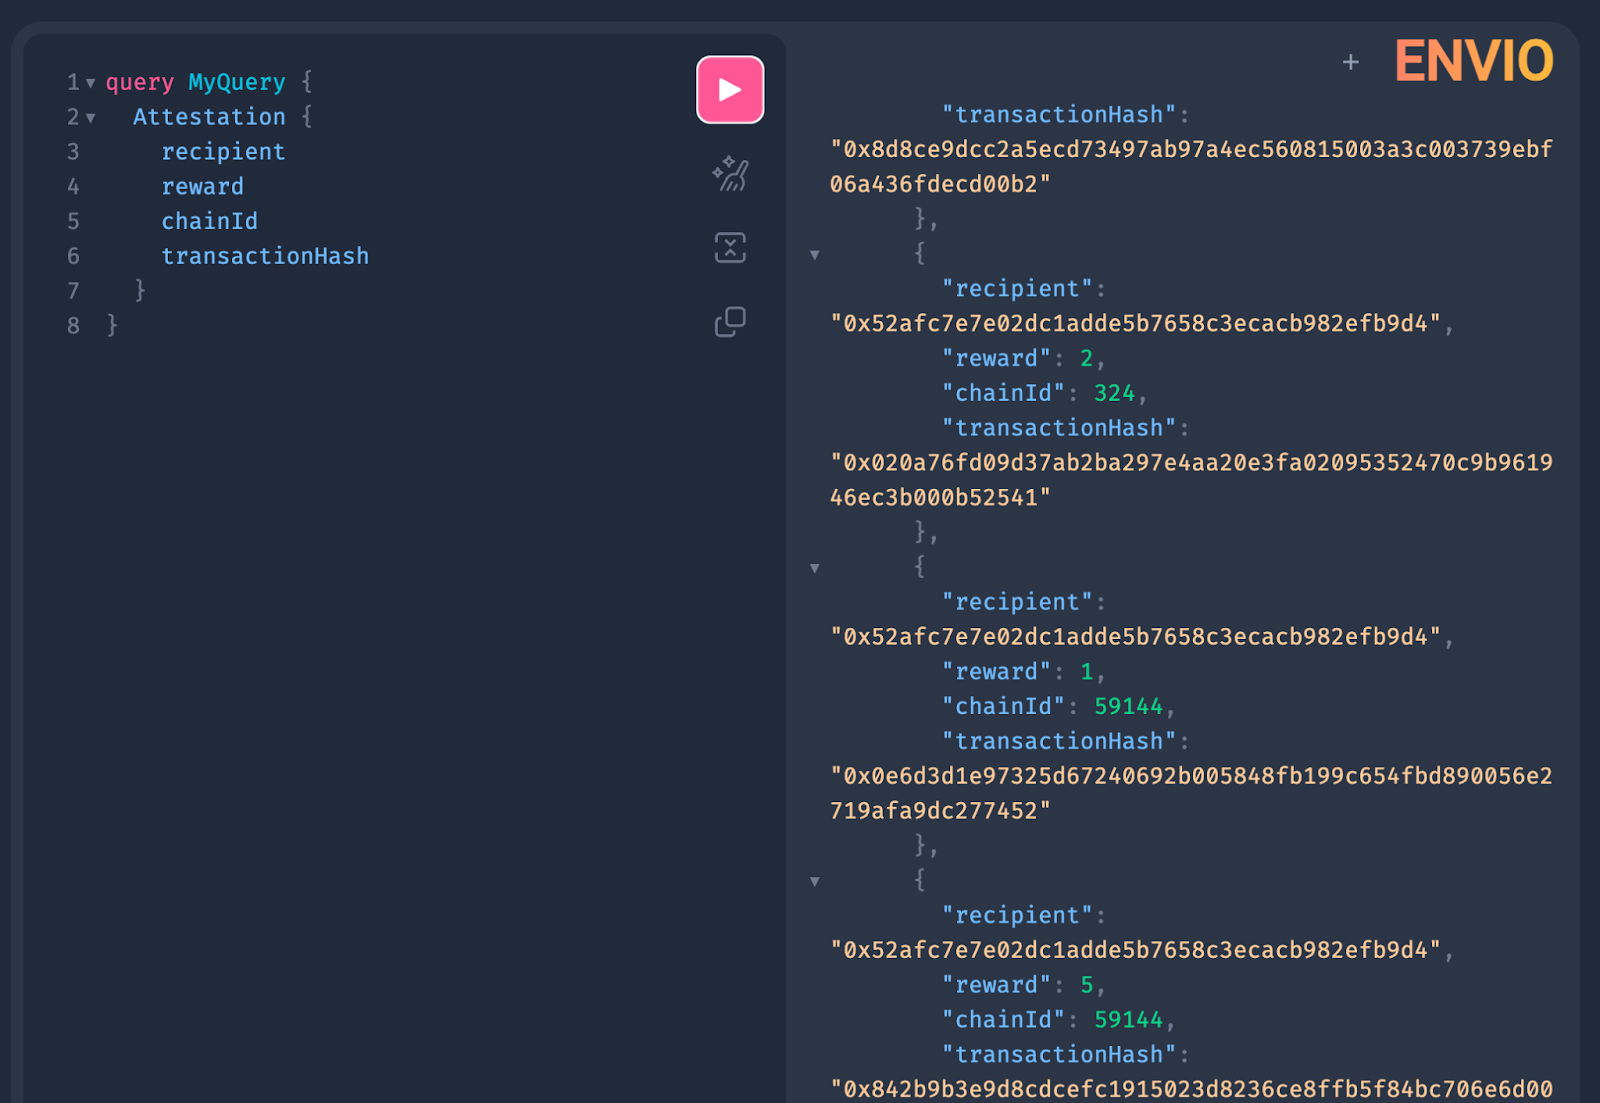 Envio's multichain architecture consolidates data from multiple blockchains into a unified database, accessible through a single API. Other indexers require a separate deployment per chain. With Envio, all networks are configured in a single config.yaml. This design simplifies development workflows, reduces infrastructure complexity, and lowers operational costs.
Moreover, by using HyperSync as the data source for HyperIndex (instead of traditional RPC methods), the zkPass engineering team benefits from exceptionally fast indexing performance and reliable data access. This empowers the zkPass team to accelerate their development lifecycle, test product features more rapidly, and drive innovation at a faster pace.
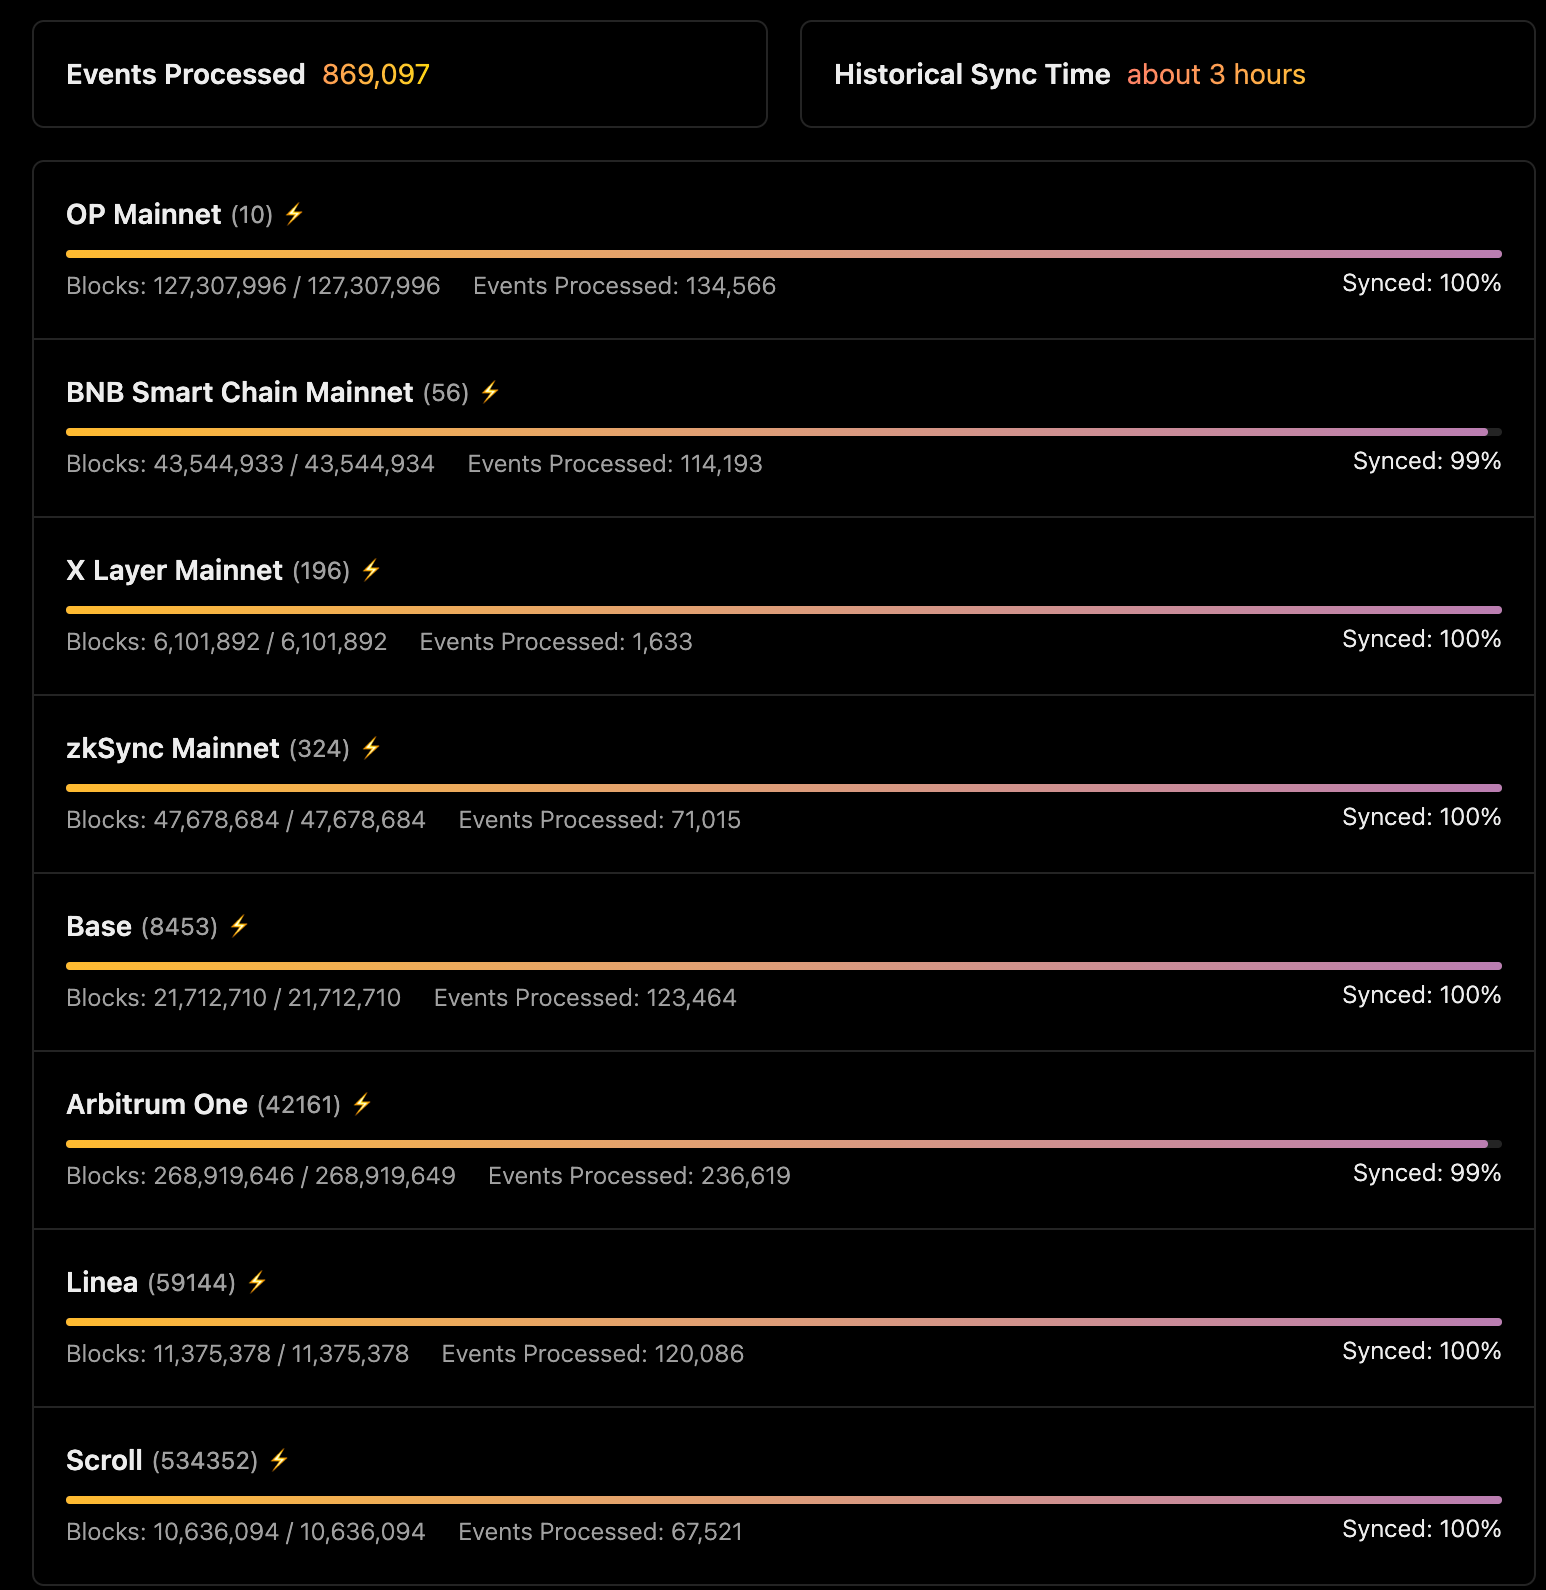 ## Conclusion
zkPass offers a glimpse into a future where privacy doesn't have to be sacrificed for convenience or verification. By allowing people to prove what they need without over-sharing sensitive details, ZKPs are redefining what's possible in user privacy. As the technology evolves and becomes more scalable, ZKPs could become the go-to solution for a wide range of privacy concerns, from identity verification to secure transactions.
As Envio continues to support decentralized applications like zkPass, we're excited to see how ZKPs will be integrated to empower better privacy and security for all users.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update December 2024
> What Envio shipped in December 2024: HyperSync milestone release, Blocksquare DeFi integration, new tutorials, and community highlights.
 Welcome to our December 2024 update. We want to take a moment to thank each and every one of you for an incredible 2024. Your support, feedback, and contributions have been at the heart of everything we've accomplished, and we couldn't be more grateful!
This month, we've been busy rolling out new features, integrating with some amazing projects, and continuing to enhance our data indexing solutions. From big milestones with HyperSync to a new DeFi integration with Blocksquare, we've got plenty to share. Plus, we're diving into some exciting updates from our latest tutorials and partnerships.
We're sending you warm wishes for a joyful, restful holiday season with your loved ones. Stay safe, enjoy the festivities, and we'll see you in the new year.
Happy holidays from all of us at Envio!
## HyperSync Milestone
 With nearly 80 billion requests served, [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) is rapidly becoming a top choice as a data source for faster data retrieval than standard RPC. Envio's indexer, HyperIndex, supports both RPC and HyperSync as sources for ingesting blockchain data.
The traditional method of retrieving blockchain data relies on RPC, which, although functional, becomes inefficient when querying large amounts of data. HyperSync enables data access up to 1000x faster than a standard node and also provides this data free of charge.
## HyperIndex Version 2.11.2 is now available
We're pleased to announce the release of **v.2.11.2**!
### Field Selection per Event
You can now specify field selection for individual events. This feature optimizes RPC and HyperSync calls by fetching only the data relevant to specific events, avoiding over-fetching.
Example:
```
events:
- event: "Transfer(address indexed from, address indexed to, uint256 value)"
field_selection:
transaction_fields:
- "to"
- "from"
```
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)! Your support means the world to us!
## Exciting De-Fi Integration with Blocksquare
 [Blocksquare](https://blocksquare.io/) has integrated Envio's advanced indexing technology! This integration boosts Blocksquare's RWA platform, providing faster, more efficient access to onchain data.
With Envio, tasks like indexing 400,000 Ethereum mainnet events now take under 20 minutes - a huge improvement over traditional methods.
This collaboration powers [Oceanpoint](https://oceanpoint.fi/) and Blocksquare's white-label real estate marketplace solutions, paving the way for more scalable real estate tokenization.
## Indexing & Reorgs
 Check out our new article on the impact of chain reorgs on data consumption and aggregation and the challenges of navigating a multichain environment.
Chain reorgs are crucial when indexing data, especially near finalized blocks. How do stateless and stateful data handle reorgs? What are the challenges of multichain indexing? And how do these reorgs play out on networks like Base and Polygon?
Explore the full [blog](https://docs.envio.dev/blog/indexing-and-reorgs).
## Tokenizing RWAs: How Blockchain is Redefining Real Estate Investment
 What if you could own real estate without the high costs? Blocksquare's tokenized real-world assets (RWAs) are unlocking new investment opportunities. No barriers - just seamless, borderless access to property markets. Welcome to the future of real estate.
Read the [full case study](https://docs.envio.dev/blog/tokenizing-real-world-assets).
## Dev Tutorial: Indexing Data on Rootstock
 Check out our latest Rootstock Educate workshop with Encode Club. Master smart contract indexing on [Rootstock](https://rootstock.io/) in under 5 minutes with live coding and hands-on examples. Learn how to identify key transactions using Envio's powerful blockchain indexing solution to handle millions of events in seconds.
For more developer tutorials check out our [YouTube](https://www.youtube.com/@envio_indexer) channel.
## Can ZKPs Redefine User Privacy? How zkPass is Shaping the Future of Data Security
 Can zero-knowledge proofs (ZKPs) redefine user privacy? [zkPass](https://zkpass.org/) is revolutionizing privacy by verifying information without exposing sensitive data. With privacy breaches becoming all too common, the question isn't if your data is exposed, it's when. Can we protect personal information while still verifying key details?
Read the full [blog](https://docs.envio.dev/blog/zkpass-shaping-future-of-data-privacy).
## Envio Powers BakoID's Handles with Efficient Data Indexing
 We're partnering with Bako, the native naming system for the Fuel ecosystem. Envio powers Bako with faster and more reliable data to power their users' handles.
This integration ensures Bako users benefit from more efficient blockchain data handling and improved performance.
Check it out at app.bako.id
## Featured Developer
 This month's Featured Community Member is [Simon Kruse](https://github.com/Simon0x), Head of Web3 Development at Blocksquare. Since 2017, Simon has been active in crypto, specializing in real estate tokenization and DeFi, focusing on borrowing and lending solutions.
Simon's team operates two of the top-signaled indexers on The Graph but is now consolidating into one unified indexer using Envio for Blocksquare and Oceanpoint. Leveraging Envio's fast indexing and developer-friendly tools, they're driving innovation in tokenized real estate and DeFi.
*"Envio is really onto something. Their tech is fascinating, and the developer experience is unparalleled. After years of working with The Graph, it's refreshing to see new players like Envio pushing the boundaries. The team is responsive, innovative, and a pleasure to work with." – Simon Kruse, Head of Web3 Development & Governance Board Member at Blocksquare*
Check out Blocksquare on [X](https://x.com/blocksquare_io) for updates and explore the Blocksquare/Oceanpoint indexer in our [explorer](https://envio.dev/app/blocksquare/blocksquare-oceanpoint).
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/7awVFZ11ewVYCk0KyMYCka?si=c198409b4f9d43c1)
## Envio Freelancer Network
Need an indexer but don't have the bandwidth? Whether you're looking to find top-notch freelancers or you're a freelancer seeking new opportunities, we've got you covered. Our thriving Freelancer Network connects skilled contractors with Web3 protocols to service their data needs.
Simply fill out the [form](https://noteforms.com/forms/envio-freelancer-network-u9zqbv) to join our freelancer network.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# What is a Blockchain Indexer?
> Learn how efficient blockchain indexers like Envio simplify data access for developers by organising and querying onchain data in real-time.
 :::note TL;DR
- Blockchain indexers transform raw, sequential onchain data into structured databases with GraphQL APIs, making it practical to build data-driven dApps.
- Envio HyperIndex is a TypeScript-first indexing framework with three core files (config.yaml, schema.graphql, EventHandlers.ts) and HyperSync for up to 2000x faster historical sync than RPC.
- Compared to The Graph (separate subgraph per chain, slower historical sync) and Goldsky, Envio uses a single config for all chains and a single GraphQL endpoint.
:::
Blockchain data is stored sequentially and is difficult to query directly. Building decentralized apps often involves navigating raw, unstructured blockchain data, which is complex and time-consuming. A blockchain indexer for dApp development solves this by transforming scattered onchain data into streamlined, structured databases that power fast, efficient apps and give Web3 developers a reliable data retrieval layer. This post covers how blockchain indexers work, why they matter, and what to look for when choosing one.
## What is a blockchain indexer?
A blockchain indexer is a specialized tool that organizes complex onchain data into a structured, ready-to-use format, making it much easier to query and retrieve exactly the data you need.
By defining data types and relationships based on your smart contracts, blockchain indexers like Envio automatically create a custom GraphQL API endpoint, enabling efficient and precise queries. This lets you focus on building your app's core functionality rather than wrangling with raw blockchain data.
Indexers also handle both real-time data retrieval and historical data access. What usually takes days or weeks with traditional methods can be completed in seconds.
## Why dApp developers need a blockchain indexer
### 1. Simplified data access
Blockchain data is inherently scattered and sequential. Fetching transaction logs might involve querying thousands of individual blocks. Indexers abstract this complexity, enabling you to retrieve filtered and aggregated data in seconds.
### 2. Improved developer experience
Without a blockchain indexer, you must handle data processing logic within your app, adding technical debt and slowing down development. Indexers remove this burden.
### 3. Responsive apps
Blockchain indexers are optimized for low-latency queries, enabling real-time access and historical data retrieval. Whether your app needs live updates or rapid insights from past data, indexers are built to handle these demands efficiently.
### 4. Multichain support
Many apps interact with multiple networks, each with unique architectures. Indexers can simplify data retrieval by providing a unified way to query data across multiple chains. For a deeper look at how this works in practice, see [What is Multichain Indexing?](https://docs.envio.dev/blog/what-is-multi-chain-indexing)
### 5. Customizability
Blockchain indexers offer tailored solutions. You can define custom data schemas, filters, and indexing logic, ensuring the infrastructure aligns with your app's requirements.
### 6. Hosted service
Operating indexer infrastructure is resource-intensive. [Hosted services](https://docs.envio.dev/docs/HyperIndex/hosted-service) take this responsibility off your hands with a reliable, fully managed, scalable solution. This lets you focus on shipping your app without worrying about maintenance or downtime.
## What are the key components of a blockchain indexer?
A typical blockchain indexer setup includes the following components:
- **[config.yaml](https://docs.envio.dev/docs/HyperIndex/configuration-file):** Defines the scope of indexing, including blockchain networks, smart contract addresses, start blocks, and events.
- **[schema.graphql](https://docs.envio.dev/docs/HyperIndex/schema):** Defines the structure of your data and how it is stored. Based on this schema, a custom GraphQL API is autogenerated, enabling efficient queries for the indexed data.
- **[Event handlers](https://docs.envio.dev/docs/HyperIndex/event-handlers)**: Detect specific onchain events and update the indexed data accordingly, ensuring accurate and up-to-date information.
## How does blockchain indexing work?
The indexing process begins with the indexer connecting to a network and monitoring new blocks as they are added to the chain. The indexer then extracts specific event data and organizes it in a structured database.
Instead of combing through each block manually, the indexer uses predefined configurations to filter and store the data most relevant to your needs. This structured data can then be queried efficiently using GraphQL APIs.
## Best examples of blockchain indexers
### Uniswap V4
This [Uniswap V4 indexer](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer) is a TypeScript-based, multichain indexer for Uniswap V4 across 10 different networks. This is the same indexer that powers the [v4.xyz](https://v4.xyz) website.
### Aerodrome
This [Aerodrome indexer](https://docs.envio.dev/docs/HyperIndex/example-aerodrome-dex-indexer) is a TypeScript-based, multichain indexer for the [Aerodrome](https://aerodrome.finance/) and [Velodrome](https://velodrome.finance/) DEXs using Envio HyperIndex. The indexer supports deployments on [Base](https://www.base.org/), [Optimism](https://www.optimism.io/), [Mode](https://www.mode.network/), and [Lisk](https://lisk.com/), with data available through a unified GraphQL API.
### Sablier
This [Sablier indexer](https://docs.envio.dev/docs/HyperIndex/example-sablier) is a TypeScript-based, multichain indexer for the [Sablier](https://sablier.com/) protocol using Envio HyperIndex, indexing data across 18 EVM chains through a unified GraphQL API.
## Exploring Envio as a blockchain indexer
Envio's blockchain indexing solution supports both the Fuel Network and any EVM-compatible blockchain, offering developers a versatile and adaptable choice:
- **Flexible language support**: Configure your event handling in JavaScript, TypeScript, or ReScript.
- **HyperSync**: Envio's proprietary data layer delivers up to 2000x faster retrieval of historical onchain data than standard RPC. [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) is used automatically on supported chains.
- **No-code quickstart**: Autogenerate the key boilerplate for an entire indexer project from single or multiple smart contracts. Deploy within minutes.
- **Multichain support**: Aggregate data across multiple networks into a single database. Query all your data with a unified GraphQL API.
- **Join onchain and off-chain data**: Connect indexed blockchain data with off-chain data to create a flexible API for rich data beyond what is emitted from onchain events.
- **Factory contracts**: Automatically register and process events emitted by all child contracts created by a specified factory or dynamic contract.
- **Hosted service**: A managed service platform for building, hosting, and querying Envio's Indexers with guaranteed uptime and performance service level agreements.
Compared to The Graph, which requires a separate subgraph for each chain and has significantly slower historical sync speeds, Envio uses a single `config.yaml` for all chains and a single GraphQL endpoint for all data.
## Conclusion
Blockchain indexers are essential infrastructure for developers working with onchain data. They streamline data access, cut development time, and boost app performance. Envio is independently benchmarked as the fastest EVM blockchain indexer and offers a developer-first experience from local development to hosted production deployment.
## Frequently asked questions
### What is the difference between a blockchain indexer and an RPC node?
An RPC node provides raw access to blockchain state and events, but querying it directly is slow and inefficient for complex data needs. A blockchain indexer processes and organizes that data into a structured database with a GraphQL API, enabling fast, filtered queries without hitting the RPC on every request.
### How long does it take to set up a blockchain indexer with Envio?
Most developers can generate a working indexer from a contract address or ABI using `pnpx envio init` in under 5 minutes. The contract import feature autogenerates the config, schema, and handler boilerplate automatically.
### Can I index multiple chains with a single Envio indexer?
Yes. Envio HyperIndex supports multichain indexing from a single `config.yaml`. You add each network as an entry under the `networks` key, and the resulting GraphQL API covers all of them through one endpoint. This is more efficient than The Graph's approach of requiring a separate subgraph per chain.
### How does HyperSync speed up historical data indexing?
HyperSync bypasses the JSON-RPC layer entirely and uses a purpose-built binary data format to retrieve blockchain data. It can deliver up to 2000x faster historical sync than standard RPC, meaning datasets that would take hours to sync via RPC complete in minutes.
### Does Envio support custom event handler logic, or is it limited to basic data storage?
Envio event handlers are written in TypeScript and support arbitrary logic, including async operations, off-chain data fetching (IPFS, external APIs), and complex entity relationships. You are not limited to simple data storage.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update January 2025
> What Envio shipped in January 2025: new network integrations, feature releases, and tooling for multichain indexing.
 Welcome to our first update of 2025!
Learn more about our latest release and new features to make your indexing experience even better. We've also rolled out new guides and integrations, making it easier than ever to work with Envio's tools and solutions. Plus, we've got some exciting integrations, partnerships, and events coming up. Let's dive in!
## HyperIndex Version 2.12.0 is now available
Please note: The latest release is V2.12.1.
 Before this big release, the RPC data source in HyperIndex had several limitations and lacked many of the features available in the HyperSync data source. This has now been resolved!
You're no longer tied to HyperSync or held back when adding new chains that aren't supported yet. HyperIndex is now a fully equipped RPC indexer, ready for anything!
**What's changed for the RPC data source?**
* Wildcard Indexing support for the RPC data source.
* Pre-registration support for the RPC data source.
* Event Filtering support for the RPC data source when applied to a single wildcard event.
* Transaction input and value fields support for the RPC data source.
* Improved RPC retries on block range error.
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)! Your support means the world to us!
## Indexing Contract Events with Envio HyperSync
 Intuition recently shared their experience using Envio HyperSync to index contract events efficiently with Rust. They highlighted how HyperSync's real-time data extraction, multichain support, and extreme speed - scanning 200M blocks in 10 seconds - enhanced their infrastructure.
Their open-source envio-indexer crate enables seamless event indexing, supporting both database storage and direct streaming to SQS. They also provided a Dockerized setup for scalability and portability.
For those looking to build high-performance indexers, their example showcases how HyperSync simplifies the process while ensuring reliability.
Learn more in their latest [blog](https://medium.com/0xintuition/index-contract-events-with-envio-hypersync-and-rust-29451efdcee0).
## New Guide: Getting Price Data in Your Indexer
Need price data in your indexer? Whether it's for historical token transfers or Uniswap TVL calculations, there are three ways to fetch prices: Oracles, DEX pools, and Offchain APIs.
* Oracles (e.g., API3, Chainlink) push price updates onchain but may lag behind real-time values.
* DEX pools (e.g., Uniswap V3) offer decentralized price data but can be impacted by low liquidity and manipulation.
* Offchain APIs (e.g., CoinGecko) provide broad historical data but come with latency and paywall restrictions.
Each method has trade-offs between speed, accuracy, and decentralization - choose what fits your use case.
Learn more in our latest [guide](https://docs.envio.dev/docs/HyperIndex/price-data).
## Falcon Gun Integrates Envio to Streamline its Data Retrieval for Enhanced Trading
 We're pleased to announce our integration with [Falcon Gun](https://falcongun.com/). Their lightning-fast trading bot terminal now leverages Envio's indexing solution to streamline data retrieval for faster, more reliable trades.
Learn more [here](https://x.com/FalconGunBot/status/1879860589704745030).
## What is a Blockchain Indexer?
 New to indexing or need a refresher? Check out our latest blog where we explain how blockchain indexers transform complex onchain data into easy-to-query, actionable insights. Learn how Envio's tools like HyperSync and multichain support make data retrieval faster and help you build decentralized apps more efficiently.
Read the full [blog](https://docs.envio.dev/blog/what-is-a-blockchain-indexer).
## Envio & ChainDensity: Featured Sponsors in Primo Data's Blockchain Tools Directory
 Envio & [ChainDensity](https://chaindensity.xyz/) are proud to sponsor and be featured alongside 300+ leading tools in Primo Data's [directory](https://www.primodata.org/blockchain-data). Explore the most comprehensive blockchain data resources and discover cutting-edge companies and open-source projects building tools to query, analyze, and visualize blockchain data.
## Featured Developer
 This month's featured developer and community member of the month is Luis Eduardo Boiko Ferreira!
Luis is a senior backend engineer who started in Web3 in 2018. His experience spans everything from building secure enclave code to developing efficient APIs and deploying cloud solutions. Currently, at [Intuition](https://www.intuition.systems/), Luis is leading the development of a contract event ingestion pipeline, handling data indexing, processing, and adding new layers of interpretation. Before Intuition, Luis worked at Bolt Labs, where he developed secure enclave systems for private key management, ensuring they passed rigorous audits. His earlier work includes building settlement engines for gaming businesses and creating multi-step data ingestion pipelines, APIs, CLIs, and TUIs.
In addition, Luis wrote the outstanding blog on indexing contract events using HyperSync mentioned above. A huge shoutout to Luis for the effort he put into crafting such a detailed, insightful deep dive and for being a stellar member of the Envio community.
***"Using Envio HyperSync has been a game-changer for us. Its simplicity and efficiency are outstanding, making our indexing tasks significantly easier. The excellent documentation allowed us to get up to speed quickly, minimizing the learning curve. We tested several other indexing solutions over the past few months, but Envio HyperSync stood out as the best. Its support for a wide array of networks enabled us to create indexers for different networks swiftly and effortlessly. Instead of spending time developing the solution, we were able to focus on the core business logic. I highly recommend Envio HyperSync for anyone looking for a reliable and efficient indexing solution."*** *- Luis Eduardo Boiko Ferreira, Senior Backend Engineer at Intuition*
Follow Luis on [X](https://x.com/lockpickingtux) for more updates and check them out on [GitHub](https://github.com/leboiko).
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/6RrIwtSy6PiKOmUHuPtBFc?si=194fb56ca8da4282)
## Envio Freelancer Network
Need an indexer but don't have the bandwidth? Whether you're looking to find top-notch freelancers or you're a freelancer seeking new opportunities, we've got you covered. Our thriving Freelancer Network connects skilled contractors with Web3 protocols to service their data needs.
Simply fill out the [form](https://noteforms.com/forms/envio-freelancer-network-u9zqbv) to join our freelancer network.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update February 2025
> What Envio shipped in February 2025: new HyperSync network support, product improvements, community highlights, and upcoming builder initiatives.
 Welcome to the Envio monthly developer update. Here is what shipped in February 2025.
## HyperSync Milestone
 Over 115 billion HyperSync requests served across multiple networks. It's becoming the go-to choice for faster data retrieval over standard RPC.
Huge thanks to all the devs building with Envio.
## HyperIndex Version 2.13.0 is now available
 A major milestone for HyperIndex: the first pull request from an external contributor has been merged.
Thanks to this contribution, you can now customize the database schema name using the `ENVIO_PG_PUBLIC_SCHEMA` environment variable, adding more flexibility to your database setup.
A huge shoutout to [Sergey Potekhin](https://x.com/potekhin_sergey) from [Pimlico](https://www.pimlico.io/) and everyone contributing to making Envio even better!
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)!
## V4: Get Real-time Analytics for Uniswap V4 Swaps Across Multiple Networks

 Check out [V4](https://uniswap-v4-analytics.vercel.app/) - powered by HyperIndex - a hub for Uniswap data and hooks that tracks top swaps, pools, and trends in real-time, all displayed in a unified dashboard.
In collaboration with [Silvio Busonero](https://x.com/SilvioBusonero) from [Boost](https://www.boost.xyz/), we've also made onchain analytics for hooks more accessible than ever.
## Oracle Wars: Visualize Onchain Oracle Performance
 Introducing [Oracle Wars](https://www.oraclewars.xyz/) - powered by HyperIndex - a live feed showcasing onchain oracle data from multiple providers, including ETH/USD feeds from [RedStone](https://www.redstone.finance/) and [Chainlink](https://chain.link/). This tool helps developers gain insights into how oracles operate in real-world scenarios, especially during periods of market volatility.
By visualizing real-time updates, Oracle Wars empowers developers to make more informed design decisions, enhancing the safety and efficiency of DeFi protocols. Built using Envio for fast data indexing, we plan to expand the platform with more feeds and networks in the future.
## Exciting DeFi Integration With Haha Wallet
 Envio's efficient indexing solution has been integrated with [Haha Wallet](https://www.haha.me/) - an innovative smart wallet delivering the best user experience on Monad.
In collaboration with [Kuru](https://www.kuru.io/markets), this integration achieves impressive indexing speeds of 10k TPS, significantly enhancing Haha Wallet's capabilities and ensuring a seamless experience for all users.
See it in action on [X](https://x.com/0xtrojan_/status/1891503860713173456).
## EthDenver: Encode Club Modular DeFi Hackathon & Research Day
 This month, our team attended [EthDenver](https://www.ethdenver.com/), where we hosted a developer workshop led by our Co-founder [Jonjon](https://x.com/jonjonclark), who built a Uniswap V4 dashboard from scratch in under 15 minutes. We also offered several bounties with a total prize pool of $5k for Encode Club's Modular DeFi Hackathon & Research Day.
A huge thank you to the [Encode](https://www.encode.club/) team for hosting us and organizing such a successful event and hackathon, as well as to all the participants and winners!
## EthDenver: Monad Evm/Accathon
 This month, we hosted the Envio Bounty Challenge during the first-ever Monad hackathon, the EVM/Accathon, inviting participants to create live analytics dashboards to track Monad's onchain activity using Envio's HyperIndex & HyperSync. The challenge featured a prize of $2,000 USD!
A big thank you to the Monad team for hosting us and coordinating such a fantastic hackathon. We also appreciate all the participants for their innovative submissions. Stay tuned for more details regarding the winner!
## EVM vs AltVM: How the Data Differs?
This month, Co-Founder Jason co-hosted a livestream with Fuel, Pangea, and Indexing Co., discussing the evolution of blockchain data indexing from traditional EVM approaches to modern AltVM solutions. The discussion emphasized the need for robust infrastructure and unique indexing strategies.
Check out the recorded version of the discussion below.
[](https://www.youtube.com/watch?v=e-gWCDearng)
## Envio Supports Developers Building on Monad
 Monad's testnet is live and a high-speed chain deserves a high-performance solution.
Envio supports devs building on [Monad](https://www.monad.xyz/) with efficient access to real-time & historical data. With [HyperSync](https://docs.envio.dev/docs/HyperSync/overview), a low-level API, devs can sync large datasets in minutes - bypassing the usual hours or days via RPC.
Learn more in our [thread](https://x.com/envio_indexer/status/1892230056719573193).
## Envio's Open Indexing Framework Supports Devs Building on Berachain
 Envio's open indexing framework supports devs building on Berachain Mainnet with efficient access to real-time & historical data. Developers can utilize Envio's HyperSync to sync millions of events 1000x faster than RPC. Easy, fast, and fully customizable!
View all current HyperSync-supported networks in our [docs](https://docs.envio.dev/docs/HyperSync/hypersync-supported-networks).
## New Feature Alert: Search Bar Now Live
 The much-anticipated search bar is here, allowing you to easily navigate the 100+ indexers deployed on Envio. Stay tuned for upcoming features, and don't hesitate to share your feedback or suggestions in our Discord!
Test it out yourself in our [Explorer](https://envio.dev/explorer).
## Upcoming Events
* EthGlobal [Pragma Cannes](https://ethglobal.com/events/pragma-cannes): 3rd June 2025
* [DappCon](https://dappcon.io/): 16th → 18th June 2025
* WAGMI Sponsors at [EthCC](https://ethcc.io/): 30th June → 3rd July 2025
## Featured Developer
 This month's featured developer and community member is [Sergey Potekhin](https://www.linkedin.com/in/sergey-potekhin/)!
Sergey is currently building [Pimlico](https://www.pimlico.io/) and is actively engaged with developments in the space, focusing on native Account Abstraction (AA), resource locks, and cross-chain intents. In his spare time, he explores zero-knowledge (ZK) mathematics and works on various related projects. With over 8 years of experience as a blockchain engineer, Sergey is a true tech enthusiast who dedicates significant time to attending meetups and contributing to open-source initiatives. We appreciate his contributions as our first external contributor and his passion for helping us make Envio even better!
Follow Sergey on [GitHub](https://github.com/pavlovdog/) for updates on his latest projects.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/0yOOvvkHFIDsi2VRHDIrH0?si=7ad749d44b464830)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# What is Multichain Indexing?
> Learn how Envio enables multichain indexing to unify data from multiple blockchains, letting developers query assets, events, and contracts across networks.
 :::note TL;DR
- Multichain indexing unifies blockchain data from multiple networks into a single structured database with one GraphQL endpoint, eliminating the need for separate data pipelines per chain.
- Envio HyperIndex supports multichain indexing from a single config.yaml, making it structurally simpler than The Graph (separate subgraph per chain) or Goldsky (separate pipelines).
- Real-world examples include Uniswap V4 (10 chains), Sablier (18 chains), and Aerodrome (Base, Optimism, Mode, Lisk), all using a single Envio indexer and a single GraphQL API.
:::
Web3 is inherently multichain. Apps no longer operate in isolation. If you are new to blockchain indexing, start with [What is a Blockchain Indexer?](https://docs.envio.dev/blog/what-is-a-blockchain-indexer) before diving in. DeFi protocols aggregate liquidity across multiple networks, NFT marketplaces span multiple ecosystems, and analytics platforms track cross-chain activity. Seamless access to reliable data across all of these is critical.
Yet querying multiple chains efficiently remains a challenge. Each network has its own architecture, RPC limitations, and data structures, making direct integration complex and resource-intensive. Multichain indexing solves this by providing a unified way to structure, query, and analyze blockchain data across chains without the overhead of managing individual indexing solutions.
## What is multichain?
Multichain describes an application, protocol or dataset that spans more than one blockchain rather than living on a single network. A multichain DeFi protocol might hold liquidity on Ethereum, Base and Arbitrum at once, and a multichain NFT marketplace might list assets across several ecosystems. The term describes how something is deployed, not the technology used to read its data.
## What is multichain indexing?
Multichain indexing is the process of ingesting, organizing, and providing blockchain data across multiple networks in a unified way. It simplifies the complexity of querying different blockchain infrastructures, giving you access to structured data from various chains through a single interface.
This means:
* You do not need to manage separate data pipelines for each chain.
* You get faster, more efficient queries across multiple networks.
* You reduce dependency on rate-limited RPC endpoints.
Instead of treating each network as an isolated system, multichain indexing organizes the data so apps can query assets, transactions, and smart contract events in a consistent format, regardless of the underlying chain.
## Why multichain indexing is essential for Web3
### 1. Interoperability without complexity
Cross-chain apps rely on real-time, consistent access to data from different chains. A prediction market built on one chain might reference pricing data from another. A DeFi aggregator might route transactions across multiple liquidity pools. Multichain indexing bridges these gaps by allowing apps to operate across chains seamlessly.
### 2. Scalability and performance
Querying raw data directly from RPC nodes is inefficient at scale. Rate limits, latency, and inconsistent indexing methods across chains create bottlenecks. Multichain indexing pre-processes and structures the data, enabling high-speed queries and scalable access without overloading RPC endpoints.
### 3. Consistent data models across chains
Each chain has its own way of storing and exposing data. Ethereum-based networks use events, whereas others such as [Fuel](https://fuel.network/) rely entirely on logs and receipts. Instead of building custom adapters for each chain, multichain indexing harmonizes data models so apps can interact with all the data in a standardized format.
### 4. Reduces developer overhead
Maintaining separate data pipelines for different chains is costly and time-consuming. With multichain indexing, you can focus on building application logic instead of dealing with raw chain infrastructure. A single, unified query layer removes the need for writing custom indexers per chain, reducing both complexity and maintenance effort.
## How Envio powers multichain indexing
Envio's [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) is designed for performance, flexibility, and scalability, enabling real-time multichain indexing with a modular architecture that is fully customizable and adaptable to different chain environments.
### Key features of Envio's HyperIndex for multichain indexing
- **Unified query layer**: Query indexed data across multiple chains with a single GraphQL API, providing a simple and unified data access point.
- **Event-driven indexing**: Indexes smart contract events across multiple chains, ensuring efficient and reliable access to real-time data.
- **Multichain support**: Handles data from various chains, enabling easy integration across different networks from a single `config.yaml`.
- **Optimized for performance**: Processes and retrieves onchain data with low latency, keeping your apps fast and responsive.
Unlike The Graph, which requires a separate subgraph deployment for each chain with separate endpoints, Envio's single-config approach means you define all networks in one file and query all of them through one GraphQL endpoint. Goldsky requires similar per-chain pipeline management. Envio eliminates that overhead entirely.
## Real-world examples: apps that use multichain indexing
### DeFi protocols (e.g., [Uniswap](https://app.uniswap.org/))
* Aggregating liquidity across multiple chains.
* Tracking user transactions and positions across ecosystems.
* Calculating cross-chain lending and borrowing rates in real time.
### NFT marketplaces (e.g., [OpenSea](https://opensea.io/))
* Fetching metadata, ownership records, and sale history across chains.
* Providing a unified search experience for cross-chain NFT collections.
### Cross-chain analytics and dashboards (e.g., [ChainDensity](https://chaindensity.xyz/))
* Monitoring activity and transaction flow across multiple blockchains.
* Standardizing data for visualization and reporting.
## Best examples of multichain indexers
### Uniswap V4
This [Uniswap V4 indexer](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer) demonstrates a TypeScript-based, multichain indexer for Uniswap V4 across 10 different networks. It powers the v4.xyz website, providing seamless data access.
### Sablier
This [Sablier indexer](https://docs.envio.dev/docs/HyperIndex/example-sablier) uses Envio HyperIndex to index data across 18 EVM chains with a single GraphQL API.
### Aerodrome
This [Aerodrome indexer](https://docs.envio.dev/docs/HyperIndex/example-aerodrome-dex-indexer) supports the Aerodrome and Velodrome DEXs, indexing data across Base, Optimism, Mode, and Lisk, served through a unified GraphQL API.
## Conclusion
Multichain indexing is no longer just a convenience: it is a core infrastructure layer for Web3 apps. Solutions like HyperIndex empower developers to achieve scalable, real-time data access across chains, enabling the next generation of multichain apps.
Web3 is inherently multichain, and applications need data infrastructure that reflects this reality. Whether building DeFi platforms, NFT marketplaces, or analytics tools, multichain indexing is now a cornerstone of scalable, efficient Web3 development.
## Frequently asked questions
### How do I add a second chain to an existing Envio HyperIndex indexer?
Add a new entry under the `networks` key in your `config.yaml` with the chain ID, start block, and contract details. The existing GraphQL schema and handlers work across all chains automatically. No separate deployment or endpoint is needed.
### Does Envio charge more for multichain indexers?
No. Multichain indexers run the same as single-chain indexers on Envio's hosted service. You define multiple networks in one config, and the indexer handles all of them in a single deployment with one GraphQL endpoint.
### What is the maximum number of chains I can index with a single Envio indexer?
There is no hard limit. Real-world Envio indexers (like the Sablier example) index 18 chains from a single config. As long as HyperSync supports the chain or an RPC endpoint is available, you can add it to your indexer.
### How does Envio handle different event schemas across chains?
If the same contract is deployed on multiple chains, Envio uses the same event handler for all of them. If contracts differ across chains, you define separate contract entries in your config, each with their own ABI and handlers. The resulting GraphQL schema unifies all the data in one queryable database.
### Can I query data from a specific chain only, even in a multichain indexer?
Yes. Because the indexed data is stored in a structured database, your GraphQL queries can filter by any field you store, including the source chain ID. You can also add a `chainId` field to your schema entities and filter on it in queries.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Now Supports 70+ Blockchains
> Learn how Envio's HyperSync supports over 70 blockchain networks delivering real-time and historical onchain data with unmatched speed and reliability.
 :::note TL;DR
- Envio's HyperSync now supports over 70 EVM-compatible networks plus Fuel, providing reliable real-time data access at speeds up to 2000x faster than standard RPC.
- HyperIndex adds full multichain indexing with a single config.yaml and a single GraphQL endpoint, making it structurally simpler than The Graph or Goldsky for cross-chain data.
- If your network is not yet supported, you can request HyperSync support directly in the Envio Discord.
:::
Envio's HyperSync supports over 70 EVM-compatible networks along with Fuel, providing reliable real-time data access across the Web3 ecosystem. This milestone advances the goal of making decentralized data more efficient and accessible for developers and analysts building across multiple blockchains.
## What is HyperSync?
[HyperSync](https://docs.envio.dev/docs/HyperSync/overview) is Envio's advanced data node, built in Rust to dramatically speed up blockchain data retrieval. It operates as a real-time, high-speed query layer, offering a low-level API compatible with Python, Rust, Node.js, and Go. With HyperSync, you can query millions of events in seconds, delivering sync speeds up to 2000x faster than traditional RPC methods.
HyperSync is well suited for performance-heavy applications like block explorers, data analytics platforms, and blockchain bridges. Traditional syncing methods can be slow and resource-intensive, especially across multiple networks. HyperSync optimizes these processes with intelligent caching and efficient data retrieval, giving you faster access to both real-time and historical blockchain data.
## Multichain indexing support
Envio HyperIndex provides multichain indexing support, enabling you to efficiently index and query multiple blockchains with a single indexer. This eliminates redundant tools, streamlines workflows, and ensures high performance at scale.
Unlike The Graph (which requires a separate subgraph per chain with separate endpoints) or Goldsky (which requires separate pipelines per chain), Envio uses a single `config.yaml` to define all networks and exposes a single GraphQL endpoint. This makes cross-chain data access significantly simpler to build and maintain.
## Supported networks
Envio supports any EVM chain and Fuel with an expanding list of networks, including [Arbitrum](https://arbitrum.io/), [Base](https://www.base.org/), [Blast](https://blast.io/en), [Celo](https://celo.org/), [Chiliz](https://www.chiliz.com/), [Citrea](https://citrea.xyz/), [Darwinia](https://darwinia.network/), [Ethereum](https://ethereum.org/en/), [Gnosis](https://www.gnosis.io/), [Metis](https://www.metis.io/), [Monad](https://www.monad.xyz/), [Morph](https://www.morphl2.io/), [Optimism](https://www.optimism.io/), [Polygon](https://polygon.technology/), [Rootstock](https://rootstock.io/), [Scroll](https://scroll.io/), and many more.
See the full list of supported networks in the [documentation](https://docs.envio.dev/docs/HyperSync/hypersync-supported-networks).
We are rapidly adding new supported networks. If your network is not listed or you would like HyperSync support added, pop us a message in our [Discord](https://discord.gg/envio).
## Why use Envio?
Envio HyperIndex offers a developer-centric blockchain data indexing solution, empowering you to efficiently access and process both real-time and historical smart contract data served via GraphQL API:
* **Flexible language support**: Configure your event handling in JavaScript, TypeScript, or ReScript.
* **HyperSync**: Delivers up to 2000x faster indexing than standard RPC for historical onchain data. Use of RPC is optional.
* **No-code quickstart**: Autogenerate the key boilerplate for an entire indexer project from single or multiple smart contracts. Deploy within minutes.
* **Multichain support**: Aggregate data across multiple networks into a single database. Query all your data with a unified GraphQL API.
* **Factory contracts**: Automatically register and process events emitted by all child contracts created by a specified factory or dynamic contract.
* **Hosted service**: A managed service platform for building, hosting, and querying Envio's Indexers with guaranteed uptime and performance service level agreements.
## Useful resources
- [Getting started](https://docs.envio.dev/docs/HyperIndex/getting-started)
- [Guides](https://docs.envio.dev/docs/HyperIndex/configuration-file)
- [Tutorials](https://docs.envio.dev/docs/HyperIndex/tutorial-op-bridge-deposits)
- [Get support](https://discord.gg/envio)
## Conclusion
Envio is a powerful alternative to traditional blockchain indexing methods. Its single-config multichain approach simplifies cross-chain data access and eliminates the per-chain overhead that comes with The Graph subgraphs or Goldsky pipelines.
## Frequently asked questions
### How do I check if my network is supported by Envio HyperSync?
Visit the [HyperSync supported networks page](https://docs.envio.dev/docs/HyperSync/hypersync-supported-networks) in the documentation. If your network is not listed, you can request support by opening a message in the [Discord](https://discord.gg/envio).
### Can I use Envio on a network that HyperSync does not yet support?
Yes. For networks without HyperSync support, Envio HyperIndex falls back to standard RPC for data retrieval. You provide an RPC URL in your config, and the indexer works the same way, just without the HyperSync speed boost. HyperSync support is added regularly.
### What languages can I use with the HyperSync API?
HyperSync exposes a low-level API with clients for Python, Rust, Node.js, and Go. You can retrieve data in JSON, Arrow, or Parquet formats depending on your pipeline needs.
### How does Envio's multichain support compare to The Graph?
The Graph requires a separate subgraph deployment for each chain, with separate GraphQL endpoints per network. Envio uses a single `config.yaml` to define all networks and a single GraphQL endpoint for all chains. This means less boilerplate, fewer deployments to manage, and simpler cross-chain queries.
### Is HyperSync available as a standalone API, or only through HyperIndex?
HyperSync is available both as the underlying data layer for HyperIndex and as a standalone API. Data analysts can query HyperSync directly using the Python, Rust, Node.js, or Go clients for custom data pipelines, analytics, and research use cases.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update March 2025
> What Envio shipped in March 2025: HyperIndex v2.15 with RPC failover, the LogTui chain scan tool, and integrations with XDC Network, Monad, and Chiliz.
 Welcome to the Envio monthly developer update. Here is what shipped in March 2025.
## HyperIndex Versions 2.14.0 & 2.15.0 are now available
### Topic Filtering goes Multichain
Now the `eventFilters` option can also accept a callback, allowing for building different filters depending on `chainId`:
```
import { ERC20 } from "generated";
const ZERO_ADDRESS = "0x0000000000000000000000000000000000000000";
const WHITELISTED_ADDRESSES = {
1: [
"0xf39Fd6e51aad88F6F4ce6aB8827279cffFb92266",
"0x70997970C51812dc3A010C7d01b50e0d17dc79C8",
],
100: ["0x3C44CdDdB6a900fa2b585dd299e03d12FA4293BC"],
};
ERC20.Transfer.handler(
async ({ event, context }) => {
//... your handler logic
},
{
wildcard: true,
eventFilters: ({ chainId }) => [
{ from: ZERO_ADDRESS, to: WHITELISTED_ADDRESSES[chainId] },
{ from: WHITELISTED_ADDRESSES[chainId], to: ZERO_ADDRESS },
],
}
);
```
### Stricter `chainId` type
The `chainId` type on `event` is now a union of chain ids the event belongs to. This is much safer than a number type used before.
### RPC as a fallback
HyperIndex v2.14.1 also went live with this update bringing enhanced reliability with RPC failover support - ensuring 100% uptime for your indexer. If HyperSync becomes unavailable, your indexer will automatically switch to an RPC provider.
#### What's new?
* **RPC as a fallback** → If the primary data source doesn't receive a new block in 20 seconds, your indexer seamlessly switches to an RPC provider.
* **New RPC configuration syntax** → Easily add redundancy with a single field.
* **Advanced control** → Define multiple RPC endpoints, set fallback priorities, and customize block intervals.
#### How to enable it?
Simply add an RPC field to your network configuration:
* If HyperSync is available for a chain, it remains the primary data source, with RPC as a fallback.
For chains without HyperSync support, RPC becomes the primary data source.
```
networks:
- id: 137 # Polygon
start_block: 0
+ rpc: https://eth-mainnet.your-rpc-provider.com
contracts:
- name: PolygonGreeter
address: 0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c
```
**Advanced RPC Configuration:**
Want more control? You got it. Now you can explicitly define primary vs. fallback RPC providers:
```
networks:
- id: 137 # Polygon
start_block: 0
+ rpc:
+ url: https://eth-mainnet.your-rpc-provider.com
+ for: sync
contracts:
- name: PolygonGreeter
address: 0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c
```
Or specify multiple RPC endpoints with custom settings:
```
networks:
- id: 137 # Polygon
start_block: 0
+ rpc:
+ - url: https://eth-mainnet.your-rpc-provider.com?API_KEY={ENVIO_MAINNET_API_KEY}
+ for: fallback
+ - url: https://eth-mainnet.your-free-rpc-provider.com
+ for: fallback
+ initial_block_interval: 1000
contracts:
- name: PolygonGreeter
address: 0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c
```
This update ensures full redundancy, uninterrupted indexing, and complete flexibility.
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)!
## Introducing LogTui: Scan Entire Chains for Logs in Seconds
 [LogTui](https://www.npmjs.com/package/logtui) is a free CLI tool that lets you scan entire chains for onchain events with a single command. It supports 70+ networks and comes with presets for major protocols like ERC-20, ERC-721, Aave, and Chainlink. Designed for speed, it can process millions of events in minutes, powered by HyperSync's efficient filtering to keep data transfer minimal.
For more details check out this [post](https://x.com/jonjonclark/status/1901604311206899760).
## Exciting DeFi Integration V12
 Envio's open-indexing framework has been integrated with V12 - an onchain order book that provides high-speed and precise trading.
With this integration, V12 can seamlessly track key trading metrics, including daily users, orders, and historical trends, all in real time. This improved visibility enhances their analytics and informs ongoing platform optimizations, ensuring a more efficient and data-driven trading experience.
## Envio's Blockchain Indexing Framework Supports Developers Building on the XDC Network
 Envio's open indexing framework supports developers building on the [XDC Network](https://xdc.org/) - an EVM-compatible L1 for secure, scalable global trade with efficient and reliable access to real-time & historical data.
## Envio Powers a Growing Ecosystem on Monad
 Envio is fueling a thriving ecosystem on [Monad](https://www.monad.xyz/), empowering projects with real-time data retrieval and optimized UX as they prepare for mainnet. From [Kuru Exchange](https://www.kuru.io/markets?marketType=trending&timeInterval=5m) and [HaHa Wallet](https://www.haha.me/) to [Nadradar](https://nadradar.com/), [Nad.fun](https://testnet.nad.fun/), [Monorail](https://testnet-preview.monorail.xyz/), [Revoke Cash](https://revoke.cash/), and more - Envio is at the heart of the next wave of high-performance applications.
Check out this [thread](https://x.com/envio_indexer/status/1900493623784808598) to explore some of the incredible projects we support on Monad.
## Envio x Chiliz: Powering the Future of Sports on Chain
 Envio's open-indexing framework now supports developers building on [Chiliz](https://www.chiliz.com/), the leading sports-focused blockchain. With seamless access to real-time and historical data, devs can create high-performance applications that bring fan engagement, sports analytics, and Web3 experiences to the next level.
## Developer Tutorials: Monad, Chiliz & Rootstock
### Monad Tutorial
 Build a Telegram bot that tracks $WMON token transfers in real-time on the Monad Testnet using Envio's open-indexing framework. This tutorial walks you through setting up an indexer, handling live events, and sending instant notifications - all powered by HyperIndex.
Learn more by visiting Monad's [documentation](https://docs.monad.xyz/guides/tg-bot-using-envio).
### Chiliz Tutorial
 Track major Fan Token transfers with a Telegram bot in just minutes. Our latest Chiliz indexing tutorial shows you how to monitor high-value moves and stay ahead in the sports-focused blockchain ecosystem.
Learn more by visiting Chiliz [documentation](https://docs.chiliz.com/develop/advanced/how-to-create-telegram-notifications-for-fan-token-transfers).
### Rootstock Tutorial
Watch our hands-on Rootstock indexing tutorial and learn how to seamlessly retrieve blockchain data for your dApps. We cover the fundamentals of data indexing, why it's critical for scalable applications, and how to get started from scratch.
## Powering the next-gen Apps on Fuel
 Envio proudly supports a rapidly growing ecosystem on the [Fuel Network](https://fuel.network/), providing the most performant and reliable data retrieval to enhance UX across cutting-edge projects like [Swaylend](https://swaylend.com/), [Mira Protocol](https://mira.ly/), [Thunder](https://thundernft.market/), [Props](https://www.propslabs.com/), V12, and more. Building the next big thing on Fuel? Join our Discord and let's chat.
For more on the projects we're powering, check out this [thread](https://x.com/envio_indexer/status/1898023661308645818).
## Visualize Any Address Instantly with Chain Density
 Block explorers show raw data - ChainDensity makes it visual. Instantly track onchain activity for any address and spot trends without complex queries.
* **Estimate Indexing Efforts** – Know event volume before indexing (135M USDC events fetched in 167 sec).
* **Identify Activity Trends** – See contract usage patterns at a glance (e.g., Tornado Cash 100 ETH pool).
Powered by HyperSync, Chain Density delivers fast, intuitive insights.
[Try it for free](https://chaindensity.xyz/)
## Congratulations to the Modular DeFi Denver Hackathon Winners
A huge thanks to the Encode Club team for hosting the Modular DeFi Hackathon in Denver! It was amazing to see all the hackers bring their best ideas to life. Big shoutout to everyone for their incredible submissions.
For more details about our winners and prizes, check out this [thread](https://x.com/envio_indexer/status/1900163549105664042).
## What is Multichain Indexing?
 Multichain indexing is the ability to read, organise, and query data from many chains through one unified system so developers can work with onchain activity without managing separate setups for each network.
Web3 is inherently multichain, but navigating networks can be challenging. Learn how to simplify multichain data access & query your data without managing multiple infras using Envio in our latest [blog](https://docs.envio.dev/blog/what-is-multi-chain-indexing).
## Upcoming Events
* EthGlobal [Pragma Cannes](https://ethglobal.com/events/pragma-cannes): 3rd June 2025
* [DappCon](https://dappcon.io/): 16th → 18th June 2025
* WAGMI Sponsors at [EthCC](https://ethcc.io/): 30th June → 3rd July 2025
## Featured Developer
 This month, we're excited to feature Gabriel Stoica, a passionate developer focused on decentralization, privacy, and bridging the gap between Web2 and Web3. With years of experience crafting smart contracts and building end-to-end dApps, Gabriel has dedicated his work to making Web3 more accessible for all.
Currently leading the development of [Werk](https://www.werk.pro/), a Web3 platform that enables freelancers and entrepreneurs to bring their daily activities onchain, Gabriel has a knack for designing seamless blockchain integrations. He's also built tools to help non-crypto natives interact with blockchain technology, especially in the ReFi/DeFi space.
***"I first heard about Envio on social media and was curious whether its impressive speed would truly be felt throughout the entire development process - from setting up an indexer to configuring and deploying it. Like any modern product, Envio wasn't perfect. I ran into a limitation and decided to reach out on Discord. What surprised me most wasn't just their responsiveness, but the level of openness and genuine collaboration they brought to the table. Their professionalism is matched by their approachability, making the experience seamless and engaging. At its core, Envio is built on rapid iteration and continuous improvement while staying deeply attuned to its users' needs. I'd highly recommend Envio as the go-to indexer for any crypto project looking to combine speed, efficiency, and top-tier support."*** *- Gabriel Stoica, Lead Developer at Werk*
We appreciate Gabriel Stoica's contributions and passion for making Web3 more intuitive and practical for real-world use. Keep up the great work!
Make sure to check out Gabriel's [GitHub](https://github.com/gabrielstoica) and follow them on [X](https://x.com/stoicaxyz) to stay updated on their latest projects and insights.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/0KuEG8cv3T7oNV0rtLKaEP?si=e00c3fc7a6f244ca)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Exploring Real-time Oracle Behavior and Push Based Feeds
> Learn how Oracle Wars uses Envio's HyperIndex to visualise how different oracle providers behave in real-time so you can design more reliable onchain systems.
Co-authors: [Jordyn Laurier](https://x.com/j_o_r_d_y_s), Head of Marketing, and [Jonjon Clark](https://x.com/jonjonclark), Co-Founder at Envio
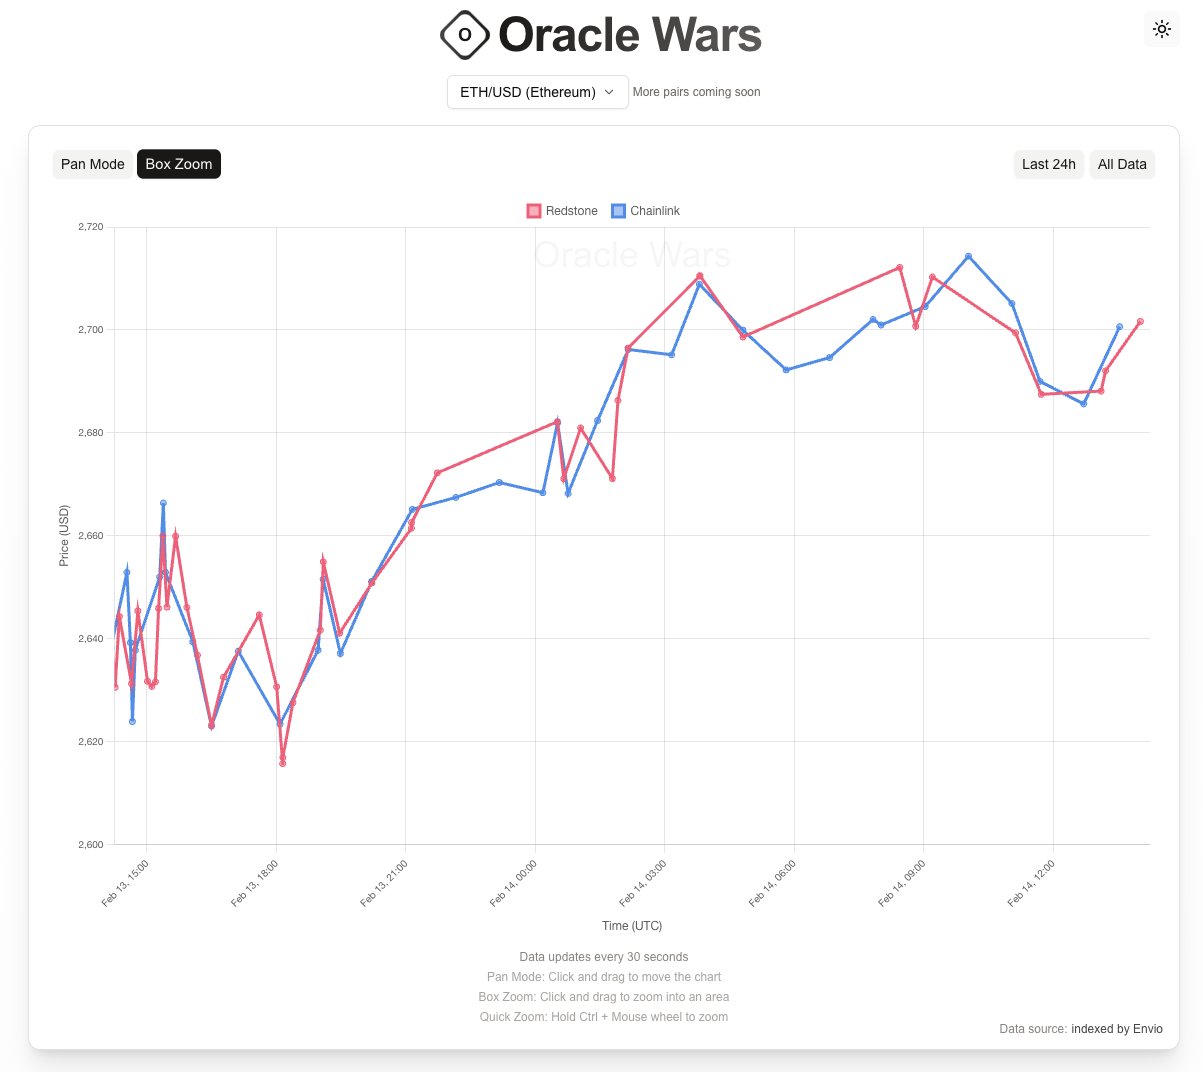 :::note TL;DR
- Oracle Wars is a live dashboard that visualizes real-time oracle behavior on MegaETH, built with Envio HyperIndex in under two hours.
- Push oracles use heartbeat intervals and deviation thresholds to trigger updates. A 0.5% deviation threshold does not mean consecutive onchain prices only differ by 0.5%.
- HyperIndex makes building real-time monitoring tools for high-throughput chains like MegaETH straightforward, with no RPC rate limit concerns.
:::
Oracles are the connection between blockchains and real-world data, enabling smart contracts to interact with off-chain events like asset prices, market rates, or real-time sports scores. Visualizing how they behave in practice offers a new level of clarity for developers building onchain apps.
[Oracle Wars](https://www.oraclewars.xyz/) is a live feed of onchain oracle data that shows how different providers behave in real time. It helps developers visualize and better understand how oracles function under different market conditions, so they can design more reliable and secure smart contracts.
**Please note**: The multi-oracle comparison dashboard shown in earlier versions is no longer live on the site. Oracle Wars currently displays live ETH/USD price oracle updates from the [Redstone Bolt](https://blog.redstone.finance/2025/04/08/introducing-redstone-bolt-the-fastest-blockchain-oracle-to-date/) oracle feed on MegaETH. Oracle Wars remains an educational and experimental tool for surfacing real-time data from various oracle providers.
## What is a blockchain oracle?
In simple terms, oracles allow smart contracts to react to external data sources. Whether it is the latest price of an asset or the outcome of a sporting event, oracles are how the blockchain sees the world.
Over time, oracle architectures have evolved, giving rise to push-based oracles, pull-based oracles, and many more. Each design has trade-offs. This post focuses on push oracles and how they behave from a data perspective.
### Push oracles in practice
A push oracle periodically pushes data onto the blockchain. Your contract reads that data and responds accordingly, whether it is executing a trade, adjusting a loan-to-value ratio, or triggering another onchain action.
Most push oracles use two primary mechanisms:
1. **Heartbeat intervals**: Regular updates (e.g., every 24 hours)
2. **Deviation thresholds**: Immediate updates when data shifts significantly (e.g., 0.5% price movement)
## Visualizing real-time oracle activity with Oracle Wars
Wonder what happens in live conditions during periods of high volatility? That is where Oracle Wars came in. The earlier version of the dashboard showed a live comparison between price feeds from different oracle providers such as [Chainlink](https://chain.link/) and [RedStone](https://www.redstone.finance/). Oracle Wars now focuses on Redstone Bolt ETH/USD updates on MegaETH, but the patterns below still apply to the earlier multi-oracle view.
You will notice that updates are not always evenly spaced. That is the deviation threshold kicking in: when markets get volatile, updates come in fast. When things are calm, fewer updates appear. This is a valuable pattern to observe if you are designing a protocol that depends on accurate and real-time data.
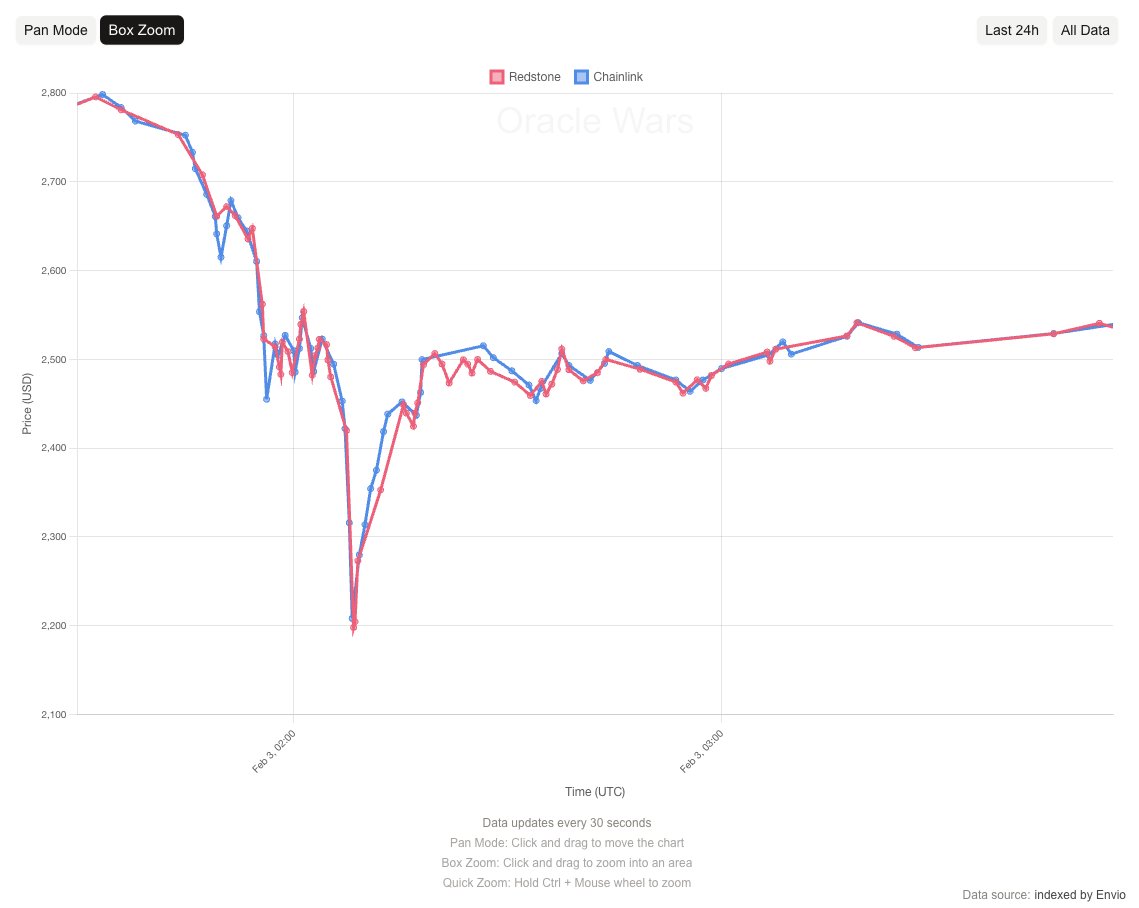 ## Understanding the limitations of deviation thresholds in push oracles
Oracle Wars also shows the maximum deviation between any two consecutive price points over 24 hours. Every DeFi protocol relies on timely and accurate price data, and large shifts between updates can lead to exploit risk, broken assumptions, or cascading failures. This metric gives developers a real-world view of how much price movement can actually occur between updates, even when using well-known oracle providers.
This brings us to a common misunderstanding: deviation thresholds are not strict limits.
Take Chainlink and RedStone, for instance. Both use a 0.5% deviation threshold for price feeds. That should mean the oracle updates whenever the price moves more than 0.5%. But here is the catch:
A 0.5% deviation threshold does not mean consecutive onchain prices will only differ by 0.5%.
In practice, you might see larger deviations. Over 24 hours alone, Oracle Wars recorded deviations of around 0.67% for both providers. This does not mean the oracles were broken. It means they are working as designed. The threshold is more of a trigger condition than a strict upper bound.
If you are competing in security audits on platforms like Sherlock, Code4rena, or CodeHawks, these edge cases are worth thinking through. Your protocol logic needs to account for potentially higher-than-expected changes, especially in volatile markets.
## Is a super-fast push oracle now better than a pull oracle?
With the advent of high-speed chains like MegaETH and Monad, we are starting to see ultra-fast push oracles that update data with each block. This near-instantaneous data feed challenges traditional push oracles, offering freshness comparable to pull oracles, provided transaction costs remain manageable.
On Oracle Wars, you can observe how these super-fast push oracles behave in real time, with feeds like the ETH/USD price on MegaETH. The data is continuously updated, providing a new level of insight into how push oracles might evolve to rival the responsiveness of pull models.
 One aspect that remains intriguing is the frequent occurrence of multiple price updates at the same timestamp. This raises questions about whether these oracles are pushing multiple updates within the same block and the rationale behind this granularity.
While Redstone's Bolt push oracle is an exciting development, it is still early days. It will be interesting to see how other oracle providers and chains approach the super-fast push model. The key question remains: can ultra-fast push oracles maintain the freshness and reliability of pull oracles without significant cost overhead?
## Oracle Wars: powered by Envio's HyperIndex
Oracle Wars was built in under two hours using Envio's HyperIndex, which made indexing real-time oracle data smooth and straightforward. No custom RPC infrastructure was needed, and no rate limit concerns applied.
If you are building dashboards, simulations, or monitoring tools, it is worth checking out. Need help getting started? Feel free to reach out in our Discord or on Telegram.
### Helpful resources
* [HyperIndex Quickstart](https://docs.envio.dev/docs/HyperIndex/contract-import)
* [Guides](https://docs.envio.dev/docs/HyperIndex/configuration-file)
* [Examples](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer)
* [GitHub Repo](https://github.com/enviodev/hyperindex)
Background posts on X that kicked this off:
* [Thinking through oracles with data](https://x.com/jonjonclark/status/1890426833088246054)
* [Understanding the Limitations of Deviation Thresholds in Push Oracles](https://x.com/jonjonclark/status/1892208677815300350)
* [How Much Latency Do High-Frequency Oracle Push Feeds Actually Have?](https://x.com/jonjonclark/status/1903109614318575809)
* [Is a super-fast push oracle now better than a pull oracle?](https://x.com/jonjonclark/status/1909635483182789020)
## Frequently asked questions
### What is the difference between a push oracle and a pull oracle?
A push oracle periodically writes updated data directly to the blockchain. A pull oracle does not write data proactively. Instead, it allows consumers to request data on demand, usually with a small fee. Pull oracles can offer fresher data per request, but push oracles are simpler to integrate since the data is already onchain when your contract needs it.
### Why can the actual price deviation between oracle updates exceed the stated deviation threshold?
Deviation thresholds are trigger conditions, not strict caps. When the threshold is set at 0.5%, the oracle updates whenever the price moves 0.5% from the last onchain price. However, by the time the update transaction is confirmed, the actual market price may have moved further. During high volatility, you can observe deviations larger than the configured threshold.
### How was Oracle Wars built so quickly using Envio?
Oracle Wars was built in under two hours because Envio HyperIndex handles all data ingestion, storage, and GraphQL API generation automatically. The developer only needed to define the oracle contract's ABI, configure the events of interest in `config.yaml`, and write event handlers to store price updates. Envio handles the rest.
### Can HyperIndex handle the data throughput of high-frequency oracle feeds on MegaETH?
Yes. HyperIndex is designed for high-throughput chains and uses HyperSync as its data retrieval layer, which bypasses RPC entirely for historical data and keeps up with real-time blocks efficiently. Oracle Wars on MegaETH demonstrates this with continuous ETH/USD price streaming at sub-millisecond block times.
### Should I use Oracle Wars for production smart contract design decisions?
Oracle Wars is an educational and experimental tool, not a production monitoring service. It is useful for understanding how push oracles behave under real market conditions and for informing your protocol design. For production systems, use the oracle provider's official documentation and run your own analysis of historical deviation data.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update April 2025
> What Envio shipped in April 2025: HyperIndex v2.16 and v2.17, topic filters by contract address, a new dev console, and expanded Monad network support.
 Welcome to the Envio monthly developer update. Here is what shipped in April 2025.
This month, we launched v2.16.0 & v2.17.0, introducing Topic Filters by Contract Addresses for more precise indexing and a new development console to track indexer progress. We've also expanded indexing support for Monad and released tools like Snubb for token approval scanning and Loggregate for real-time EVM event data aggregation and much more.
## HyperIndex Version 2.16.0 & 2.17.0 are now available
*Please note: Current release 2.17.1*
### Topic Filters by Contract Addresses
Besides **
 ### Logger improvements
Added the ability to pass params on a log call:
```
context.log.info("Sucessfully handled Transfer()", { from: event.params.from, to: event.params.to })
These params will be displayed in the logs in your terminal as well as in Hosted Service.
You can also pass an error:
} catch (error) {
context.log.error("Failed ipfs call", error)
}
```
For more information, you can view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)!
## Envio Delivers Modular, Real-Time Indexing for Monad Builders
 Envio's open indexing framework now supports developers building on Monad. [Monad](https://www.monad.xyz/) is pushing the boundaries of performance at the execution layer, and Envio ensures your data pipeline keeps up seamlessly. Instantly index real-time and historical data on Monad using Envio, fast, reliable, and fully customizable. Track complex state changes, power prediction markets, or build whatever you're working on with full control over how your data flows.
We're proud to support Monad developers with the fastest blockchain indexing solution available.
## Introducing Snubb: A Multichain Token Approval Scanner for Your Terminal
 Inspired by [Revoke](https://revoke.cash/), Snubb is an incredibly fast and efficient CLI tool to scan for outstanding token approvals for your address across as many as 70 chains simultaneously.
Try it out now with one terminal command:
```
npx snubb --address
 Introducing [Loggregate](https://www.npmjs.com/package/loggregate), inspired by [LogTUI](https://www.npmjs.com/package/logtui). It's a terminal-native tool that lets developers aggregate and analyze EVM event data in real-time. Whether it's token transfers, swaps, or deposits, Loggregate makes it easy to pull meaningful data from Ethereum and other networks.
With Loggregate, you can quickly calculate key statistics like counts, sums, and averages, all within your terminal. For example, we aggregated live transfer data to reveal 127 million transfers with an average value of $111,727 per transaction.
Built for developers and powered by [HyperSync](https://docs.envio.dev/docs/HyperIndex/overview), Loggregate is fully open-source and extensible.
Try it out now:
```
npx loggregate -e "event Transfer(address indexed from, address indexed to, uint256 value)" -n eth -p "value" -c 0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48 -d 6
```
Explore it on [npm](https://www.npmjs.com/package/loggregate) and check out the open-source [repo](https://github.com/denhampreen/loggregate).
Feel free to check out the original background [post](https://x.com/DenhamPreen/status/1909267253821845707) on X.
## Oracle Wars: Exploring Real-Time Oracle Behavior and Push-Based Feeds
 Powered by HyperIndex, [Oracle Wars](https://www.oraclewars.xyz/) visualizes how oracle feeds behave onchain, highlighting deviations and helping you design more reliable smart contracts.
Learn more about it in our latest [blog](https://docs.envio.dev/blog/oracle-wars).
## Envio's HyperSync Powers Trading Strategy with Multichain Data Collection
 Check out how [Trading Strategy](https://tradingstrategy.ai/) leveraged Envio to collect onchain data across multiple chains and dive into their epic data & research notebook analyzing the performance of 7,000 ERC-4626 vaults across 10 blockchains!
Learn more in this [post](https://x.com/TradingProtocol/status/1910319480887975965).
## HyperSync Now Supports 70+ EVM Networks, Enhancing Real-time Data Access Across Web3
 HyperSync now supports 70+ EVM networks, with many more on the way! Developers and analysts can now access real-time and historical data across various EVM networks with ease. Whether you're tracking activity, analyzing trends, or powering apps, HyperSync makes querying fast, reliable, and effortless.
To learn more about the networks we support, check out our latest [blog](https://docs.envio.dev/blog/envio-hypersync-supports-70-networks).
## Developer Workshop: Indexing Real-Time Data on the XDC Network with Envio
Missed our XDC Developer Workshop? We got you. Check out this step-by-step walkthrough on how to instantly index real-time and historical data on the XDC Network using Envio.
## Upcoming Events
* [Sonic Summit](https://www.soniclabs.com/summit): 6th → 8th May 2025
* [ETHPrague](https://ethprague.com/): 27th → 29th May 2025
* [DappCon](https://dappcon.io/): 16th → 18th June 2025
* WAGMI Sponsors at [EthCC](https://ethcc.io/) Cannes: 30th June → 3rd July 2025
* [Pragma](https://ethglobal.com/events/pragma-cannes) Cannes: July 3rd 2025
## Featured Developer
 This month, we're excited to feature Manu Soman, a talented developer who transitioned from UX design to mastering backend programming in Rust and JavaScript. Manu's work primarily revolves around systems programming and crypto, with a special focus on Solana. Recently, he's been expanding his skill set by exploring Go.
Manu has been actively building out the UniV3 Indexer (coming soon) using Envio, a custom-built multichain indexer for Uniswap V3 powered by HyperIndex. This project tracks top swaps, pools, and trends in real-time, providing invaluable insights into liquidity, trading volumes, fees, and more!
His passion for exploring new technologies and creating robust solutions makes him a standout developer and member of our community.
***"Though my prior experience with blockchain indexers is limited to a small project using Subgraph, I was amazed at how quickly HyperIndex was able to index high-traffic smart contracts like Uniswap. Not only is it fast, it's also easy to set up and fully syncs with chains. Subgraph fell short in all of those areas. Envio's tech support on Discord is also active, responsive, and super helpful. Choosing Envio for indexing is a no-brainer." - Manu Soman***
We're excited to see where Manu's journey takes him next and appreciate his contributions to our community.
Be sure to follow Manu and his work on [X](https://x.com/manu_221b) for the latest updates and insights!
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/5ICzfWy4hkVDOEe0NSOuZy?si=762121a2d366461b)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Announcing the Monad Envio Hackathon Winners
> Winning projects from the Monad Envio Hackathon where developers built high-performance apps and showcased real-time blockchain data indexing on Monad.
 The first-ever Monad hackathon (evm/accathon) brought some serious builder energy. We were proud to support teams with the fastest and most performant data indexing on Monad.
Huge shoutout to the Monad team and every dev who participated, especially those who built with us. Here's a look at the two standout winning submissions that used Envio's open indexing infrastructure to power their projects on Monad.
## Gorillionaire
By [luduvigo](https://x.com/luduvigo), [sammino](https://x.com/sammino__), and [CKobril](https://x.com/CKobril)
[Gorillionaire](https://www.gorillionai.re/) is an AI-powered crypto trading platform delivering real-time Buy/Sell signals by analyzing onchain data, whale activity, token listings, and price feeds. It uses Envio to index data on Monad, giving users and bots fast access to high-signal, real-time insights.
With [Privy](https://www.privy.io/) for authentication and the [0x](https://0x.org/) API for execution, users can act on signals instantly and compete on a gamified leaderboard. The platform also features AI-generated token analytics and gated access to private signals via [Nillion](https://nillion.com/)'s Secret Vault.
Backed by Monad's performance and Envio's real-time indexing infrastructure, Gorillionaire shows what's possible when AI meets production-grade indexing built for scale.
Watch the [demo](https://www.loom.com/share/b302c11bbd2640ec8b4fc1c85d4cf7c8 ).
## MonFundMe
By [defilova1](https://x.com/defilova1) and [hillary_jayden](https://x.com/hillary_jayden)
[MonFundMe](https://monfundme.vercel.app/) is a decentralized fundraising platform built on Monad, offering fast, transparent donations without the friction of Web2. Inspired by GoFundMe but reimagined for Web3, it cuts out high platform fees and removes all-or-nothing fundraising limits.
Powered by Envio, MonFundMe tracks donations in real time, offering complete transparency and faster access to funds. It's an ideal fit for urgent causes or ongoing community campaigns alike.
## How to Index Data on Monad
These projects highlight what's possible when you combine a high-performance chain like Monad with high-performance infrastructure like Envio.
Whether you're building real-time analytics, AI agents, NFTs, or dashboards, indexing data on Monad with Envio is fast, flexible, and fully customizable.
→ [Start indexing Monad data](https://docs.envio.dev/docs/HyperIndex/overview)
## Big thanks to the builders
Huge thanks to the Monad team for pulling together an incredible hackathon. The quality of submissions was seriously impressive, and picking winners wasn't easy. We're grateful to every dev who took the time to build, experiment, and ship using Envio.
We're looking forward to seeing these projects grow and to the next hackathon.
## About Monad
[Monad](https://www.monad.xyz/) is a high-performance L1 built to bring scalability to the EVM without compromising composability. With Monad's parallel execution engine and focus on low-latency performance, it enables devs to build next-gen applications with higher throughput and lower fees, without rewriting existing EVM code.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update May 2025
> What Envio shipped in May 2025: major version releases, CLI improvements, indexer tooling updates, integrations, and DappCon 2025 sponsorship.
 Welcome to the Envio monthly developer update. Here is what shipped in May 2025.
We shipped major versions with powerful new features, which gave indexing performance a serious upgrade, and made the CLI even smoother for automation.
We also landed some exciting integrations, improved tooling across the board, locked in our DappCon 2025 sponsorship and speaking slot, and much more.
## Latest Releases: v2.19.0 → v2.21.3
### Fixed Invalid Rollback on Reorg Bug
In v2.21.3, we addressed an issue with invalid rollbacks during reorgs. We highly recommend upgrading to this version to ensure smoother contract indexing and enhanced system stability.
#### Async Contract Registration
You can now register contracts asynchronously using external logic. Perfect for dynamic deployments where the contract address depends on an external source.
```
NftFactory.SimpleNftCreated.contractRegister(async ({ event, context }) => {
const version = await getContractVersion(event.params.contractAddress);
if (version === "v2") {
context.addSimpleNftV2(event.params.contractAddress);
} else {
context.addSimpleNft(event.params.contractAddress);
}
});
```
#### New EVM Fields
Added `accessList` and `authorizationList` (EIP-7702) to transactions for expanded chain compatibility.
#### JSON Field Support in Schema
You can now define flexible `JSON` fields in your GraphQL schema, ideal for storing dynamic metadata.
```
type User {
id: ID!
metadata: Json!
}
```
#### Effect API for Efficient External Calls
The new Effect API lets you batch, memoize, and deduplicate external calls directly from your handlers.
Paired with loaders, it prevents overfetching and speeds up processing across large batches.
Check out the [walkthrough](https://www.loom.com/share/af44351d1a0a4d81882ea72e2c750c44) on Loom or dive into our [Loaders](https://docs.envio.dev/docs/HyperIndex/loaders) guide to learn more.
#### Contract Registration Boost
Dynamic contract indexing is now dramatically faster. We've deprecated preRegisterDynamicContracts option, it's no longer needed.
#### Improved RPC Error Handling
We added support for 9 more RPC error types to improve retry logic and block range fallback.
#### Non-Interactive CLI Setup
You can now initialize an indexer entirely through the CLI, no prompts, ideal for scripting and automation.
This comes as part of early experimentation with Envio MCP.
For more information, view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)!
## Envio Rolls Out Major Upgrade to Contract Indexing
Our latest performance upgrade unlocks dramatically faster dynamic indexing, especially for contracts deployed by factories. What previously took hours can now be done in minutes, with indexing speeds reaching nearly 30,000 events per second, even while dynamically registering new contracts.
No more two-pass preregistration flows. As of V2.19.0, contract registration happens in real-time, and the preregistration option has been deprecated. HyperIndex supports nested factory contracts, so if your contracts deploy other contracts (even more factories), we'll handle it automatically.
Big shoutout to one of our leading devs, [Dmitry Zakharov](https://x.com/dzakh_dev), for leading the work to streamline contract registration.
Here's a look at the local dev console, a useful way to track indexing speed and progress in real time. In this example, it's tearing through Uniswap V3 data.
 ## Envio Sponsors DappCon 2025
 Envio is one of the proud sponsors of [DappCon](https://dappcon.io/) 2025, joining an incredible lineup of projects pushing Web3 forward.
Be sure to also catch our speaking slot. Envio Co-founder [Denham Preen](https://x.com/DenhamPreen) will be sharing insights on real-time blockchain indexing and building open access to onchain data.
See you in Berlin!
## Exciting DeFi Integration With Nad.fun
 Envio has been integrated with [Nad.fun](https://testnet.nad.fun/), an onchain trading game built on Monad. We recently developed geographic request visualizations as we began serving HyperSync requests from multiple regions. Check out the awesome graphs showcasing where traffic is coming from.
Learn more in this [post](https://x.com/naddotfun/status/1920483968417177768) on X.
## Envio Powers Real-Time Analytics on Monorail
 [Monorail](https://testnet-preview.monorail.xyz/) is now serving up real-time blockchain analytics, powered by our indexing infrastructure on Monad.
From live data to actionable insights, it's all running smoothly under the hood.
Learn more in this [post](https://x.com/envio_indexer/status/1923323564117156011) on X.
## Sonic Summit Keynote
 Learn how to index millions of events on Sonic - in seconds.
Watch our keynote from Sonic Summit and see what real-time indexing looks like on a chain built for speed.
Watch on [YouTube](https://www.youtube.com/watch?v=DYvzHIRinQQ).
## Integration Spotlight: Forever Moments
 [Forever Moments](https://www.forevermoments.life/) just rolled out a robust new indexing setup using Envio. The result? Faster performance, cleaner data feeds, and expanded features. Even better, they'll be open-sourcing their version soon so others can build on it too.
Shout out to the Forever Moments team for pushing onchain media forward.
Learn more in this [post](https://x.com/momentsonchain/status/1927278966659785058) on X.
## Monad Evm/Accathon Winners
 Congratulations to the winners of the first-ever Monad hackathon (evm/accathon). It brought some serious builder energy, and we were proud to support teams with the fastest and most performant data indexing on Monad.
Learn more about the winning projects in our [blog](https://docs.envio.dev/blog/announcing-the-monad-envio-hackathon-winners).
## Upcoming Events
* [DappCon](https://dappcon.io/): 16th → 18th June 2025
* WAGMI Sponsors at [EthCC](https://ethcc.io/) Cannes: 30th June → 3rd July 2025
* [Pragma](https://ethglobal.com/events/pragma-cannes) Cannes: July 3rd, 2025
## Featured Developer
 This month, we're proud to spotlight Paul Berg, co-founder and CEO of Sablier Labs, and a long-time contributor to the open-source Ethereum ecosystem. Known for building tools like [Sablier](https://sablier.com/) and [PRBMath](https://github.com/paulrberg/prb-math), Paul continues to push the space forward with thoughtful, developer-first projects.
***"Envio is the best indexer for EVM chains. Blazing fast indexing and native multichain support make it a game-changer." - Paul Berg, Co-Founder & CEO at Sablier Labs***
We're especially thankful for Paul's ongoing support of Envio and for being such an engaged developer and community member.
We highly recommend exploring Paul's contributions and projects in the space. He's an active voice on [X](https://x.com/PaulRBerg) where he shares insights that go beyond crypto, diving into topics like longevity, epistemology, and physics. Give him a follow and check out his [GitHub](https://github.com/PaulRBerg) to stay in the loop!
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/5qpi10IrOQcNv8ixqWPkFB?si=876ddf7528534b2f)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Index Monad Data Using Envio
> Learn how to efficiently index data on Monad using Envio from setting up your project to mapping contracts and querying onchain events in real-time.
 :::note TL;DR
- Monad is a high-performance EVM Layer 1 with 1-second block times, parallel execution, and 10,000+ TPS, purpose-built for data-rich decentralized applications.
- Envio supports Monad with HyperIndex (full GraphQL indexing), HyperSync (up to 2000x faster than RPC for historical data), and HyperRPC (drop-in RPC proxy backed by HyperSync).
- Compared to The Graph (EVM-only, separate subgraph per chain), Envio's single config covers Monad and all other supported chains through one GraphQL endpoint.
:::
Envio supports developers and data analysts building on Monad with efficient and reliable access to real-time and historical data through a modular indexing stack. Monad's exceptional throughput of up to 10,000 transactions per second, combined with Envio's indexing infrastructure, gives developers everything they need to build highly performant applications.
Monad is a fully EVM-compatible Layer 1 that combines one-second block times, optimistic parallel execution, and single-slot finality. In this blog, we explore why Envio is the right blockchain indexer for Monad and how the indexing stack lets you sync, query, and leverage data on Monad.
## What is Monad?
[Monad](https://www.monad.xyz/) is a high-performance Layer 1 blockchain built to bring scalability to the EVM without compromising composability. With Monad's parallel execution engine and focus on low-latency performance, developers can build efficient applications with higher throughput and lower fees without rewriting existing EVM code.
### Monad features
* One-second block times that reduce transaction finality delays.
* [Parallel execution](https://docs.monad.xyz/monad-arch/execution/parallel-execution) through Monad's superscalar architecture for efficient transaction processing.
* Single-slot finality powered by [MonadBFT](https://docs.monad.xyz/monad-arch/consensus/monad-bft) consensus, ensuring fast and secure state updates.
* A highly optimized storage layer called [MonadDB](https://docs.monad.xyz/monad-arch/execution/monaddb) for efficient state access and management.
* [RaptorCast](https://docs.monad.xyz/monad-arch/consensus/raptorcast) for efficient block transmission and network performance.
* [Asynchronous execution](https://docs.monad.xyz/monad-arch/consensus/asynchronous-execution) to pipeline consensus and execution, extending the execution time budget.
These features make Monad an ideal foundation for data-rich decentralized applications that demand speed, reliability, and seamless composability.
## How to index data on Monad
### HyperIndex
A full-featured blockchain indexing framework that transforms onchain events into structured, queryable databases with GraphQL APIs. It offers Monad developers a complete indexing solution with schema management and event handling, making data on Monad easily accessible and developer-friendly.
[Learn more](https://docs.envio.dev/docs/HyperIndex/overview)
### HyperSync
A high-performance data retrieval layer that gives developers unprecedented access to data on Monad. It directly replaces traditional RPC endpoints, delivering up to 2000x faster data access. HyperSync enables rapid and cost-effective retrieval of both real-time and historical blockchain data and can be used directly for custom data pipelines and specialized applications.
[Learn more](https://docs.envio.dev/docs/HyperSync/overview)
### HyperRPC
A local RPC proxy that supercharges blockchain data access by mapping standard RPC requests to HyperSync's ultra-fast data engine. HyperRPC accepts typical RPC calls and translates them into HyperSync queries, dramatically reducing latency and eliminating the bottlenecks of traditional RPC endpoints.
[Learn more](https://docs.envio.dev/docs/HyperRPC/overview-hyperrpc)
A high-throughput chain deserves infrastructure that can keep up. By utilizing Envio, you can harness the full potential of Monad's high-throughput environment and build fast, reliable applications.
### Additional features for Monad indexers built using Envio
Envio offers a range of advanced capabilities that make it easy to build rich, flexible data pipelines on Monad:
* **Flexible language support**: Configure your event handling in JavaScript, TypeScript, or ReScript.
* **No-code quickstart**: Autogenerate the key boilerplate for an entire indexer project based on single or multiple smart contracts. Deploy within minutes.
* **Multichain support**: Aggregate data across multiple networks into a single database and query everything through a unified GraphQL API.
* **Join onchain and off-chain data**: Connect indexed blockchain data with off-chain data to create a flexible API that goes beyond simple onchain event logs, such as integrating external NFT metadata.
* **Factory contracts**: Automatically register and process events emitted by all child contracts created by a specified factory or dynamic contract.
* **Hosted service**: The simplest way to deploy production-ready indexers on Monad. A managed service platform for building, hosting, and querying Envio's Indexers with guaranteed uptime and performance service level agreements.
## Existing use cases on Monad utilizing Envio
* [Monorail](https://github.com/monorail-xyz/uniswap-v3-pools-indexer)
* [Nad.fun](https://x.com/naddotfun/status/1920483968417177768)
* [Haha Wallet](https://x.com/envio_indexer/status/1892230066328756263)
These are just a few examples of Envio powering applications in the Monad ecosystem. Check out this [thread](https://x.com/envio_indexer/status/1900493623784808598) for more examples, or explore the [Envio Explorer](https://envio.dev/explorer).
## Relevant resources
* [Getting Started](https://docs.envio.dev/docs/HyperIndex/getting-started)
* [Indexing Monad Data with Envio](https://envio.dev/chains/monad-testnet)
* [Envio's HyperSync](https://docs.envio.dev/docs/HyperSync/overview)
* [Envio's Hosted Service](https://docs.envio.dev/docs/HyperIndex/hosted-service)
* [How to build a transfer notification bot with Envio HyperIndex](https://docs.monad.xyz/guides/indexers/tg-bot-using-envio)
## Frequently asked questions
### Does Envio support Monad mainnet and testnet?
Yes. Envio HyperSync and HyperIndex support both Monad mainnet and testnet. You configure the network in your `config.yaml` using the appropriate chain ID, and the indexer handles data retrieval automatically.
### How fast is HyperSync on Monad compared to standard RPC?
HyperSync can deliver up to 2000x faster historical data retrieval than standard RPC on Monad by bypassing the JSON-RPC layer entirely. This means syncing millions of events that would take hours via RPC completes in minutes.
### Can I use Envio to index multiple chains including Monad in a single indexer?
Yes. Add Monad and any other EVM chains to the `networks` section of your `config.yaml`. The resulting indexer processes all chains and exposes a single GraphQL endpoint for all data, making cross-chain queries straightforward.
### What is the difference between HyperSync and HyperRPC on Monad?
HyperSync is a low-level API used internally by HyperIndex for fast historical data retrieval and available as a standalone API for custom pipelines. HyperRPC is a local proxy that maps standard JSON-RPC calls to HyperSync queries, so existing tools that use RPC can benefit from HyperSync's speed without code changes.
### Is Envio the best indexer for Monad compared to The Graph?
The Graph does not natively support Monad. Envio has dedicated HyperSync support for Monad and provides the full HyperIndex framework for building GraphQL APIs on Monad data. Envio's single-config multichain approach also makes it easier to combine Monad data with data from other EVM chains in one indexer.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Index MegaEth Data Using Envio
> Learn how to index data on MegaEth using Envio with a step-by-step guide to project setup, contract mapping, and real-time onchain data querying.
 :::note TL;DR
- MegaETH is a high-performance EVM chain with sub-millisecond block times and 100,000+ TPS, purpose-built for real-time applications that demand scale and speed.
- Envio supports MegaETH with HyperIndex (full GraphQL indexing), HyperSync (up to 2000x faster than RPC for historical data), and HyperRPC (standard RPC proxy backed by HyperSync).
- Oracle Wars, built in under two hours using Envio HyperIndex on MegaETH, demonstrates how quickly developers can build real-time monitoring tools on high-throughput chains.
:::
Envio supports developers and data analysts building on MegaETH with a performant real-time indexing stack designed for high-throughput environments. Get fast, reliable access to both real-time and historical data without the usual bottlenecks.
MegaETH combines sub-millisecond block times with support for over 100,000 transactions per second, built for next-generation applications that demand scale, speed, and reliability. In this blog, we walk through how to index, sync, and query millions of events on MegaETH using Envio.
## What is MegaETH?
[MegaETH](https://www.megaeth.com/) is a high-performance EVM chain purpose-built for real-time applications. It combines sub-millisecond block times with over 100,000 transactions per second, giving developers a foundation to build real-time, responsive, production-grade apps.
Unlike other chains that trade off EVM compatibility for speed, MegaETH keeps your Solidity code, dev tools, and mental models intact. You get Ethereum's programming experience with significantly reduced latency. Whether you are powering data analytics, an onchain game, or a reactive dashboard, MegaETH ensures your stack stays responsive.
### Key features
- [Mini Blocks + EVM Blocks](https://docs.megaeth.com/architecture): Fast mini-blocks (~10 ms) combined with full EVM block finality offer real-time latency and standard blockchain guarantees.
- [High-Throughput Sequencing + Parallel Execution](https://docs.megaeth.com/architecture): MegaETH achieves high TPS through a centralized sequencer architecture and parallel execution across node types.
- [Realtime API Access](https://docs.megaeth.com/realtime-api): The Realtime API surfaces mini-block data via standard JSON-RPC methods, allowing near-instant visibility into state and transaction outcomes.
- **EigenDA-Powered Data Availability**: By integrating EigenDA, MegaETH enables scalable, secure data access without burdening Ethereum's onchain storage.
- **Full EVM Support**: MegaETH supports Solidity, EIP-1559, EIP-7702, large contract sizes, and existing Ethereum tooling out of the box.
These core features make MegaETH a robust environment for building real-time DeFi, high-frequency trading bots, streaming onchain gaming, and on-demand NFT mints.
## How to index data on MegaETH
### HyperIndex
A full-featured blockchain indexing framework that transforms onchain events into structured, queryable databases with GraphQL APIs. It offers MegaETH developers a complete indexing solution with schema management and event handling, making data on MegaETH easily accessible and developer-friendly.
[Learn more](https://docs.envio.dev/docs/HyperIndex/overview)
### HyperSync
A high-performance data retrieval layer that gives developers unprecedented access to data on MegaETH. It directly replaces traditional RPC endpoints for raw block data, delivering up to 2000x faster data access. HyperSync enables rapid and cost-effective retrieval of both real-time and historical blockchain data and can be used directly for custom data pipelines and specialized applications.
[Learn more](https://docs.envio.dev/docs/HyperSync/overview)
### HyperRPC
A local RPC proxy that supercharges blockchain data access by mapping standard RPC requests to HyperSync's ultra-fast data engine. HyperRPC accepts typical RPC calls and translates them into HyperSync queries, dramatically reducing query time and eliminating the bottlenecks of traditional RPC endpoints.
[Learn more](https://docs.envio.dev/docs/HyperRPC/overview-hyperrpc)
MegaETH moves fast, and your indexing stack should too. Envio gives you the infrastructure to match that speed, so you can build applications that are responsive, reliable, and ready for scale.
### Additional features for MegaETH indexers built using Envio
Envio offers a range of advanced capabilities that make it easy to build rich, flexible data pipelines on MegaETH:
* **Flexible language support**: Configure your event handling in JavaScript, TypeScript, or ReScript.
* **No-code quickstart**: Autogenerate the key boilerplate for an entire indexer project based on single or multiple smart contracts. Deploy within minutes.
* **Multichain support**: Aggregate data across multiple networks into a single database and query everything through a unified GraphQL API.
* **Join onchain and off-chain data**: Connect indexed blockchain data with off-chain data to create a flexible API that goes beyond simple onchain event logs, such as integrating external NFT metadata.
* **Factory contracts**: Automatically register and process events emitted by all child contracts created by a specified factory or dynamic contract.
* **Hosted service**: The simplest way to deploy production-ready indexers on MegaETH. A managed service platform for building, hosting, and querying Envio's Indexers with guaranteed uptime and performance service level agreements.
## Existing use cases on MegaETH utilizing Envio
### Oracle Wars
 [Oracle Wars](https://www.oraclewars.xyz/) is an experimental dashboard built with Envio's HyperIndex that visualizes real-time oracle behavior on MegaETH. It showcases how push-based oracles like [RedStone Bolt](https://blog.redstone.finance/2025/04/08/introducing-redstone-bolt-the-fastest-blockchain-oracle-to-date/) behave under live market conditions by tracking heartbeat intervals, deviation thresholds, and latency patterns. The project helps developers understand how oracles operate in volatile environments and the potential risks of delayed or unexpected updates. Built in under two hours, Oracle Wars demonstrates how Envio enables rapid development of real-time monitoring tools on high-throughput chains like MegaETH.
Take a deeper dive in the full [Oracle Wars blog](https://docs.envio.dev/blog/oracle-wars).
This is just one of many examples of what Envio is powering in the MegaETH ecosystem. For more, explore the [Envio Explorer](https://envio.dev/explorer).
## Relevant resources
* [Getting Started](https://docs.envio.dev/docs/HyperIndex/getting-started)
* [Envio's HyperSync](https://docs.envio.dev/docs/HyperSync/overview)
* [Envio's Hosted Service](https://docs.envio.dev/docs/HyperIndex/hosted-service)
* [Indexing MegaETH Data with Envio](https://envio.dev/chains/megaeth)
## Frequently asked questions
### Does Envio support MegaETH mainnet and testnet?
Yes. Envio HyperSync and HyperIndex support both MegaETH mainnet and testnet. You configure the network in your `config.yaml` using the appropriate chain ID, and the indexer handles data retrieval automatically.
### How fast is HyperSync on MegaETH compared to standard RPC?
HyperSync can deliver up to 2000x faster historical data retrieval than standard RPC on MegaETH by bypassing the JSON-RPC layer entirely. This means syncing large datasets that would take hours via RPC completes in minutes.
### Can I index MegaETH alongside other chains in a single Envio indexer?
Yes. Add MegaETH and any other EVM chains to the `networks` section of your `config.yaml`. The indexer processes all chains and exposes a single GraphQL endpoint for all data, making cross-chain queries straightforward from one deployment.
### How does Envio handle MegaETH's mini-block architecture?
Envio's HyperSync is designed for high-throughput chains and handles MegaETH's high block frequency efficiently. For indexing purposes, HyperIndex processes full EVM blocks. If you need mini-block granularity, use the MegaETH Realtime API alongside HyperSync for full-block historical data.
### Is Envio better than The Graph for MegaETH indexing?
The Graph does not natively support MegaETH. Envio has dedicated HyperSync support for MegaETH and provides the full HyperIndex framework for building GraphQL APIs on MegaETH data. Envio's single-config multichain approach also makes it easier to combine MegaETH data with other EVM chains in one indexer.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Building Visualizers & Dashboards on Monad using Envio
> Learn how to build visual dashboards on Monad using Envio to stream real-time and historical data and create interactive analytics experiences with ease.
 :::note TL;DR
- As part of Mission 4 from the Monad Developers community, builders created real-time dashboards and visualizers on Monad using Envio, demonstrating what is possible with a fast chain and a high-performance indexer.
- Envio's HyperSync and HyperIndex power all submissions, handling real-time data streaming with no RPC rate limit concerns and minimal latency.
- All Envio indexers use three core files (config.yaml, schema.graphql, EventHandlers.ts) and deploy to Envio's hosted service via a GitHub push.
:::
As part of Mission 4 from the [Monad Developers](https://discord.gg/monaddev) community, builders were challenged to create real-time dashboards and visualizers on [Monad](https://www.monad.xyz/) using Envio. The results were exceptional, showcasing not only creative visualizers and dashboards but also what is possible with Envio's indexing stack on a high-throughput chain.
Monad's rapid growth has created a strong need for scalable, real-time data infrastructure. Whether tracking protocol activity, analyzing transaction flows, or building live analytics dashboards, a high-performance indexer is critical. These submissions highlight how Envio simplifies data indexing on Monad, enabling rich, real-time applications with speed, accuracy, and ease.
## Monad Super Visualizer
By [@monadicoo](https://x.com/monadicoo)
 This immersive dashboard allows users to explore live activity across the entire Monad chain, with deep visibility into data from specific protocols, contracts, or addresses. Envio powers two core functionalities: streaming live, chain-wide activity to the homepage, and offering a filtered data feed for targeted protocol analysis.
Check it out [here](https://monadviewer.vercel.app/)
## Monad Genki Dama
By [@sifu_lam](https://x.com/sifu_lam)
 A Dragon Ball Z-inspired visual experience that depicts each Monad testnet block as energy contributing to a Genki Dama. Monanimals generate power balls representing transaction types, visually charging the Monad mainnet. Envio's HyperSync ensures real-time accuracy and high throughput with minimal latency.
Check it out [here](https://monad-genki-dama.vercel.app/)
## LendHub Stats Page
By [@bossonormal1](https://x.com/bossonormal1)
 LendHub's dashboard presents real-time analytics for a peer-to-peer NFT lending protocol. It tracks metrics such as loans listed, funded, repaid, claimed, and withdrawn. Custom-built with Envio's config.yaml, schema.graphql, and event handlers, this tool uses a GraphQL endpoint to update dynamically based on key smart contract events.
Check it out [here](https://www.lendhub.xyz/stats)
## Miris
By [@velkan_gst](https://x.com/velkan_gst)
 Miris is a fully featured chain visualizer offering insights into blocks, transactions, and overall network health. Envio handles the indexing of core protocols like Wormhole and Apr Labs, and the Explorer page uncovers activity from additional Monad projects. Built using Apollo Client and Next.js.
## Monad Frens
By [@WagmiArc](https://x.com/WagmiArc)
 Monad Frens delivers real-time and historical chain insights in a visually engaging format, including a pizza-themed chain status display. Envio's HyperSync feeds accurate block and transaction data, while a custom API calculates cumulative transactions since Block 0. The dashboard filters transactions by timestamp, ensuring comprehensive tracking.
Check it out [here](https://dashboard.monadfrens.fun/)
## MonLake
By [@YOUZYPOOR](https://x.com/YOUZYPOOR)
 An aquarium-themed visualization of the Monad testnet where Monanimals represent blocks and treasure chests symbolize various transaction types. Failed transactions appear as jellyfish. Real-time metrics like gas price and transaction distribution are updated using Envio, which indexes all relevant data without stressing RPC endpoints.
Check it out [here](https://monlake.vercel.app/)
## Animonad
By [@Samruddhi_Krnr](https://x.com/Samruddhi_Krnr)
 Animonad tracks live transactions per second across Monad-based dApps like Magma, PancakeSwap, and Narwhal Finance. Each transaction is categorized by address and function signature. Envio's HyperSync facilitates rapid data retrieval to update the UI every second, powering dynamic graphs and protocol rankings.
Check it out [here](https://animonad.vercel.app/)
## NadMetrics
By [@yomax75](https://x.com/yomax75)
 Built with React, TypeScript, Node.js, and WebSockets, NadMetrics is a robust analytics platform offering real-time and historical data for Monad. The dashboard is ideal for developers and analysts monitoring chain volume, transaction flow, and usage trends. Envio serves as the foundation for its high-speed data ingestion.
Check it out [here](https://nadmetrics.com/live)
## Monalytics
By [@gabriell_santi](https://x.com/gabriell_santi)
 An interactive dashboard for real-time visualization of activity on the Monad testnet. It leverages Envio for continuous onchain event streaming and HyperRPC for fast, low-latency data access. The platform delivers both a global view of the network, including metrics like TPS, gas usage, and block entropy, and protocol-specific panels for apps like MonTools, Castora, Ambient, and more.
Check it out [here](https://analytics.montools.xyz/chain)
## Monanimals Blast Mayhem
By [@Pradeeppilot2k5](https://x.com/Pradeeppilot2k5) and [@vidit_0](https://x.com/vidit_0)
 A gamified dashboard transforming real-time blockchain stats into interactive graphics. Monanimals symbolize block numbers, and animated graphs display key metrics such as gas usage, TPS, and block peers. Envio's HyperRPC ensures seamless data delivery for a high-performance user experience.
Check it out [here](https://monanimalblastmayhem.vercel.app/)
## Indexing Monad data using Envio
Envio offers a modular indexing solution for developers and analysts seeking to build scalable, real-time applications on Monad. Whether you are building visual dashboards or analytics platforms, Envio's indexing stack provides the essential building blocks to transform raw blockchain data into accessible, actionable insights.
### HyperIndex
A full-featured blockchain indexing framework that transforms onchain events into structured, queryable databases with GraphQL APIs. It offers Monad developers a complete indexing solution with schema management and event handling, making data on Monad easily accessible and developer-friendly.
[Learn more](https://docs.envio.dev/docs/HyperIndex/overview)
### HyperSync
A high-performance data retrieval layer that gives developers unprecedented access to data on Monad. It directly replaces traditional RPC endpoints, delivering up to 2000x faster data access. HyperSync enables rapid and cost-effective retrieval of both real-time and historical blockchain data and can be used directly for custom data pipelines and specialized applications.
[Learn more](https://docs.envio.dev/docs/HyperSync/overview)
### HyperRPC
A local RPC proxy that supercharges blockchain data access by mapping standard RPC requests to HyperSync's ultra-fast data engine. HyperRPC accepts typical RPC calls and translates them into HyperSync queries, dramatically reducing latency and eliminating the bottlenecks of traditional RPC endpoints.
[Learn more](https://docs.envio.dev/docs/HyperRPC/overview-hyperrpc)
Envio makes it easy to define events, build handlers, and deploy powerful indexers that power dashboards, data tools, analytics platforms, and more at scale.
## Frequently asked questions
### How do I get started building a dashboard on Monad with Envio?
Run `pnpx envio init` to scaffold a new indexer from your contract address or ABI. Define your entities in `schema.graphql`, configure your network and events in `config.yaml`, and write your event handlers in TypeScript. Then run `pnpm dev` locally or deploy to Envio's hosted service.
### Do I need to manage RPC endpoints or infrastructure to build a real-time dashboard on Monad?
No. When using Envio HyperIndex, HyperSync is the default data source and handles all data retrieval automatically, with no RPC URL configuration needed for supported chains. Envio's hosted service manages all infrastructure on your behalf.
### What is the difference between using HyperSync and HyperRPC for building dashboards?
HyperSync is the underlying data layer used by HyperIndex for fast historical backfills and real-time event processing. HyperRPC is a drop-in RPC replacement that maps standard JSON-RPC calls to HyperSync queries, useful when your frontend or tooling is already wired to use RPC. For indexer-based dashboards, you typically use HyperIndex, which uses HyperSync internally.
### Can these dashboards handle Monad's 10,000 TPS throughput without falling behind?
Yes. Envio's HyperSync and HyperIndex are designed for high-throughput chains. The submissions in Mission 4 demonstrate real-time tracking of chain-wide activity on Monad without RPC rate limit issues, using Envio as the indexing layer.
### Can I deploy my Monad dashboard indexer for free with Envio?
Yes. Envio's hosted service includes a free development tier. You connect your GitHub repository, and the Envio Deployments bot auto-deploys on every push. For production workloads requiring SLA guarantees, production tiers are available.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update June 2025
> What Envio shipped in June 2025: new indexer tools, upgraded data pipelines, and expanded network support for multichain development.
 Welcome to the Envio monthly developer update. Here is what shipped in June 2025.
From refining core DX with new helpers and project structure improvements to smarter multichain batching and smoother loader behavior, we shipped updates that made indexing with Envio faster, cleaner, and easier to work with.
We also wrapped up Mission 4 with the Monad community, ran another internal hackathon, hit DappCon Berlin, and plenty more.
## Latest Releases: v2.22.0 → v2.24.0
*Note: Current Release is v2.24.0*
### V2.22.0
Added `context.Entity.getOrCreate` and `context.Entity.getOrThrow` API
```
// Before:
// let pool = await context.Pool.get(poolId);
// if (!pool) {
// pool = {
// id: poolId,
// totalValueLockedETH: 0n
// }
// context.Pool.set(pool);
// }
const pool = await context.Pool.getOrCreate({
id: poolId,
totalValueLockedETH: 0n
})
// Before:
// const pool = await context.Pool.get(poolId);
// if (!pool) {
// throw new Error(`Pool with ID ${poolId} is expected.`)
// }
const pool = await context.Pool.getOrThrow(poolId)
// Will throw: Entity 'Pool' with ID '...' is expected to exist.
// Or you can pass a custom message as a second argument:
const pool = await context.Pool.getOrThrow(poolId, `Pool with ID ${poolId} is expected.`)
```
These are additional helpers for DX improvements. Accessible from both handlers and loaders.
### Loaders Consistency
Loaders optimize indexer performance by running twice: first in parallel for all events in the batch, and then just before handler execution to fetch the latest data. While this process remains unchanged, we've made a few improvements:
* If the loader fails on the first run, the error is silently ignored. This can happen if the entity is only available on the second run, so we continue indexing without interruption.
* The HyperIndex test framework now runs the loaders twice to match the actual indexer logic.
Learn more about optimizing database access with loaders in our [docs](https://docs.envio.dev/docs/HyperIndex/loaders).
### Clever Batch Creation for Unordered Multichain Mode
In previous versions, events for Unordered Multichain Mode were batched based on their order onchain, pulling from all available chains. While this approach worked, it's more efficient for larger indexers relying on loader optimization to batch events from a single chain. This increases the chances of deduplication and batch optimization.
In the latest version, we now prioritize creating processing batches with events from one chain, and only rotate to another chain for the next batch.
Learn more about multichain event ordering in our [docs](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#multichain-event-ordering).
### Flexible Project Structure
Previously, to get HyperIndex running, we had a few requirements that limited flexibility and could be confusing:
* It required **
pnpm-workspaces.yaml** file
* It required **.npmrc** file with shamefully hoisting dependencies
* It required to have the start script in your **package.json** with ts-node generated/src/Index.bs.js
With the latest update, none of these are necessary. Feel free to remove them, and instead of using ts-node generated/src/Index.bs.js, simply replace it with `envio start`.
For more information, view [all past and current release notes](https://github.com/enviodev/hyperindex/releases) on our GitHub.
If you love what we're building as much as we do and want to stay updated on our latest releases and developments, give us a star on [GitHub](https://github.com/enviodev/hyperindex)!
## Mission 4: Building Visualizers & Dashboards on Monad
 As part of Mission 4 with the Monad Developer community, we invited builders to push the limits of real-time dashboards and visualizers on Monad, powered by Envio. The outcome? A wave of standout projects that combined sharp design with serious indexing performance.
Catch the highlights in our [blog](https://docs.envio.dev/blog/how-to-build-visualizers-and-dashboards-on-monad-using-envio).
## Exploring Cross-Chain Arbitrage on Uniswap V4
 Curious how much prices diverge across the same Uniswap V4 pools deployed on different chains? One builder tracked ETH/USDC across Ethereum, Base, Arbitrum, and Unichain, building a real-time dashboard that surfaces price discrepancies, trade sizes, and cross-chain spread opportunities as they appear.
[V4](https://www.v4.xyz/) digs into how often mispricings occur, how significant they get, and how quickly they're arbitraged, highlighting the unique challenges of cross-chain arbitrage.
Read more on [X](https://x.com/jonjonclark/status/1936066826149994585).
## Internal Hackathon
This month, we wrapped up another internal hackathon. 24 hours, 7 hackers, and a stack of ideas. The goal? Build fast, test new concepts, and push Envio's tech in new directions.
Take a look at what we shipped by reading this [thread](https://x.com/envio_indexer/status/1929907328163213409).
## How to Index Data on MegaEth Using Envio
 Envio proudly supports developers and data analysts building on MegaEth with the most performant real-time indexing stack designed for high-throughput environments. Get fast, reliable access to both real-time and historical data without the usual bottlenecks.
Learn more about how to efficiently index data on MegaEth in our [blog](https://docs.envio.dev/blog/how-to-index-megaeth-data-using-envio).
## Join Us at Pragma Cannes
 We're heading to EthGlobal's Pragma in Cannes and running a hands-on workshop built for developers. Learn how to easily access, index, and query multichain data with Envio.
Still need a ticket? Grab $70 off with our [referral link]( https://ethglobal.com/events/pragma-cannes?ref=JONJONNCE ).
## Analyzing Safe Data in Real-time Using HyperIndex
 Missed our speaking slot at DappCon? Check out this session. Learn how Envio's HyperIndex unlocks instant visibility into [Safe](https://safe.global/) transactions, from multisig behavior to governance and fund flows in our [developer workshop](https://www.youtube.com/live/3_5__fpQjKM?t=18381s).
## How to Index Data on Monad Using Envio
 Envio is proud to support developers and data analysts building on [Monad](https://www.monad.xyz/) by providing the most efficient and reliable access to real-time and historical data on the Monad network through our modular indexing stack.
Learn more about how to efficiently index data on Monad in our [blog](https://docs.envio.dev/blog/how-to-index-monad-data-using-envio).
## Upcoming Events
* WAGMI Sponsors at [EthCC](https://ethcc.io/) Cannes: 30th June → 3rd July 2025
* [Pragma](https://ethglobal.com/events/pragma-cannes) Cannes: July 3rd, 2025
* Devconnect Buenos Aires: 17th → 22nd November 2025
## Featured Developer
 This month's featured developer is Thalles Passos. He's a full-stack developer from Brazil who started building professionally at just 17. Thalles began his journey with [Notus Labs](https://notus.team/) and is now working on [Notus API](https://docs.notus.team/docs/guides), where the team is creating a complete suite for account abstraction.
He's also been an active part of the Envio community, giving thoughtful feedback and pushing our indexing tools in real use cases.
***"Initially, I found Envio's developer experience a bit unusual and wasn't convinced it was the right fit. However, once I gave it a real try, I was absolutely blown away by its speed. What other indexers might take weeks to accomplish, Envio completed in mere days, and that instantly hooked me.***
***Their support also truly impressed me. As anyone in web3 knows, getting effective support can be an impossible feat, but Envio completely changed that for me, guiding me through various issues. And as a Brazilian company, where the dollar exchange rate is always a consideration, their pricing structure was incredibly appealing and genuinely surprised us."*** - *Thalles Passos Full-stack Developer At Notus Labs*
Be sure to follow Thalles on [X](https://x.com/thallescomumh) and check out his work on [GitHub](https://github.com/thallesp) to see what he's building next.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/0YkXxUDzOrUSh2h0eznxu6?si=192e7f80b18e478a)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update July 2025
> What Envio shipped in July 2025: built-in cache for effect calls, one-click indexer generator, internal hackathon highlights, and Base ecosystem integrations.
 Welcome to the Envio monthly developer update. Here is what shipped in July 2025.
This month, we embraced built-in cache for effect calls, improved loaders, added new testing utilities, and introduced more control over output configuration. We also launched a one-click indexer generator, shipped fresh hacks from our internal hackathon, and kept refining the overall developer experience.
We made stops at EthCC and Pragma Cannes too, catching up with builders from across the space.
## Latest Releases: v2.23.0 → v2.26.0
_Note: Current Release is v2.26.0_
### Built-in Cache for Effect Calls
```
import { experimental_createEffect, S } from "envio";
export const getMetadata = experimental_createEffect(
{
name: "getMetadata",
input: S.string,
output: {
description: S.string,
value: S.bigint,
},
cache: true, // Simply set cache to true
},
async ({ input, context }) => {}
})
```
Learn more in our [docs](https://docs.envio.dev/docs/HyperIndex/effect-api#persistence) about how to persist the cache on reruns and share it with Hosted Service (alpha).
## V2.23.0
### Embracing loaders
In v2.23.0, we added `context.set`, **
context.unsafeDelete**, and **context.getOrCreate** to loaders.
Add **context.isPreload** to distinguish between the first and second loader run. If you are a power user, from now on we recommend going all-in with loaders and keeping your handlers empty.
Learn more in our dedicated loaders [guide](https://docs.envio.dev/docs/HyperIndex/loaders#going-all-in-with-loaders).
For a full list of changes and more information about current and past releases, view the release notes on our [GitHub](https://github.com/enviodev/hyperindex/releases).
Love what we're building as much as we do and want to stay updated on our latest releases and developments? Give us a star on [GitHub](https://github.com/enviodev/hyperindex)!
## New Feature: Instantly Generate an Indexer from Your Contract Address
 We've refreshed our landing page with a handy new tool. Simply paste your contract address to:
- Get an estimated indexing time
- Receive one command to autogenerate your indexer
- No config files. No guesswork. Just paste and go.
Try it out now by visiting our landing [page](https://envio.dev/).
## Envio Supports Base with Lightning Fast Data Retrieval
 [Base](https://www.base.org/) is booming. Envio's HyperSync supports Base with the most advanced indexing on the market. Sync historical data in minutes, access it up to 2000x faster than RPC, and query structured logs, traces, events, and functions.
Learn how to index millions of events in seconds on Base using Envio in this [thread](https://x.com/envio_indexer/status/1943657401506304443).
## Internal Hackathon July 2025
 We wrapped up another successful internal hackathon during our team offsite this month. The goal? Build tools that push Envio forward. Some are already live.
We run these every last Thursday of the month, so keep an eye out for more builds.
Check out this [thread](https://x.com/envio_indexer/status/1950145932516880605) to see what we built in under 24 hours.
## Supercharge Your Ethereum Data With Envio's HyperSync
 [Ethereum](https://ethereum.org/en/) is on fire. ETF inflows are climbing, regulatory clarity is coming, and price action is picking up. The network's heating up, but can your infrastructure keep up? Envio's HyperSync lets you index millions of events on Ethereum in seconds. No delays. Just fast, structured access to the data that matters.
Learn how in this [thread](https://x.com/envio_indexer/status/1945849077746327639).
## EthCC & Pragma Cannes 2025 Recap
 Big shoutout to the [EthCC](https://ethcc.io/) team for an incredible event, and to [ETHGlobal](https://ethglobal.com/) for hosting a packed Pragma. Non-stop energy, great convos, and a stacked builder crowd.
We're proud to be building alongside some of the sharpest devs and innovators in the space. Huge thanks to everyone who made it happen.
Missed our workshop on lightning-fast multichain indexing? Catch the replay on [YouTube](https://www.youtube.com/watch?v=-sFCbIVVeRw&list=PLXzKMXK2aHh6jZYPY5-YIBzvMtUT3ajjI).
## Upcoming Events
- [Ethereum 10th Anniversary Cape Town](https://lu.ma/ethereum-10y-capetown): → 30th July 2025
- [Devconnect Buenos Aires](https://devconnect.org/): 17th → 22nd November 2025
- [Mobil3 Hackathon Mexico](https://mobil3.xyz/): 20th → 24th August 2025
## Featured Developer
 This month's featured developer is Nikhil, a software developer and technical content creator who's been sharing practical insights with Web3 devs for years. He's worked with teams like Figment, Celo, and Bitquery, crafting developer-facing content. Nikhil has also contributed as a Solidity developer on smaller DeFi projects and is now focusing on personal projects while exploring new opportunities.
He recently got hands-on with Envio, using our tools live on stream to build a custom database for [Across Protocol](https://x.com/AcrossProtocol). His clear walkthroughs on his YouTube [channel](http://youtube.com/@decryptedbytes) and detailed feedback have helped surface valuable insights and made our tooling more accessible to the wider community.
***"I came across Envio through some of the content Jonjon had shared, his projects like [Logtui](https://www.npmjs.com/package/logtui) and [V4](https://www.v4.xyz/), really caught my attention and pushed me to try it out. What I was looking for was a framework that gave me full control and flexibility, and Envio delivers exactly that.***
***I'm currently working on a personal project to build an explorer and analytics platform for Across Protocol, so it felt like a good time to dive into Envio. So far, the experience has exceeded expectations. The documentation is solid, it answers almost every question I've had while working with it."*** - *Nikhil, Developer & Web3 Educator*
Be sure to follow Nikhil on [X](https://x.com/nikbhintade) and check out their work on [GitHub](https://github.com/nikbhintade) to see what they're building next.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/1vyctkfc1CrmnVv2dMCrUo?si=84f39e6a4b1d436e)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update August 2025
> See what Envio shipped in August 2025 including key product updates, internal hackathon projects, new integrations, and expanded network support for builders.
 Welcome to the Envio monthly developer update. Here is what shipped in August 2025.
This month, we shipped preload optimization in v2.27.0, added contract-specific start blocks, and rolled out improved contributing guidelines with built-in Cursor rules. HyperSync also went global, we joined the Mobil3 hackathon in Mexico City, and we built a Telegram-to-Notion sync utility to make CRM management easier.
## Big Releases: v2.27.0
#### Preload Optimization
HyperIndex now preloads entities used by handlers via batched database queries, maintaining the original order of event processing. Paired with the Effect API for external calls, this gives big performance gains over other indexing solutions.
Set a single line in your config and make your handlers run multiple times faster without changing a single line of code:
```
preload_handlers: true
```
*Note: Preload optimization runs your handlers twice. From **
envio@2.27**, all new indexers include it by default.*
#### Contract-specific start block
HyperIndex now supports indexing with start blocks on a per-contract basis (previously, start blocks were only per-network), a highly requested feature contributed by one of our community members, [Rangel Stoilov](https://github.com/rori4).
**Example**: register NFT contracts from a factory but start processing Transfers only from block 30,000,000:
```
name: nft-indexer
description: NFT Factory
networks:
- id: 1337
start_block: 0
contracts:
- name: NftFactory
address: 0x4675a6B115329294e0518A2B7cC12B70987895C4
handler: src/EventHandlers.ts
events:
- event: SimpleNftCreated(string name, string symbol, uint256 maxSupply, address contractAddress)
- name: Nft
# No address field - we'll discover these addresses from SimpleNftCreated events
start_block:
handler: src/EventHandlers.ts
start_block: 30000000 # Overwrite the network start block
events:
- event: Transfer(address from, address to, uint256 tokenId)
```
#### Contributing Improvements
We've updated our **CONTRIBUTING.md** with a detailed guide to navigating the HyperIndex codebase and examples of changes in action. We've also added `.cursor` rules to make developing new HyperIndex features easier.
#### Embrace Vibe-Coding
All new projects now include initial `.cursor` rules to help you build indexers with agent support. Got ideas? Send a PR with rule suggestions to improve the experience for everyone.
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Introducing Shipper Logs
Our new [YouTube series](https://www.youtube.com/@envio_indexer/playlists) covers release updates, new features, and optimizations. Episode 1 covers preload optimization in the v2.27.0 release and how it speeds up indexing.
## Introducing Chain Pulse
 A simple yet powerful tool to quickly check the pulse of multiple blockchains in real time.
With a single command, you can instantly see:
- Throughput
- Transaction activity
- Address activity
- Logs & other key metrics
Chains already cooking include: BNB, MegaETH, Taraxa, Monad, Base, Unichain (Sepolia), and Polygon, with more on the way.
Just run:
```
npx chainpulse
```
Check out the original post on [X](https://x.com/jonjonclark/status/1958497121293787146).
## Envio Powers Zup Protocol
 Easily search millions of pools across multiple DEXs and chains for the best yield per pair.
Zup Protocol now connects you to 1M+ pools and 16 protocols across 5 blockchains.
Powered by Envio, you can compare 1,000+ combos in just 10 seconds.
Check out Zup Protocol: [app.zupprotocol.xyz](https://app.zupprotocol.xyz)
## HyperSync is now Globally Distributed
 We've joined the official list of [K8GB adopters](https://k8gb.io/ADOPTERS/). HyperSync is now served from multiple regions, giving builders faster and more reliable access wherever they are.
## Mobil3 Hackathon - Mexico City
 We had a great time at the [Mobil3](https://mobil3.xyz/) Hackathon in CDMX!
Envio put up a [$2,000 USD bounty](https://x.com/mobil3_xyz/status/1956083421018833267) for the best real-time payments or consumer fintech dashboards built using Envio.
Co-founder Denham Preen was on-site, leading a workshop on HyperIndex + HyperSync and offering 1:1 mentoring to teams throughout the hackathon.
Big thanks to the Mobil3 organizers, the Monaa Foundation, and all the builders who made it an incredible event!
## $943M Frozen
 Say hello to the only list you don't want to be on → [The Banned List](https://thebannedlist.xyz)
This dashboard tracks funds frozen across USDT and USDC on Ethereum mainnet. Right now, over $943M is locked in blacklisted wallets. USDT accounts for $833.78M and USDC makes up $109.73M.
Some of the top wallets hold tens of millions, with one blocked from moving $50.25M. New addresses continue to be blacklisted, including one with $1.37M that keeps trying to move funds out. It's still not clear why these wallets have been targeted, but the dashboard makes it easy to explore and investigate what's happening in real time.
Check out the original post on [X](https://x.com/DenhamPreen/status/1956037853927846261).
## Introducing Liquidator
 Say hello to Liquidator, a new tool that lets you watch liquidation events unfold live in your terminal.
Powered by Envio, it can cut through more than 10 chains in seconds and surface hundreds of thousands of liquidation events, raw, unfiltered, and in real time.
Liquidator is currently live for Aave, with more protocols coming soon.
See the original post on [X](https://x.com/jonjonclark/status/1950609313719783846).
## Telegram to Notion Sync CRM Tool
Managing endless Telegram groups is a hassle, so we built an open-source CLI tool that syncs your Telegram chats into a Notion database.
It finds all chats with a specific substring, adds new ones automatically, and lets you manage them with Kanban, labels, and reminders.
Credits to [Kenau Vith](https://x.com/KenauVith32)
Check it out on [GitHub](https://github.com/enviodev/telegram-to-notiondb)
## Upcoming Events
* [Encode London](https://luma.com/Encode-London-25): 24th → 26th October 2025
* [Devconnect Buenos Aires](https://devconnect.org/): 17th → 22nd November 2025
## Featured Developer
 This month's featured developer is Mikko Ohtamaa, CEO and Co-Founder of [Trading Strategy](https://tradingstrategy.ai/), a Web3 algorithmic trading protocol. Over the past decade, Mikko has served as CTO at leading blockchain companies like LocalBitcoins (one of the first Bitcoin exchanges) and TokenMarket (one of the first ICO platforms), where he helped build infrastructure for more than $1B in digital assets. He's also an active voice in digital rights and open-source communities.
Thanks for being an awesome member of our community, Mikko!
***"We use Envio because it's the first indexer that works. Envio is easy to integrate with modern data research and trading pipelines based in Python. This allows us to integrate more chains, faster, go deeper in data, and finally have a developer experience blockchain programmers have craved for."*** - *Mikko Ohtamaa, CEO & Co-Founder at Trading Strategy*
Be sure to follow them on [X](https://x.com/moo9000) and check out their work on [GitHub](https://github.com/miohtama/) to stay up to date with what they are building.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/3n3qReuChMo6SEgl0Bso3Z?si=23e45edbfde34be1)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update September 2025
> Catch the highlights from Envio's September 2025 developer update including product improvements, new network integrations, and community builder milestones.
 Welcome to the Envio monthly developer update. Here is what shipped in September 2025.
This month, we shipped major new features in v2.28.0 and v2.29.0, introduced Block Handlers and the new `_meta` query, and rolled out significant performance improvements that make indexing even faster and more efficient. We were on the ground at Pragma, ETHGlobal New Delhi, and Sonic Summit in Singapore, explored how AI is shaping blockchain data, and showcased Envio's indexing support for MegaETH along with how we power tools like Liqo, a liquidations leaderboard.
We also kicked off new hackathons with MetaMask and Monad and confirmed our partnership for Encode London next month.
## Big Releases: v2.28.0 → v2.29.0
### V2.28.0
For a visual walkthrough, check out our Shipper Log v2.28.0 on [YouTube](https://www.youtube.com/watch?v=qnYX59jWx_k).
#### Official _meta query
HyperIndex now exposes an official `_meta` query that returns indexing metadata per chain, making it simple to monitor progress and track sync status.
#### 2x faster and cheaper historical sync
Block range selection for log queries has been improved, cutting the number of required requests for some RPC providers in half, making historical sync up to 2x faster. HyperSync responses are now smaller, faster, and simpler, reducing ingress costs while improving performance.
#### Big performance boost for large factories
Indexers handling large numbers of addresses now sync significantly faster. In testing, an indexer with over 2 million addresses synced in about two days instead of four.
#### Subgraph migration Cursor rules cheatsheet
A new Cursor rule example in our repo helps you quickly migrate existing Subgraphs to HyperIndex.
#### Potential breaking change
We've refactored internal tables to focus on a single public entry point: `_meta`. Internal tables such as `chain_metadata`, `event_sync_state`, `persisted_state`,
end_of_block_range_scanned_data, and **dynamic_contract_registry** are now hidden from Hasura, and their internal representations have changed.
If this impacts your setup, reach out, and we'll help you migrate smoothly.
 ### V2.29.0
View Shipper Log on [YouTube](https://www.youtube.com/watch?v=q2CNXIxtVjQ)
#### Block Handlers
You can now run logic on every block or at defined intervals, unlocking new use cases like aggregations, time-series data, and bulk updates using raw SQL.
Example:
```
import { onBlock } from "generated";
onBlock(
{
name: "MyBlockHandler",
chain: 1,
interval: 10,
startBlock: 10_000_000,
},
async ({ block, context }) => {
context.log.info(`Processing block ${block.number}`);
}
);
```
Read our [docs](https://docs.envio.dev/docs/HyperIndex/block-handlers) to learn more about block handlers and the powerful use cases they enable, like:
* Time intervals
* Preset handlers
* Multichain mode
* Different intervals for historical vs. real-time sync
Be sure to check out our [Example Indexer](https://github.com/enviodev/all-contracts-indexer/blob/main/src/EventHandlers.ts) to see Block Handlers combined with Preload Optimization, Effect API queries, and Traces indexing to track all contracts deployed on Mainnet.
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Liqo Brings Real-Time Liquidation Insights Across Major DeFi Protocols
 Track major real-time liquidations in style with [Liqo](https://www.liqo.xyz/), a powerful liquidation leaderboard tool powered by Envio. The new leaderboard gives you a clear view of the most active liquidators across top protocols like [Aave](https://aave.com/), [Morpho](https://morpho.org/), and [Euler](https://euler.finance/), with support for [Twyne](https://twyne.xyz/) coming soon.
It makes exploring liquidation activity across multiple chains and protocols easier than ever, all from one place.
Shoutout to [Saurav](https://x.com/the_truthseekah) for their contributions to the sleek UI upgrade.
Check out the original post on [X](https://x.com/jonjonclark/status/1970164446480695754).
## MetaMask Smart Accounts Hackathon with Monad and Envio
 The MetaMask Smart Accounts Hackathon, in collaboration with Monad and Envio, is now live and will run from September 19 to October 20. Builders are invited to create next-level applications on Monad with a focus on account abstraction and user experience.
Envio is putting up $5,000 for builders:
- $2,000 for Best Use of Envio
- $3,000 in bonuses
In total, $15,000 in prizes are up for grabs.
More details on [Hackquest](https://www.hackquest.io/hackathons/MetaMask-Smart-Accounts-x-Monad-Dev-Cook-Off).
Missed our kickoff call and want to learn more? Check out the broadcast on [X](https://x.com/i/broadcasts/1OwxWemMopDGQ).
## Envio at Pragma and ETHGlobal New Delhi
 The team was in New Delhi for Pragma and ETHGlobal, spending the week with builders, founders, and partners across the ecosystem. Every dapp relies on indexing, but most existing solutions are slow, siloed, and unreliable.
We shared how HyperIndex and HyperSync change that, bringing high performance, multichain infrastructure that scales with the modular ecosystem. The result is faster dapps, richer analytics, and a reliable data backbone developers can build on with confidence.
Big thanks to ETHGlobal, the organisers, partners, and everyone who stopped by to chat with us in New Delhi.
## Envio Supports MegaETH Builders with Lightning-Fast Onchain Data Access
 100k+ TPS, 10+ ggas p/s & less than 10ms blocks? Envio is built for it. Our indexing framework supports developers building on MegaETH with efficient access to both real-time and historical data.
With Envio, you can sync millions of events up to 2000x faster than RPC, making data access easy, fast, and fully customizable even at massive scale. Our performance and mainnet readiness make Envio the ideal choice for builders looking to ship real-time and performant applications on MegaETH.
## The State of AI in Blockchain Data: Neon x Envio
 Blockchain generates endless streams of data, and powerful indexers like Envio make it usable. But what happens when AI steps into the picture?
We joined Neon and Subsquid for a live panel to dig into how AI is reshaping the way data is accessed, organized, and understood in Web3. The conversation explored how intelligence layers can boost indexing workflows, change how developers build with onchain data, and what the future looks like as AI becomes part of the core data stack.
Missed it live? Catch the full recording of the broadcast on [X](https://x.com/i/broadcasts/1BRJjgOnEMjxw).
## Join Envio at Encode London This October
 We're excited to be partners at the Encode London Hackathon and Conference, taking place from 24–26 October at the [Encode Hub](https://hub.encode.club/) in Shoreditch, London. This three-day event brings together builders, researchers, and industry leaders for hands-on hacking, talks, and workshops focused on AI and Web3. Our team will be on the ground all weekend supporting builders, so keep an eye out for us throughout the event.
Plus, we'll be hosting a speaking slot and putting up a couple of bounties with prizes, more details coming soon!
See full event details and get tickets in [Luma](https://luma.com/Encode-London-25).
## Developer Workshop Series: Exploring Aave with Envio
We've kicked off a 16-part developer workshop series, starting with a session focused on exploring Aave data using Envio. The series is designed to help developers get hands-on with real onchain data, showing how to query, index, and build with Aave using Envio.
More workshops are on the way, so be sure to subscribe to this YouTube [channel](https://www.youtube.com/@decryptedbytes/playlists)
to follow along and catch every session.
## Upcoming Events
* [Encode London](https://luma.com/Encode-London-25): 24th → 26th October 2025
* [Devconnect Buenos Aires](https://devconnect.org/): 17th → 22nd November 2025
## Featured Developer
 This month's featured developer is [Ryan Holanda](https://www.linkedin.com/in/ryan-holanda/), Co-founder and CTO of [Zup Protocol](https://zupprotocol.xyz/). A software engineer since the age of 16, Ryan brings advanced expertise across front-end, mobile, blockchain, and design. Driven by a deep passion for DeFi and the Web3 ecosystem, he has dedicated his career to building innovative solutions that empower users and promote financial freedom.
At just 20 years old, Ryan has already won multiple hackathons, contributed to several open source projects, and founded Zup Protocol. He is known for his quick problem-solving skills across a wide range of domains, from Figma design to complex blockchain engineering.
***"Envio is by far the best indexer on the market today. Their innovative approach to indexing blockchain data helped Zup Protocol reduce the sync time for historical liquidity pools data from 3 months with Subgraphs to just 2 days using their hosted service. The Envio team is amazing and always ready to help whenever you need support. If you like great products and cool teams, you should definitely give it a try (pro tip: the migration from Subgraphs is veeeery easy )."*** - *Ryan Holanda, Co-Founder & CTO of Zup Protocol*
Be sure to follow them on [X](https://x.com/moo9000) and check out their work on [GitHub](https://github.com/RyanHolanda) to stay up to date with what they are building.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/2lOYVNjlopciZGOUGdPED1?si=34ee9820a0db4494)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update October 2025
> What Envio shipped in October 2025: v2.31.0 with rollback improvements, Scaffold ETH 2 extension, and highlights from ETHOnline and Encode London.
 Welcome to the Envio monthly developer update. Here is what shipped in October 2025.
Reliability and performance were the big themes this month, with a focus on making indexing even smoother across the board. We rolled out v2.31.0, shipped key upgrades to rollback handling and database performance, and saw some great contributions from the community.
We dive into how a Uniswap alert system uncovered a MEV bot making millions, introduced a new Scaffold ETH 2 extension for faster indexer setup, and shared a look at the team's involvement across ETHOnline and Encode London.
## MAJOR Releases: v2.30.0 → v2.31.0
### V2.30.0: Speed, consistency, and migration-friendly improvements
Version 2.30.0 introduced key performance and compatibility updates focused on reliability at scale.
#### Address Format Configuration
You can now choose between **
checksum** (default) and ** lowercase** addresses directly in your config.yaml. The lowercase option makes it easier to migrate existing SubGraphs and can improve performance in some cases.
```
# config.yaml
address_format: lowercase
```
#### Faster Event Decoder for RPC Source
The RPC source now uses the HyperSync event decoder, offering a significant speed boost compared to the previous Viem decoder.
**Fixes:**
* Resolved a regression in 2.29 that affected indexing at the head Prometheus metric.
* Fixed a race condition during Hasura configuration that occasionally prevented certain GraphQL entities from having read permissions.
**Internal Improvements:**
* Ensured all events from a single block are processed together for stronger data consistency.
* Optimized JS batch creation logic, improving handling for high-volume indexers (100k+ events/sec).
* Adjusted dynamic address persistence to only store processed events.
These updates laid the groundwork for the reorg refactoring work and further system optimizations in 2.31.0 and upcoming releases.
### V2.31.0: Big Reliability Release
#### Rollback On Reorg Refactoring
We completely rebuilt our rollback on reorg logic to make indexing more robust, predictable, and faster. This update introduces a range of performance and stability improvements across indexing and database handling.
#### Highlights
* Fixed all known indexing and rollback on reorg issues
* Optimised database writing logic to reduce latency by dozens of milliseconds
* Reduced internal table size for managing reorg and rollback
* Improved Events Processed counter accuracy for verifying data consistency
#### Nice Additions
* Added subgraph migration cursor rule initialisation support
* Exposed chain readiness status through context.chains
* Expanded supported entity name length up to 63 characters
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## The Uniswap Alert System That Uncovered a MEV Bot Making Millions
 While testing a Uniswap alert system, the team accidentally uncovered an active MEV bot that has been making millions every week on mainnet!
The Telegram bot was meant to ping whenever a Uniswap v4 pool hit $1M TVL. The goal was simple: catch hot new tokens early. Instead, the alerts started firing on pools that barely held any TVL at all.
A closer look revealed flash liquidity spikes driven by an MEV bot executing sandwich attacks across v3 and v4 pools. With over 11 million transactions on mainnet, the onchain data paints a wild picture of just how active these bots are.
Read the original thread on [X](https://x.com/DenhamPreen/status/1976565715940307345) and join the [Telegram group](https://t.me/+n7KoVuOoOPAzNTJk) to see the alerts in action.
## Getting Started with Envio's Scaffold ETH 2 Extension
You can now build [Scaffold ETH 2](https://scaffoldeth.io/extensions) apps that stream real-time data into your frontend without writing any code.
Our curated Envio extension adds automatic indexer generation to your project, making it simple to index all deployed contracts and query their data through a GraphQL API. Your frontend can subscribe to events as they happen, power live dashboards, and stay in sync with the chain with minimal setup.
Check out the [full tutorial](https://docs.envio.dev/docs/HyperIndex/scaffold-eth-2-extension-tutorial) in our documentation.
## ETHGlobal's ETHOnline Hackathon
ETHGlobal's [ETHOnline](https://ethglobal.com/events/ethonline2025/info/start) returned this month, bringing together builders from around the world for one of the largest virtual hackathons of the year.
Envio joined as a proud partner with [$5K in bounties](https://ethglobal.com/events/ethonline2025/prizes#envio) up for grabs. If you're participating, check out our ETHOnline workshop for an introduction to HyperIndex and HyperSync, how to scaffold, deploy, and stream real-time data, plus past winning hacks, tips, and starter repos to help you ship faster.
Our bounties can double as a bonus on top of whatever you're already building, since our tooling plugs right in if you're deploying contracts or working with onchain data.
## Understanding Stablecoin Flows in Real-time
 Stablecoins move faster than ever, and understanding that flow in real-time opens up new layers of insight, from transaction velocity to how close we are to Visa or Mastercard throughput.
Co-Founder Jonjon Clark shared an early look at a live dashboard powered by Envio, which tracks stablecoin transfers across chains in real-time. It highlights what's possible when real-time data meets transparent onchain finance.
Check out the original post on [X](https://x.com/jonjonclark/status/1973431528228045193).
## Scaling Indexing for the Next Generation of Blockchains | Pragma New Delhi Workshop
Blockchain throughput has grown from 15 TPS in early networks to over 400K TPS on chains like Monad, Sonic, and MegaETH. As networks scale execution, Envio focuses on scaling indexing so developers can keep up with real-time data at that speed.
Co-Founder [Denham Preen](https://x.com/DenhamPreen) led a workshop at ETHGlobal Pragma New Delhi, sharing how Envio approaches modern blockchain indexing at scale and what it takes to stay in sync with high-performance chains.
## Envio Showcase
 We launched a new showcase page highlighting live demos built with HyperIndex and HyperSync. From real-time dashboards to onchain visualizations, it's a growing collection of projects built by the community and team to show what's possible with Envio.
Explore the [Showcase](https://docs.envio.dev/showcase) in our documentation.
## Empowering Builders with Real-Time Indexing | Encode London 2025
 Envio joined [Encode London](https://luma.com/Encode-London-25) 2025 as a partner, offering $3K in bounties to support builders throughout the weekend hackathon.
The event brought together developers, founders, and innovators from across the ecosystem for a full weekend of hacking, talks, and late nights at the Hub.
Our Co-Founder, Jonjon Clark, hosted a [workshop](https://x.com/encodeclub/status/1976293549663715658) on real-time blockchain indexing, sharing how developers can move from indexing to streaming data in real-time using Envio's suite of tools.
Well done to all the builders and a big shoutout to the Encode team and organizers for an incredible event!
## Current/Upcoming Conferences, Events & Hackathons
* [EthOnline Hackathon](https://ethglobal.com/events/ethonline2025/info/start): 10th → 31st October 2025
* [Edge City Patagonia](https://www.edgecity.live/patagonia): 18th October → 15th November, 2025
* [Devconnect Buenos Aires](https://devconnect.org/): 17th → 22nd November 2025
## Featured Developer
 This month's featured developer is Enguerrand, a builder with a strong focus on low level tech and decentralized solutions to real world problems.
As CTO at [LONG()](https://long.xyz), he's building plug and play monetization rails for platforms. With a few API calls, LONG() lets teams integrate markets for crowdfunding, fair launches, and rewards, powered by transparent and open market mechanics that make Web3 monetization seamless.
Before LONG(), Enguerrand operated one of Ethereum's earliest mining setups and led engineering at [Lum Network](https://lum.network), contributing to multiple Cosmos based stacks. He's also worked with Ubisoft on community made multiplayer mods for Watch Dogs Legion and created mods for the Mafia series.
He recently contributed to our latest release by adding the ability to access chain readiness status through context.chains, helping improve transparency and reliability across indexing operations.
Always great seeing developers like Enguerrand push performance and developer experience even further with Envio.
***"What I really appreciated at Envio is 1. the DX is great and super easy to move to, 2. it works flawlessly, 3. its SUPER performant compared to competitors and 4. The team is great, super professional and easy to reach." - Enguerrand CTO at LONG()***
Be sure to follow them on [X](https://x.com/enguerrandpp) and check out their work on [GitHub](https://github.com/Segfaultd) to stay up to date with what they're building.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/01eyMwoIMDEmcDjuFJsuhm?si=0319312d9a2d4499)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Encode London 2025: Envio Hackathon Winners
> Discover the Encode London 2025 hackathon winners who built real-time Web3 applications using Envio's blockchain indexing tools.
 Envio proudly partnered with Encode Club at the London 2025 hackathon, offering $3,000 in bounties for builders using [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) and [HyperSync](https://docs.envio.dev/docs/HyperSync/overview). Over one weekend, developers explored how Envio's fast blockchain indexing stack helps power real-time applications in Web3.
The results spoke for themselves.
## Best use of HyperIndex ($1,000): VeriLoan
 **Team:** Myo Myat
**GitHub:** [LuLuKar05/VeriLoan](https://github.com/LuLuKar05/VeriLoan)
**Demo:** [YouTube](https://youtu.be/3t525_GDlCM)
VeriLoan solves one of DeFi's biggest problems: trust. It connects [Concordium](https://www.concordium.com)'s privacy preserving identity proofs with EVM wallets to enable verified borrower profiles. Using Envio HyperIndex, the team aggregated lending data from [Aave](https://aave.com), [Compound](https://compound.finance), and [Spark](https://spark.fi) to generate real-time DeFi credit reports. The project shows how Envio's blockchain indexer can power private, compliant, and capital efficient lending systems built on trust rather than collateral.
## Best use of HyperSync ($1,000): Sniffer
 **Team:** Abdul Aaqib Ali
**GitHub:** [Junaid2005/encode-hack-nov](https://github.com/Junaid2005/encode-hack-nov)
**Demo:** [YouTube](https://youtu.be/HXjyv-ngJis)
Sniffer uses Envio HyperSync and GPT 5 to make blockchain forensics conversational. Investigators can ask natural language questions and receive instant fraud reports with charts, alerts, and insights. HyperSync's real-time data access, up to 2000 times faster than RPC, allows Sniffer to detect suspicious patterns almost immediately in real-time. It is a perfect example of how powerful blockchain indexing tools like Envio can bring AI and onchain analytics together.
## Best use of HyperIndex Runner Up ($500): TradeTrackr
 **Team:** Xferno GT
**GitHub:** [Cozkou/portfi](https://github.com/Cozkou/portfi)
**Demo:** [YouTube](https://youtu.be/uhtsKPt45oE)
TradeTrackr turns crypto trading into a social experience. Users can track their portfolios, join groups, and compete in trading leagues with real-time data indexed by Envio HyperIndex. Built with React, Tailwind, and shadcn UI, it supports Ethereum, Polygon, Base, and Arbitrum. The app uses Concordium for optional identity verification, creating fair competitions and trusted leaderboards. It shows how modern blockchain indexers like Envio make multichain analytics accessible for any Web3 project.
## Conclusion
From AI powered fraud detection to privacy aware lending and social trading apps, these teams proved that real-time data is the foundation of the next generation of decentralized applications.
Envio continues to push the boundaries of performance and reliability for developers who need a fast, scalable, and developer friendly Web3 indexer. Big thanks to the Encode team for having us, all the organizers and partners. Congratulations to all the winners and to every builder who participated.
## About Encode London
Encode London is part of the global [Encode Club](https://www.encodeclub.com) hackathon series, which brings together developers, founders, and students to build new Web3 applications and infrastructure. The event connects builders with technical partners like Envio, helping them explore blockchain indexing, data analytics, and real-time Web3 tools.
Each Encode Club hackathon fosters collaboration, education, and growth within the Web3 community, showcasing how open innovation continues to push blockchain development forward.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# MetaMask Smart Accounts x Monad Hackathon Winners
> Standout projects from the MetaMask Smart Accounts x Monad Dev Cook Off using MetaMask SDKs, Monad, and Envio for real-time onchain indexing.
 # MetaMask Smart Accounts x Monad x Envio Hackathon: Envio Winners
Envio joined [MetaMask](https://metamask.io/en-GB/developer) Developers and [Monad](https://www.monad.xyz) for the MetaMask Smart Accounts Dev Cook-Off, a global hackathon focused on the next generation of wallet and smart account experiences. Over three weeks, builders explored account abstraction, modular execution, AI driven automation, and real-time blockchain data indexing using Envio.
The projects below stood out across innovation, execution quality, and use of Envio's indexing stack.
## Best use of Envio ($2,000): Last Monad
 Last Monad built a live network dashboard that showcases activity across Monad in real-time. Using Envio to index contract events with high speed and accuracy, the team delivered an always up to date view of the chain.
The project shows how real-time blockchain indexers like Envio unlock transparent analytics for high performance networks, giving developers a clear way to explore and understand onchain behaviour as it happens.
## Best Onchain Automation ($1,000): TradeClub
 TradeClub introduced automated onchain execution powered by smart accounts. The project used Envio to index their data to power intent based triggers and automated flows, allowing users to run actions without managing complex backend logic.
It highlights how real-time data from Envio's blockchain indexing solution can support consumer friendly automation and smarter onchain behaviour.
## Best AI Agent ($1,000): ShieldAI
 ShieldAI built an onchain monitoring agent that reacts to blockchain events on Monad in real-time. With Envio providing reliable, indexed data, the agent could track contract interactions, detect anomalies, and surface insights efficiently.
It shows how AI agents become significantly more powerful when they can rely on clean, real-time blockchain data from indexing solutions like Envio.
## Best Consumer App ($1,000): Smart Account Explorer
 Smart Account Explorer created a clear interface for viewing and understanding smart account activity. With Envio's real-time blockchain indexing layer handling the heavy lifting, the app delivered fast lookups of permissions, transactions, and account behaviour without any lag. It made smart accounts feel accessible and transparent for everyday users.
The project shows how consumer apps can improve usability by pairing smart accounts with fast, structured onchain data from indexing solutions like Envio.
## Conclusion
The MetaMask Smart Accounts x Monad Dev Cook Off highlighted what happens when wallet innovation meets real-time data performance. From onboarding to gaming and DeFi UX, each project showed what's possible when you mix smart accounts and efficient blockchain tools like Envio.
Envio's multichain blockchain indexer remains a cornerstone for teams indexing Monad data. Developers can use it to access efficient, real-time data on Monad and any other EVM chain. It gives them a simple way to query and understand Monad activity in real-time without dealing with the overhead of running or scaling their own indexing infrastructure.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update November 2025
> What Envio shipped in November 2025: v2.32.0, Monad Mainnet indexing, Alchemy Subgraphs migration, HyperSync Sonic results, and new Rootstock tutorials.
 Welcome to the Envio monthly developer update. Here is what shipped in November 2025.
November was a big month of product updates, mainnet support and ecosystem activity. We shipped v2.32.0 with new Effect API controls, rolled out full indexing support for Monad Mainnet, and published guidance for teams affected by the Alchemy Subgraphs shutdown to help them migrate their subgraphs to Envio. HyperSync delivered strong benchmarking results on Sonic, and we wrapped up multiple hackathons across MetaMask, Monad and Encode. We also spent time with builders across Edge City in Patagonia and Devconnect in Buenos Aires.
## Exciting Release: Version 2.32.0
### Effect API: Goodbye Experimental Prefix
We've officially removed the
experimental_ prefix from the Effect API and introduced some major improvements to indexing visibility and query flexibility.
**This update comes with two new features:**
- **RateLimit** option lets you control how often Effects are called, with support for custom durations
- Disable cache for specific Effect calls using context.cache = false
Effect API, released on May 8, served us well, and we officially removed the experimental_ prefix from createEffect.
```
export const getMetadata = createEffect(
{
name: "getMetadata",
input: S.string,
output: S.optional(S.schema({
description: S.string,
value: S.bigint,
})),
// Protect your API from burst Effect calls
rateLimit: {
calls: 5,
per: "second"
},
cache: true,
},
async ({ input, context }) => {
try {
const response = await fetch(`https://api.example.com/metadata/${input}`);
const data = await response.json();
return {
description: data.description,
value: data.value,
};
} catch(_) {
// Don't cache failed response
context.cache = false
return undefined;
}
}
);
```
### Development Console Insights
The Development Console now shows detailed performance metrics for every Effect API execution. You can see execution time, rate limits, and caching behaviour at a glance, making it much easier to debug and fine tune performance. A simple way to get more visibility and improve your indexer.
 ### New getWhere.lt Query
You can now use
context.<Entity>.getWhere.<FieldName>.lt to filter entities where field values are lower than a given value. This adds more flexibility for granular queries and custom data filtering directly within your indexers.
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Monad Mainnet Is Live: Learn How to Index Data on Monad
 Envio is live on [Monad](https://www.monad.xyz) Mainnet. Get easy access to real-time and historical data on Monad through performant syncing and a smooth, high performance indexing experience from day one. We supported teams throughout testnet and continue to provide the same fast, reliable indexing setup for a growing ecosystem on Mainnet.
If you are live or going live on Monad and need help getting set up, chat to us about your data needs in [Discord](https://discord.gg/envio). For more on how to index data on Monad, read our [blog article](https://docs.envio.dev/blog/how-to-index-monad-data-using-envio).
## How to Migrate Alchemy Subgraphs to Envio
 Alchemy Subgraphs are officially sunsetting on **December 8, 2025**. Many teams relying on their subgraph service will need a new solution before that date to avoid downtime.
Envio is supporting affected teams with **2 months of free hosting**, faster backfills, multichain indexing, and full white-glove migration support to help you move over smoothly. HyperIndex gives you a modern indexing setup with real-time syncing and production ready deployments, making the transition quick and reliable.
If your subgraphs are affected and you need to migrate, chat to our team in [Discord](https://discord.gg/envio) and we will help you get set up.
For a full walkthrough on how to migrate, read our guide on [How to Migrate Alchemy Subgraphs to Envio](https://docs.envio.dev/docs/HyperIndex/migrate-from-alchemy).
## MetaMask x Envio Advanced Permissions Hackathon is Live
 We have partnered with MetaMask for the Advanced Permissions Dev Cook-Off hackathon, inviting developers to build with ERC-7715 and ship new agent and automation ideas. The hack is now live with $10,000 in total prizes available.
For full details and registration, check the event page on [HackQuest](https://www.hackquest.io/hackathons/MetaMask-Advanced-Permissions-Dev-Cook-Off).
## Stable Radar: Monitoring USDC Transactions in Real-Time
 [Stable Radar](https://www.stable-radar.com) is a new live visualisation that tracks USDC transfers per second across multiple chains including Ethereum, Base, Monad, Sonic, HyperEVM, Worldchain, XDC and many more. It gives a clear view of stablecoin activity as it happens and makes it easy to watch real usage and adoption play out in real-time across different networks. Be sure to check out our [showcase](https://docs.envio.dev/showcase) for more examples of Envio in action.
Check the original post on [X](https://x.com/DenhamPreen/status/1988980819629863208?s=20).
## How to Monetize HyperSync Queries using x402
 A new demo went live this month showing how analysts and builders can monetize their HyperSync queries using [x402](https://www.x402.org). The project combines HyperSync's fast querying and filtering across multiple networks with x402's pay per request model to create simple monetizable blockchain APIs. The example lets users fetch token transfer history for any address across all HyperSync supported networks, with optional filtering by token.
Explore the demo or try it yourself on [GitHub](https://github.com/nikbhintade/x402-hypersync).
## Devconnect and Edge City | Argentina
 The team recently attended [Edge City](https://www.edgecity.live/patagonia) in Patagonia, spending time with builders and getting a closer look at what teams are working on across the ecosystem. It was a good mix of conversations, working sessions and meeting new faces.
From there we headed to Buenos Aires for [Devconnect](https://devconnect.org), catching up with teams throughout the week. We also partnered with Sonic, Pyth and Gelato for an evening [event](https://luma.com/pghidhv5) in the city that brought all of our communities together in one venue.
We wrapped up the month at Devconnect Buenos Aires, taking part in the sessions and connecting with builders across the ecosystem. Big thanks to all the partners, organisers and teams we met along the way.
## Encode Hackathon: Envio's Winners
 Envio partnered with Encode Club at Encode London 2025 and awarded $3,000 in bounties for builders using HyperIndex and HyperSync. The winners included:
* Best Use of HyperIndex ($1,000) → VeriLoan
* Best Use of HyperSync ($1,000) → Sniffer
* HyperIndex Runner-Up ($500) → TradeTrackr
Congratulations to all the builders who took part and big thanks to the Encode team. For the full breakdown of winners and what they built, check our [blog post](https://docs.envio.dev/blog/encode-london-2025).
## High Performance Indexing on Sonic with HyperSync
 Building on Sonic? Envio keeps up.
[Compare Nodes](https://www.comparenodes.com/providers/envio/) recently benchmarked Envio's HyperSync on [Sonic](https://www.soniclabs.com) Mainnet and shared the results publicly. HyperSync provides one of the strongest high performance indexing solutions for Sonic data, backed by real benchmarking results. Their tests scaled from 0 to 1,000 RPC requests per second with full success, and later pushed up to 5,000 requests per second across ten methods. Across two runs they processed around 3.3 million requests in just over thirty minutes!
For the full performance benchmark and breakdown, check Compare Nodes' original post on [X](https://x.com/CompareNodes/status/1991114058771128655?s=20)
## Tutorial: How to Index Rootstock Data with Envio
[Rootstock](https://rootstock.io) released a new tutorial walking developers through how to use Envio to capture and organize onchain events from smart contracts deployed on Rootstock. The session covers everything from setting up a local environment to writing mappings, generating entities and querying indexed data. It is part of the Hacktivator program and gives builders a full walkthrough of how to index Rootstock data using Envio.
See Rootstock's original post on [X](https://x.com/rootstock_io/status/1991446212256624989?s=20).
## MetaMask Smart Accounts x Monad x Envio Hackathon Winners
 We partnered with [MetaMask](https://metamask.io/en-GB/developer) and [Monad](https://www.monad.xyz/brand-and-media-kit) for the Smart Accounts hackathon, which featured a total prize pool of $15,000. This hackathon focused on the next generation of wallet and smart account experiences. Builders explored account abstraction, modular execution, AI driven automation and real-time blockchain indexing using Envio.
For the full list of winners and a detailed breakdown of their projects, read our [blog](https://docs.envio.dev/blog/metamask-smart-accounts-hackathon-winners).
## Current & Upcoming Events
* [MetaMask x Envio: Advanced Permissions Dev Cook-Off Hackathon](https://www.hackquest.io/hackathons/MetaMask-Advanced-Permissions-Dev-Cook-Off): 18th Nov → 31st Dec 2025
* [Solana Breakpoint](https://solana.com/breakpoint): 11th → 13th Dec 2025
## Featured Developer: Kevin Lin
 This month's featured dev is Kevin Lin, a Web3 engineer from Taiwan who has been building dashboards and analytics tools across identity, x402 community activity and prediction markets. Kevin uses Envio as the indexing layer across several of his projects.
For [Self Protocol](https://self.xyz), he indexes real-time registration and disclosure actions to help the team track user growth and protocol health. In the x402 ecosystem, he built this epic [PING dashboard](https://ping-analytics-web.vercel.app/), which tracks community engagement around the first major x402-era meme, including new addresses, interaction patterns and Uniswap V3 and V4 liquidity pools.
His latest project, [PolyPilot](https://polypilot.vercel.app/), is a Polymarket analytics tool that pulls candlestick charts from onchain trades and includes a Market Explorer and Trader Explorer, with more smart money analysis on the way.
Big thanks to Kevin for all his amazing contributions, for being an outstanding member of our community and for everything he continues to build with Envio.
***"What I really like about Envio is that the DX is super smooth. The documentation is excellent, with solid templates and multiple examples, so it's very friendly for vibe coders working on side projects. It also scales nicely from internal dashboards to public products, and lets me focus on what the user sees instead of worrying about indexing infra." - Kevin Lin, Integration Engineer at Self Protocol***
Be sure to follow them on [X](https://x.com/Slutsky___) and check out their work on [GitHub](https://github.com/kevinsslin) to stay up to date with what they are building.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/5soTYYQq62La4bssYRdwzH?si=d1e1faa2d3bf44bd)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update December 2025
> What Envio shipped in December 2025: an early look at HyperIndex v3.0.0, Solana experimentation, Sonic support, and a USDT0 indexing example.
 Welcome to the Envio monthly developer update. Here is what shipped in December 2025.
As we wrap up the end of the year, this update shares what's next for Envio and what we've been working on across the product and community.
This month includes an early look at HyperIndex v3.0.0, early experimentation with Solana support, continued support for teams building on Sonic, updates from Decypted Bytes streams, a new USDT0 indexing example, and our featured developer for December, and much more.
## HyperIndex v3.0.0 is Coming
HyperIndex v3.0.0 is an alpha release introducing ESM support with top-level await and automatic handler registration, alongside lower HyperSync latency and faster queries. The release also includes an experimental ClickHouse Sink, cleaner configuration and defaults, and early experimental Solana support, and much more to come.
### CommonJS → ESM
HyperIndex now runs ESM-only.
This unlocks support for modern libraries and enables **top-level await** across handlers, and `envio init` now comes with new templates and an updated `tsconfig.json`.
```
{
/* For details: https://www.totaltypescript.com/tsconfig-cheat-sheet */
"compilerOptions": {
/* Base Options: */
"esModuleInterop": true,
"skipLibCheck": true,
"target": "es2022",
"allowJs": true,
"resolveJsonModule": true,
"moduleDetection": "force",
"isolatedModules": true,
"verbatimModuleSyntax": true,
/* Strictness */
"strict": true,
"noUncheckedIndexedAccess": true,
"noImplicitOverride": true,
/* For running Envio: */
"module": "ESNext",
"moduleResolution": "bundler",
"noEmit": true,
/* Code doesn't run in the DOM: */
"lib": ["es2022"]
}
}
```
### Top-level await
You can now use top-level await directly in handlers files in HyperIndex V3.
This makes it easy to load things like whitelisted addresses or config from a server instead of hardcoding values into the codebase.
```
import { ERC20 } from "generated";
const ZERO_ADDRESS = "0x0000000000000000000000000000000000000000";
// THIS IS NEW
const addressesFromServer = await loadWhitelistedAddresses();
ERC20.Transfer.handler(
async ({ event, context }) => {
//... your handler logic
},
{
wildcard: true,
eventFilters: [
{ from: ZERO_ADDRESS, to: addressesFromServer },
{ from: addressesFromServer, to: ZERO_ADDRESS },
],
}
);
```
### src/handlers auto registration
HyperIndex v3 automatically registers handler files from src/handlers. You no longer need to list explicit handler paths in `config.yaml`. Just place your files in src/handlers and they will be picked up automatically.
If you prefer a different structure, you can override this using the handlers option. Explicit handler paths still work as before.
*Deprecation: Explicit handler paths are still supported, so no changes are required.*
### Block handler indexers
It is now possible to create indexers using only block handlers. Event handlers are no longer required, and contracts are optional in config.yaml.
### Flexible entity fields
Restrictions on entity field names have been removed. Improvements have also been made to ensure database columns are generated in the same order as they are defined in schema.graphql.
### HyperSync source improvements
Several updates on the HyperSync side reduce latency and unnecessary traffic. These include using server sent events for block updates, more efficient query serialization, and caching for repetitive queries.
### Experimental ClickHouse Sink support
HyperIndex v3 adds experimental ClickHouse Sink support. Postgres remains the primary database. You can additionally sink entities to ClickHouse for restart and reorg resistant workloads.
### Experimental additions: Solana Support
V3 introduces experimental Solana support using RPC as a source. Be sure to check out our [docs](https://docs.envio.dev/docs/HyperIndex/solana) for more information.
Try it out with:
```
pnpx envio init solana
```
### Cleanups and defaults
Deprecated APIs and legacy options have been removed, defaults have been updated, and Node.js 22 is now the minimum supported version. Internal naming and metrics have also been cleaned up for consistency.
This is just the start, with a lot more to come. Stay tuned!
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Envio Supports Developers Building on Sonic
 Envio supports developers and analysts building on Sonic by providing access to real-time and historical onchain data through a reliable indexing layer designed for high-throughput environments.
With Sonic's fast finality and high transaction volumes, teams need indexing infrastructure that can keep up without adding operational complexity. Envio is built to handle these conditions, allowing developers and analysts to query, monitor, and analyze Sonic data efficiently.
This support makes it easier for teams to build data-heavy applications, analytics dashboards, and monitoring tools on Sonic without having to manage indexing infrastructure themselves.
[Start building on Sonic](https://envio.dev/chains/sonic)
## Monad Testnet Re-Genesis: Reindex Required for Envio Users
The Monad testnet underwent a full re-genesis, restarting the network from block 1.
For Envio users indexing Monad, this means indexers need to reindex from block 1 now that the refreshed testnet is live. As part of the re-genesis, all existing onchain state was reset and any deployed contracts needed to be redeployed.
This update removes legacy behaviours from early testnet phases and is expected to reduce state sync time going forward. Teams indexing Monad can continue building against the refreshed testnet.
If you need support reindexing or redeploying after the re-genesis, feel free to reach out to the Envio team in our [Discord](https://discord.gg/envio).
## Envio at Solana Breakpoint 2025 in Abu Dhabi
 The Envio team attended [Solana Breakpoint](https://solana.com/breakpoint) in Abu Dhabi this month, spending time with teams across the Solana ecosystem and learning more about their data needs and how they're building on Solana.
We had a great few days of conversations with builders, protocols, and infrastructure teams, getting a better sense of the tools, patterns, and challenges teams are working through as the ecosystem continues to grow.
Alongside the event, we've been experimenting with early, [experimental Solana support](https://docs.envio.dev/docs/HyperIndex/solana) in Envio. These conversations were valuable in helping us better understand Solana use cases and how indexing infrastructure can support developers and analysts building on the network.
Big thanks to everyone we met and spoke with at Solana Breakpoint. We're looking forward to continuing these conversations as our Solana support evolves. Watch this space.
## Envio Developer Workshops: Decypted Bytes Is Back
 Decypted Bytes streams are back and now running daily at 3:00pm UTC, focused on hands-on developer workflows using Envio.
Recent and upcoming sessions cover practical indexing patterns and data pipelines built with HyperIndex and HyperSync, walking through real examples end-to-end.
#### Recent streams include:
* [Base–Solana Bridge Indexer with HyperIndex](https://www.youtube.com/watch?v=yWfw5gfTibI), showing how to track cross-chain token transfers between Base and Solana
* [DuckDB Sink for HyperSync](https://www.youtube.com/watch?v=8wNprGmbN24), covering how to write indexed blockchain data into DuckDB for local analytics and querying
All stream links, topics, and the full schedule are available via the [Decypted Bytes stream schedule](https://decrypted-bytes.notion.site/2c30f730c03780d8a0a5dfba76689f96?v=2c30f730c03780b7b59b000c65b4467d). Be sure to subscribe to stay up to date with upcoming sessions.
## Envio Adds Support for Tempo
 Envio now supports [Tempo](https://tempo.xyz), giving teams an easier way to index and query data in real-time and build fully customizable data pipelines.
This support makes it simpler for developers to work with Tempo data using [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview), without needing to set up or maintain custom indexing infrastructure. Teams can define their own indexing logic and query patterns while keeping full control over how data flows through their pipelines.
To get started and learn how to index data on Tempo, check out the [setup guide](https://envio.dev/chains/tempo) in the Envio docs.
## How to Index Cross-Chain USDT0 Transfers with Envio
 Learn how to build a [USDT0](https://usdt0.to) Indexer using Envio by exploring this example repository, which demonstrates how to track USDT0 transfers across multiple chains.
The repository shows how to use Envio and HyperSync to index USDT0 activity across supported networks, providing a practical reference for teams working with cross-chain token flows.
You can explore the full example, code, and setup instructions in the [GitHub repository](https://github.com/enviodev/usdt0-indexer).
## Envio Powers Slab.cash with Efficient Data Indexing
 [Slab.cash](https://slab.cash) recently went live, bringing onchain collectibles to users.
Envio proudly powers Slab.cash with efficient data indexing, giving the team easy and reliable access to real-time and historical blockchain data so their app can run smoothly as usage grows.
Big congrats to the Slab.cash team on the launch.
## Getting Started with Envio for the MetaMask Advanced Permissions Hackathon
As part of the [MetaMask x Envio Advanced Permissions Hackathon](https://www.hackquest.io/hackathons/MetaMask-Advanced-Permissions-Dev-Cook-Off), we ran a workshop walking developers through how to get started with Envio and how it can be used during the hackathon.
The session covered setting up an indexer, exploring demos and examples, and understanding how Envio can support data needs while building.
The MetaMask Advanced Permissions Hackathon is live and runs until December 31, 2025. If you're taking part and building with Envio, we're happy to help support teams throughout the hack.
## Current & Upcoming Events
* [MetaMask x Envio: Advanced Permissions Dev Cook-Off Hackathon](https://www.hackquest.io/hackathons/MetaMask-Advanced-Permissions-Dev-Cook-Off): 18th Nov → 31st Dec 2025
## Featured Developer: Port
 This month's featured developer is Port, a builder who loves experimenting with ideas and shipping fast. His journey into development started a few years ago after a health scare, which pushed him to rethink how he wanted to spend his time. Coming from a non-technical background, he began learning web development through The Odin Project and quickly found his way into Web3.
After discovering Monad, Port became deeply involved in the ecosystem, moving on to Speedrun Ethereum and joining [BuidlGuidl](https://buidlguidl.com). Along the way, he built and contributed to a wide range of open source and community projects, including the block explorer for [Scaffold ETH](https://scaffoldeth.io), [address.vision](https://address.vision), and contributions to [abi.ninja](https://abi.ninja).
Today, Port is part of the Monad devrel team, where he continues to explore what the tech makes possible while building and experimenting whenever he gets the chance. Some of his recent and notable projects include NFT Snapshot, [Monad Monitor](https://github.com/portdeveloper/monad-monitor), [Oracle Dashboard](https://oracle-dashboard-seven.vercel.app), Calculate My PnL, [MonadClip](https://monadclip.fun), [Splait](https://github.com/portdeveloper/splait), [Gulltoppr](https://github.com/portdeveloper/gulltoppr), [ConvertETH](https://github.com/portdeveloper/converteth), [Anvuil](https://github.com/portdeveloper/anvuil), and [Vanitoor](https://github.com/portdeveloper/vanitoor).
***"I had an idea, asked it to Claude, and Claude suggested and built the app with Envio without me interfering at any point. I just added the API key to the env file. It was very easy to build with Envio, and the founders are very responsive so you can just ask them questions about how you should be using it." - Port, DevRel at Monad***
Be sure to follow them on [X](https://x.com/port_dev) and check out their work on [GitHub](https://github.com/portdeveloper?tab=repositories) to stay up to date with what they are building.
## Merry Xmas from the Envio Team
 As the year comes to a close, we want to say a big thank you to everyone building with Envio for your contributions, feedback, and continued support throughout the year.
We're wishing many of you a fantastic time over the festive season. The Envio team will still be fully available throughout the Christmas period, so feel free to reach out if you need support or want to chat about what you're building.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/757HncfHabgU6rpMv9748b?si=94a19e83ccdc4f0d)
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Migrate Alchemy Subgraphs to Envio
> Migrate Alchemy Subgraphs to Envio HyperIndex with a clean four-step flow. Keep your existing schema, avoid a full rebuild, and get fast real-time indexing.
 :::note TL;DR
- Alchemy sunset Subgraph support on December 8th, 2025. Teams need a migration path that preserves their existing indexing logic and keeps data live without a full rebuild.
- Envio's HyperIndex accepts your existing schema and mapping logic, adds 142x faster backfills via HyperSync ([Sentio Uniswap V2 Factory benchmark, May 2025](https://github.com/enviodev/open-indexer-benchmark)), and includes 2 months of free hosting for all Alchemy users.
- The migration takes four steps: generate a new HyperIndex project, bring over your schema, move your mapping logic, and use migration cursors to avoid replaying from block zero.
:::
Alchemy sunset their Subgraph support on the **8th December 2025**. If you are running production workloads or preparing for mainnet, you need a stable home for your data and a migration path that keeps most of your existing work intact.
Envio gives you a clean and fast way to migrate your existing Alchemy Subgraphs into Envio's [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) so your data stays live, stable, and real-time. This guide covers exactly how to migrate your Alchemy Subgraph, what changes you need to make, and why Envio is the right destination for your migration.
## Why teams are migrating their Alchemy Subgraphs to Envio
With Alchemy having sunset its Subgraph support, teams need to move quickly. You still rely on your data, you still need your indexers, and rebuilding the entire stack is not realistic in the given timeframe. With Envio, you get:
- 142x faster backfills via HyperIndex
- Multichain indexing supported out of the box
- 2 months free hosting for all Alchemy users
- White-glove migration support tailored for Alchemy Subgraphs
- Support for your existing schema
- A migration flow that avoids a full rebuild
- Efficient access to real-time and historical data
- A seamless cutover to production-ready endpoints
- The option to run locally or fully hosted
Most importantly, Envio lets you bring your current indexing logic across and run it on a much faster setup.
Compared to The Graph (which Alchemy Subgraphs are based on), Envio uses a single `config.yaml` for all chains, delivers faster historical sync via HyperSync, and provides an active team that supports your migration directly.
## Before you migrate
Make sure you have:
- Your current Alchemy Subgraph
- Your ABI or contract addresses
- Node.js and pnpm installed
- Docker Desktop if you want to test locally (Windows users: [WSL](https://learn.microsoft.com/en-us/windows/wsl/install) Windows Subsystem for Linux)
Envio supports both HyperIndex and HyperSync. For migrations, you will be using HyperIndex.
## How to migrate from Alchemy to Envio: a step-by-step guide
Here is the exact workflow to migrate an Alchemy Subgraph to Envio:
### 1. Generate a new HyperIndex project
Run:
```bash
pnpx envio init template --name alchemy-migration --directory alchemy-migration --template greeter --api-token "YOUR_ENVIO_API_KEY"
```
### 2. Bring over your schema
Take your existing Alchemy Subgraph schema and drop it into your new Envio project under the schema directory. If you need help mapping fields, the Envio migration team can do this for you.
### 3. Move over your mapping logic
Copy your Subgraph mappings into Envio mapping files. The structure is familiar if you have used The Graph or Alchemy Subgraphs before. Events and handlers work the same way, so this step should feel straightforward.
### 4. Use migration cursors
Envio has a dedicated migration cursor flow so you do not have to replay your entire chain from block zero. This saves hours for larger projects.
After this, you can run the indexer locally with Docker or deploy directly to [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service). Once deployed, your indexer will sync with HyperSync-level speed.
If you prefer hands-on help, or would like the team to check your setup, reach out in [Discord](https://discord.gg/envio).
## What changes when you leave Alchemy?
Most of your stack stays the same. Here is what changes:
- You are no longer tied to a provider that is ending support
- You get faster indexing with real-time data
- You get an active team supporting your indexers
- You get a future-proof path that consistently scales with you
Your application code stays untouched. Queries stay close to what you already use. And you get more reliability as soon as you deploy.
## Conclusion
Alchemy stepping away from Subgraphs does not mean your project has to stop. Migrating to Envio is fast, stable, and gives you a more reliable long-term foundation for your data.
Move your Subgraphs and keep shipping without interruption.
## Frequently asked questions
### How long does it take to migrate an Alchemy Subgraph to Envio?
Most straightforward migrations can be completed in a few hours to a day, depending on the complexity of your schema and handler logic. Envio offers white-glove migration support and free migration calls for Alchemy users, and the four-step process is designed to preserve your existing work as much as possible.
### Do I need to re-sync from block zero when migrating?
No. Envio has a dedicated migration cursor flow that lets you continue from your current sync position rather than replaying the entire chain history. This is particularly important for large or long-running indexers where a full resync would take hours or days.
### Will my existing GraphQL queries still work after migrating to Envio?
Queries will be very similar. HyperIndex uses a GraphQL API structure that is familiar to anyone who has used The Graph or Alchemy Subgraphs. Field names and filtering conventions may require minor adjustments, but your application logic generally remains intact.
### How does Envio compare to The Graph as an Alchemy Subgraph replacement?
The Graph is the closest architectural equivalent to Alchemy Subgraphs, but it has the same limitations: separate subgraph per chain, slower historical sync, and no native multichain support. Envio delivers 142x faster backfills via HyperSync, supports multichain indexing from a single config, and includes an active team for migration support.
### Is there a free tier on Envio Cloud for migrating teams?
Yes. Alchemy users get 2 months of free hosting when migrating to Envio. A permanent free development tier is also available for all developers. Production tiers with SLA guarantees are available for teams that need them.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Blockchain Indexer For Application Backends
> How blockchain indexers are used in practice to build reliable application backends and how Envio fits into that workflow.
 :::note TL;DR
- Blockchain indexers sit between the chain and your application backend, transforming raw events into structured, queryable data your app can depend on.
- Without an indexer, backends must reconstruct state from history, handle reorgs, and translate raw logs. This complexity compounds as projects scale.
- Envio handles this with a single `config.yaml`, TypeScript event handlers, HyperSync for fast historical sync, and a hosted GraphQL API that works across multiple chains.
:::
A blockchain indexer is rarely the end product. For most teams, it is a core part of the backend that sits between the blockchain and their application.
This post covers how developers actually use a blockchain indexer in practice, the problems it solves at the backend layer, and how Envio fits into that workflow.
## What is a blockchain indexer
A blockchain indexer is a specialised tool that ingests raw blockchain data and transforms it into structured data that application backends can query efficiently.
Rather than querying blocks, transactions, or logs directly through RPC on every request, developers define how blockchain events should be processed and stored. The indexer applies this logic consistently as new data is produced and as historical data is processed.
The result is a reliable, queryable data layer built from onchain activity.
## How blockchain indexers work
In practice, a blockchain indexer follows a simple model:
- Read blockchain data: blocks, transactions, and event logs
- Apply developer-defined logic to the data
- Store the results as structured entities
This logic is deterministic and repeatable. Given the same inputs, the indexer produces the same outputs, which makes indexed data predictable and safe to depend on in application backends.
## The backend problem blockchain apps run into
Application backends need structured state. Blockchains expose raw data. When applications rely directly on RPC endpoints, backend logic quickly becomes responsible for:
- Reconstructing state from historical events
- Tracking contract changes over time
- Handling retries, partial failures, and reorgs
- Translating low-level logs into usable application data
As a project scales, this logic becomes difficult to manage and expensive to maintain. Blockchain indexers absorb this complexity by transforming onchain events into structured, queryable data that backends can depend on.
## What role a blockchain indexer plays
Rather than serving as an analytics layer, a blockchain indexer functions as backend infrastructure. It continuously processes blockchain data and maintains an up-to-date representation of application state that backends can query directly.
In practice, this means:
- Indexing contract events once instead of repeatedly
- Converting raw logs into structured entities
- Persisting derived state that applications can rely on
- Keeping blockchain-specific logic out of application code
This separation makes backends simpler, more predictable, and easier to scale.
## Where the indexed data gets used
Once data is indexed, application backends can:
- Serve APIs backed by indexed blockchain state
- Power user interfaces with pre-processed data
- Track contract state without rescanning history
- Build features that depend on event-driven updates
Because the indexing logic is deterministic and versioned, teams can evolve their schema and handlers without rewriting application logic.
## When a blockchain indexer becomes necessary
Most teams reach for a blockchain indexer when:
- Application logic depends on more than the latest block
- The application needs access to real-time and historical onchain data
- Data needs to be queried frequently or predictably
- The application spans multiple networks and needs a unified data layer
- Backend reliability becomes a priority
At that point, indexing once and querying structured data becomes the simplest approach.
## Building a blockchain indexer with Envio
Envio is designed around a developer-first indexing workflow. Developers define the contracts and events relevant to their application, write deterministic event handlers that map blockchain data into entities, and run the indexer locally to develop and validate logic. The same indexing code runs in hosted environments without changes.
Other indexers like The Graph require separate subgraph deployments per chain and charge query fees through a decentralized network. With Envio, all chains are configured in a single `config.yaml` and exposed through one GraphQL endpoint, with no per-chain deployment overhead.
As projects scale, Envio provides capabilities that support more advanced indexing and production requirements:
- **TypeScript-first:** Write event handling logic in JavaScript or TypeScript.
- **[HyperSync](https://docs.envio.dev/docs/HyperSync/overview):** A high-performance data retrieval layer that delivers up to 2000x faster historical sync than standard RPC. HyperSync is used automatically for all supported networks.
- **No-code quickstart:** Autogenerate a complete indexer project from a single contract address or ABI using `pnpx envio init`. Deploy within minutes.
- **Multichain indexing:** Aggregate data across multiple networks into a single database. Query everything through a unified GraphQL API.
- **Onchain and offchain data:** Combine indexed onchain events with offchain sources such as NFT metadata, token prices from aggregators, or current chain state via RPC.
- **Factory contract support:** Automatically register and process events from child contracts created by a factory or dynamic contract.
- **[Hosted service](https://docs.envio.dev/docs/HyperIndex/hosted-service):** A managed hosting platform for building, hosting, and querying Envio indexers, with 99.99% uptime SLA and GitHub-based auto-deploy.
The result is a backend data layer that remains consistent and reliable across development and production.
## Getting started
Envio is designed to start small and scale as requirements grow:
- Index single or multiple contracts
- Map a small set of events into entities
- Run the indexer locally during development with `pnpm dev`
- Expand the schema and handlers as application requirements grow
For many applications, a blockchain indexer becomes a core part of the backend. Envio supports this workflow from early development through production using the same indexing code across environments.
## Frequently asked questions
### What does a blockchain indexer do in an application backend?
A blockchain indexer reads raw onchain events, applies developer-defined logic, and stores the results as structured entities in a database. Application backends query this database directly instead of hitting RPC endpoints on every request.
### When should I use a blockchain indexer instead of direct RPC calls?
When your application needs historical data, depends on multiple events across contracts or chains, or needs to serve data at scale. Direct RPC calls force the backend to reconstruct state on every query and cannot efficiently handle historical lookups or cross-chain aggregation.
### How does Envio differ from The Graph for backend indexing?
The Graph requires a separate subgraph per chain and charges query fees through a decentralized network. Envio uses a single `config.yaml` for all chains, a single GraphQL endpoint, and TypeScript handlers with no per-query fees. HyperSync also makes historical sync orders of magnitude faster than The Graph's RPC-based approach.
### Does Envio support multichain backends?
Yes. All networks are defined in one `config.yaml`. Envio processes events from each chain in parallel and writes them to a shared database. Your GraphQL API reflects the combined state of all configured chains through a single endpoint.
### Can I run Envio locally during development?
Yes. Running `pnpm dev` spins up the full stack locally using Docker, including the database and GraphQL API. The same handler logic runs locally and in production without modification.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update January 2026
> Envio Developer Update January 2026: HyperIndex V3 alpha with a new testing framework, Vitest support, init improvements, and ecosystem updates.
 Over the past month, we’ve continued making steady progress on HyperIndex V3, with a strong focus on improving how developers build, test, and operate indexers day to day.
This update covers the latest V3 alpha features including a new testing framework, Vitest adoption, improvements to envio init, configuration and state access updates, and several quality of life enhancements across the CLI and TUI. We’re also sharing recent ecosystem updates, production migration examples, and highlights from teams building with Envio.
As always, these changes are incremental building blocks toward a more reliable and flexible indexing workflow, from local development through to production.
## HyperIndex V3 (alpha): Exciting Feature Updates
### BIG feature alert: New Testing Framework (experimental)
V3 supports testing handler logic using real blockchain data, programmatic debugging, & testing block handlers together with event handlers.
The framework also enables LLM workflows using a TDD approach, supports snapshotting indexer behaviour, & runs multiple tests in parallel using isolated worker threads.
```
import { describe, it, expect } from "vitest"
import { createTestIndexer } from "generated"
describe("Indexer Testing", () => {
it("Should create accounts from ERC20 Transfer events", async () => {
const indexer = createTestIndexer();
expect(
await indexer.process({
chains: {
1: {
startBlock: 10_861_674,
endBlock: 10_861_674,
},
},
}),
"Should find the first mint at block 10_861_674"
).toMatchInlineSnapshot(`
{
"changes": [
{
"Account": {
"sets": [
{
"balance": -1000000000000000000000000000n,
"id": "0x0000000000000000000000000000000000000000",
},
{
"balance": 1000000000000000000000000000n,
"id": "0x41653c7d61609d856f29355e404f310ec4142cfb",
},
],
},
"block": 10861674,
"blockHash": "0x32e4dd857b5b7e756551a00271e44b61dbda0a91db951cf79a3e58adb28f5c09",
"chainId": 1,
"eventsProcessed": 1,
},
],
}
`);
}
}
```
### Vitest - Recommended Testing Framework
V3 recommends Vitest as the testing framework for indexer projects.
It replaces **
mocha**, **chai**, and **tsx** with a single package that works out of the box, and supports features like snapshot testing.
All envio init templates have been updated to use Vitest, with tests living directly in src and support for handler specific test files.
```
"scripts": {
- "mocha": "tsc --noEmit && NODE_OPTIONS='--no-warnings --import tsx' mocha --exit test/**/*.ts",
- "test": "pnpm mocha",
+ "test": "vitest run"
},
"devDependencies": {
- "@types/chai": "^4.3.11",
- "@types/mocha": "10.0.6",
- "chai": "4.3.10",
- "tsx": "4.21.0",
- "mocha": "10.2.0"
+ "vitest": "4.0.16"
}
```
### Envio Init Improvements
V3 improves the **envio init** flow to make project setup quicker and smoother.
The ERC20 template has been updated to be multichain and includes the new testing framework as a reference. New projects can also initialize git automatically.
The improved init flow can include additional setup options from upcoming releases, such as configured GitHub CI and an [AGENTS.md](http://agents.md/) file to support LLM-based development.
 ### Expose Indexer Config & State
V3 introduces the indexer value as a replacement for **
getGeneratedByChainId**.
It provides typed chains and contract data from config, along with current indexing state such as **isLive** and **addresses**.
New official types are also introduced:
**Indexer**, **EvmChainId**, **FuelChainId**, **SvmChainId**.
 ### Automatic Contract Configuration
V3 automatically configures all globally defined contracts.
Globally defined contracts are handled automatically, even when they aren’t linked to a specific chain or address.
 ### Conditional Event Handlers
V3 allows event handlers to be enabled or disabled conditionally.
You can now return a boolean value from the eventFilters function to control whether a handler runs.
 ### TUI Love
V3 brings updates to the TUI, making it even more beautiful & compact.
It uses fewer resources, shares a link to the Hasura playground, and adjusts dynamically to the terminal width.
 ### Envio API Token Required
For indexers using HyperSync as a data source, setting an `ENVI0_API_TOKEN` is now required.
You can learn more about API tokens or create one for free at:
[https://envio.dev/app/api-tokens](https://envio.dev/app/api-tokens)
Alongside this, HyperIndex V3 also supports using [Podman](https://podman.io/) for local development, in addition to Docker.
This is just the beginning for V3. Many of these features are early building blocks, with loads more improvements, refinements, and additions already in underway.
For a deeper dive into everything included so far, be sure to check out the full release notes. More updates coming soon.
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Indexing Data on Injective
 Envio proudly supports developers and analysts building on [Injective](https://injective.com) by providing efficient access to real-time and historical onchain data to help teams build robust apps on Injective.
With Envio, teams can sync and query Injective data and define fully customizable indexing logic based on their application needs, without managing indexing infrastructure themselves.
## Migrating Production Subgraphs: Polymarket Indexer
 A common question we hear is what migrating a real production subgraph setup actually looks like in practice.
This example shows every Polymarket subgraph migrated into a single Envio indexer, providing a concrete reference for teams looking to consolidate or migrate existing subgraph infrastructure.
The full implementation is available here:
[https://github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer)
* Note: This example is still a work in progress and under active testing*
## Blockchain Indexer For Application Backends
Indexers are a core part of most application backends, sitting between the blockchain and the app. By transforming raw onchain data into structured, queryable state, indexing removes a lot of complexity from backend logic and makes applications easier to build and scale as they grow. Envio fits into this workflow by providing a consistent indexing layer teams can use from local development through production, without changing how their backend logic is defined.
For more details, read the full [blog](https://docs.envio.dev/blog/blockchain-indexer-application-backends).
## Envio Powers Funnel with Efficient Data Indexing
 [Funnel](https://funnel.markets/) is back after completing a successful backend migration to Envio, which has improved the performance and reliability of the onchain data powering their application heading into 2026.
Funnel uses Envio as its indexing layer to ingest and query onchain data used across the app, including data supporting trading views and listings built on Hyperliquid.
The migration gives the Funnel team a more robust and maintainable data pipeline, allowing them to focus on shipping product without managing indexing infrastructure.
See this post on [X](https://x.com/funnel_markets/status/2009670839940329711) for more info.
## Current & Upcoming Events & Hackathons
* [EthDenver - Denver](https://ethdenver.com/): Feb 17th → 21st
* [EthCC - Cannes](https://ethcc.io/): March 30th → April 2nd
* [EthConf - New York](https://ethconf.com/): June 8th → 10th
## Featured Developer: Zod
 This month’s featured developer is Zod. They’ve been building for a few decades and working onchain since 2019. Over the past year, they’ve been actively using tools like Cursor and exploring in-the-loop agentic development.
In August 2024, Zod took over [Scale](https://scale.farm/) from [Equalizer](https://migrate.equalizer.exchange/) and began transforming it into what they describe as a MetaIndex. This concept focuses on generating revenue across DeFi, rather than limiting revenue to V2 pools, to reduce fresh emissions by earning treasury revenue through other protocols such as Aerodrome.
Scale continues to emit its own token and run liquidity, while integrating Manual CL as part of this evolution.
***“To power our instant-on, data-rich experience across millions of transactions, I need fast, real-time data and deep historical depth with tight latency. I run multiple Envio indexers in parallel with an orchestration layer, which gives us exactly that. Having the full source as a git submodule means I can do deep dives when facing issues, and the team has been super helpful. After previously unhappy experiences with other indexers, Envio has been a massive win.” - Zod, Co-Founder & Lead Developer at Scale***
Well done, Zod. Be sure to check out Scale and follow the team on [X](https://x.com/Scale_Farm) to stay up to date with their latest developments.
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/3LismooWdej6nDxwY9486d?si=00ab83ef26874d81)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you’re working on a Web3 project and want a smoother development process, Envio’s got your back(end). Check out our docs, join the community, and let’s talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update February 2026
> Envio Developer Update February 2026: HyperIndex v3 alpha.13, 3x faster backfills, MegaETH and Sei indexing, new builder series, and Uniswap v4 alert bots.
 February brings a couple new HyperIndex V3 alpha release along with expanded network support and feature updates. We shipped HyperIndex v3.0.0 alpha.13 & alpha.14 with 3x faster historical backfills, support for DESC indices, improved RPC source support, experimental WebSocket support, and a breaking configuration change with `rpc_config` removed in favour of `rpc`, new getWhere API, removed ordered multichain mode support, big Cursor/Claude update and much more!
We expanded our indexing support to MegaETH mainnet and Sei. This month also includes a new multi-part YouTube series on building with HyperIndex and updates to our Uniswap v4 alert bots. Let’s dive in!
## New release: HyperIndex v3.0.0 - alpha.13 & alpha.14
### Alpha.14
### Breaking: New getWhere API
We updated our getWhere API to enable support for multiple filters at a time in future HyperIndex versions. Instead of chaining, it now uses a single function call with filters that match GraphQL style for familiarity.
```
Old: context.Entity.getWhere.fieldName.eq(value)
New: context.Entity.getWhere({ fieldName: { _eq: value } })
```
### Breaking: Removed Ordered Multichain Mode Support
Ordered Multichain Mode forced events across all processed chains into global onchain order, causing significant latency and allowing one bad chain to freeze the entire indexing process.
Events are still processed in onchain order per chain.
For cross-chain interactions, create a partial entity on one chain and finalize it when the related event arrives on another chain. This provides lower latency and a more reliable system.
### Big Cursor/Claude Skills Update
We updated `envio init` to create projects with multiple skills to support agentic driven development.
The LLM landscape changes quickly, so we welcome feedback to improve the skills and the development experience with them.
### Chain Info for Test Indexer
```
const indexer = createTestIndexer();
indexer.chainIds
indexer.chains
indexer.chains[1].id
indexer.chains[1].name
indexer.chains[1].startBlock
indexer.chains[1].endBlock
indexer.chains[1].ERC20.abi
indexer.chains[1].ERC20.addresses // Useful to test dynamic registrations
```
### Alpha.13
This alpha release focused on performance improvements, expanded indexing capabilities, and RPC configuration changes as we continue iterating on V3.
Historical backfills are significantly faster, query flexibility has improved with support for descending indices, RPC sources now expose additional receipt level fields, and configuration has been streamlined with the removal of `rpc_config` in favour of a unified **
rpc** structure.
### 3x Historical Backfill Performance
We introduced chunking logic to request events across multiple ranges at once, fixed overfetching for contracts with much later `start_block` values, and sped up dynamic contract registration.
If data fetching was your bottleneck, this release helps.
**25k events per second is now standard**
### Support for DESC Indices
You can now define indices with descending order to improve query performance:
```
type PoolDayData
@index(fields: ["poolId", ["date", "DESC"]]) {
id: ID!
poolId: String!
date: Timestamp!
}
```
### Improved RPC Source Support
Added support for receipt-only fields:
• **gasUsed**
• **cumulativeGasUsed**
• **effectiveGasPrice**
When one of these fields is added in `field_selection`, HyperIndex will automatically perform an additional `eth_getTransactionReceipt` request.
### WebSocket Support for RPC (Experimental)
Experimental WebSocket support for RPC sources to improve head latency.
If you run into issues, please open a GitHub issue.
```
chains:
- id: 1
rpc:
url: ${ENVIO_RPC_ENDPOINT}
ws: ${ENVIO_WS_ENDPOINT}
for: live
```
### Breaking: rpc_config Removed
`rpc_config` has been removed in favour of **rpc**.
```
- rpc_config
+ rpc:
url: ${ENVIO_RPC_ENDPOINT}
+ for: sync # Add to force RPC usage instead of HyperSync
```
Additionally, you can specify multiple rpcs by providing a list:
```
rpc:
- url: ${ENVIO_RPC_ENDPOINT}
for: sync
- url: ${ENVIO_RPC_FALLBACK_ENDPOINT}
for: fallback
```
If **for** is not provided, the RPC URL is used as a fallback for HyperSync or as the main source when HyperSync is not supported.
We recommend migrating to v3.0.0 alpha. 13 to take advantage of the performance improvements and configuration updates. Give it a test and let us know how it goes. We welcome any feedback as we continue refining V3.
For information, be sure to check out the full release notes. More updates coming soon.
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Indexing Data on MegaEth Mainnet
 [MegaETH](https://rabbithole.megaeth.com) launched its public Mainnet on February 9, 2026, marking the transition from testnet experimentation to a live production network. As a performance focused Ethereum Layer 2, MegaETH is built to support high throughput and low latency execution for onchain applications.
With mainnet now live, developers can deploy and operate applications directly on the network.
Envio proudly supports developers building on MegaETH Mainnet, providing efficient access to real-time and historical data for teams building in the ecosystem.
For more information, see the original [post](https://x.com/envio_indexer/status/2020882703583727665?s=20) on X.
## Building Indexers with HyperIndex
 Check out Decrypted Bytes’ new multi-part YouTube series that walks through how to build with HyperIndex. The series covers building an indexer using HyperIndex from scratch. It follows the full process in a live coding format, showing how to set up, iterate, and expand an indexer step by step.
If you want to learn how to build with HyperIndex in practice, this series is a great place to start.
Be sure to check out the series on [YouTube](https://www.youtube.com/@decryptedbytes/streams) and subscribe to follow along as more parts are released.
## Tyde Terminal Tide Visualiser
 Tyde is an open source terminal based tool that visualises real world tide levels directly in the command line. It renders an animated tide scene with waves, sand, and foam, alongside a 24-hour tide chart showing the current position in the cycle. Sunrise and sunset times are also displayed, with support for a day and night cycle.
Tide predictions are computed locally using harmonic analysis across more than 50 global stations, with no external APIs required.
You can run Tyde directly in your terminal on macOS or Linux, or build it from source.
For more information, see the [GitHub repo](https://github.com/moose-code/tyde) or the original [post](https://x.com/jonjonclark/status/2022313741593858297?s=20) on X.
## Index Data on Sei
 Just Sei it.
Build, index & scale high performance apps on [Sei](https://www.sei.io) using Envio.
Instantly access real-time & historical data on one of the fastest L1 EVMs. Sync millions of events in minutes, 2000× faster than RPC.
Easy. Fast. Fully customizable.
For more information, see the original [post](https://x.com/envio_indexer/status/2021981848557986255?s=20 ) on X.
## Envio Alerts: Uniswap v4 Alert Bots
 Get automated alerts when a Uniswap v4 pool crosses 1m in TVL, including when an MEV bot trade causes the threshold to be hit.
Each alert includes:
* Token pair
* TVL threshold hit
* Chain
The [MEV Alerts bot](https://t.me/+5uldwTve8ns3MDFk) highlights MEV driven TVL events, while the [Liquid Token Alerts bot](https://t.me/+0eUs4YO6HMJlNzBk) tracks pools crossing the 1m TVL mark.
Be sure to join the bot groups on Telegram to receive alerts in real-time and stay up to date on Uniswap v4 pool activity.
## Current & Upcoming Events & Hackathons
* [EthDenver - Denver](https://ethdenver.com/): Feb 17th → 21st
* [EthCC - Cannes](https://ethcc.io/): March 30th → April 2nd
* [EthConf - New York](https://ethconf.com/): June 8th → 10th
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/0CNf2YeAWBGUii76h6xilv?si=575e6a3e76c844b5)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you’re working on a Web3 project and want a smoother development process, Envio’s got your back(end). Check out our docs, join the community, and let’s talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Agentic Blockchain Indexing with Envio Cloud
> Learn how an AI agent can scaffold, configure, and deploy an EVM indexer to Envio Cloud using the envio-cloud CLI, with no manual config required.
 :::note TL;DR
- Envio HyperIndex and the `envio-cloud` CLI enable end-to-end agentic deployment of blockchain indexers with no manual config.
- An AI agent scaffolded, configured, pushed to GitHub, and deployed a wstETH indexer on Monad Mainnet from a single prompt.
- 400,000 events indexed in approximately 20 seconds.
- Every step is CLI-driven and scriptable, with JSON output for downstream agent logic.
:::
Agentic development works best when an AI agent can take a single prompt and run with it, end-to-end, without handing back to a human at every step. For blockchain indexing, that's exactly what we've built at Envio.
With the Envio Cloud CLI (`envio-cloud`) and HyperIndex, an agent can scaffold a production-ready indexer, configure it for any EVM-compatible chain, push it to GitHub, and deploy it to Envio Cloud, without a human ever touching a config file.
**The result: 400,000 events indexed in ~20 seconds**
## What is HyperIndex?
[HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) is Envio's high-performance blockchain indexing framework. It's designed to make indexing fast to build and even faster to run, with support for EVM-compatible networks and a developer experience built around real workflows.
HyperIndex is the default indexing framework for agentic development with the Envio Cloud CLI tool and comprehensive Claude skills. That means when an AI agent needs to spin up a blockchain data pipeline, HyperIndex is the go-to solution.
## The Envio Cloud CLI: `envio-cloud`
The [envio-cloud](https://www.npmjs.com/package/envio-cloud) CLI is the command-line interface for Envio Cloud, the managed infrastructure layer that runs your HyperIndex indexers in production.
With it you can:
- Authenticate via GitHub (`envio-cloud login`)
- Register a new indexer pointing to your GitHub repo (`envio-cloud indexer add`)
- Monitor sync progress and deployment status in real-time (`envio-cloud deployment status`, `envio-cloud deployment metrics`)
- Promote deployments to production (`envio-cloud deployment promote`)
- Pull JSON output for any command (`-o json`), making it fully scriptable and agent-friendly
_No dashboard required. Everything that matters is exposed through the CLI._
## End-to-End: Agentic deployment of a wstETH indexer on Monad
Here's the full workflow an agent ran to deploy a live ERC20 indexer for wstETH on [Monad](https://www.monad.xyz) Mainnet, start to finish.
### Step 1: Scaffold the indexer
```
pnpx envio init template -t erc20 -l typescript -d ./my-indexer
```
The `envio` CLI scaffolds a TypeScript ERC20 indexer template. No API token is needed at this stage as authentication is handled through the hosted service at deployment time.
### Step 2: Configure for Monad
The agent edits `config.yaml` to target the wstETH contract on Monad Mainnet (chain ID 143, contract address `0x10Aeaf63194db8d453d4D85a06E5eFE1dd0b5417, start_block: 0`).
Then runs codegen and a type check to confirm everything is clean:
```
pnpm codegen
pnpm tsc --noEmit
```
_Note: the ERC20 template test file references a different contract address and network, so any resulting type errors need to be fixed before the type check passes._
### Step 3: Push to GitHub
Create a public repo and push:
```
gh repo create wsteth-monad-indexer-demo --public
git init && git add . && git commit -m "init"
git push -u origin main
```
If the push fails because your GitHub token lacks permission to push workflow files (like `.github/workflows/test.yaml`), refresh auth with workflow scope:
`gh auth refresh -s workflow`
Envio Cloud deploys from the `envio` branch by default, so create and push it:
```
git checkout -b envio && git push -u origin envio
```
### Step 4: Connect the Envio GitHub Bot
The Envio GitHub App must have access to the repo before deployments will trigger. If the repo is not already linked, visit:
[https://github.com/apps/envio-deployments/installations/select_target](https://github.com/apps/envio-deployments/installations/select_target)
Then grant the bot access to the `wsteth-monad-indexer-demo` repository.
### Step 5: Deploy
```
pnpx envio-cloud login
pnpx envio-cloud indexer add
--name wsteth-monad-indexer-demo
--repo wsteth-monad-indexer-demo
--description "wstETH ERC20 indexer on Monad"
--branch envio
--skip-repo-check
--yes
```
### Step 6: Verify
```
pnpx envio-cloud indexer get wsteth-monad-indexer-demo {org}
pnpx envio-cloud deployment status wsteth-monad-indexer-demo
 See the full walkthrough on [Loom](https://www.loom.com/share/09cdac43b18f4143ad78b18c8c8a492b), covering the complete agent driven workflow from scaffold to deployment.
## Why this matters for agentic development
The blockchain data layer has historically been one of the friction points in agentic workflows. Spinning up an indexer meant reading docs, manually editing configs, managing infrastructure, and waiting for sync.
HyperIndex and the `envio-cloud` CLI change that equation. Every step in the workflow above is scriptable, CLI-driven, and designed to be executed by an agent without human intervention. The JSON output flag (`-o json`) makes it straightforward to pipe deployment status into downstream logic. The GitHub-native deployment flow means agents that can commit code can deploy indexers.
This is what it looks like in practice for HyperIndex to be the default indexing framework for agentic development.
## Getting started
Install the Envio Cloud CLI:
```
npm install -g envio-cloud
```
Scaffold your first indexer:
```
pnpx envio init template -t erc20 -l typescript -d ./my-indexer
```
Whether you're building on Monad, Ethereum, or any other EVM compatible network, Envio enables agent driven indexing from first prompt to live deployment. The GitHub-native deployment flow means agents that can commit code can deploy indexers in minutes.
Be sure to check out our [Envio Docs MCP Server](https://docs.envio.dev/blog/envio-docs-mcp-server) for AI-assisted indexer development.
## Frequently Asked Questions
### What is agentic blockchain indexing?
Agentic blockchain indexing is the process of using an AI agent to scaffold, configure, and deploy a blockchain indexer without manual human intervention. With Envio HyperIndex and the envio-cloud CLI, an agent can go from a single prompt to a live production indexer in minutes.
### What is the envio-cloud CLI?
The envio-cloud CLI is the command-line interface for Envio Cloud, the managed infrastructure layer that runs HyperIndex indexers in production. It supports login, indexer registration, deployment monitoring, and promotion, all scriptable with JSON output via the `-o json` flag.
### How fast is Envio HyperIndex for historical sync?
In independent benchmarks run by Sentio, HyperIndex completed the Uniswap V2 Factory sync in 8 seconds, 142x faster than The Graph and 15x faster than the nearest competitor (Subsquid). In the agentic deployment demo, 400,000 wstETH events on Monad Mainnet were indexed in approximately 20 seconds.
### Which chains does Envio support for agentic indexing?
Envio supports any EVM-compatible chain. HyperSync natively covers
 :::note TL;DR
- Envio HyperIndex is the fastest blockchain indexer in independent benchmarks: 8 seconds on the Sentio Uniswap V2 Factory workload (May 2025), 142x faster than The Graph and 15x faster than the nearest competitor.
- It is the only indexer in this comparison with true wildcard indexing, multichain from a single indexer, TypeScript handlers, and a proprietary data engine (HyperSync, up to 2000x faster than standard RPC).
- If you need non-EVM chains, use SubQuery or Subsquid. If you need access to public subgraphs, use The Graph.
- Every claim in this article is sourced. Raw benchmark data is open and reproducible: [https://github.com/enviodev/open-indexer-benchmark](https://github.com/enviodev/open-indexer-benchmark)
:::
Choosing a blockchain indexer should be straightforward, but most comparisons rely on self-reported metrics or product descriptions rather than independently benchmarked data and publicly verifiable sources.
This article takes a different approach. Every claim is backed by public documentation or third-party benchmarks, with clear notes where only self-reported data exists.
We cover seven blockchain indexers: Envio, [The Graph](https://thegraph.com) (Subgraphs), [Goldsky](https://goldsky.com), [SubQuery](https://subquery.network), [Subsquid](https://www.sqd.ai) (SQD), [Ormi](https://ormilabs.com) and [Ponder](https://ponder.sh).
If you would like to review the raw benchmark data yourself, it is fully open:
[https://github.com/enviodev/open-indexer-benchmark](https://github.com/enviodev/open-indexer-benchmark)
An open, honest, and objective benchmark for blockchain indexers across EVM, Solana, and more. It compares historical backfill speed, latency, data storage, developer experience, and anything else that matters.
We welcome anyone to contribute, run it, test it, and explore the results. We encourage you to share what you find.
This is a benchmark-backed comparison of custom indexing frameworks, the category of tools developers use to define schemas, write handlers, and expose queryable APIs over onchain data. Custom indexers are distinct from RPC providers like Alchemy, QuickNode, and Infura, which serve raw blockchain data but do not index it. They are also distinct from pre-indexed data APIs like Dune Analytics and Covalent, which expose read-only datasets that cannot be customised. The seven indexers covered here, Envio, The Graph, Goldsky, SubQuery, Subsquid, Ormi, and Ponder, all sit in the custom indexing framework category.
## Quick verdict: which indexer is right for you
| Indexer | Best For |
| --- | --- |
| Envio | The fastest independently benchmarked EVM indexer. True wildcard indexing, multichain in a single indexer, TypeScript throughout. Fully managed or self-hosted. |
| The Graph | Ecosystem access, existing public subgraphs, decentralised network |
| Goldsky | Managed subgraphs plus real-time data streaming to your own database |
| SubQuery | Non-EVM chains, broadest network coverage |
| Subsquid (SQD) | Fast historical backfills, non-EVM |
| Ormi | Fully managed, Graph-compatible |
| Ponder | Self-hosted TypeScript stack, full control |
## How we evaluated
Feature lists rarely tell the full story. We evaluated each indexer on six criteria that matter in production:
* **Indexing speed**: How fast can it sync historical data and stay at the chain head? We used the open benchmark results from Sentio (April 2025) as our primary reference, cross-checked against each indexer's own documentation.
* **Feature completeness**: Does it support event handlers, block handlers, wildcard indexing, and multichain from a single indexer? These are not nice-to-haves once you are building at scale.
* **Developer experience**: What language do you write handlers in? TypeScript is the standard. AssemblyScript adds friction.
* **Chain support**: EVM-only vs multi-ecosystem matters depending on what you are building.
* **Operational model**: Fully managed vs self-hosted vs decentralised. Each has real trade-offs.
* **AI compatibility**: Does the indexer have first-class support for AI-assisted development workflows? This includes Claude Code markdown, Claude skills, and tooling that integrates naturally into AI-native development environments.
## The rankings
### #1 Envio: Fastest EVM indexer with one of the most complete feature sets
**Best for:** Teams building on EVM chains who need the fastest possible indexing with minimal infrastructure overhead.
Envio is the only indexer in this list powered by a proprietary high-performance data engine. [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) delivers up to 2000x faster data access than traditional RPC. Two independent benchmarks run by Sentio confirm this: in the LBTC benchmark (April 2025), HyperIndex completed in 3 minutes versus 3 hours 9 minutes for The Graph. In the Uniswap V2 Factory benchmark (May 2025), HyperIndex completed in 8 seconds, 15x faster than the nearest competitor (Subsquid), 142x faster than The Graph, and 157x faster than Ponder.
HyperSync's speed also makes HyperIndex the fastest data source for onchain AI agents, where query latency and data freshness directly impact decision quality.
#### Key strengths:
* Powered by HyperSync, up to 2000x faster than RPC
* Independently benchmarked as fastest in class: 15x faster than nearest competitor, 157x faster than Ponder, 142x faster than The Graph (Sentio, May 2025, Uniswap V2 Factory benchmark)
* Wildcard indexing (only indexer in this list with full support)
* Single indexer across multiple chains with unordered multichain mode
* Write handlers in TypeScript or ReScript (no AssemblyScript required)
* Full block handler support
* Fully managed hosted service available, no infrastructure management required
* White glove migration support for teams moving from any stack
#### Honest caveats:
HyperSync native support covers
depth** setting and a chosen behaviour such as **replay** or `log`
* Graph-compatible subgraphs for instant GraphQL APIs
* Compose product for event-triggered onchain and offchain workflows
#### Honest caveats:
Goldsky does not support traditional block handlers in the subgraph sense. Their docs do not cover this as a feature. For block-level data access, Goldsky provides pre-indexed Blocks Subgraphs. Block-triggered processing via Compose requires additional setup. Subgraph handlers are written in AssemblyScript (Graph-compatible), not TypeScript. Wildcard indexing is not documented as a feature.
### #4 SubQuery: Best for non-EVM chain coverage
**Best for:** Teams building across EVM and non-EVM ecosystems, including Polkadot, Cosmos, Bitcoin, and more.
SubQuery stands out for its chain coverage. With support for [300+ chains](https://subquery.network/networks) across EVM and non-EVM ecosystems,it is one of the most chain-inclusive indexers in this list. If your product lives on Polkadot or Cosmos and you also need EVM support, SubQuery is the most natural fit for now.
#### Key strengths:
* 300+ chains, broadest coverage including non-EVM
* Single project can index data across multiple chains
* TypeScript handlers
* Block handlers supported
* Decentralised hosted service via SubQuery Network
#### Honest caveats:
Data ingestion runs on standard RPC speed. Block handlers are noted in SubQuery's own documentation to slow indexing as they fire on every block.
### #5 Subsquid (SQD): Best option with fast historical backfills
**Best for:** Teams who want fast historical data access, and non-EVM chain support.
Subsquid's decentralised data lake processes historical blockchain data at tens of thousands of blocks per second. SQD describes this approach as up to 1000x faster than traditional methods like subgraphs, based on their own published benchmarks ([source](https://blog.sqd.dev/fastest-web3-indexer-explained/)).
#### Key strengths:
* Decentralised data lake, significantly faster than RPC for historical data (SQD’s own claim: up to 1000x faster than traditional methods like subgraphs ([source](https://blog.sqd.dev/fastest-web3-indexer-explained/)))
* 100+ chains including EVM and non-EVM
* TypeScript handlers
* Block handlers supported
* Factory contract wildcard patterns supported
#### Honest caveats:
The wildcard support is scoped to factory contract patterns and is not the same as Envio's fully address-free wildcard indexing. Live chain-head performance is not independently benchmarked against the other indexers in this list.
### #6 Ormi (0xGraph): Best fully managed option for Graph-compatible subgraphs
**Best for:** Teams already using The Graph's subgraph standard who want a managed, low-latency alternative without rebuilding their indexing logic.
Ormi's main pitch is a managed, high-performance layer on top of the subgraph standard. If you have existing subgraphs and want to migrate to a lower-latency managed service without rewriting your handlers, Ormi is a credible path. They also offer GraphQL, REST, and SQL query interfaces in a single platform, which is a genuine differentiator.
#### Key strengths:
* Fully managed service
* GraphQL, REST, and SQL query interfaces
* The Graph subgraph standard compatible
* pnpx envio init**
## Frequently asked questions
### What does a blockchain indexer do that an RPC node can't?
A blockchain indexer continuously listens to onchain events (transactions, logs, state changes, blocks) and writes them into a structured, queryable database, exposed through a fast API like GraphQL. RPC nodes return raw data per request but cannot aggregate across events, filter efficiently, or serve historical queries at production speed. For dApps, DeFi protocols, NFT platforms, and analytics tools, an indexer replaces direct RPC calls almost entirely.
### What is the fastest blockchain indexer in 2026?
Based on two independent benchmarks run by Sentio, Envio HyperIndex is the fastest blockchain indexer in independent benchmarks. In the Uniswap V2 Factory benchmark (May 2025), HyperIndex completed in 8 seconds, 15x faster than the nearest competitor (Subsquid), 142x faster than The Graph, and 157x faster than Ponder. In a separate LBTC workload (April 2025), HyperIndex completed in 3 minutes versus 3 hours 9 minutes for The Graph. All benchmark data is publicly available. HyperIndex handles both real-time event streaming at chain head and historical backfill in the same indexer, with automatic transition between the two modes.
### Which blockchain indexer supports the most chains?
SubQuery supports the most chains at 300+, including both EVM and non-EVM networks such as Polkadot, Cosmos, and Bitcoin. Subsquid supports 100+ chains. Goldsky supports 150+ chains. Envio supports  March saw continued progress across HyperIndex, tooling, and the wider Envio ecosystem. We shipped multiple alpha releases focused on improving scale, flexibility, testing, and observability, alongside new workflows that make it easier to go from idea to production-ready indexers.
This month we also rebranded our Hosted Service to Envio Cloud. Alongside this, we introduced updates across subgraph hosting, agentic indexing workflows, and new ways to explore and interact with prediction market data. Across the ecosystem, we saw strong developer contributions, new projects being built with Envio, and continued momentum leading into upcoming events.
Let's dive in!
## Alpha Releases: Alpha.15 -> Alpha.19
Loads of exciting progress landed across the latest alpha releases this month. This stretch focused on improving scale, flexibility, testing, and the overall developer experience across HyperIndex, with a mix of new features, internal improvements, and important updates to observability.
### Alpha.15
#### New getWhere operators:
_gte, _lte, _in
Three new filter operators have been added for getWhere queries, following Hasura-style conventions:
```typescript
context.Entity.getWhere({ amount: { _gte: 100n } })
context.Entity.getWhere({ amount: { _lte: 500n } })
context.Entity.getWhere({ status: { _in: ["active", "pending"] } })
```
#### Support double handler registration
Allows double handler registration for the same event with similar filters:
```typescript
import { ERC20 } from "generated";
ERC20.Transfer.handler(async ({ event, context }) => {
// Your logic here
});
ERC20.Transfer.handler(async ({ event, context }) => {
// And here
});
```
#### Other improvements
We consistently improve HyperIndex to make it easier to contribute to for both humans and AI. Recent work includes:
* Restructuring HyperIndex into a pnpm workspace
* Moving tests from mocha/chai to vitest
* Reworking the CI pipeline to run faster and reuse the production artifact for both testing and publishing
* Developing a highly customisable internal testing framework so AI can create reproduction tests for tricky edge cases
### Alpha.18
#### Support indexers with 2.1B+ events per chain
Scale indexers approaching int32 limits. Now you can build even larger, more performant indexers with HyperIndex.
#### Breaking: Official /metrics endpoint
Existing Prometheus metrics just got a major upgrade.
We cleaned up metric names and measured data, switched time units to seconds instead of milliseconds, and started following Prometheus naming conventions more closely.
We also added metrics for data points previously covered by the `--bench` feature.
Starting with v3.0.0, Prometheus metrics are no longer experimental. The `/metrics` endpoint now follows semver and will be documented.
For more information and to stay up to date with all current and past releases, be sure to check out our release notes below.
See full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Hosted Service is now Envio Cloud
 We've renamed the Hosted Service to Envio Cloud. Same product, same infrastructure, no changes required on your end.
For those new to it, Envio Cloud is a fully managed hosting solution for your indexers, taking care of all infrastructure, scaling, and monitoring so you can focus on building. Plans range from free dev environments through to enterprise-grade dedicated hosting, with static production endpoints, built-in alerts, and production-ready infrastructure across all tiers.
Learn more in our [docs](https://docs.envio.dev/docs/HyperIndex/hosted-service)
## Agentic blockchain indexing with Envio
 We explored what it looks like to go from prompt to production-ready indexers using Envio.
This walkthrough shows how to scaffold an indexer for any EVM-compatible chain, push it to GitHub, and deploy it to Envio's Cloud (previously Hosted Service) without manually touching a config file.
As an example, **400,000+ wstETH events were indexed on Monad in ~20 seconds.**
Use the following command to scaffold your indexer:
```bash
pnpx envio init template -t erc20 -l typescript -d ./my-indexer
```
Learn more in our blog and test it yourself here: [https://docs.envio.dev/blog/agentic-blockchain-indexing-envio-hyperindex](https://docs.envio.dev/blog/agentic-blockchain-indexing-envio-hyperindex)
## Host your subgraphs on Envio
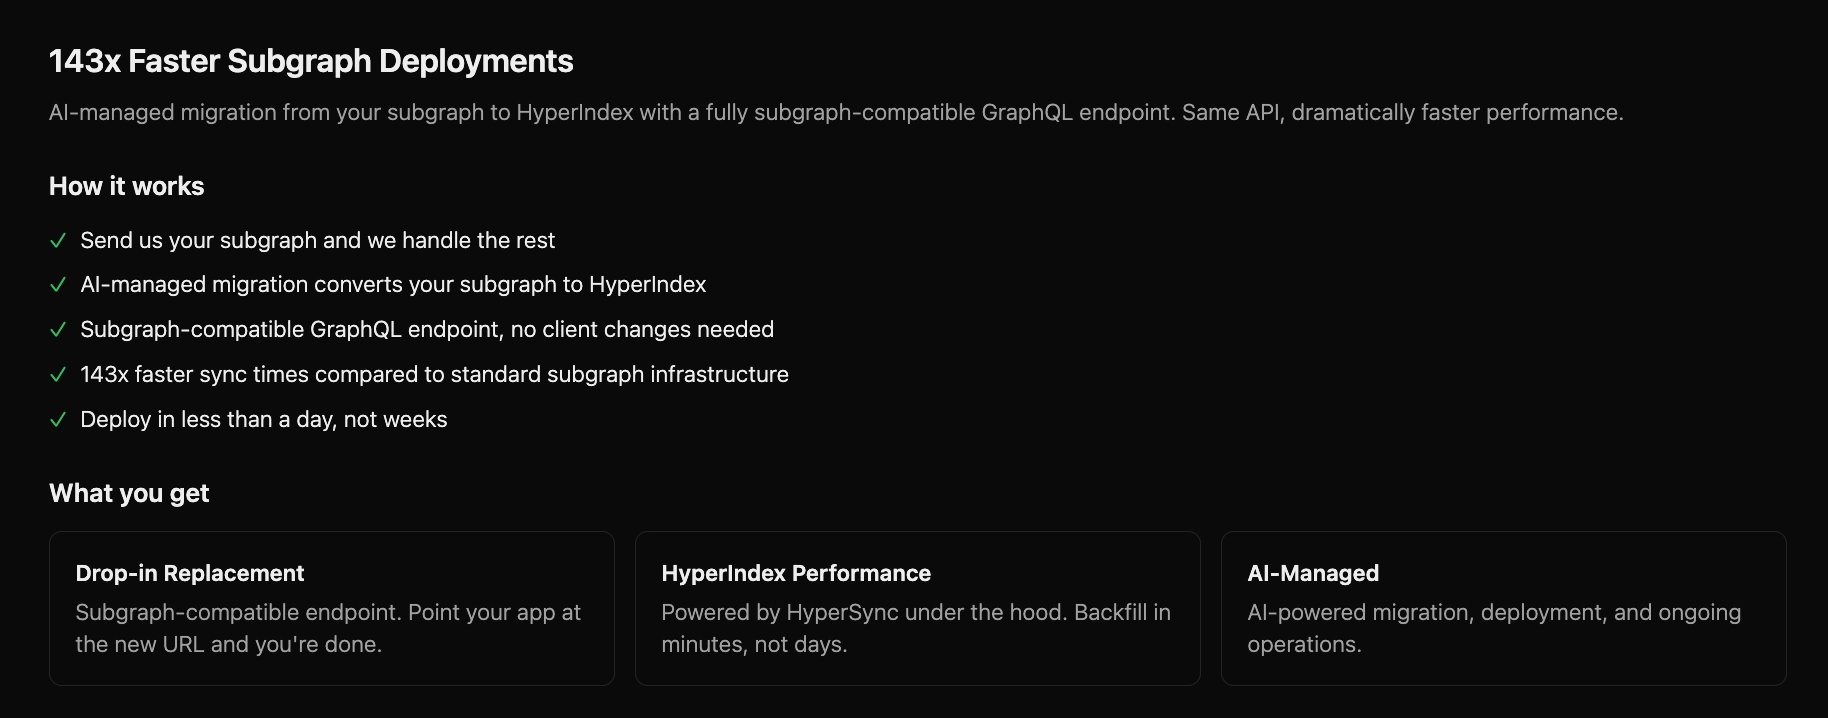 Deploy and host your subgraphs with HyperIndex, with a fully subgraph-compatible GraphQL endpoint and no client changes required.
Migrate your existing subgraphs and keep the same API, with faster sync, quicker backfills, and deployments live in less than a day.
The process is handled end-to-end, converting your subgraph to HyperIndex and getting it up and running without needing to manage infrastructure.
Learn more here: [https://envio.dev/pricing/subgraphs](https://envio.dev/pricing/subgraphs)
Get started on Discord - open a support ticket: [https://discord.gg/envio](https://discord.gg/envio)
## Heatbook: Polymarket Orderbooks as Heatmaps
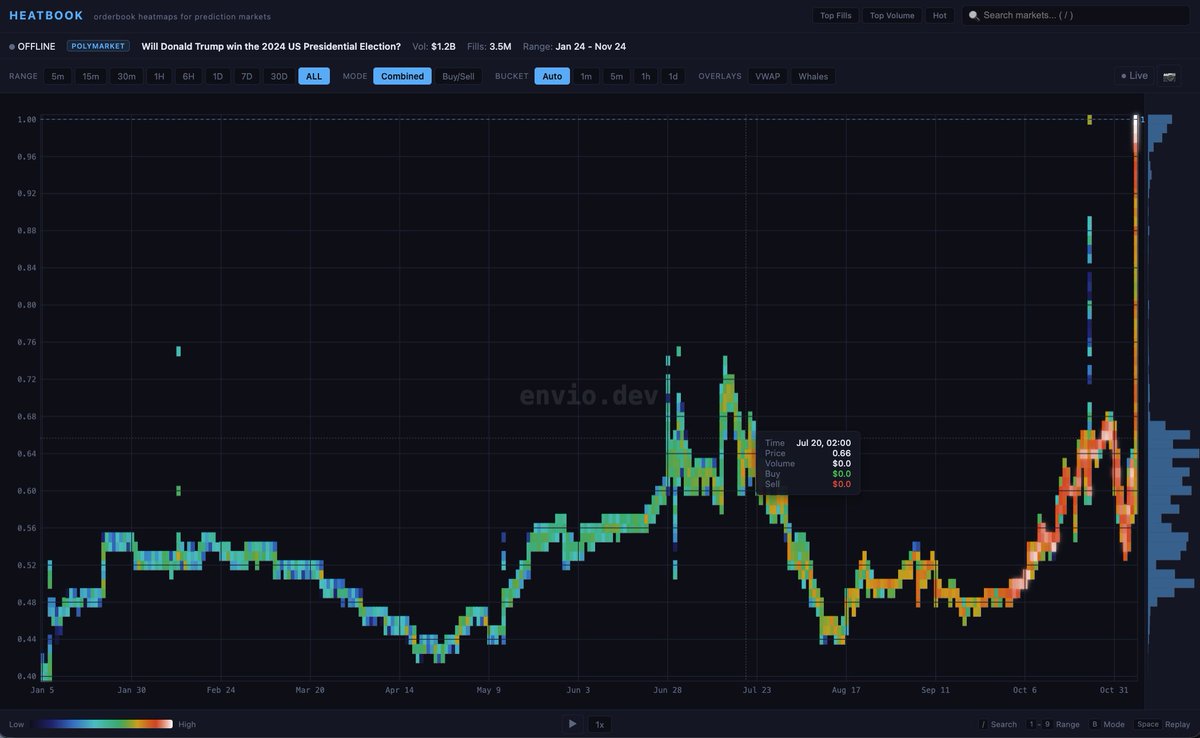 An interface for visualising Polymarket orderbooks using historical heatmaps. Orderbook heatmaps for prediction markets, with 115M+ fills visualised. View any market and explore activity over time.
Supports [Polymarket](https://polymarket.com/predictions/all), [Limitless](https://limitless.exchange/markets), and more soon.
More here: [https://heatbook.xyz/](https://heatbook.xyz/)
See original post: [https://x.com/jonjonclark/status/2031016707309949042?s=20](https://x.com/jonjonclark/status/2031016707309949042?s=20)
## EthCC[9]: Sapphire Sponsor
 Envio is a Sapphire sponsor of [EthCC[9]](https://ethcc.io), taking place at Palais des Festivals in Cannes from March 30 to April 2, 2026.
EthCC is an annual Ethereum community conference bringing together developers, researchers, and teams from across the ecosystem.
The team will be there across the week. Catch our [talk](https://ethcc.io/speakers/jonjon-clark) on the Monroe stage and swing by our booth - let's chat about your data needs.
P.S. be sure to get your hands on one of our snazzy Envio caps and stickers.
## Developer contributions: Uniswap CCA indexer
 Check out this Uniswap CCA indexer built with HyperIndex to index continuous clearing auction contracts across Ethereum, Base, Arbitrum, and Unichain. It tracks auctions, bids, ticks, steps, and checkpoints, using HyperSync for logs and selective RPC reads for derived onchain state.
Shoutout to [@0xdivergence](https://x.com/0xdivergence) for sharing this and building with Envio.
Check it out on GitHub: [https://github.com/dzmbs/uniswap-cca-indexer](https://github.com/dzmbs/uniswap-cca-indexer)
## Open Indexer Benchmark
We believe tech should speak for itself.
That's why we started working on and maintaining the Open Indexer Benchmark (originally forked from Sentio).
An honest, objective benchmark for blockchain indexers.
We're reopening it to benchmark new use cases and warmly welcome all contributions:
[https://github.com/enviodev/open-indexer-benchmark](https://github.com/enviodev/open-indexer-benchmark)
## Wonderland CTF
 Envio is a proud sponsor of the Wonderland CTF. The event takes place on April 1, 2026, in person at EthCC[9] in Cannes.
Wonderland CTF is a capture-the-flag event featuring Solidity and Aztec Noir challenges, with tracks ranging from beginner to advanced and teams of 1 to 5 members.
Create your team and learn more here: [https://ctf.wonderland.xyz](https://ctf.wonderland.xyz)
## Polymarket Whale Tracker TUI
 We put together a simple whale tracker using HyperSync to track Polymarket whale activity in real time. It follows large traders on Polymarket and surfaces what they're doing as it happens, making it easier to monitor higher-conviction activity without sifting through smaller trades.
Clean, fast, and easy to plug into your workflows.
More here: [https://github.com/enviodev/poly-whale-tracker](https://github.com/enviodev/poly-whale-tracker)
Run:
```bash
npx poly-whales
```
For a step-by-step guide on how to build your own, see: [https://docs.envio.dev/blog/track-polymarket-trades-hypersync](https://docs.envio.dev/blog/track-polymarket-trades-hypersync)
## Best blockchain indexers in 2026
 We put together a benchmark-driven comparison of blockchain indexers, looking at how different solutions perform in practice. The guide focuses on how indexers handle real workloads, comparing performance, sync speeds, and overall reliability across different approaches.
It's a practical breakdown of the trade-offs between tools and what to consider when choosing an indexer for your use case.
Learn and compare in our latest blog: [https://docs.envio.dev/blog/best-blockchain-indexers-2026](https://docs.envio.dev/blog/best-blockchain-indexers-2026)
## Current & Upcoming Events & Hackathons
* [EthCC - Cannes](https://ethcc.io/): March 30th -> April 2nd
* [EthConf - New York](https://ethconf.com/): June 8th -> 10th
## Featured Developer: Praveen Matheesha
 This month's featured developer is Praveen Matheesha, a developer focused on building advanced onchain analytics infrastructure. He is currently working on [@paralensdotai](https://x.com/paralensdotai), a next-generation blockchain analytics engine designed to extract economic behavior and strategy-level insights from raw blockchain transactions. His focus is on turning complex onchain data into meaningful signals for traders, researchers, and analysts, with a particular interest in transaction-level intelligence, MEV analysis, and understanding the economic intent behind smart contract interactions.
**What Praveen had to say about Envio:**
> ***"Before discovering Envio, I was building my own EVM indexer from scratch in Rust. I implemented support for chain reorg handling, historical backfilling, batched RPC ingestion, and WebSocket streams for real-time updates. While it worked, a significant amount of time went into building and maintaining the infrastructure layer itself. When I discovered Envio and HyperSync, it immediately stood out as a much more efficient approach. It solves many of the challenges around reliable, high-performance blockchain data access that developers often end up rebuilding from scratch. If I had found it earlier, I likely could have saved weeks of work and focused more on the actual analytics and business logic rather than the ingestion pipeline. I also wrote a detailed article about building a production-ready EVM indexer in Rust, where I mentioned Envio as a great option for developers who want to avoid spending weeks building indexing infrastructure themselves. Overall, HyperSync makes it significantly easier to work with large volumes of onchain data and allows developers to focus on building insights and applications instead of reinventing core data infrastructure."***
Well done, Praveen. Be sure to follow the team on [X](https://x.com/hpmszk) and check out their [GitHub](https://github.com/matheeshame) to stay up to date with their latest developments.
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/240pHTCbwvf6kBMdfWGmw9?si=bb40d616e82a49f3)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you're working on a Web3 project and want a smoother development process, Envio's got your back(end). Check out our docs, join the community, and let's talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Track Polymarket Trades Using Envio's HyperSync
> Track Polymarket trades in real time using Envio HyperSync. Stream OrderFilled events on Polygon and decode trade data using TypeScript and Bun.
 :::note TL;DR
- Build a real-time Polymarket trade tracker using Envio HyperSync and TypeScript with Bun.
- Stream block heights from Polygon and query OrderFilled events from the Polymarket Exchange contracts on each new block.
- Decode events with Viem, identify buy vs sell trades by checking `makerAssetId`, and calculate price per share.
- Extend with filters for trade amount or specific wallet addresses to track high-conviction traders.
:::
Since the rise of prediction markets like [Polymarket](https://polymarket.com) and [Kalshi](https://kalshi.com), many people have been tracking activity on them to get a sense of where the money is going. If we try to track every trade on these prediction markets, you will see many people betting like $10 here, $15 there. If you want a stronger signal, then you should track trades with higher amounts, since those traders have more conviction in the outcome they are betting on.
In this article, we are going to build a tool with HyperSync where you can track Polymarket trades above a certain amount. We also have one feature where you can track trades from certain addresses. If you know some addresses from good traders, you can follow them too.
## Prerequisites
We are going to use Bun for this article, so make sure you have it installed. If not, please check the [Bun documentation](https://bun.com/docs/installation) for installation instructions. If you want to use some other runtime that supports TypeScript, you can do that too.
You will also need an Envio API token to access HyperSync. If you don’t have it already, go to [https://envio.dev/app/api-tokens](https://envio.dev/app/api-tokens) and you can find your token there.
Here are step-by-step instructions for creating new API tokens: [https://docs.envio.dev/docs/HyperSync/api-tokens#generating-api-tokens](https://docs.envio.dev/docs/HyperSync/api-tokens#generating-api-tokens)
## What is HyperSync
[HyperSync](https://docs.envio.dev/docs/HyperSync/overview) is Envio's high-performance blockchain data retrieval layer, built as an alternative to traditional JSON-RPC endpoints. It gives developers direct access to onchain data up to 2000x faster than standard RPC methods.
For this article, we are using HyperSync to stream real-time block heights and query Polymarket trade events on Polygon as they happen. Client libraries are available for Python, Rust, Node.js, and Go. HyperSync supports
 :::note TL;DR
- Polymarket's 8 independent subgraphs on The Graph were replaced with a single Envio HyperIndex indexer written in TypeScript.
- The unified indexer synced over 4,000,000,000 events from block 3,764,531 on Polygon Mainnet in 6 days.
- Handler merging processes each shared contract event once, updating all relevant domains simultaneously rather than redundantly across multiple subgraphs.
- The full indexer is open source at [github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer).
:::
[Polymarket](https://polymarket.com) is one of the most data-intensive protocols in Web3. Every trade, position, fee, liquidity event, and oracle resolution across its entire prediction market ecosystem lives onchain on Polygon. Querying any of it meaningfully requires a serious blockchain indexer.
For years, Polymarket's data infrastructure relied on 8 independent subgraphs on [The Graph](https://thegraph.com), each written in AssemblyScript, each tracking a separate domain, all running since 2021. This post documents how all 8 were replaced with a single Envio HyperIndex indexer, syncing over 4,000,000,000 events in 6 days on Polygon Mainnet.
The indexer is fully open source: [github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer)
## Envio HyperIndex: The Fastest Blockchain Indexer Available
Envio is a real-time multichain blockchain indexing framework for EVM chains. Developers write event handlers in TypeScript and deploy a single indexer that covers multiple contracts, chains, and domains simultaneously.
HyperIndex is independently benchmarked as the fastest blockchain indexer available. In the Uniswap V2 Factory [benchmark run by Sentio](https://github.com/enviodev/open-indexer-benchmark) in May 2025, HyperIndex completed in 8 seconds, 142x faster than The Graph and 15x faster than the nearest competitor. In the LBTC benchmark (April 2025), HyperIndex completed in 3 minutes versus 3 hours 9 minutes for The Graph.
This performance comes from [HyperSync](https://docs.envio.dev/docs/HyperSync/overview), Envio's proprietary data engine. Instead of querying RPC endpoints block by block, HyperSync fetches filtered event data in bulk directly from a purpose-built data lake, delivering up to 2,000x faster data access than standard RPC. Polygon is one of
 Live deployment: [https://envio.dev/app/moose-code/polymarket-indexer/7cad3ad](https://envio.dev/app/moose-code/polymarket-indexer/7cad3ad)
## Why Teams Migrate to HyperIndex from The Graph
Polymarket's setup before this migration is a pattern that shows up across the ecosystem: multiple subgraphs, shared contracts, AssemblyScript handlers, fragmented data. Here is what changes when teams move to HyperIndex:
**Speed.** HyperIndex is 142x faster than The Graph on independent benchmarks. For protocols with years of history like Polymarket, that directly translates to days versus months on historical sync.
**TypeScript, not AssemblyScript.** Handlers are standard TypeScript with generated types from both the schema and ABIs. Any npm package works. No WebAssembly compilation. No AssemblyScript-specific constraints.
**One codebase.** All domains, all contracts, all chains in a single indexer. One deployment to ship, one codebase to maintain, one endpoint to query.
**Single source of truth.** Cross-domain queries happen at the database level, not at the application layer. No joining across APIs at runtime.
**Dynamic contract registration.** Factory contracts that create new instances onchain register them automatically, without requiring a redeployment.
Envio offers white-glove migration support for teams moving from The Graph or any other indexer. The Polymarket indexer is an open-source reference for what a large-scale migration looks like end to end.
## Frequently Asked Questions
### What is Polymarket?
Polymarket is the world's largest decentralized prediction market, built on Polygon. Users trade outcome shares on real-world events using USDC. All positions, trades, and settlements are handled entirely onchain via smart contracts with no central custodian.
### How many subgraphs did Polymarket use before migrating to HyperIndex?
Polymarket previously ran 8 independent subgraphs on The Graph, each written in AssemblyScript: fee-module, sports-oracle, wallet, orderbook, open-interest, activity, pnl, and fpmm. All 8 were consolidated into a single Envio HyperIndex indexer written in TypeScript.
### How did Polymarket migrate 8 subgraphs to HyperIndex?
The 8 AssemblyScript subgraphs were consolidated into a single TypeScript HyperIndex indexer on Polygon. Because HyperIndex handlers are TypeScript, and AssemblyScript is a subset of TypeScript, most handler logic carried across directly. Envio also provides a [migration guide](https://docs.envio.dev/docs/HyperIndex/migration-guide), a CLI validation tool to compare output between both endpoints, and white-glove migration support.
### What is handler merging in the Polymarket indexer?
Handler merging lets one handler process a shared contract event once and update all relevant entities simultaneously. A `ConditionalTokens.PositionSplit` event previously triggered redundant processing across the open-interest, activity, and pnl subgraphs. In the unified HyperIndex indexer, a single handler fires once and updates open interest, records the split activity, and adjusts user PnL positions in one pass.
### Which Polymarket contracts does the open-source indexer cover?
The indexer covers Exchange and NegRiskExchange, ConditionalTokens, NegRiskAdapter, FPMMFactory, FixedProductMarketMaker (dynamically registered), FeeModule and NegRiskFeeModule, UmaSportsOracle, plus USDC, RelayHub, and SafeProxyFactory. The full handler structure and event list is documented in the post.
### Does HyperIndex support dynamic contract registration?
Yes. The Polymarket indexer uses FPMMFactory to register new Fixed Product Market Maker instances automatically as they are created onchain, without requiring a redeployment.
### How long does it take to index Polymarket's full history on Polygon?
Using Envio HyperIndex with HyperSync, the full historical sync of Polymarket's onchain data on Polygon, over 4,000,000,000 events from block 3,764,531, completed in 6 days.
### Is the Polymarket HyperIndex indexer open source?
Yes. The full indexer is available at [github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer), with 29 tests covering all handler phases including a HyperSync integration test. Run it locally with `pnpm dev`.
### Where can I see the live Polymarket indexer deployment?
The live indexer is deployed at [envio.dev/app/moose-code/polymarket-indexer/7cad3ad](https://envio.dev/app/moose-code/polymarket-indexer/7cad3ad). Polygon Mainnet is one of
 :::note TL;DR
- Envio's documentation is now directly accessible to your AI coding assistant via MCP.
- Connect Claude Code, Cursor, Copilot, or any MCP-compatible client in one step.
- Your assistant searches and fetches live Envio docs on demand, no copy-pasting required.
- Envio Docs MCP quicklink: [https://docs.envio.dev/docs/HyperIndex/mcp-server](https://docs.envio.dev/docs/HyperIndex/mcp-server)
:::
Envio now has a hosted MCP server for its documentation. Point your AI coding assistant at it and it can search and read Envio docs on demand. No more copy-pasting links into chat and no more watching your model confidently invent a config field that does not exist.
Whether you are building an indexer, querying onchain data with HyperSync, or just exploring what Envio can do, the MCP server gives your agent a direct line to the real documentation while it works.
## What is an MCP server?
Model Context Protocol (MCP) is an open standard for connecting AI assistants to external tools and data sources. An MCP server exposes a set of capabilities, like searching a knowledge base, fetching a document, or calling an API, that any MCP-compatible client can call on demand.
In practice, this means you can give your AI assistant a stable, structured way to reach into a real system, instead of relying on whatever happened to be in its training data or fumbling around the web trying to find something relevant.
## What is the Envio Docs MCP Server?
The Envio Docs MCP server is a hosted MCP server that gives AI coding assistants direct access to Envio's documentation. It exposes two tools:
| Tool | Description |
|------|-------------|
| `docs_search` | Full-text search across all Envio documentation. Returns matching pages with titles, URLs, and content snippets. |
| `docs_fetch` | Retrieves the full content of a documentation page as markdown. |
The server is hosted at:
[https://docs.envio.dev/mcp](https://docs.envio.dev/mcp)
## Why this matters for Envio users
Without an MCP server, an AI assistant trying to use Envio docs is mostly working blind. It either falls back on whatever it remembers from training, or hops between links and fetches raw HTML pages to parse out the parts it needs. That is slow, noisy, and easy to get wrong: the model ends up sifting through navigation, sidebars, and styling just to find a single config option.
The Envio Docs MCP server replaces that with a structured way for your assistant to ask the docs a question directly. Instead of scraping pages, it can search across all of Envio's documentation and pull back exactly the content it needs.
That means:
- **Always up to date.** The MCP server reads from the same docs site you read. When the docs change, your assistant sees the change immediately.
- **Grounded in source docs.** Your agent looks up the exact answer in the documentation instead of guessing.
- **Less copy-paste.** No more shuttling doc snippets back and forth between your browser and your editor.
- **Useful across the whole stack.** Whether you are building an indexer, pulling onchain data with HyperSync, or exploring Envio Cloud, your assistant has the right context for the job.
## How to connect it
### Claude Code
```bash
claude mcp add --transport http envio-docs https://docs.envio.dev/mcp
```
### Cursor / VS Code
Add the following to your MCP configuration (`.cursor/mcp.json` or your VS Code MCP settings):
```json
{
"mcpServers": {
"envio-docs": {
"url": "https://docs.envio.dev/mcp"
}
}
}
```
### Other MCP clients
Point any MCP-compatible client to `https://docs.envio.dev/mcp` using the Streamable HTTP transport.
For full, always-current setup instructions, see the Envio Docs MCP Server guide.
Once connected, your assistant can search the docs and pull back full pages whenever it needs context, with no extra prompting from you.
## Frequently Asked Questions
### What Is an MCP Server?
An MCP server is a server that implements the Model Context Protocol, an open standard for connecting AI assistants to external tools and data sources. It lets AI coding assistants like Claude Code and Cursor access real, structured information on demand rather than relying on training data.
### What Is the Envio Docs MCP Server?
The Envio Docs MCP server is a hosted server at [https://docs.envio.dev/mcp](https://docs.envio.dev/mcp) that gives AI coding assistants direct access to Envio's documentation. It supports two operations: searching across all docs and fetching the full content of any documentation page.
### Which AI Assistants Does the Envio MCP Server Support?
The Envio Docs MCP server works with any MCP-compatible client. Setup instructions are available for Claude Code and Cursor / VS Code. Any other client that supports the Streamable HTTP transport can connect using the endpoint URL directly.
### Is the Envio MCP Server Always Up to Date?
Yes. The MCP server reads directly from the live Envio docs site. When documentation is updated, your assistant has access to the latest version immediately.
### How Do I Get Started with Envio HyperIndex?
Run `pnpx envio init` to scaffold your first indexer in minutes. Write event handlers in TypeScript, configure your chains and contracts in `config.yaml`, and deploy to Envio Cloud for managed hosting. See the [HyperIndex overview](https://docs.envio.dev/docs/HyperIndex/overview) and [getting started guide](https://docs.envio.dev/docs/HyperIndex/getting-started) for full documentation.
## Build With Envio
Envio HyperIndex is independently benchmarked as the fastest EVM blockchain indexer available. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, or come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Using ClickHouse Storage in HyperIndex V3
> HyperIndex V3 Alpha adds experimental ClickHouse Storage. Postgres stays primary, entity data mirrors to ClickHouse for analytics workloads on billions of onchain events.
:::info TL;DR
- HyperIndex V3 Alpha adds experimental **ClickHouse Storage**, Postgres stays as the primary database, and your entity data is replicated to ClickHouse for analytics workloads.
- ClickHouse is a columnar database built for heavy analytical queries on datasets in the 100s of GBs or TBs, a natural fit for onchain data, which can easily reach billions of events for a single token.
- You can enable it on Envio Cloud by setting four environment variables: `ENVIO_CLICKHOUSE_HOST`, `ENVIO_CLICKHOUSE_DATABASE`, `ENVIO_CLICKHOUSE_USERNAME`, and `ENVIO_CLICKHOUSE_PASSWORD`.
- Currently supported on the **Dedicated Plan** only, and you need to bring your own ClickHouse instance. Managed ClickHouse is coming to Envio Cloud, [**fill out this form**](https://forms.gle/P19S7KXYfdHQM8J69) if you want to be one of the first users.
:::
## Why We Built ClickHouse Storage
Since day one, HyperIndex has used Postgres as its primary database. Postgres is battle-tested, runs well for small and large indexers alike, and gives you GraphQL out of the box through Hasura. It is a solid default for almost every indexer.
But over the last few months, enough teams have asked the same question that we knew we had to do something about it: **can we replicate the data to ClickHouse?**
Most teams asking were building on DEXes, or DeFi protocols where data volumes are large enough that even a well-tuned Postgres query to do analytics starts to slow down. That is exactly the workload ClickHouse is built for. So in HyperIndex V3, we shipped experimental ClickHouse Storage support.
V3 is in alpha at the time of writing, and ClickHouse Storage is flagged as experimental. Both will be marked stable once V3 reaches its stable launch, at which point you can use ClickHouse Storage in production without the experimental label. If you want to try ClickHouse on Envio Cloud today, [**fill out this form**](https://forms.gle/P19S7KXYfdHQM8J69), it is currently supported only on the Dedicated Plan.
## What is ClickHouse?
ClickHouse is a **columnar database** designed for analytical workloads. Most transactional databases, including Postgres, store data row by row, which is fast when you are reading or writing a single record by its primary key but slow when you are scanning millions of rows to compute an aggregate. A columnar database flips that around, values for each column are stored together on disk, so aggregations across billions of rows finish in seconds instead of minutes.
This matters a lot for blockchain data. For example, just USDC on Ethereum has hundreds of millions of **`Transfer`** events. Add in every other chain USDC is deployed on, and you cross into the billions. Now imagine you want to group those transfers by sender, bucket them by hour, and compute the sum per chain. A row store will struggle no matter how many indexes you throw at it. A columnar engine was built for exactly that kind of query.
Onchain data has three properties that make it a near-perfect match for ClickHouse:
- **Append-heavy** - once an event is emitted, it rarely changes.
- **Highly structured** - every event of the same type has the same shape.
- **Queried in aggregate** - most analytics questions are counts, sums, averages, or time-bucketed views, not single-row lookups.
If your indexer is powering a dashboard, a leaderboard, historical charts, or any kind of reporting layer on top of a large dataset, ClickHouse is the right tool for that read path. Postgres is still great for your day-to-day indexer writes and GraphQL reads, ClickHouse Storage just gives you a second surface that is optimised for the analytical side.
## How ClickHouse Storage Works in HyperIndex
HyperIndex runs two storage layers in parallel. Postgres remains the primary indexed state that your app queries through GraphQL. ClickHouse is a purpose-built analytics mirror, not a fallback. On every batch, events parsed by your handlers are flushed to both: Postgres gets the current state, ClickHouse gets the history.
ClickHouse Storage writes two things:
- **Entity history tables** - every change to every entity as an **`INSERT`**, tagged with a **`SET`** or **`DELETE`** action and a checkpoint ID linking it to a specific block. ClickHouse never receives an **`UPDATE`**, it is optimised for inserts, not mutation.
- **Checkpoints table** - one row per processed block with block number, block hash, chain ID, and event count.
"Current state" is served by **views** that sit on top of the history table and select the latest **SET** row per entity ID. You get a full audit trail for free, and you can query state at any past block just by filtering on checkpoint ID.
Reorgs are handled by a single **`DELETE`** per table that removes all rows above the reorg checkpoint, the append only model makes rollbacks trivial, with no partial state to unwind. Schemas are auto-created on startup from your **`schema.graphql`**, with type mappings handled for you (`BigInt` → `Decimal`, `Date` → `DateTime64`, `enums` → `Enum8`/`Enum16`, and so on). No DDL to write.
Both backends are **restart- and reorg-resistant**, the checkpoints table lets the indexer resume cleanly after a crash, and Prometheus metrics carry a **`storage-name`** label so you can monitor Postgres and ClickHouse write paths separately.
:::info[Note]
During historical backfill, ClickHouse Storage does not store every intermediate entity change. If an entity is modified multiple times within a single batch, only the final state of that batch is written to ClickHouse. Once the indexer reaches the head and is processing live, every change is captured.
:::
:::warning[Warning]
Do not run multiple indexers writing to the same ClickHouse database at the same time.
:::
## **How to Enable ClickHouse on Envio Cloud**
To scaffold a new V3 alpha indexer, run:
```bash
pnpx envio init
```
This will set up a fresh project on the latest alpha release. Enable both storage backends in `config.yaml`:
```yaml
storage:
postgres: true
clickhouse: true
```
ClickHouse connection is configured via four environment variables, set them in your `.env` file for local development (`envio dev` will spin up a ClickHouse Docker container alongside), or from the Envio Cloud dashboard for hosted deployments:
| Variable | Description |
| ----- | ----- |
| `ENVIO_CLICKHOUSE_HOST` | The host of your ClickHouse instance. |
| `ENVIO_CLICKHOUSE_DATABASE` | The ClickHouse database to write into. |
| `ENVIO_CLICKHOUSE_USERNAME` | Username for the ClickHouse connection. |
| `ENVIO_CLICKHOUSE_PASSWORD` | Password for the ClickHouse connection. |
Once those are set, HyperIndex will replicate the same entity data it writes to Postgres into your ClickHouse database. Every entity in your `schema.graphql` becomes a ClickHouse table with a matching schema, so you can point your analytics queries, BI tools, or dashboards directly at ClickHouse, no extra ETL pipeline needed.
Postgres and GraphQL keep working exactly as they do today. ClickHouse Storage is additive: you get a second read-optimised surface without giving up the one you already have.
## Who Can Use ClickHouse Storage?
Right now, ClickHouse Storage is available on the **Dedicated Plan**, and you need to bring your own ClickHouse instance. If you are already running ClickHouse (or you are comfortable standing one up), you can plug it into your indexer today using the environment variables above.
We are also working on a managed ClickHouse offering on Envio Cloud so teams won't have to run their own instance. If you want to be one of the first users when that rolls out, [**fill out this form**](https://forms.gle/P19S7KXYfdHQM8J69). Tell us a bit about your indexer and the kind of analytics you are trying to run and we will get you onboarded.
## **Get Started**
ClickHouse Storage is available today on the Dedicated Plan for teams running their own ClickHouse instance. For teams that want managed ClickHouse on Envio Cloud, fill out the waitlist form to be one of the first users when it rolls out.
- Envio docs: [https://docs.envio.dev/](https://docs.envio.dev/)
- HyperIndex V3 migration guide: [https://docs.envio.dev/docs/HyperIndex/migrate-to-v3](https://docs.envio.dev/docs/HyperIndex/migrate-to-v3)
- Managed ClickHouse waitlist: https://forms.gle/P19S7KXYfdHQM8J69
- Discord: [https://discord.gg/envio](https://discord.gg/envio)
- Telegram: [https://t.me/+BeS5ihVUFONjNGFk](https://t.me/+BeS5ihVUFONjNGFk)
- Follow us on X: [https://x.com/envio\_indexer](https://x.com/envio_indexer)
## **Frequently Asked Questions**
### ClickHouse vs Postgres: When Should I Use Which?
Use Postgres for transactional reads, your GraphQL API, single-entity lookups, and anything latency-sensitive that your application serves directly to users. Use ClickHouse for analytical queries: large aggregations, time-bucketed views, leaderboards, historical charts, and BI dashboards. The rule of thumb is that if a query scans millions of rows to compute a result, it belongs on ClickHouse. If a query fetches a specific record by ID, it belongs on Postgres.
### Can I Use BI Tools Like Metabase, Superset, or Grafana With ClickHouse Storage?
Yes. Once ClickHouse Storage is running, your ClickHouse database is a standard ClickHouse instance as far as any external tool is concerned. Any tool with a ClickHouse connector (Metabase, Superset, Grafana, Tableau, Hex, Redash, and most others) can connect directly. Point it at the same host, database, and credentials you configured on Envio Cloud.
### Does ClickHouse Storage Slow Down My Indexer?
ClickHouse Storage writes in the same batches HyperIndex uses for Postgres, so there is some additional write work per batch. In practice, ClickHouse inserts are designed to be fast and writes are batched, so the overhead is small for most workloads. If you are seeing lag, the usual culprit is your ClickHouse instance's write capacity or network latency between the indexer and ClickHouse, not HyperIndex itself.
### How Do I Query Past State in ClickHouse?
Because the history tables store every change with a checkpoint ID tied to a specific block, you can reconstruct state at any historical point by filtering on checkpoint ID. This gives you time-travel queries for free, without needing snapshots or a separate archive. The latest-state views handle the "current state" case automatically, so you only reach for checkpoint filtering when you specifically want a past view.
### Can I Add Custom Tables or Indexes to My ClickHouse Database?
ClickHouse Storage manages its own tables based on your `schema.graphql` and will create them on startup. You can add your own tables, materialised views, or downstream aggregations in the same database alongside the managed tables, as long as you don't modify or collide with them. A common pattern is to build materialised views on top of the history tables to pre-aggregate heavy queries.
### What Happens If My ClickHouse Instance Goes Down?
Postgres and your GraphQL API keep serving as normal. ClickHouse Storage is additive, so a ClickHouse outage does not stop your indexer from processing events or serving queries from Postgres. Once ClickHouse is back, replication resumes from where it left off using the checkpoints table.
### Is There a Cost Difference Between Running With and Without ClickHouse Storage?
On Envio Cloud, ClickHouse Storage itself is available on the Dedicated Plan. The main cost consideration is your ClickHouse instance, you are bringing your own, so storage, compute, and egress costs depend on your provider (ClickHouse Cloud, self-hosted, Altinity, etc.) and the size of your dataset. Entity history tables grow faster than Postgres state tables because every change is stored rather than just the current value.
### Why Did Envio Build This Instead of Just Recommending an ETL Pipeline?
Running a separate ETL pipeline (CDC from Postgres to ClickHouse, a Kafka connector, a custom script) adds another system to maintain, another place for data to drift, and another source of lag. Building ClickHouse Storage into HyperIndex means entity data lands in ClickHouse as part of the same batch that writes to Postgres, with reorg handling and schema management already solved. One indexer, two read surfaces, no extra pipeline.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, plus analytics that keep up with your indexer, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.com/invite/gt7yEUZKeB) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA)
---
# How to Track Native ETH Transfers Using Envio's HyperSync
> Native ETH transfers don't emit event logs, so tracking them over RPC means slow trace calls. This guide shows how to stream native transfers efficiently using HyperSync's trace filtering with the Node.js client in a Bun project.
:::info TL;DR
- Tracking native ETH transfers onchain requires parsing traces rather than event logs, which is slow over standard RPC.
- HyperSync exposes trace filtering directly, letting you stream native transfers by filtering on `call_type=call` with a value threshold.
- Full working example uses the Node.js client in a Bun project, streaming results until 10 transfers above 0.005 ETH are collected.
- Trace support is available on Ethereum, Base, Arbitrum, Gnosis, and Monad.
:::
Tracking native token transfers onchain is trickier than ERC-20 transfers. There's no event log to index, so you have to dig through traces. With a standard RPC node, that means calling eth_traceBlock and iterating every trace in every block, which is slow.
HyperSync gives you a faster alternative: a data retrieval layer with native trace filtering.
## Prerequisites
We are going to use [Bun](https://bun.com/docs/installation) for this article, so make sure you have it installed. If you want to use another runtime that supports TypeScript, you can do that too.
You will also need an Envio API token to access HyperSync. If you don't have one, go to [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens) to create one. Step-by-step instructions are at [docs.envio.dev/docs/HyperSync/api-tokens](https://docs.envio.dev/docs/HyperSync/api-tokens#generating-api-tokens).
## HyperSync & Queries
HyperSync is optimized for data retrieval, not consensus, so it's far faster than RPC nodes. To fetch data, you send a query describing what you want and HyperSync returns only that data.
A typical query looks like this:
```json
{
"fromBlock": 0,
"transactions": [
{ "from": ["0x5a830d7a5149b2f1a2e72d15cd51b84379ee81e5"] },
{ "to": ["0x5a830d7a5149b2f1a2e72d15cd51b84379ee81e5"] }
],
"fieldSelection": {
"transaction": ["BlockNumber", "Hash", "From", "To", "Value"]
}
}
```
Every query has three main parts: `fromBlock`, a filter section (one of `transactions`, `blocks`, `logs`, or `traces`), and `fieldSelection`. See the [full query reference](https://docs.envio.dev/docs/HyperSync/hypersync-query#query-structure-reference) for all available options.
### Filtering for Native Transfers
Native ETH transfers occur only in traces where `call_type` is `call`, not `staticcall` or `delegatecall`. Filtering on `callType` directly is more efficient than filtering on trace `kind`, since it lets HyperSync skip irrelevant trace types upfront.
## Building the Fetcher
### Setup
Create a new Bun project and install the HyperSync client:
```sh
bun init -y && bun install @envio-dev/hypersync-client
```
Add your API token to a `.env` file. If you don't have one, generate it at [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens).
```sh
ENVIO_API_TOKEN=your_token_here
```
> **Note:** HyperSync trace support is currently available on Ethereum, Base, Arbitrum, Gnosis, and Monad. [Reach out](mailto:nikhil@envio.dev) if you need trace support for other chains.
### Imports & Helpers
```ts
import { HypersyncClient, type TraceField } from "@envio-dev/hypersync-client";
```
We'll filter out dust transfers using a minimum threshold and format values as human-readable ETH:
```ts
const THRESHOLD_WEI = BigInt("5000000000000000"); // 0.005 ETH
const WEI_PER_ETH = BigInt("1000000000000000000"); // 1 ETH
const DECIMALS = 6;
function weiToEth(wei: bigint): string {
const whole = wei / WEI_PER_ETH;
const remainder = wei % WEI_PER_ETH;
const remainderStr = remainder.toString().padStart(18, "0").slice(0, DECIMALS);
return `${whole}.${remainderStr}`;
}
```
### Creating the Client
Use the Ethereum traces endpoint:
```ts
const client = new HypersyncClient({
url: "https://eth-traces.hypersync.xyz",
apiToken: process.env.ENVIO_API_TOKEN!,
});
```
### Query
Request only `call` type traces and select the fields we care about:
```ts
const query = {
fromBlock: 22000000,
traces: [
{
callType: ["call"],
},
],
fieldSelection: {
trace: ["From", "To", "Value", "CallType", "BlockNumber"] as TraceField[],
},
};
```
### Streaming Results
HyperSync offers two fetch modes: `get` (single response) and `stream` (continuous). We'll stream and stop once we've collected 10 transfers above the threshold:
```ts
console.log("Fetching native transfers (call_type=call, value > 0.005 ETH)...\n");
const results: { from: string; to: string; valueEth: string }[] = [];
const stream = await client.stream(query, {});
outer: while (true) {
const res = await stream.recv();
if (res === null) break; // stream exhausted
if (res.data?.traces) {
for (const trace of res.data.traces) {
if (trace.value === undefined || trace.value === null) continue;
if (trace.value <= THRESHOLD_WEI) continue;
results.push({
from: trace.from ?? "unknown",
to: trace.to ?? "unknown",
valueEth: weiToEth(trace.value),
});
if (results.length >= 10) break outer;
}
}
}
await stream.close();
if (results.length === 0) {
console.log("No results found.");
} else {
console.table(
results.map((r) => ({
From: r.from,
To: r.to,
"Value (ETH)": r.valueEth,
}))
);
}
```
Run it with:
```sh
bun run index.ts
```
## Next Steps
We only used callType as a filter here. From this starting point you can track a specific wallet by adding from or to address filters to the trace selection, narrow further using other TraceSelection fields like sighash or kind, or switch the endpoint to another HyperSync trace-enabled network to run the same query across chains.
See the HyperSync query reference for the full TraceSelection schema and field list.
## Frequently Asked Questions
### What Is HyperSync's Traces Query?
[HyperSync](https://docs.envio.dev/docs/HyperSync/overview)'s traces query exposes EVM execution traces (`call`, `create`, `suicide`, `reward`) directly, rather than just contract event logs. This makes it possible to track operations that don't emit events, like native ETH transfers, by filtering on `call_type` and `value`. The traces feature is currently available on Ethereum, Base, Arbitrum, Gnosis, and Monad. Other queries (logs, transactions, blocks) work across
 April was a big step forward for AI-assisted indexing on Envio. We launched the Envio Docs MCP Server and a new Quickstart with AI guide for building or migrating indexers with Claude, Cursor, and other AI coding assistants. HyperIndex v3.0.0 alpha.21 ships with an experimental ClickHouse Sink, improved multiple data-sources support, and an updated testing framework with three ways to feed events. We also released the Polymarket V2 Indexer, which is now powering a new data-driven series breaking down the actual top-PnL traders on Polymarket. HyperSync added Monad trace support with full history from block 0, Envio went live on Tempo, and much more. The team was also at EthCC[9] in Cannes.
Let's dive in.
## HyperIndex v3.0.0 Alpha: alpha.20 & alpha.21
Continuing steady progress on V3 across indexing resilience, testing, analytics, and developer experience.
### Improved Multiple Data-Sources Support
HyperIndex now handles data source switching more intelligently.
After switching to a fallback source, HyperIndex automatically attempts to recover to the primary source 60 seconds later, rather than staying stuck on the fallback until it goes down or the indexer is restarted. The logic for choosing which source to use next has also been improved, alongside stricter enforcement of source usage configured for live mode.
The result: better indexing resilience, less vendor lock-in, and more predictable failover behaviour in production.
### Testing Framework Highlights
Our testing framework has matured with three ways to feed events, making it easier to write tests against the same indexer that runs in production. No database, no Docker, no manual mock wiring.
* Auto-exit: zero config, processes the first block with matching events
* Explicit block range: deterministic CI snapshots
* Simulate: typed synthetic events, no network needed
```typescript
import { describe, it } from "vitest";
import { createTestIndexer } from "generated";
describe("ERC20 indexer", () => {
it("processes the first block with events", async (t) => {
const indexer = createTestIndexer();
const result = await indexer.process({ chains: { 1: {} } });
// Auto-filled by Vitest on first run, just review and commit
t.expect(result).toMatchInlineSnapshot(`
{
"changes": [
{
"Transfer": {
"sets": [
{
"blockNumber": 10861674,
"from": "0x0000000000000000000000000000000000000000",
"id": "1-10861674-23",
"to": "0x41653c7d61609D856f29355E404F310Ec4142Cfb",
"transactionHash": "0x4b37d2f343608457ca...",
"value": 1000000000000000000000000000n,
},
],
},
"block": 10861674,
"chainId": 1,
"eventsProcessed": 1,
},
],
}
`);
});
});
```
### Experimental ClickHouse Sink
 HyperIndex V3 Alpha introduces an experimental ClickHouse Sink. Postgres remains the primary database, with your entity data additionally replicated to ClickHouse for analytics workloads.
ClickHouse is a columnar database built for heavy analytical queries on datasets in the 100s of GBs or TBs, a natural fit for onchain data which can easily reach billions of events for a single token. If your indexer is powering a dashboard, leaderboard, historical chart, or any reporting layer on top of a large dataset, ClickHouse is the right tool for that read path.
Enable it on Envio Cloud by setting four environment variables:
* `ENVIO_CLICKHOUSE_SINK_HOST`
* `ENVIO_CLICKHOUSE_SINK_DATABASE`
* `ENVIO_CLICKHOUSE_SINK_USERNAME`
* `ENVIO_CLICKHOUSE_SINK_PASSWORD`
Currently supported on the Dedicated Plan only, and you need to bring your own ClickHouse instance. Managed ClickHouse is coming to Envio Cloud, fill out [this form](https://forms.gle/P19S7KXYfdHQM8J69) to be one of the first users.
Read the full walkthrough here: [https://docs.envio.dev/blog/clickhouse-storage-hyperindex-v3](https://docs.envio.dev/blog/clickhouse-storage-hyperindex-v3)
See the full [release notes](https://github.com/enviodev/hyperindex/releases).
Star us on [GitHub](https://github.com/enviodev/hyperindex) ⭐
## The Top Hundred Polymarket Traders
 We released the Polymarket V2 Indexer this month, a drop-in reference for teams wanting to collect all v2 market data. It covers the new v2 markets end-to-end, designed to scale alongside Polymarket's growth.
Check it out on GitHub: [https://github.com/enviodev/polymarket-v2-indexer](https://github.com/enviodev/polymarket-v2-indexer)
Off the back of the release, we kicked off a data-driven series breaking down the actual top-PnL traders on Polymarket. 2.66 million wallets have traded on the platform, and the top 100 captured $853 million in profit between them. None of them are clicking buttons on a phone app between sips of beer.
Day 1 profiles "Bids On Everything", the wallet ranked #24 by realized PnL with roughly $24 million net profit across 2,698,796 fills, 44,954 simultaneous markets, and 289 active days. The strategy in one sentence: post buy orders on every outcome token of every binary market at every price level, then merge YES + NO pairs for one dollar whenever both fill.
It's a strong example of the kind of analysis you can run when you have full historical and real-time access to v2 market data. Stay tuned for more!
Read the full breakdown: [https://x.com/jonjonclark/status/2049067586046816561?s=20](https://x.com/jonjonclark/status/2049067586046816561?s=20)
## Envio Docs MCP Server
 Envio docs now speak AI. Plug your AI coding assistant (Claude Code, Cursor, Copilot, and more) straight into our docs with the new Envio Docs MCP Server.
* Always up-to-date
* Instant accurate context
* Easy setup
The biggest shift in AI workflows isn't better prompts, it's better context, and that's exactly what the MCP Server solves. Your assistant pulls live documentation on demand instead of relying on stale training data.
Setup guide and more here: [https://docs.envio.dev/blog/envio-docs-mcp-server](https://docs.envio.dev/blog/envio-docs-mcp-server)
## Quickstart with AI
 Build or migrate an indexer end-to-end using Claude, Cursor, or any other AI coding assistant with our new Quickstart with AI guide.
What's included:
* Live docs via MCP
* Non-interactive init
* Built-in Claude skills
* AI-assisted subgraph migration
* Programmatic deploys via the envio-cloud CLI
This pulls everything together into a single agentic workflow, from scaffolding to deployment, without touching a config file manually.
Get started here: [https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai)
## Concentrated Liquidity on Uniswap v4
Envio was a Sapphire sponsor of EthCC[9], held at Palais des Festivals in Cannes from March 30 to April 2, 2026.
JonJon took to the Monroe Stage with his talk "From x*y=k to Ticks: Seeing Concentrated Liquidity on Uniswap v4 in Real Time", walking through the jump from x*y=k to ticks on Uniswap v4, with a real-time visual layer tracking active liquidity and pool behaviour across chains.
Big thanks to the EthCC team, sponsors, organisers, and volunteers for putting on such a great event. Had a great time connecting with some incredible teams and builders across the week, and a special thanks to everyone who swung by our booth.
## Monad Traces Live on HyperSync
 Monad traces are live on HyperSync, with full history from block 0.
Stream all Monad trace data in minutes and export it to CSV using our new export tool. Ideal for teams running deep onchain analytics, MEV research, or custom pipelines on top of Monad's execution traces.
Export tool on GitHub: [https://github.com/enviodev/export-monad-traces](https://github.com/enviodev/export-monad-traces)
## Envio is Live on Tempo
 Envio is live on Tempo, the blockchain built for stablecoin payments at scale.
Index and query real-time payment data, build fully customisable data pipelines, and query millions of events up to 2000x faster than traditional RPC.
Easy, fast, and fully customisable.
Original post on X: [https://x.com/i/status/2042577679380013222](https://x.com/i/status/2042577679380013222)
## How to Track Native ETH Transfers Using HyperSync
 Tracking native ETH transfers onchain is trickier than ERC-20 transfers. There's no event log to index, so you have to parse traces, which is slow over standard RPC.
Our new tutorial walks through how to use HyperSync's native trace filtering to stream transfers by filtering on `call_type=call` with a value threshold. It includes a full working example using the Node.js client in a Bun project, streaming results until 10 transfers above 0.005 ETH are collected.
HyperSync trace support is currently available on Ethereum, Base, Arbitrum, Gnosis, and Monad.
Read the full tutorial: [https://docs.envio.dev/blog/tracking-native-eth-transfers-hypersync](https://docs.envio.dev/blog/tracking-native-eth-transfers-hypersync)
## Current & Upcoming Events & Hackathons
* [ETHConf - New York](https://ethconf.com/): June 8th -> 10th (sponsoring)
## Featured Developer: Claude
 This month's featured developer is Claude.
A shoutout to Anthropic's Claude, who has become a familiar name in the developer community and a strong collaborator for teams building with AI assistants. With the launch of the Envio Docs MCP Server and Quickstart with AI guide this month, we're excited to see how the community continues to build with AI alongside Envio.
More to come.
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/240pHTCbwvf6kBMdfWGmw9?si=bb40d616e82a49f3)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you're working on a Web3 project and want a smoother development process, Envio's got your back(end). Check out our docs, join the community, and let's talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# What is HyperSync?
> HyperSync is Envio's high-performance blockchain data layer, up to 2000x faster than RPC across dozens of supported chains. Learn what it is, how it works, and how to query it.

:::info TL;DR
- HyperSync is Envio's high-performance blockchain data-retrieval layer.
- Up to 2000x faster than RPC for getting or fetching the logs, transactions, traces, and blocks across
 :::note TL;DR
- Revert Finance's PancakeSwap V3 subgraph on The Graph had been stuck at 70% sync on BNB Smart Chain for over 2 years.
- Envio HyperIndex synced 1,711,569,200 events to 100% in 10 days, solving a problem that had gone unresolved for over 2 years.
- HyperSync eliminates the RPC bottleneck that causes other indexing frameworks to stall on high-throughput chains, like BNB Smart Chain, while HyperIndex's batch processing and caching ensure the indexer keeps up with the throughput.
:::
Revert Finance builds analytics and management tools for AMM liquidity providers across protocols including PancakeSwap, Uniswap, and others. Accurate, real-time onchain data is the foundation of everything they build.
They run several indexers using Envio, spanning multiple chains and contracts. This case study covers one of them: a PancakeSwap V3 indexer on BNB Smart Chain. Their previous subgraph had been stuck at 70% sync for over 2 years, unable to reach the chain's head.
 The subgraph instance can be viewed here: [https://thegraph.com/explorer/subgraphs/Hv1GncLY5docZoGtXjo4kwbTvxm3MAhVZqBZE4sUT9eZ?view=Query&chain=bsc](https://thegraph.com/explorer/subgraphs/Hv1GncLY5docZoGtXjo4kwbTvxm3MAhVZqBZE4sUT9eZ?view=Query&chain=bsc)
Envio built a HyperIndex indexer for PancakeSwap V3 on BNB Smart Chain. It synced 1,711,569,200 events to 100% in 10 days.
## The Problem Revert Finance Needed to Solve
Revert Finance requires real-time PancakeSwap V3 position and liquidity data to power its analytics and tooling for liquidity providers. A public subgraph on The Graph's decentralized network had been stuck at 70% sync on BNB Smart Chain for over 2 years, unable to reach chain head.
BNB Smart Chain's high throughput has presented well-documented challenges for RPC-based indexing, with teams reporting sync issues going back to 2021. The volume of events per block outpaces what standard indexing infrastructure can sustain, causing subgraphs to fall progressively further behind until they stall entirely.
A subgraph stuck at 70% sync for over 2 years is effectively unusable.
## The Solution: Envio HyperIndex on BNB Smart Chain
Envio HyperIndex is a real-time multichain blockchain indexing framework for any EVM chain. Developers write event handlers in TypeScript and deploy a single indexer covering multiple contracts and chains simultaneously. It uses [HyperSync](/docs/HyperSync/overview), Envio's proprietary data engine, which serves filtered event data in bulk directly from a purpose-built data lake, replacing having to poll RPC endpoints block by block. This removes the RPC bottleneck entirely, which is precisely what causes subgraph stalls on BNB Smart Chain.
HyperIndex is independently benchmarked as the fastest blockchain indexer available. In the Uniswap V2 Factory benchmark run by Sentio in May 2025, HyperIndex synced in 8 seconds, 142x faster than The Graph and 15x faster than the nearest competitor. BNB Smart Chain is one of
 ## The Results
| Metric | Result |
|--------|--------|
| Chain | BNB Smart Chain (chain ID 56) |
| Events processed | 1,711,569,200 |
| Historical sync time | 10 days |
| Final sync status | 100% at block 88,286,723 |
| Start block | 26,956,207 |
Over 1.7 billion events, fully synced, on a chain where the equivalent subgraph had been stuck for over 2 years. The indexer is hosted on Envio Cloud, Envio's managed hosting platform.

"We had a problem with our PancakeSwap V3 data on BNB for over two years. The subgraph just would not catch up, and we'd basically given up on it. Envio synced it in 10 days. Great team, great dev experience!"
Mario Romero, Founder at Revert Finance
 :::note TL;DR
- Privacy Pools is live on **4 chains (Ethereum, Optimism, BSC, Arbitrum) across 21 pools**, with ~$5.78M of TVL, ~5,180 lifetime deposits, ~5,630 withdrawals, and a healthy mainnet ETH pool of **2,320 distinct depositors** behind a strong anonymity set.
- The protocol's ZK proof hides which deposit funded which withdrawal cryptographically. Public-data signals an outside observer could attempt to read are heuristic only, and the protocol's design (open ragequit, free decoy construction, relayer flow) makes those heuristics impossible to verify from on-chain data alone.
- Indexed end-to-end with one Envio HyperIndex v3 indexer, ClickHouse storage, and a thin Uniswap V4 price feed on BSC. Full multichain sync to head: ~30 seconds.
- Full open-source code, queries, and BI report generator at [github.com/enviodev/privacy-pools](https://github.com/enviodev/privacy-pools).
:::
[Privacy Pools](https://privacypools.com) is one of the more ambitious privacy primitives shipped on Ethereum and its L2s. The protocol, [co-authored by Vitalik Buterin and others](https://papers.ssrn.com/sol3/papers.cfm?abstract_id=4563364), pairs a zero-knowledge proof of pool membership with an off-chain compliance vetting layer (the **Association Set Provider**, ASP). The result is a privacy mechanism that gives users cryptographic unlinkability between their deposit and their withdrawal, while still letting an off-chain layer say "we don't think this commitment came from a sanctioned address". Both halves matter, and both halves are working.
This post walks through a fully indexed snapshot of every deposit, withdrawal, ragequit, ASP root update, and relayer fee across all 21 live pools on every chain Privacy Pools runs on (14 on Ethereum, 2 on Optimism, 2 on BSC, 3 on Arbitrum). The headline takeaways are positive: the ZK proof is sound, the relayed-withdrawal path that preserves privacy gets used by 91% of withdrawers, and the largest pool has a genuinely diverse depositor base. The smaller, newer pools are doing what newer pools do: building toward those numbers.
The interesting analytical question, then, is what an outside observer with the public on-chain data can or can't say about who linked to whom. The answer is a clean "very little, and never with certainty". This is by design, and the data shows the design holding.
The full stack (indexer, analytics queries, BI report generator) is open-source at [github.com/enviodev/privacy-pools](https://github.com/enviodev/privacy-pools) under MIT license.
## What is Privacy Pools
Three on-chain entities matter for indexing:
- **The Entrypoint**: the singleton each pool registers under. Routes deposits and relays withdrawals.
- **PrivacyPool**: one contract per asset (ETH, USDC, USDT, fxUSD, BOLD, and so on). Emits `Deposited`, `Withdrawn`, `Ragequit`, `LeafInserted`, `PoolDied`.
- **Association Set Provider (ASP)**: off-chain vetting. On-chain footprint is the `RootUpdated` events from the Entrypoint, each carrying a Merkle root and an IPFS pointer to the approved set.
The deposit/withdraw flow produces a commitment in a per-pool Merkle tree on deposit, and on withdrawal proves "I own *some* commitment in this pool, and that commitment is in the **Association Set** approved by the ASP", without revealing which commitment. `Ragequit` is the escape hatch: a depositor whose commitment has been excluded from a recent ASP root pulls their position out without the ZK-protected withdrawal flow.
## The Dataset
The indexer covers every Entrypoint and every PrivacyPool live across the four supported chains. Headline state at the time of writing (block heights are real-time):
| chain | pools | deposits | withdrawals | ragequits | leaves |
|---|---|---|---|---|---|
| Ethereum | 14 | 4,731 | 5,138 | 322 | 9,883 |
| Optimism | 2 | 124 | 128 | 37 | 254 |
| BSC | 2 | 60 | 20 | 45 | 82 |
| Arbitrum | 3 | 265 | 344 | 36 | 612 |
| **Total** | **21** | **5,180** | **5,630** | **440** | **10,831** |
USD TVL across all chains: **~$5.78M**. Largest pools:
| pool | TVL (USD) |
|---|---|
| Ethereum USDT | $2.40M |
| Ethereum ETH | $1.75M |
| Ethereum USDC | $1.46M |
## The mainnet ETH pool: a working anonymity set
The Ethereum ETH pool is the protocol's flagship deployment, and its numbers tell a clear story:
- **2,320 distinct depositors** (the next-largest cohort is 253 on Ethereum USDC).
- **7,889 leaves** in the Merkle tree, more than every other pool combined.
- **Herfindahl-Hirschman Index of 132** on depositor-value share, far below the 2,500 threshold considered "highly concentrated". The top depositor controls 8.0% of value, the top five 17.4%, the top ten 24.7%. There is no dominant wallet.
Together those numbers describe a pool with real anonymity. A withdrawal from this pool has thousands of plausible commitments behind it, and no single dominant depositor for an analyst to single out.
The smaller pools (BNB on BSC, yUSND on Arbitrum, BOLD on Ethereum, and the rest of the long tail) are at much earlier points in the same curve. With anywhere from 1 to ~250 leaves, the long tail is in early-cohort phase. Concentration is high there because the pools are young, not because the protocol is broken.
## Anonymity-set growth
Each commitment lives as a leaf in the per-pool Merkle tree. Both deposits and the ZK-replacement leaves emitted on withdrawal contribute, so the leaf count keeps climbing as the pool gets used.
 The Ethereum ETH pool dominates by volume, but every active pool shows steady growth. There is no sign of pool abandonment.
## Activity patterns
Aggregating deposits and withdrawals by hour-of-day and day-of-week (UTC) reveals a global usage pattern: activity is roughly continuous, with a mild ramp through European and US business hours and a softer Asia-Pacific tail. Privacy Pools is being used as a steady utility, not as an event-driven product.
 The lack of strong timezone clustering is itself a privacy positive: a sharply timezone-skewed user base would be an inadvertent fingerprint. This data shows a globally distributed user set.
## Relayed-withdrawal share
Withdrawals can be self-submitted (the recipient submits their own proof, paying gas with their own address) or relayed (a relayer submits on the recipient's behalf, taking a fee). Self-submitted withdrawals link the recipient address to the gas-paying address; relayed withdrawals don't.
Across all chains:
- **5,148** withdrawals were relayed.
- **482** were self-submitted (~8.6%).
**91.4%** of withdrawals took the privacy-preserving relayed path. That's a strong positive signal: users understand the privacy model and use it.
The relayer market on Ethereum is currently concentrated, with one relayer (`0xec15c200…`) processing ~77.7% of relayed flow and `0x855b4a60…` taking 19.9%. The relayer doesn't see the deposit side, so they can't break the ZK link, but the concentration is worth watching as the relayer ecosystem matures. New relayers entering the market would distribute that observability and is a natural maturation step for the protocol.
## Linkability: the public-data heuristic, and why it can never be proof
Take every (deposit, withdrawal) pair in the same pool with the same on-chain value, and a time gap of 60 seconds to 2 hours. Treat the withdrawal as *possibly linkable* to that deposit by an external observer.
This is a heuristic. There is no proof the same actor controls both addresses, only that the visible flow is consistent with that.
| pool | candidate pairs | total withdrawals | linkable share | median gap |
|---|---|---|---|---|
| Ethereum USDC | 50 | 862 | 5.6% | 61 min |
| Ethereum USDT | 7 | 170 | 3.5% | 57 min |
| Ethereum ETH | 882 | 3,916 | ~10.9% | 39 min |
| Arbitrum USDC | 26 | 150 | 16.0% | 57 min |
| Arbitrum ETH | 28 | 168 | 15.5% | 47 min |
| Optimism ETH | 13 | 60 | 15.0% | 61 min |
| BSC USDT | 3 | 8 | 37.5% | 25 min |
| Ethereum USDS | 3 | 8 | 37.5% | 4 min |
About one in ten Ethereum ETH withdrawals fits this shape. On the smaller pools, the share is higher because there are fewer deposits to lose oneself in. These are upper bounds on what a naive heuristic can flag, and they are not proofs. The next section shows why.
## Decoy withdrawals: how the protocol absorbs the heuristic
The same-amount heuristic has a known counter, and it is a feature of the privacy model rather than a workaround.
An existing depositor whose funds have been in the pool for weeks or months sees a fresh deposit hit the contract. They withdraw an equivalent amount within the heuristic's time window, to a fresh address that has nothing to do with the new depositor. An outside observer running the same-amount analysis links the new deposit to that withdrawal address.
From outside, the pair looks like "Alice deposited and Alice (the withdrawal recipient) withdrew shortly after". Inside, Alice and the withdrawal recipient have nothing to do with each other. The withdrawer's funds predate Alice entirely.
Querying for deposits followed within 30 minutes by a same-amount withdrawal where the depositor and the withdrawal recipient are different addresses:
- **393** decoy-candidate pairs across the dataset.
- **163** distinct depositors had a same-amount withdrawal land within 30 minutes from a different address.
- **160** distinct withdrawal addresses received those decoy-shaped withdrawals.
These are candidates, not proven decoys. Every pair could be one of three things, all indistinguishable from public data:
1. The depositor really is the same actor, just routing the receipt through a different address.
2. Two unrelated parties happen to transact for the same round amount within minutes (more likely on busy pools and round denominations).
3. An existing depositor deliberately constructs the match to spoof the heuristic.
Because option (3) is cheap (one extra withdrawal proof) and option (2) is plausible on common amounts, the linkable-share table above is a *plausibility upper bound*, not a recall figure. An actor who knows the heuristic exists can deliberately produce false matches, and an actor who is genuinely the same person across both addresses will also show up in the same table. This is the verifiability ceiling that the protocol's design relies on, and it does the load-bearing work of converting the cryptographic guarantee into practical anonymity. Plausible deniability is real precisely because it can never be ruled out from public data.
## Ragequit: the safety valve doing its job
Ragequit is the escape hatch. When the ASP excludes a commitment from the latest approved root, the depositor still gets their funds back, just through a path that reveals which commitment they originally made.
The mainnet ETH baseline is **6.0% ragequit-by-count, 9.2% by value**. The smaller pools have higher rates:
 | pool | ragequit % (count) | ragequit % (value) |
|---|---|---|
| BSC BNB | 78.3% | 97.1% |
| Arbitrum yUSND | 48.5% | 90.7% |
| BSC USDT | 72.9% | 78.6% |
| Ethereum USDS | 62.5% | 58.7% |
| Ethereum sUSDS | 54.5% | 35.7% |
| Ethereum fxUSD | 15.8% | 33.2% |
| Ethereum wstETH | 23.5% | 24.0% |
| Ethereum ETH | 6.0% | 9.2% |
Three pools (BSC BNB, Arbitrum yUSND, BSC USDT) have seen most of their deposit value exit through the ragequit path rather than ordinary withdrawals. Depositors did not lose funds, they got their money back. What was lost on those specific commitments was the cryptographic privacy property, because ragequit reveals which commitment exited.
This is the ASP doing what it is designed to do: rejecting commitments after the fact when the off-chain compliance check changes its mind, and giving users a way out that doesn't trap their funds. The fact that the escape hatch is being exercised on the edges (small, young pools) is the system's compliance layer working as advertised, and it doesn't affect the privacy of any other depositor. For the mainnet ETH pool, where the bulk of activity sits, the ragequit rate is low and stable.
## Where the public-data layer helps
A privacy protocol's job is to provide cryptographic guarantees that an external observer can't link who deposited what to who withdrew. Privacy Pools does that: the ZK proof is sound, the verifiers are deployed, the on-chain mechanism works.
What the on-chain trail also does is record every deposit value, every withdrawal value, every relayer address, every recipient, and every timestamp. From that an indexed dataset gives you:
- A linkable-share number per pool (5-37% across the indexed pools), constrained by the verifiability ceiling above.
- A concentration index per pool that tells you how mature the anonymity set is.
- A ragequit-rate signal that confirms the ASP layer is active and that the safety valve is functioning.
- A relayed-share number showing 91% of withdrawers using the privacy-preserving path.
- A decoy-candidate count that quantifies how much credibility the plausible-deniability layer has on each pool.
None of these break the protocol. None of these are verifiable. All of them are useful operational metadata that anyone, including the ASP, the protocol team, and end users, can use to track the protocol's health.
The point of indexing the protocol publicly is precisely that this kind of monitoring should be open. The same dataset that enables the heuristics also exposes the limits of those heuristics, and lets honest actors and the protocol team work on the things that actually matter (anonymity-set growth on the long-tail pools, relayer-market diversification, ASP responsiveness) without anyone needing privileged access.
## What this isn't
A few things this analysis explicitly does *not* show:
- **It does not break the ZK proof.** Every linkability claim above is heuristic. A withdrawal that matches a deposit by amount and timing is consistent with the same actor controlling both addresses, but it is not proof.
- **The decoy-candidate count is not a fraud detector.** Many of the 393 decoy-shaped pairs will be coincidence on common round amounts, and some will be the same actor using a fresh address. The count is a ceiling on intentional decoys, not a measurement of them.
- **High-ragequit pools aren't broken.** Ragequit firing is the system working as designed when the ASP excludes a commitment.
- **The fee figures are operator drains, not gross protocol revenue.** The Entrypoint emits post-fee deposit values, so we can only observe the cashflow at the `FeesWithdrawn` step.
Any heuristic an analyst can run, a depositor can game. Anyone can construct decoy patterns at low cost. Anyone can split deposits across rounds, jitter timing, and rotate recipient addresses. Public-data heuristics are a probability surface, not a truth function. Privacy Pools is built for exactly that constraint.
## How this was indexed
The full stack is one Envio HyperIndex v3 indexer running locally with dual Postgres + ClickHouse storage:
- **One config**, four chains: Ethereum (1), Optimism (10), BSC (56), Arbitrum (42161). Same `Entrypoint` and `PrivacyPool` ABIs reused across all four. The L2s share a deterministic `0x44192215…` Entrypoint via CreateX, while mainnet has the original `0x6818809E…`.
- **One handler set** writes 9 entity types: `Pool`, `Deposit`, `Withdrawal`, `Ragequit`, `MerkleLeaf`, `AssociationSetRoot`, `Account`, `FeeWithdrawal`, plus a derived `LatestPrice`/`TokenPrice` pair from a thin Uniswap V4 price feed on BSC. All chain-scoped IDs (`{chainId}_{address}`) so the L2 ETH-pool address collision (`0x4626…918ff` is the ETH pool on Optimism, BSC, *and* Arbitrum) doesn't fold rows together.
- **Multichain sync to head: ~30 seconds.** HyperSync handles 4 chains in parallel; the only non-trivial cost is the V4 price feed, which we keep cheap by starting near BSC's head and filtering Swap events to ~70 hardcoded pricing-pool IDs (see [Uniswap V4 deployments](https://developers.uniswap.org/contracts/v4/deployments)). No Initialize handler, no historical V4 backfill, just current prices.
- **Analytics on ClickHouse.** A Python `analytics/` package runs the headline queries through `clickhouse-connect`, charts them with matplotlib, and assembles a markdown BI report that renders to PDF via `reportlab`. The full report regenerates in a couple of seconds against the live ClickHouse.
The schema and the SQL queries are designed for this kind of question. Adding a new heuristic, say "deposits whose precommitment hash has a leading-zero prefix", is an `.sql` file, not a re-index.
## Reproducing this
The full stack lives at [**github.com/enviodev/privacy-pools**](https://github.com/enviodev/privacy-pools) under MIT license. One HyperIndex v3 indexer plus a Python analytics package that ships the BI report generator and every saved query.
- `config.yaml`, `schema.graphql`, `src/EventHandlers.ts`, `src/v4Pricing.ts`, `src/v4PoolMeta.ts`: the indexer.
- `analytics/queries/{health,anonymity,risk,asp,relayers,fees,activity,pricing}/*.sql`: every metric in this post.
- `analytics/scripts/generate_bi_report.py`: assembles the report markdown plus 6 charts.
- `analytics/scripts/render_pdf.py`: markdown to PDF, including image embedding.
```bash
git clone https://github.com/enviodev/privacy-pools
cd privacy-pools
cp .env.example .env # add your free ENVIO_API_TOKEN from envio.dev
pnpm install
pnpm envio start
# in another shell
cd analytics
cp .env.example .env
uv sync
uv run python scripts/generate_bi_report.py
```
Multichain sync completes in well under a minute. The BI report regenerates against live ClickHouse in seconds.
If you want to extend the analysis (chain-cross transitive linkability, ASP root vs deposit timing, relayer-collusion graphs, or anything else), every entity carries `chainId` and `blockNumber`, and the schema is documented end-to-end in `analytics/CLAUDE.md`.
## Build with Envio
Envio HyperIndex is independently benchmarked as the fastest EVM blockchain indexer available. The Privacy Pools indexer is one example of what's possible when multichain coverage and an analytics-grade columnar store are first-class features. If you're building onchain (DeFi, prediction markets, gaming, or something nobody has thought of yet), the [docs](https://docs.envio.dev/docs/HyperIndex/overview) are the starting point.
- Repo: [https://github.com/enviodev/privacy-pools](https://github.com/enviodev/privacy-pools)
- Docs: [https://docs.envio.dev/](https://docs.envio.dev/)
- Discord: [https://discord.gg/envio](https://discord.gg/envio)
- Telegram: [https://t.me/+BeS5ihVUFONjNGFk](https://t.me/+BeS5ihVUFONjNGFk)
- X: [https://x.com/envio_indexer](https://x.com/envio_indexer)
---
# Why AI Agents Acting Onchain Need an Indexer
> AI agents that act onchain need reorg-safe, queryable data they can act on. HyperIndex delivers it. Real MCP server, real Claude skills, 400k events in 20 seconds.
 :::note TL;DR
- HyperIndex is Envio's multichain blockchain indexing framework for EVM chains. It is the right data layer for AI agents acting onchain because it ships reorg-safe data, structured GraphQL output, an MCP server that exposes the docs to any agent, and a `.claude/skills/` directory that auto-discovers for Cursor, Claude Code, and Codex.
- The published [agentic demo](https://docs.envio.dev/blog/agentic-blockchain-indexing-envio-hyperindex) documents an end-to-end flow where an agent scaffolded, configured, pushed to GitHub, and deployed a wstETH indexer on Monad Mainnet from a single prompt. 400,000 events indexed in approximately 20 seconds.
- The Envio docs MCP server exposes two tools (`docs_search` and `docs_fetch`) over Streamable HTTP at `https://docs.envio.dev/mcp`. Configured into Claude Code, Cursor, or VS Code with one command.
- HyperIndex projects scaffold a `.claude/skills/` directory pre-populated with 14 skills covering config, schema, handler syntax, factory patterns, filters, multichain, performance, traces, transactions, wildcard, blocks, external calls (the Effect API), testing, and subgraph migration.
:::
The agentic-onchain conversation in 2026 has settled into two camps. One says agents need a reconciled SQL warehouse to make sense of raw blockchain data. The other says agents need a programmable indexer that lets them act, not just analyse. Both are right about the diagnosis. Raw RPC is unworkable for an agent. The disagreement is about what replaces it.
This blog is the case for indexers, not warehouses. A SQL warehouse lets an agent ask questions. An indexing framework lets an agent build, deploy, and own new data pipelines mid-session. The first is a query tool, the second is infrastructure. Agents acting onchain need the second. HyperIndex ships it today.
## Why Raw Blockchain Data Breaks Agents
An agent reading from RPC directly hits four problems within minutes.
**1. Reorgs.** A recent block can be reorged. An agent that wrote a record based on an unfinalized block has to either lag the chain head (and miss real-time signals) or roll its own rollback logic (and get it wrong on the next edge case). Neither is acceptable for an agent running in a production environment.
**2. Schema.** RPC returns logs and transactions. It does not return entities, relationships, or aggregations. The agent has to assemble the schema in memory on every query. Cross-contract state, factory pattern instances, and anything time-windowed have to be rebuilt from scratch.
**3. Throughput.** An agent that wants to know the last 1,000 trades on a market has to issue 1,000 `eth_getLogs` calls or hand-tune a paginated request. A historical sweep across a year of activity can take hours to query from RPC.
**4. Multichain.** Most agents that matter operate across at least two chains. Each chain is a separate RPC, separate quirks, separate rate limits. The application code that joins those RPCs is exactly the indexing code an indexer would write for you.
The standard response to "raw RPC is unworkable for agents" is to put a SQL warehouse in front of it. That works for read-only analytical queries. It does not work for an agent that needs to spin up a new product on top of the data within a session.
## What HyperIndex Provides Instead
HyperIndex addresses all four problems by being a blockchain indexing framework rather than a query layer.
- **Reorg safety at the framework level.** Entity state history, automatic rollback, no reorg logic required in handlers. Learn more in [Indexing and Reorgs](https://docs.envio.dev/blog/indexing-and-reorgs).
- **Structured GraphQL output.** Entities, relationships, aggregations, time-windowed views, all queryable from one endpoint. Agents read GraphQL, not raw logs.
- **HyperSync historical throughput.** Up to 2,000x faster than RPC. The Polymarket reference indexer synced its first 4,000,000,000 events in 6 days and has indexed over 6,500,000,000 to date.
- **Multichain in one config.**
 :::note TL;DR
- HyperIndex is Envio's multichain blockchain indexing framework for EVM chains. With Claude Code pointed at a HyperIndex project, the agent has the docs (via the docs MCP server) and the patterns (via the auto-discovered `.claude/skills/` directory shipped with every v3 rc project) to scaffold, code, deploy, and run an indexer end to end.
- The CLI surface is `pnpx envio init` for scaffold, `TUI_OFF=true pnpm dev` for local, and the GitHub-native `envio-cloud indexer add` flow for hosted deployments. Every command is scriptable and agent-friendly.
- The Polymarket reference at [github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer) is the public production example. 8 subgraphs replaced with 1; the first 4,000,000,000 events synced in 6 days, over 6,500,000,000 indexed to date.
- Anything in this blog is reproducible today against the current HyperIndex release tracked at [github.com/enviodev/hyperindex/releases](https://github.com/enviodev/hyperindex/releases).
:::
This is a practical, end-to-end walkthrough of building a HyperIndex indexer with Claude as a pair programmer. Every command is from the published Envio docs. Every code shape is taken directly from the public Polymarket reference indexer. The aim is to show the shortest reliable path from a blank project to a deployed multichain indexer that an engineer (or an agent) can actually run today.
## What You're Building
A multichain HyperIndex indexer that tracks ERC20 transfers across two chains (Ethereum and Base) and exposes the data through a GraphQL endpoint. Two contracts, one schema, one config, deployed to [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service) and queryable in roughly 30 minutes if you are reading along, or roughly 5 minutes if Claude is driving.
The structure of the project will be three files plus generated TypeScript:
```text
my-erc20-indexer/
config.yaml # Networks, contracts, events
schema.graphql # Entity model
src/EventHandlers.ts # The handler logic
```
Source for the three-file structure: [docs.envio.dev/docs/HyperIndex/quickstart-with-ai](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai).
## Step 0: Wire Up Claude
Once. Then never again. The Envio [docs MCP server](https://docs.envio.dev/docs/HyperIndex/mcp-server) exposes the live docs to any MCP-capable agent. From the docs MCP server reference, the setup commands are:
For Claude Code:
```bash
claude mcp add --transport http envio-docs https://docs.envio.dev/mcp
```
For Cursor or VS Code, drop this into the MCP config:
```json
{
"mcpServers": {
"envio-docs": {
"url": "https://docs.envio.dev/mcp",
"transport": "http"
}
}
}
```
After this, Claude has two tools available in any session: `docs_search` (semantic search) and `docs_fetch` (retrieve a page). The agent uses these instead of guessing at API surface from training data.
## Step 1: Scaffold the Project
Use the template flow to scaffold an ERC20 indexer in one non-interactive command.
```bash
pnpx envio@3.0.0-rc.0 init template -t erc20 -l typescript -d ./my-indexer --api-token ""
```
This pulls the current HyperIndex v3 release candidate, which ships with the V3 testing framework, the built-in `.claude/skills/` directory, and the current CLI flags. The current release is tracked at [github.com/enviodev/hyperindex/releases](https://github.com/enviodev/hyperindex/releases).
The `--api-token ""` flag tells the init to run non-interactively, with no prompt for an Etherscan-style API token. If an agent is driving, every interactive prompt is a failure mode.
The init produces the three files plus a `package.json`, `tsconfig.json`, an `AGENTS.md` and `CLAUDE.md` documenting the conventions, and an auto-discovered `.claude/skills/` directory. Every project scaffolded with v3 rc ships these skills out of the box, encoding the indexing patterns Claude needs to write idiomatic HyperIndex code without improvising.
## Step 2: Make It Multichain
The init scaffolds for one chain. Adding a second is a config edit, not a fresh project. Open `config.yaml` and add a second chain entry. The shape mirrors the public [Polymarket config](https://github.com/enviodev/polymarket-indexer/blob/main/config.yaml). HyperIndex uses two-tier declaration. Top-level `contracts:` for global event signatures, then a `chains:` array for per-chain addresses and start blocks.
```yaml
# Pattern from: https://github.com/enviodev/polymarket-indexer/blob/main/config.yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: erc20-multichain
contracts:
- name: USDC
events:
- event: "Transfer(address indexed from, address indexed to, uint256 value)"
field_selection:
transaction_fields:
- hash
- from
- to
chains:
- id: 1
start_block: 17000000
contracts:
- name: USDC
address: "0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48"
- id: 8453
start_block: 2000000
contracts:
- name: USDC
address: "0x833589fCD6eDb6E08f4c7C32D4f71b54bdA02913"
```
Three things to call out:
- `chains:` is the keyword, not `networks:`. Per the AGENTS.md generated into every HyperIndex project: "Uses chains (not networks)." If your editor or an AI agent suggests `networks:`, the schema validation will fail.
- The `handler:` field is optional. Handlers auto-register from `src/handlers/`. Same AGENTS.md.
- `field_selection` controls which transaction fields HyperSync ships down. Asking for fewer fields is faster and uses less memory.
For the current set of supported config options including per-contract `start_block` and environment variable interpolation, the full [configuration reference](https://docs.envio.dev/docs/HyperIndex/configuration-file) lives in the docs.
## Step 3: The Schema
Edit `schema.graphql` to model entities the application will query. The shape uses a `chainId`-first pattern (per-chain entities plus aggregated entities) for clean cross-chain queries:
```graphql
# Pattern from: https://github.com/enviodev/polymarket-indexer/blob/main/schema.graphql
type Transfer
@index(fields: ["from", ["timestamp", "DESC"]])
@index(fields: ["to", ["timestamp", "DESC"]])
{
id: ID!
from: String! @index
to: String! @index
value: BigInt!
chainId: Int!
blockNumber: Int!
timestamp: Int!
}
type AccountBalance {
id: ID!
account: String! @index
chainId: Int!
balance: BigInt!
lastUpdated: Int!
}
type AggregateBalance {
id: ID!
account: String! @index
totalAcrossChains: BigInt!
lastUpdated: Int!
}
```
Two HyperIndex-specific things worth noting in this schema:
- No `@entity` decorator. From the project's `AGENTS.md`: "Unlike TheGraph, schema types have no decorators." Subgraphs put `@entity` on every type. HyperIndex does not.
- `@index` is composable. The [Polymarket schema](https://github.com/enviodev/polymarket-indexer/blob/main/schema.graphql) uses both per-field `@index` and per-type composite indexes like `@index(fields: ["from", ["timestamp", "DESC"]])` to drive the queries the application needs.
`Transfer` carries every transfer event with `chainId` first-class. `AccountBalance` is per-chain. `AggregateBalance` is the cross-chain rollup. The same indexer writes to all three.
After editing the schema, run `pnpm codegen` to regenerate the typed bindings. The project's `AGENTS.md` is explicit that codegen is required after any schema or config change. Types go stale otherwise.
## Step 4: The Handler
In v3 rc, types come from the `envio` package directly. The handler imports `indexer` plus any entity types it needs, then registers handlers as `indexer.onEvent({ contract: "CONTRACT_NAME", event: "EVENT_NAME" }, handler)`.
```typescript
import {
indexer,
type Transfer,
type AccountBalance,
type AggregateBalance,
} from "envio";
indexer.onEvent(
{ contract: "USDC", event: "Transfer" },
async ({ event, context }) => {
const transferId = `${event.chainId}_${event.block.number}_${event.logIndex}`;
const transfer: Transfer = {
id: transferId,
from: event.params.from,
to: event.params.to,
value: event.params.value,
chainId: event.chainId,
blockNumber: event.block.number,
timestamp: event.block.timestamp,
};
context.Transfer.set(transfer);
const fromKey = `${event.chainId}_${event.params.from}`;
const toKey = `${event.chainId}_${event.params.to}`;
const fromBal: AccountBalance = (await context.AccountBalance.get(fromKey)) ?? {
id: fromKey,
account: event.params.from,
chainId: event.chainId,
balance: 0n,
lastUpdated: event.block.timestamp,
};
context.AccountBalance.set({
...fromBal,
balance: fromBal.balance - event.params.value,
lastUpdated: event.block.timestamp,
});
const toBal: AccountBalance = (await context.AccountBalance.get(toKey)) ?? {
id: toKey,
account: event.params.to,
chainId: event.chainId,
balance: 0n,
lastUpdated: event.block.timestamp,
};
context.AccountBalance.set({
...toBal,
balance: toBal.balance + event.params.value,
lastUpdated: event.block.timestamp,
});
const fromAgg: AggregateBalance = (await context.AggregateBalance.get(event.params.from)) ?? {
id: event.params.from,
account: event.params.from,
totalAcrossChains: 0n,
lastUpdated: event.block.timestamp,
};
context.AggregateBalance.set({
...fromAgg,
totalAcrossChains: fromAgg.totalAcrossChains - event.params.value,
lastUpdated: event.block.timestamp,
});
const toAgg: AggregateBalance = (await context.AggregateBalance.get(event.params.to)) ?? {
id: event.params.to,
account: event.params.to,
totalAcrossChains: 0n,
lastUpdated: event.block.timestamp,
};
context.AggregateBalance.set({
...toAgg,
totalAcrossChains: toAgg.totalAcrossChains + event.params.value,
lastUpdated: event.block.timestamp,
});
},
);
```
Three project-enforced conventions visible in this snippet, all spelled out in the `AGENTS.md` generated into every HyperIndex project:
- **Spread operator for updates.** Entities returned by `context.Entity.get()` are read-only. Always spread: `context.Entity.set({ ...existing, field: newValue })`. Direct mutation throws.
- **Composite IDs for cross-chain uniqueness.** `${event.chainId}_${event.block.number}_${event.logIndex}` is the Polymarket pattern. Without `chainId` in the ID, two chains writing the same `(block, logIndex)` collide.
- **Effect API for any external call.** If the handler needs to fetch Gamma metadata, call an RPC, or hit any other async I/O, use `createEffect` plus `context.effect()`. Never call external services directly. The Polymarket `TokenRegistered` handler shows the pattern with `context.effect(getMarketMetadata, token0Str)`.
This is the structure an agent with the `indexer-handlers` and `indexer-external-calls` skills produces when asked to "write the Transfer handler that updates per-chain and aggregate balances." The skills encode these conventions so the agent does not improvise them wrongly.
## Step 5: Run It Locally
```bash
pnpm install
pnpm codegen # regenerate types from schema + config
pnpm tsc --noEmit # type-check without emitting
TUI_OFF=true pnpm dev # run indexer (TUI_OFF gives AI-friendly stdout)
```
Source for these exact commands: [polymarket-indexer/AGENTS.md](https://github.com/enviodev/polymarket-indexer/blob/main/AGENTS.md).
The local dev environment spins up a Postgres and a Hasura GraphQL instance. The indexer starts pulling events from both chains via HyperSync. Sync rates of 25,000 events per second on historical backfill are standard. The [Polymarket case study](https://docs.envio.dev/blog/polymarket-hyperindex-case-study) documents 4,000,000,000 events synced in 6 days on Polygon; the indexer has since indexed over 6,500,000,000 in total.
The Hasura GraphQL endpoint is available locally. Once the indexer is at chain head, queries like:
```graphql
query AggregateBalanceForAccount {
AggregateBalance(where: { account: { _eq: "0xabc..." } }) {
account
totalAcrossChains
lastUpdated
}
}
```
return live data.
## Step 6: Deploy to Envio Cloud
Envio Cloud uses a GitHub-native deploy model. An agent commits the indexer to a GitHub repo, pushes to the `envio` branch (the default deploy branch), and registers the indexer with `envio-cloud indexer add`. The Envio GitHub App handles deployments from there. No deploy button, no dashboard step.
Install the CLI and authenticate:
```bash
npm install -g envio-cloud
envio-cloud login
```
Push the project to GitHub on the `envio` branch:
```bash
gh repo create my-erc20-indexer --public
git init && git add . && git commit -m "init"
git push -u origin main
git checkout -b envio && git push -u origin envio
```
Connect the Envio GitHub App to the repo (one-time install at [github.com/apps/envio-deployments](https://github.com/apps/envio-deployments/installations/select_target)), then register the indexer:
```bash
envio-cloud indexer add \
--name my-erc20-indexer \
--repo my-erc20-indexer \
--description "Multichain ERC20 indexer" \
--branch envio \
--skip-repo-check \
--yes
```
The verified CLI surface (from the [agentic indexing blog](https://docs.envio.dev/blog/agentic-blockchain-indexing-envio-hyperindex)) includes:
- `envio-cloud login` authenticates via GitHub
- `envio-cloud indexer add` registers a new indexer pointing at a GitHub repo and branch
- `envio-cloud indexer get` fetches indexer details
- `envio-cloud deployment status` returns the current sync state of a deployment
- `envio-cloud deployment metrics` returns runtime metrics
- `envio-cloud deployment promote` promotes a deployment to production
- `-o json` on any command for parseable output
Track sync progress with `envio-cloud deployment status` and `envio-cloud deployment metrics`. Full reference at [docs.envio.dev/docs/HyperIndex/envio-cloud-cli](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli).
## Step 7: Test It
`pnpm test` runs the project's Vitest suite. In v3 rc, tests import `createTestIndexer` and `TestHelpers` from the `envio` package directly, so tests use the same types as handlers. The `indexer-testing` skill in `.claude/skills/` encodes the current API surface (mock event factories, test indexer setup, assertion patterns) and the [testing reference docs](https://docs.envio.dev/docs/HyperIndex/testing) cover it end to end.
## What the Stack Looks Like End to End
```text
[Claude Code or Cursor]
|
| (reads docs via MCP server, applies built-in Claude skills)
v
[HyperIndex Project (config.yaml + schema.graphql + handlers)]
|
| (pnpm dev locally, or push to GitHub envio branch)
v
[HyperIndex Runtime + HyperSync]
|
| (live indexes EVM chains natively, any EVM via RPC)
v
[Postgres + Hasura GraphQL endpoint]
|
| (queried by application, dashboard, agent, or downstream service)
v
[Your AI-Powered Onchain App]
```
Each layer is a piece you have full control over. None of them require black-box assumptions about how an indexer behaves under reorgs, source outages, or scale. The [reliability blog](https://docs.envio.dev/blog/production-indexer-reliability-hyperindex) covers what HyperIndex provides at the framework level.
## Get Started
- [HyperIndex Quickstart with AI](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai)
- [Envio docs MCP server](https://docs.envio.dev/docs/HyperIndex/mcp-server)
- [envio-cloud CLI reference](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli)
- [config.yaml reference](https://docs.envio.dev/docs/HyperIndex/configuration-file)
- [Testing docs (V3 framework)](https://docs.envio.dev/docs/HyperIndex/testing)
- [Polymarket production reference](https://github.com/enviodev/polymarket-indexer)
- [Companion: AI-assisted subgraph migration](https://docs.envio.dev/blog/ai-subgraph-migration-hyperindex-claude)
## Frequently Asked Questions
### What does an AI-powered onchain app stack look like?
The stack is: Claude Code (or another MCP-aware editor) as the development surface, a HyperIndex project with an auto-discovered `.claude/skills/` directory shipped by v3 rc, the HyperIndex runtime with [HyperSync](/docs/HyperSync/overview) as the data engine, Postgres plus Hasura for GraphQL, and the application or agent on top. Every layer is real and shipping today.
### How do I deploy a HyperIndex indexer programmatically?
Install the envio-cloud CLI with `npm install -g envio-cloud` and authenticate with `envio-cloud login`. Push the indexer code to a GitHub repo on the `envio` branch, connect the Envio GitHub App to the repo, then register with `envio-cloud indexer add`. Track sync state with `envio-cloud deployment status` and `envio-cloud deployment metrics`. Every command supports `-o json` for parseable output. Full reference at [docs.envio.dev/docs/HyperIndex/envio-cloud-cli](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli).
### Can I add a chain to a HyperIndex indexer without redeploying?
Adding a chain requires a config change and a redeploy because the indexer needs to start a new HyperSync stream. The redeploy itself is one CLI command. Adding a contract on an existing chain that uses the factory pattern can be done dynamically without a redeploy. See the `indexer-factory` skill in the project.
### How does HyperIndex compare to subgraphs for an AI workflow?
Subgraphs use AssemblyScript handlers, single-chain config per subgraph, and matchstick for testing. HyperIndex uses TypeScript handlers, multichain config in one file, and Vitest for testing. The TypeScript surface is what makes Claude's involvement straightforward. The migration story is covered in [AI-assisted subgraph migration](https://docs.envio.dev/blog/ai-subgraph-migration-hyperindex-claude).
### Is HyperIndex faster than other indexers in benchmarks?
In Sentio's independent Uniswap V2 Factory benchmark, HyperIndex completed in 8 seconds, 142x faster than The Graph and 15x faster than the nearest competitor.
### Where can I see a public production reference?
The [Polymarket reference indexer](https://github.com/enviodev/polymarket-indexer). Synced its first 4,000,000,000 events from block 3,764,531 in 6 days, replacing 8 separate subgraphs, and has indexed over 6,500,000,000 to date. Live at [envio.dev/app/moose-code/polymarket-indexer/7cad3ad](https://envio.dev/app/moose-code/polymarket-indexer/7cad3ad).
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.com/invite/gt7yEUZKeB) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# AI-Assisted Subgraph Migration to HyperIndex with Claude
> Migrate a subgraph from The Graph to Envio HyperIndex with Claude doing the AssemblyScript-to-TypeScript rewrite. Real config, real handlers, real repo.
 :::note TL;DR
- HyperIndex is Envio's multichain blockchain indexing framework for EVM chains. It accepts subgraph YAML and ABIs as input, scaffolds a HyperIndex project, and ships a TypeScript handler skeleton that AssemblyScript handler logic can be ported into.
- Claude (running with the Envio docs MCP server and the auto-discovered `.claude/skills/` directory, including the dedicated `migrate-from-subgraph` skill) handles the AssemblyScript-to-TypeScript rewrite end to end. Skills auto-discover for Cursor, Claude Code, and Codex.
- The Polymarket reference indexer is the public production-scale example: 8 subgraphs' worth of logic consolidated into one TypeScript indexer that synced its first 4,000,000,000 events in 6 days on Polygon and has indexed over 6,500,000,000 to date.
:::
The hardest part of migrating off The Graph to HyperIndex has always been the AssemblyScript rewrite. Subgraphs run handler code in WebAssembly, which means handlers are written in AssemblyScript, a stricter subset of TypeScript with its own constraints, its own tooling, and its own foot-guns. Teams who otherwise live in TypeScript every day end up maintaining one codebase in a language they touch only when their indexer breaks.
The HyperIndex reference indexer for Polymarket demonstrates the consolidation pattern at scale, 8 subgraphs' worth of logic rewritten as a single TypeScript indexer. The full reference is public on [GitHub](https://github.com/enviodev/polymarket-indexer) and is documented in our [Polymarket case study](https://docs.envio.dev/blog/polymarket-hyperindex-case-study).
This blog is about how you can leverage Claude (or any coding agent) to migrate your subgraphs to HyperIndex. The agent does the AssemblyScript-to-TypeScript rewrite; a developer reviews the diff, runs the tests, and ships the indexer.
## What HyperIndex Is and Why the Migration Story Changed
HyperIndex is Envio's multichain blockchain indexing framework for EVM chains. HyperIndex handlers are written in regular TypeScript. Unlike AssemblyScript, which restricts which npm packages handlers can use, HyperIndex lets you bring in any npm package you want. Since handlers are TypeScript, there is no WebAssembly compilation step and no AssemblyScript-specific syntax to learn, you write handlers in the language you already use every day.
Two things changed in the last six months that turned subgraph migration into a tractable AI-assisted workflow:
1. The [HyperIndex docs MCP server](https://docs.envio.dev/docs/HyperIndex/mcp-server) went live, exposing the entire docs site as two tools (`docs_search` and `docs_fetch`) over Streamable HTTP at `https://docs.envio.dev/mcp`. Any IDE or assistant that speaks MCP, including Claude Code, Cursor, Codex, and VS Code, can now ground answers about HyperIndex in the live docs rather than stale training data.
2. HyperIndex projects ship a `.claude/skills/` directory that auto-discovers for Cursor, Claude Code, and Codex. The Polymarket reference repo's directory currently ships 14 skills, including a dedicated `migrate-from-subgraph` skill purpose-built for this workflow, plus `indexer-configuration`, `indexer-schema`, `indexer-handlers`, `indexer-factory` (dynamic contracts), `indexer-external-calls` (the Effect API), `indexer-multichain`, `indexer-performance`, `indexer-testing`, `indexer-blocks`, `indexer-filters`, `indexer-traces`, `indexer-transactions`, and `indexer-wildcard`. The full list lives at [the canonical skills directory](https://github.com/enviodev/hyperindex/tree/main/packages/cli/templates/static/shared/.claude/skills).
Combined, these mean a developer can hand the agent a subgraph repo and a working HyperIndex project shell and ask for a migration. The agent has live docs, a project-resident migration skill, and its own validation tooling.
The [Polymarket case study](https://docs.envio.dev/blog/polymarket-hyperindex-case-study) is the production reference for what the end state looks like. The rest of this post walks the AI-assisted version of that same migration on a smaller surface area, anchored to real artifacts in the Polymarket repo.
## The Four Files Claude Needs to See
Every subgraph has the same four primary inputs. Claude reads them in this order.
```text
my-subgraph/
subgraph.yaml # contracts, networks, event handlers, start blocks
schema.graphql # entity types and relations
src/mappings/*.ts # AssemblyScript handler logic (despite the .ts extension)
abis/*.json # contract ABIs the handlers parse logs against
```
`subgraph.yaml` carries the network, the contract addresses, the start blocks, and the event-to-handler mapping. `schema.graphql` carries the entity model. The mappings carry the actual logic. The ABIs carry the signatures for the events mappings parse.
HyperIndex needs the same four kinds of input, restructured. The Polymarket reference shows the target shape. From [the canonical config.yaml](https://github.com/enviodev/polymarket-indexer/blob/main/config.yaml) (selected events shown for brevity):
```yaml
# Source: https://github.com/enviodev/polymarket-indexer/blob/main/config.yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: polymarket-indexer
description: Unified Polymarket HyperIndex
contracts:
- name: Exchange
abi_file_path: ./abis/Exchange.json
events:
- event: "OrderFilled(bytes32 indexed orderHash, address indexed maker, address indexed taker, uint256 makerAssetId, uint256 takerAssetId, uint256 makerAmountFilled, uint256 takerAmountFilled, uint256 fee)"
- event: "OrdersMatched(...)"
- event: "TokenRegistered(...)"
- name: ConditionalTokens
abi_file_path: ./abis/ConditionalTokens.json
events:
- event: "PositionSplit(...)"
- event: "PositionsMerge(...)"
- event: "PayoutRedemption(...)"
field_selection:
transaction_fields:
- hash
- from
- to
chains:
- id: 137 # Polygon
start_block: 3764531
contracts:
- name: Exchange
address:
- "0x4bFb41d5B3570DeFd03C39a9A4D8dE6Bd8B8982E"
- "0xC5d563A36AE78145C45a50134d48A1215220f80a"
start_block: 33605403
- name: ConditionalTokens
address: "0x4D97DCd97eC945f40cF65F87097ACe5EA0476045"
start_block: 4023686
```
Three small differences from subgraph YAML to know up front: HyperIndex uses `chains:` (not `networks:`), declares contracts once at the top level with addresses supplied per-chain, and auto-registers handlers from `src/handlers/
 :::note TL;DR
- HyperIndex is Envio's multichain blockchain indexing framework for EVM chains. Production reliability lives at the framework level, not bolted on per indexer.
- Reorg handling is built in. Entity state history is tracked for every unfinalized block; the framework rolls back automatically when a chain re-orgs. No handler code required.
- The indexer is restart-resistant. State (including dynamically registered contracts) is persisted to the database and restored on reboot. If a handler fails, the framework restarts automatically without data loss, the indexer resumes from the last committed block.
- HyperSync, Envio's default data engine, ships a robust set of data validation features that RPC does not: block parent hash verification, fork detection, automatic re-sync. The indexer can trust that no events are silently missed, in contrast to raw RPC which only serves whatever the upstream node currently considers canonical.
- Multi data-source recovery falls back to a secondary source on primary outage and attempts to recover to the primary 60 seconds later. The indexer stays alive through upstream RPC and HyperSync failures.
- Polymarket's HyperIndex reference indexer synced its first 4,000,000,000 events in 6 days on Polygon and has indexed over 6,500,000,000 to date. Public at [github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer).
:::
A production indexer fails in three ways. The chain reorgs and the indexer either misses the rollback or hand-rolls bespoke logic that breaks at the next edge case. The data source goes down and the indexer either stalls silently or fails over and never comes back to primary. The indexer hits a counter ceiling, a memory leak in a long-running handler, or another silent failure, and the operator finds out from a downstream outage instead of an alert.
HyperIndex is Envio's multichain blockchain indexing framework for EVM chains. Reliability lives at the framework level so that any indexer built on it inherits the behaviour without writing operational code. Four guarantees compound to keep an indexer production-correct: framework-level reorg handling, restart-resistant operation, HyperSync data validation, and multi data-source recovery. Observability through Prometheus layers on top.
## Why These Four Reliability Pillars Reinforce Each Other
Reorg handling guarantees your indexer doesn't carry corrupt state forward when a chain rolls back. Restart-resistant operation means a failed indexer process doesn't leak that corruption into a stuck or amnesiac state. HyperSync validation means the data feeding both is the canonical chain, not a stale or partial fork. Multi-source recovery keeps the whole stack live when upstream sources fail. Each pillar protects the rest.
## Reorg Handling at the Framework Level
The reorg architecture is the deepest piece of work HyperIndex's reliability story rests on. To understand why "framework-level" matters, it helps to be precise about what a reorg actually does to an indexer.
A reorg is a chain rolling back to a previous point in time. A recent block (or several) is no longer canonical, and the new canonical chain has different events at those heights. The implications for an indexer split along a single axis, stateless versus stateful.
Stateless indexers only create entities. On a reorg, the fix is mechanical. Delete the entities written from orphaned blocks, re-ingest from the canonical chain, move on. Stateless indexing parallelises well and is fast.
Stateful indexers also update and delete entities based on previous state. An order book's running volume, an account's balance, a market's open interest, all of these aggregate prior state into current state. On a reorg, you cannot just delete and replay. You have to revert previous operations to the entity state at the pre-reorg point, then replay forward against the canonical chain. Doing that correctly requires tracking the history of every change to every entity for the entire unfinalized window.
HyperIndex's framework keeps that entity history for you.
> "Envio HyperIndex tracks entity state history for all unfinalized blocks. When a reorg is detected, it rolls back entity state to the correct point and reprocesses events from the canonical chain. This happens automatically and does not require any custom rollback logic in your event handlers."
>
> Denham Preen, Envio Co-founder
Learn more in our [Indexing and Reorgs](https://docs.envio.dev/blog/indexing-and-reorgs) blog.
Three architectural details worth knowing about that mechanism:
1. **History is per-entity, not per-block.** The framework persists the prior state of each entity each time a handler writes to it within the unfinalized window. On a reorg, the rollback walks the per-entity history backwards to the pre-reorg state, applies it, and reprocesses forward.
2. **History is pruned automatically.** Once a block is finalised, its entries in the entity history are no longer needed. The framework prunes them. The unfinalized window is the only window that ever carries history overhead, which keeps the storage cost bounded regardless of total chain length.
3. **Multichain reorg handling is harder than single-chain, and the framework does it.** When a single entity's state is updated by events from multiple chains, a reorg on chain A may force the framework to also reprocess events on chain B that were applied after the reorg point but depended on the rolled-back state. The reorg blog calls this out explicitly. Hand-rolling correct multichain reorg logic is the kind of thing you do not want any application engineer to have to write.
### Reorgs in the Wild
These are not theoretical edge cases. From the same reorg blog:
- **Polygon** has frequent and sometimes deep reorgs. The forum has documented a single [157-block reorg at block height 39,599,624](https://forum.polygon.technology/t/157-block-reorg-at-block-height-39599624/11388). Polymarket runs on Polygon. Polymarket's reference indexer at [github.com/enviodev/polymarket-indexer](https://github.com/enviodev/polymarket-indexer) has stayed correct through every Polygon reorg, including the deep ones, because the framework does the work.
- **Ethereum mainnet** sees roughly 1% of blocks affected by reorgs. Assuming a 50/50 chance of a transaction landing in the orphaned versus canonical fork, that's about 1 in 200 transactions ending up in a reorged block. An indexer that does not roll back state is silently wrong for ~0.5% of the transactions it ingests.
- **Base and OP-stack chains** are largely reorg-resistant due to single-slot finality, with [documented exceptions](https://optimistic.etherscan.io/blocks_forked).
Why this matters operationally:
- **No bespoke per-handler logic.** The most common subgraph reliability bug is a handler that does not handle a reorg correctly because the dev forgot to. With HyperIndex that bug class does not exist.
- **No "wait for N confirmations" delay.** Some indexers paper over reorgs by lagging behind the chain head by N blocks. HyperIndex stays at chain head and rolls back if needed.
- **Multichain stays correct.** A multichain indexer with one chain reorging does not corrupt the cross-chain aggregates. The framework rolls back the dependent state on every other chain too.
## Multi Data-Source Recovery
HyperIndex's multi data-source recovery is documented in the [dev update archive](https://docs.envio.dev/blog) and tracked in the [GitHub releases](https://github.com/enviodev/hyperindex/releases).
The feature has three concrete pieces.
### 1. Smarter source selection
Indexers configured with multiple data sources (a primary plus one or more fallbacks) route requests using selection logic that weights source health. A flapping fallback does not win the rotation purely because it answered fastest.
### 2. Automatic failover within seconds
When the primary source goes down, the indexer fails over to a fallback within seconds. When the primary comes back, [HyperIndex attempts to recover to it 60 seconds later](https://docs.envio.dev/docs/HyperIndex/whats-new-in-v3#improved-multiple-data-sources-support). The indexer does not need to be restarted to return to its preferred source.
### 3. Realtime mode enforcement
Realtime mode means the indexer is at chain head and processing new blocks as they arrive. HyperIndex enforces realtime mode strictly: if the indexer's effective progress is stalling on a degraded source, metrics surface it. Operators see the degradation before downstream consumers do.
This pillar is the one operators feel daily. Most indexer outages in 2025 were not chain outages. They were data-source outages that the indexer did not handle gracefully. Multi data-source recovery removes the operator pager from that loop.
## Resumes Cleanly Across Restarts
A production indexer runs for months. The host will restart. Configs will change. The reliability question isn't whether restarts happen, it's what state the indexer is in when they do.
HyperIndex persists indexer state across restarts. On reboot, state is restored from the database, including dynamically registered contracts. The indexer resumes from the last committed block, not from chain head and not from genesis. Application code does not have to track checkpoints or persist offsets, the framework handles it.
Handler-side failures are caught at the framework level too. If a handler throws an unhandled exception, the indexer restarts automatically without data loss. Application code does not have to wrap handlers in try/catch, implement custom retry logic, or rebuild offsets after a crash. The framework does this for you.
The dev environment also preserves data by default. `envio dev` no longer wipes the database on incompatible config or schema changes; the explicit opt-in is `envio dev -r`. For some config changes (RPC configuration is the first to land), the indexer can continue indexing through the change without erroring out at all.
This complements the reorg story. Reorg handling protects against chain-side rollbacks; restart persistence protects against indexer-side restarts. Together they cover the failure surface a production indexer actually faces.
## HyperSync Data Validation
The data feeding the indexer matters as much as the indexer itself. A reorg-aware framework with restart safety is still only as correct as the events that arrive at the handler.
HyperIndex pulls historical data through HyperSync, Envio's data engine. HyperSync ships a robust set of validation features that raw RPC does not, block parent hash verification, fork detection, automatic re-sync on detected forks. The validation runs at ingestion, not in your handler. The framework's confidence is that no events are silently missed by the data layer.
Raw RPC does not give the same guarantee. A standard RPC endpoint will serve whatever the upstream node currently considers canonical, and a slow rotation between forks (or a single RPC sitting on an orphaned tip) can quietly hand stale events to a downstream indexer. With HyperSync as the data layer, that class of silent corruption is removed before any handler sees it.
For application teams: events that reach your handler are canonical-chain events. For AI agents acting on indexer state: the data they reason over is validated upstream, not a best-effort RPC read.
### Why Data Validity Matters for AI
When an agent acts on indexer data, the agent is only as correct as the data it queries. A missing or stale event in a derivative pricing agent, a position tracker, or a governance bot is not a logging error, it's a financial event. The premise of the AI-onchain stack is that the data layer underneath gives the agent verified, canonical state.
HyperIndex's framework-level guarantees (reorg-aware, restart-persistent, parent-hash-validated upstream) are what let an agent treat indexer output as a stable source of truth rather than a feed to second-guess. The [companion blog on agentic blockchain indexing](https://docs.envio.dev/blog/agentic-blockchain-indexing-envio-hyperindex) covers the agent-side story end to end.
## Observability Through Prometheus
HyperIndex exposes a standard Prometheus `/metrics` endpoint with three properties operators rely on.
- **Semver-stable contract.** Metric names and labels do not change between minor versions. Grafana dashboards built against this endpoint do not need to be rebuilt every release.
- **Time units in seconds.** Every duration metric is in seconds, matching Prometheus convention. Histograms use second-based buckets.
- **Benchmark data points in the standard endpoint.** The data points historically surfaced under a separate benchmark mode are part of the standard `/metrics` output. Continuous benchmarking against a production deployment does not require a separate run mode.
For self-hosted deployments, the endpoint plugs into existing Prometheus infrastructure. For Envio Cloud deployments, alerts are exposed through the standard alert channels (Discord, Slack, Telegram, and Email).
## Reliability on Envio Cloud
The four pillars above are framework guarantees: they hold whether you self-host or deploy to [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service), Envio's fully managed hosting. Envio Cloud adds the operational layer on top.
- **Zero-downtime deployments.** Each indexer gets a static production endpoint. A new version deploys alongside the running one; "promote to production" switches the endpoint instantly, and rolling back to a previous deployment is one click. Consumers see no endpoint change.
- **Built-in alerts.** Paid plans surface indexer health, performance warnings, and deployment events through Discord, Slack, Telegram, and Email, so the reorg, failover, and restart events the framework handles stay visible without wiring up your own monitoring.
- **Built-in monitoring.** Logs, per-chain sync status, and deployment health are tracked in real time from the dashboard.
- **Region choice.** Dedicated plans can pick a primary deployment region (USA or EU) for latency and data-residency needs. Broader cross-region support is in active development.
Self-hosting keeps all four framework pillars. Envio Cloud removes the hosting and the on-call wiring on top of them.
## What This Looks Like in a Real Configuration
The Polymarket reference indexer's `config.yaml` is the public production example. The structural pieces below are drawn from [the canonical file](https://github.com/enviodev/polymarket-indexer/blob/main/config.yaml) (selected events shown for brevity):
```yaml
# Source: https://github.com/enviodev/polymarket-indexer/blob/main/config.yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: polymarket-indexer
description: Unified Polymarket HyperIndex
contracts:
# Phase 1A: Fee Module
- name: FeeModule
abi_file_path: ./abis/FeeModule.json
events:
- event: "FeeRefunded(bytes32 indexed orderHash, address indexed to, uint256 id, uint256 refund, uint256 indexed feeCharged)"
# Phase 2B: Orderbook
- name: Exchange
abi_file_path: ./abis/Exchange.json
events:
- event: "OrderFilled(bytes32 indexed orderHash, address indexed maker, address indexed taker, uint256 makerAssetId, uint256 takerAssetId, uint256 makerAmountFilled, uint256 takerAmountFilled, uint256 fee)"
- event: "OrdersMatched(bytes32 indexed takerOrderHash, address indexed takerOrderMaker, uint256 makerAssetId, uint256 takerAssetId, uint256 makerAmountFilled, uint256 takerAmountFilled)"
# Phase 3: Open Interest + Activity
- name: ConditionalTokens
abi_file_path: ./abis/ConditionalTokens.json
events:
- event: "PositionSplit(address indexed stakeholder, address collateralToken, bytes32 indexed parentCollectionId, bytes32 indexed conditionId, uint256[] partition, uint256 amount)"
- event: "PositionsMerge(address indexed stakeholder, address collateralToken, bytes32 indexed parentCollectionId, bytes32 indexed conditionId, uint256[] partition, uint256 amount)"
- event: "PayoutRedemption(address indexed redeemer, address indexed collateralToken, bytes32 indexed parentCollectionId, bytes32 conditionId, uint256[] indexSets, uint256 payout)"
field_selection:
transaction_fields:
- hash
- from
- to
chains:
- id: 137 # Polygon
start_block: 3764531
contracts:
- name: FeeModule
address:
- "0xE3f18aCc55091e2c48d883fc8C8413319d4Ab7b0"
- "0xB768891e3130F6dF18214Ac804d4DB76c2C37730"
start_block: 75253526
- name: Exchange
address:
- "0x4bFb41d5B3570DeFd03C39a9A4D8dE6Bd8B8982E"
- "0xC5d563A36AE78145C45a50134d48A1215220f80a"
start_block: 33605403
- name: ConditionalTokens
address: "0x4D97DCd97eC945f40cF65F87097ACe5EA0476045"
start_block: 4023686
```
Three details worth pointing at in this config:
1. **Two-tier declaration.** The top-level `contracts:` block declares the contract name, ABI, and event signatures globally. The `chains:` block (per chain ID) supplies addresses and per-contract `start_block` overrides. This is how the same contract definition gets reused across multiple deployed addresses (Exchange has two production addresses, FeeModule has two) without duplicating the event signatures.
2. **`field_selection`** controls which transaction fields HyperSync ships down to the handler. Polymarket asks for `hash`, `from`, and `to` only. Smaller per-event payload, faster sync, lower memory pressure. Available on every config.
3. **No reorg block.** There is no `rollback_on_reorg` flag set in the config because rollback is the framework default. The handlers in `src/` do not contain reorg logic. They write entities, the framework manages history, the database stays consistent.
The full file declares 9 V1 contracts (FeeModule, UmaSportsOracle, RelayHub, SafeProxyFactory, USDC, Exchange, ConditionalTokens, NegRiskAdapter, FPMMFactory) plus a dynamic FixedProductMarketMaker registered at runtime, and 5 V2 contracts (CTFExchangeV2, PolyUSD, Rewards, CtfCollateralAdapter, NegRiskCtfCollateralAdapter), all routed through merged handlers in a single multichain-capable config. For a true multichain deployment, the same `chains:` array gets additional entries (e.g., `id: 8453` for Base) with their own contracts block.
## Why Reliability Beats Speed When You Are Picking an Indexer
Speed is the easier comparison and the one most blog posts lead with. Sentio's independent Uniswap V2 Factory benchmark put HyperIndex at 8 seconds, 142x faster than The Graph and 15x faster than the nearest competitor. Polymarket synced 4 billion events in 6 days. Our [agentic indexing blog](https://docs.envio.dev/blog/agentic-blockchain-indexing-envio-hyperindex) covers a 400,000-event Monad indexer in roughly 20 seconds.
Reliability is the one that decides whether an indexer stays running for years. The four pillars above (framework reorg handling, restart-resistant operation, HyperSync data validation, and multi data-source recovery) are what separate a production indexer from a benchmark.
Two operational consequences for teams choosing HyperIndex over alternatives:
- **One on-call surface, not three.** The framework handles reorgs, source failover, restart recovery, and observability. The on-call person reads the Prometheus dashboard and the Envio Cloud alerts. They do not also have to maintain custom reorg or checkpoint code.
- **Source diversity without operator overhead.** Adding a fallback source is a config change. Multi data-source recovery does the runtime work. The operator does not author retry policies.
## Get Started
- [What's new in v3](https://docs.envio.dev/docs/HyperIndex/whats-new-in-v3)
- [HyperIndex quickstart](https://docs.envio.dev/docs/HyperIndex/getting-started)
- [Quickstart with AI](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai)
- [Benchmarks](https://docs.envio.dev/docs/HyperIndex/benchmarks)
- [Reorg handling reference](https://docs.envio.dev/blog/indexing-and-reorgs)
- [Polymarket reference indexer](https://github.com/enviodev/polymarket-indexer)
- [Envio Cloud (alerts, hosted reliability)](https://docs.envio.dev/docs/HyperIndex/hosted-service)
## Frequently Asked Questions
### How does Envio HyperIndex handle blockchain reorgs?
HyperIndex tracks entity state history for every unfinalized block at the framework level. When a reorg occurs, the framework walks the per-entity history backwards to the pre-reorg state, applies it, then reprocesses forward against the canonical chain. History is pruned automatically once a block is finalised. No handler code is required.
### How does HyperSync guarantee canonical chain data?
HyperSync ships a robust set of validation features that raw RPC does not, block parent hash verification, fork detection, automatic re-sync on detected forks. The indexer can trust that no events are silently missed by the data layer. The validation runs at ingestion, not in your handler. Raw RPC endpoints serve whatever the upstream node currently considers canonical, which is why a standard RPC-fed indexer can silently ingest stale or orphaned data from a slow-rotating provider.
### How often do reorgs actually happen?
On Ethereum mainnet, roughly 1% of blocks undergo reorgs, meaning approximately 1 in 200 transactions ends up in a reorged block. Polygon experiences deeper reorgs more frequently and has documented a single 157-block reorg at block height 39,599,624. Base and OP-stack chains are largely reorg-resistant due to single-slot finality, with documented exceptions.
### What is multi data-source recovery in HyperIndex?
Multi data-source recovery automatically routes between configured data sources. On primary outage, the indexer fails over to a fallback within seconds. When the primary returns, the indexer attempts to recover to it 60 seconds later, no restart required. Selection logic weights source health, not just first-response. Realtime mode enforcement surfaces through metrics when forward progress slows on a degraded source.
### What happens to the indexer when the process restarts or a handler fails?
HyperIndex is restart-resistant. State persists to the database; on restart, the indexer restores state (including dynamically registered contracts) and resumes from the last committed block. If a handler fails mid-execution, the framework restarts automatically without data loss. Application code does not have to track checkpoints, persist offsets, or wrap handlers in retry logic.
### Is the HyperIndex Prometheus metrics endpoint production-ready?
Yes. The `/metrics` endpoint follows semver, uses second-based time units, and exposes the benchmark data points historically surfaced under a separate run mode as part of the standard endpoint.
### Where can I see the production-scale HyperIndex reference?
The [Polymarket reference indexer](https://github.com/enviodev/polymarket-indexer). It synced 4,000,000,000 events from block 3,764,531 on Polygon Mainnet in 6 days, replacing 8 separate subgraphs.
### What alert channels does Envio Cloud support?
Envio Cloud alerts route through the platform's alert channels documented in the [hosted service docs](https://docs.envio.dev/docs/HyperIndex/hosted-service).
### Does HyperIndex stay at chain head or lag for safety?
HyperIndex stays at chain head. Reorgs are handled by rollback, not by lag. There is no "wait N confirmations" mode required for correctness.
## Build With Envio
Envio is the fastest independently benchmarked EVM blockchain indexer for querying real-time and historical data. If you are building onchain and need indexing that keeps up with your chain, check out the [docs](https://docs.envio.dev/docs/HyperIndex/overview), run the benchmarks yourself, and come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.com/invite/gt7yEUZKeB) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Migrate from Ponder to Envio HyperIndex
> Migrate from Ponder to HyperIndex in three steps. Up to 157x faster sync. Same TypeScript, multichain by default. Real before-and-after code.
 :::note TL;DR
- Migrating from Ponder to HyperIndex is straightforward. Both frameworks use TypeScript, index EVM events, and expose a GraphQL API.
- Three things change: `ponder.config.ts` becomes `config.yaml`, `ponder.schema.ts` becomes `schema.graphql`, and event handlers adapt to the HyperIndex entity API.
- Up to 157x faster historical sync via HyperSync (Sentio Uniswap V2 Factory benchmark).
- Multichain by default. One config, any number of chains.
- Full migration reference at [docs.envio.dev/docs/HyperIndex/migrate-from-ponder](https://docs.envio.dev/docs/HyperIndex/migrate-from-ponder). AI-assisted migration docs also available for Cursor and Claude Code.
:::
If you are running a Ponder indexer in production, you already know two things. The framework is TypeScript end-to-end, and historical backfills using RPC are the bottleneck. Envio HyperIndex keeps the TypeScript and removes the bottleneck. Up to 157x faster sync via HyperSync, same GraphQL API on top.
This blog walks the three-step migration end to end. Every code block is taken directly from the official migration reference in our docs.
## AI-Assisted Migration
If you prefer not to do the rewrite by hand, HyperIndex ships with built-in Claude skills that guide AI coding assistants through the migration. See our [Quickstart with AI](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai) guide that walks you through the full setup.
Combined with the Envio docs [MCP server](https://docs.envio.dev/docs/HyperIndex/mcp-server), an agent can read your Ponder config, schema, and handlers, and produce the HyperIndex equivalents while you review the diff. Learn more about general AI-assisted migration in our [blog](https://docs.envio.dev/blog). The same flow applies to Ponder migration.
## Migration Overview
Three steps plus a bootstrap:
1. `ponder.config.ts` becomes `config.yaml`
2. `ponder.schema.ts` becomes `schema.graphql`
3. Event handlers adapt syntax and entity operations
At any point during the migration, run:
```bash
pnpm envio codegen # validate config + schema, regenerate types
pnpm dev # run the indexer locally
```
If you are new to HyperIndex, see the [Getting Started](https://docs.envio.dev/docs/HyperIndex/getting-started) guide.
## Step 0: Bootstrap the Project
```bash
pnpx envio init
```
Follow the prompts, using your Ponder project as the source of truth for contract addresses, ABIs, and events. This generates a boilerplate indexer you can use as a base to edit.
Convert your ABIs first. Ponder exports ABIs as TypeScript (`as const`). For each contract, strip the `export const ... =` wrapper and the `as const`, and save it as a plain `.json` file in `abis/`. Have these ready before running `envio init`, because the local ABI import asks for the path to each contract's JSON ABI file. If a contract is verified on a block explorer, `envio init` can fetch the ABI for you instead.
## Step 1: `ponder.config.ts` to `config.yaml`
Here is the same indexer configured in both frameworks, taken from the migration docs.
**Ponder:**
```ts
import { createConfig } from "ponder";
export default createConfig({
chains: {
mainnet: { id: 1, rpc: process.env.PONDER_RPC_URL_1 },
},
contracts: {
MyToken: {
abi: myTokenAbi,
chain: "mainnet",
address: "0xabc...",
startBlock: 18000000,
},
},
});
```
**HyperIndex:**
```yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: my-indexer
contracts:
- name: MyToken
abi_file_path: ./abis/MyToken.json
events:
- event: Transfer
- event: Approval
chains:
- id: 1
start_block: 0
contracts:
- name: MyToken
address:
- 0xabc...
start_block: 18000000
```
**Key differences:**
| Concept | Ponder | HyperIndex |
| --- | --- | --- |
| Config format | `ponder.config.ts` (TypeScript) | `config.yaml` (YAML) |
| Chain reference | Named + viem object | Numeric chain ID |
| RPC URL | In config | `ENVIO_RPC_URL_
 :::note TL;DR
- Katana migrated two production subgraphs, SushiSwap V3 and the Sushi staker, from The Graph to Envio HyperIndex while keeping its existing data model intact.
- Katana's existing subgraph-style queries ran against Envio's subgraph-compatible endpoint, and for the full GraphQL feature set its app needed, Katana moved its queries onto Envio's native endpoint. The data model itself carried over unchanged.
- Katana forked the indexer and deployed it on Envio Cloud, and the Envio team assisted with the backend configuration, the subgraph-compatible endpoint, and the cache.
:::
Migrating your data infrastructure from one provider to another is rarely simple, mostly because of everything that has to change around it. Katana is a DeFi network, and its app surfaces SushiSwap data such as V3 pools, swaps, fees, positions, and staking to its users. That data was served by two production subgraphs running on The Graph. Katana wanted to move this data layer to Envio HyperIndex without disrupting the apps that depend on it.
Because this was a live production system rather than a greenfield build, the priority was continuity. The existing queries had to keep working and the data had to stay correct. This case study walks through how the migration came together, from the subgraph-compatible endpoint that kept Katana's queries running to the hands-on support that handled the rest.
## The Challenge: Moving a Production Data Layer Without Disrupting It
Katana's existing subgraph queries were wired into production and had to keep working. Data quality and expected behaviour had to be preserved. And it had to be efficient, a swap, not a multi-week infrastructure project. For DeFi data, correctness and uptime were non-negotiable, because their application and users depended on it.
During development, the team also noticed the existing subgraph data often running around three blocks behind the chain head. For user-facing DeFi data, that kind of freshness gap matters.
## The Solution: A Subgraph-Compatible Path off The Graph
The migration came down to two things. Envio's tooling fit the setup Katana already had, and the support was there at every step.
The foundation was schema parity. The HyperIndex deployment reproduces the original Sushi V3 subgraph entity-for-entity, all 23 entity types, tracking the Uniswap V3 factory, the position manager, and every pool it deploys. Same entities, same shape, so Katana did not have to redesign its data or rebuild against a new model.
Envio exposes two GraphQL endpoints, a subgraph-compatible one that runs existing subgraph-style queries as a drop-in, and a native one with the full query feature set. Katana's standard queries ran against the compatible endpoint, and for the full feature set its app needed, Katana standardised on the native endpoint, with the Envio team working through the move alongside them.
### Contracts Indexed
The SushiSwap V3 indexer runs on Katana mainnet:
| Contract | Address | Start block |
|----------|---------|-------------|
| UniswapV3Factory | `0x203e8740894c8955cb8950759876d7e7e45e04c1` | 1,858,972 |
| NonfungiblePositionManager | `0x2659c6085d26144117d904c46b48b6d180393d27` | 1,860,127 |
| UniswapV3Pool | Dynamic, registered by the factory | When each pool is deployed |
The process was a fork-and-deploy flow. Katana forked the indexer, connected it to Envio Cloud, and deployed, while the Envio team handled the backend configuration, set up the subgraph-compatible endpoint, and managed the caching for the deployment. The team could also validate on a fast instance first. With the most RPC-heavy fields turned off, backfill ran about ten times faster, so they could confirm everything looked right before running the full indexer with every field populated.
The Envio team set up the endpoints, configured the caching, and worked through the query migration directly with Katana's engineers.
## The Results
Katana migrated both production subgraphs, SushiSwap V3 and the Sushi staker, from The Graph to Envio. Its existing queries kept working through the subgraph-compatible endpoint, so the app did not need a rewrite. A third subgraph, a pre-staking one with deprecation already planned, was left as-is by design.
*The SushiSwap V3 indexer on Envio, fully synced (11,473,382 events) in about two hours.*
 *The Sushi staker subgraph, fully synced (68,201 events) in under 20 seconds on Envio.*
 With the migration complete, both SushiSwap indexers run on Envio Cloud, serving Katana's app through the same queries it used before. Where the original subgraph had drifted a few blocks behind, the new indexer indexes in real time at the chain head.
"The comprehensive resources and proactive support provided by the Envio team made our migration from The Graph remarkably smooth and efficient."
Kirienzo, Senior Software Engineer, Katana
 May was our biggest month yet. After five months of alpha and release candidates, HyperIndex V3 officially shipped, production-ready, faster, and the foundation for everything we build next. Alongside it we went live on Katana, published four large-scale case studies (Polymarket, Revert Finance, Privacy Pools, and Katana's SushiSwap migration off The Graph), and shipped a stack of deep-dive guides on HyperSync, production reliability, and building onchain with AI.
We also joined Monad's Devrel livestream to talk HyperIndex, started rolling out HyperSync rate limits ahead of paid plans, and confirmed our ETHConf New York sponsorship in June.
Let's dive in!
## HyperIndex V3 Is Here
 After five months of alpha, HyperIndex V3 officially shipped. This is the biggest release in the framework's history, a full modernisation that bundles five months of work into a stable, production-ready release. A unified handlers API, ESM with top-level await, a purpose-built testing framework, 3x faster historical sync, Solana support, ClickHouse as a second storage backend, and a much smaller package. With V3 we are back to following SemVer and set up for the next year of features.
To upgrade an existing project, follow the [Migrate to V3](https://docs.envio.dev/docs/HyperIndex/migrate-to-v3) guide. For the complete rundown, see [What's New in V3](https://docs.envio.dev/docs/HyperIndex/whats-new-in-v3).
### Unified Handlers API
All handler registrations now flow through a single indexer value. Contract-specific exports are replaced by `indexer.onEvent`, `indexer.contractRegister`, and `indexer.onBlock`.
```typescript
import { indexer } from "envio";
indexer.onEvent(
{
contract: "ERC20",
event: "Transfer",
wildcard: true,
where: ({ chain }) => ({
params: [
{ from: chain.Safe.addresses },
{ to: chain.Safe.addresses },
],
}),
},
async ({ event, context }) => {
// Handler logic
},
);
```
### 3x Faster Historical Backfill
We added chunking logic to request events across multiple ranges at once, removed overfetching for contracts with a much later start block, and sped up dynamic contract registration.
**25k events per second is now standard.**
### A Purpose-Built Testing Framework
HyperIndex now ships its own testing framework powered by `createTestIndexer()`. You write tests against the same indexer that runs in production, with no database, no Docker, and no manual mock wiring. It integrates with Vitest, includes snapshot testing out of the box, and gives you three ways to feed events (auto-exit, explicit block range, or simulate).
```typescript
import { describe, it } from "vitest";
import { createTestIndexer } from "envio";
describe("ERC20 indexer", () => {
it("processes the first block with events", async (t) => {
const indexer = createTestIndexer();
const result = await indexer.process({ chains: { 1: {} } });
// Auto-filled by Vitest on first run -- just review and commit
t.expect(result).toMatchInlineSnapshot(`
{
"changes": [
{
"Transfer": {
"sets": [
{
"blockNumber": 10861674,
"from": "0x0000000000000000000000000000000000000000",
"id": "1-10861674-23",
"to": "0x41653c7d61609D856f29355E404F310Ec4142Cfb",
"transactionHash": "0x4b37d2f343608457ca...",
"value": 1000000000000000000000000000n,
},
],
},
"block": 10861674,
"chainId": 1,
"eventsProcessed": 1,
},
],
}
`);
});
});
```
### ESM and Top-Level Await
We migrated HyperIndex from CommonJS to ESM. That unlocks the latest versions of libraries that dropped CommonJS long ago, and lets you use `await` directly at the top of your handler files.
### Solana Support (Experimental)
HyperIndex now supports Solana with RPC as a source. Spin up a Solana project with `pnpx envio init svm`. Solana exposes its block-stream handler as `indexer.onSlot` rather than `onBlock`, matching Solana's slot-based model.
### ClickHouse as an Additional Storage Backend (Experimental)
HyperIndex can now run with multiple storage backends side by side. Postgres remains the primary database, and entities can additionally be written to a ClickHouse database that is restart and reorg resistant. Enable it in `config.yaml` and route each entity via the `@storage` directive in `schema.graphql`.
```yaml
storage:
postgres: true
clickhouse: true
```
Envio Cloud supports ClickHouse on the Dedicated Plan.
### A Much Smaller Package and Bun Support
You can run HyperIndex on Bun with `bun --bun envio dev`, and we removed the runtime ReScript compiler from the published package by eliminating dynamically generated ReScript code.
**The envio npm package shrank from 141MB to 53MB.**
### Agentic Mode in envio init
`envio init` now ships an agentic mode. When an AI coding assistant runs the command, it produces an AI-readable guiding prompt instead of a TTY error, so the agent knows exactly how to scaffold an indexer end to end.
```
Welcome to Envio Indexer! Let's set up an indexer that will become a reliable blockchain backend you trust, love, and own.
Leave the rest to your favorite agent:
1. Prompt the user for the project intent if it is missing from context (what should the indexer track and surface?).
2. Determine the chain, contract, and addresses needed to produce that result. Use web search or block-explorer tool calls when the user hasn't supplied them.
3. To continue, call:
pnpx envio init contract-import explorer \
-n ${indexer-name} \
-c ${address} \
-b ${chainId} \
--single-contract \
--all-events \
-d ${directory}
Then `cd ${directory}` and run `pnpm test`. Don't hand the project off yet -- keep iterating on the indexer with a TDD loop (extend tests, run them, fix handlers) until the user's goal is met.
```
See the full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex) ⭐
## Envio is Live on Katana
 We launched production-grade indexing on Katana, the DeFi-first chain built where liquidity concentrates and real yield flows back to users. Developers can now access real-time and historical onchain data on Katana, up to 2000x faster than RPC.
Easy, fast, and fully customisable.
Original post on X: [https://x.com/katana/status/2056389958303441051](https://x.com/katana/status/2056389958303441051)
## Indexing 4 Billion Polymarket Events
 We replaced Polymarket's eight production subgraphs, four years of fragmentation across separate AssemblyScript codebases on The Graph, with a single HyperIndex indexer written in TypeScript. Over 4 billion events synced in 6 days on Polygon.
The unlock is handler merging. A shared contract event like `ConditionalTokens.PositionSplit` previously fired across three or four separate subgraphs. In the unified indexer, one handler fires once and updates open interest, activity, and PnL together. That is 25+ entity types behind a single GraphQL endpoint, and one deployment to maintain instead of eight. The full indexer is open source as a reference for any team migrating from The Graph.
Read the case study: [https://docs.envio.dev/blog/polymarket-hyperindex-case-study](https://docs.envio.dev/blog/polymarket-hyperindex-case-study)
## Revert Finance Fixed 2 Years of Unsynced PancakeSwap V3 Data
 Revert Finance builds analytics and management tools for AMM liquidity providers. Their PancakeSwap V3 subgraph on BNB Smart Chain had been stuck at 70% sync for over two years, unable to reach chain head, because the chain's throughput outpaced what RPC-based indexing could sustain.
We built a HyperIndex indexer covering the full PancakeSwap V3 contract surface on BNB Smart Chain. 1,711,569,200 events synced to 100% in 10 days.
Read the case study: [https://docs.envio.dev/blog/revert-finance-pancakeswap-bnb-hyperindex](https://docs.envio.dev/blog/revert-finance-pancakeswap-bnb-hyperindex)
## Privacy in Public, Indexing Privacy Pools
 Privacy Pools is a privacy primitive co-authored by Vitalik Buterin that pairs a zero-knowledge proof of pool membership with an off-chain compliance layer. We indexed every deposit, withdrawal, ragequit, ASP root update, and relayer fee across all 21 live pools on four chains (Ethereum, Optimism, BSC, and Arbitrum) with a single HyperIndex indexer using dual Postgres and ClickHouse storage.
Full multichain sync to head in roughly 30 seconds, and 91% of withdrawals use the privacy-preserving relayed path. The full stack, including the indexer, the analytics queries, and the BI report generator, is open source under MIT license. It is a great example of multichain coverage and an analytics-grade columnar store as first-class features.
Read the case study: [https://docs.envio.dev/blog/privacy-in-public-case-study](https://docs.envio.dev/blog/privacy-in-public-case-study)
## Katana Migrates SushiSwap Off The Graph
 Katana migrated two production subgraphs, SushiSwap V3 and the Sushi staker, from The Graph to Envio HyperIndex without disrupting the app surfacing the data. Katana's existing subgraph-style queries kept working through Envio's subgraph-compatible endpoint, and for the full GraphQL feature set its app needed, Katana moved onto Envio's native endpoint, with our team supporting the move directly.
SushiSwap V3 synced 11,473,382 events in about two hours, and the Sushi staker synced 68,201 events in under 20 seconds.
Read the case study: [https://docs.envio.dev/blog/case-study-katana-sushiswap](https://docs.envio.dev/blog/case-study-katana-sushiswap)
## What is HyperSync?
 Reading onchain data over standard JSON-RPC breaks down the moment you need fast, filtered, or multichain historical data. HyperSync is our high-performance data retrieval layer built to fix exactly that. It is written in Rust, uses optimised binary encoding and parallel fetching, and exposes a single query interface across every supported chain.
Scanning Arbitrum for sparse log data takes 2 seconds with HyperSync, up to 2000x faster than RPC. HyperSync is the engine behind HyperIndex. Client libraries are available for TypeScript, Python, Rust, and Go. This blog covers what it is, how it works, and how to use it in your own application.
Learn more here: [https://docs.envio.dev/blog/what-is-hypersync](https://docs.envio.dev/blog/what-is-hypersync)
## Production Indexer Reliability with HyperIndex
 Speed wins benchmarks, but reliability is what keeps an indexer running for years. This post walks through the four reliability guarantees HyperIndex provides at the framework level, so any indexer built on it inherits them without writing operational code. Those guarantees are built-in reorg handling with automatic rollback, restart-resistant operation, HyperSync data validation, and multi data-source recovery.
Reorgs are handled automatically by tracking entity state history for every unfinalized block and rolling back without any custom handler logic. Multi data-source recovery fails over to a fallback within seconds and recovers to the primary 60 seconds later. Observability comes through a semver-stable Prometheus endpoint.
More here: [https://docs.envio.dev/blog/production-indexer-reliability-hyperindex](https://docs.envio.dev/blog/production-indexer-reliability-hyperindex)
## Why AI Agents Acting Onchain Need an Indexer
 SQL warehouses let agents ask. Indexers let them act. An agent reading raw RPC hits four walls quickly, namely reorgs, no schema, low throughput, and per-chain quirks at multichain scale. A SQL warehouse fronted by an LLM solves the read side, but an agent acting onchain needs to build, deploy, and own new data pipelines mid-session, not just query existing ones.
This post makes the case for a programmable indexer over a query layer, backed by the docs MCP server, the auto-discovered `.claude/skills/` directory, and the GitHub-native deploy flow.
**One prompt, roughly 20 seconds, 400,000 events indexed on Monad.**
Read the full breakdown: [https://docs.envio.dev/blog/ai-agents-acting-onchain-indexer](https://docs.envio.dev/blog/ai-agents-acting-onchain-indexer)
## AI-Assisted Subgraph Migration to HyperIndex with Claude
 The hardest part of moving off The Graph has always been the AssemblyScript rewrite. With the docs MCP server and the dedicated migrate-from-subgraph skill shipped in every HyperIndex project, Claude can handle the AssemblyScript-to-TypeScript translation end to end while a developer reviews the diff, runs the tests, and ships the indexer.
This guide walks the full workflow on a real surface area, anchored to the open-source Polymarket reference. A migration that used to take weeks becomes a one or two day exercise.
Read the full tutorial: [https://docs.envio.dev/blog/ai-subgraph-migration-hyperindex-claude](https://docs.envio.dev/blog/ai-subgraph-migration-hyperindex-claude)
## Build an AI-Powered Onchain App with HyperIndex and Claude
 A practical, end-to-end walkthrough of building a multichain HyperIndex indexer with Claude as a pair programmer. It covers wiring up the docs MCP server, scaffolding the project, making it multichain, writing the schema and handlers, running locally, and deploying to Envio Cloud through the GitHub-native flow.
Every command is reproducible against the current release, and the patterns come straight from the public Polymarket reference indexer. With Claude driving, you can go from a blank project to a deployed, queryable indexer in minutes.
More here: [https://docs.envio.dev/blog/ai-onchain-app-hyperindex-claude](https://docs.envio.dev/blog/ai-onchain-app-hyperindex-claude)
## Migrating from Ponder to Envio
 Both Ponder and HyperIndex are TypeScript-first and expose a GraphQL API, so migration is mostly mechanical translation. Three things change. `ponder.config.ts` becomes `config.yaml`, `ponder.schema.ts` becomes `schema.graphql`, and event handlers adapt to the HyperIndex entity API. This guide walks all three steps end to end, with every code block taken from the official migration reference.
Up to 157x faster historical sync via HyperSync, with multichain support by default.
For teams looking for a clear path forward, our team supports the migration end to end, from planning the rewrite to getting the indexer live on Envio Cloud.
Read the full tutorial: [https://docs.envio.dev/blog/migrate-from-ponder-to-envio](https://docs.envio.dev/blog/migrate-from-ponder-to-envio)
## HyperSync Rate Limits
Throughout May we have been rolling out HyperSync rate limits more aggressively. Limits ratchet down gradually so you get the smoothest possible transition to paid plans without disruption to your services. Keep an eye out for 429 rate limit exceeded errors.
If you are already on a paid HyperSync plan, your normal plan limits apply and no action is needed. If you are not on a paid plan yet, get sorted as soon as possible by opening a Discord ticket to arrange one with the team, or by picking a plan directly.
This affects all HyperSync users and anyone self-hosting HyperIndex with a HyperSync token. Envio Cloud deployments are not affected.
## Polymarket's Top Traders Run on Indexed Data
 Co-founder Jonjon Clark published a data-driven series profiling the top 100 Polymarket traders by realised PnL, and the deeper he digs, the clearer it becomes that these operations live or die on fast, real-time access to onchain data, exactly the workload HyperIndex and HyperSync are built for. Here are a few that stand out.
### The 95% Win Rate Trader
$23.6M in realised PnL and a 95.4% win rate. It runs a live NBA model that prices games faster than the order book, pre-positions on the cheap side before tip-off, and rides the eventual winner to oracle redemption.
[Read the thread](https://x.com/jonjonclark)
### The 15-Minute Bitcoin Loop Trader
 7.6 million fills across 32,021 markets in 111 days, about one fill per second, netting $2.38M. It posts resting bids on both sides of Polymarket's 15-minute BTC binaries and captures the spread off retail flow, completely indifferent to which way Bitcoin moves.
[Read the thread](https://x.com/jonjonclark)
### The UMA Gap Trader
 Number 26 on the leaderboard with $8M in lifetime realised PnL. Its cleanest mechanism is the settlement sweep, buying near-par winning tokens in the gap between when a result is known and when the UMA oracle finalises payout, for a 98.2% win rate across more than 4,000 positions.
[Read the thread](https://x.com/jonjonclark)
## Envio x Monad's Devrel Livestream
[
 ](https://x.com/i/broadcasts/1qxvvkjpedaxB)
Co-founder Denham joined Monad's Devrel Livestream to chat HyperIndex on Monad, Monskills, and how to vibecode your way to a production indexer.
Missed it live? Catch the full recording on [X](https://x.com/i/broadcasts/1qxvvkjpedaxB).
## Current & Upcoming Events & Hackathons
* [ETHConf - New York](https://ethconf.com/): June 8th -> 10th (sponsoring)
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/3XgXvqbIgrCTLzxqJRehxC?si=5d1949361dfb49a4)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you're working on a Web3 project and want a smoother development process, Envio's got your back(end). Check out our docs, join the community, and let's talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Index Sei Smart Contract Data in Minutes using Envio
> A step-by-step guide to indexing a Sei ERC20 contract with Envio HyperIndex. Build a local indexer that streams Sei USDC Transfer and Approval events into Postgres and serves them through a GraphQL API.
 :::note TL;DR
- Scaffold the ERC20 template with `pnpx envio init template -t erc20 -d ./sei-indexer`
- Point `config.yaml` at Sei mainnet (chain ID `1329`, start block `79123881`) and USDC at `0xe15fC38F6D8c56aF07bbCBe3BAf5708A2Bf42392`
- Define an `Account` and `Approval` schema, write `Transfer` and `Approval` handlers in `src/handlers/MyContract.ts`
- Run `pnpm codegen`, then `pnpm dev`, and query live Sei USDC data at `http://localhost:8080/v1/graphql`
:::
This guide walks you through building a HyperIndex indexer for a smart contract on Sei. By the end, you will have a local indexer that streams Sei blockchain data into a Postgres database and serves it through a GraphQL API.
## What you will build
An indexer for USDC on Sei mainnet (Circle's native USDC). It tracks `Transfer` and `Approval` events, keeps a running token balance per account, and records every approval.
Target contract:
- Chain: Sei mainnet, chain ID `1329`
- Contract address: `0xe15fC38F6D8c56aF07bbCBe3BAf5708A2Bf42392`
- Explorer: [seitrace.com](https://seitrace.com/address/0xe15fC38F6D8c56aF07bbCBe3BAf5708A2Bf42392)
Indexing testnet instead? See the [Indexing on Sei testnet](#indexing-on-sei-testnet) section at the bottom of this guide for the testnet config changes.
## Steps at a glance
1. Scaffold the indexer
2. Configure the indexer for Sei
3. Define the data schema
4. Write the event handler
5. Generate types
6. Run the indexer
7. Query your data
8. Stop the indexer
## Before you begin
Make sure you have the following prerequisites installed. Run each check in a terminal:
- Node.js v22 or later. Check with `node -v`.
- pnpm v8 or later. Check with `pnpm -v`.
- Docker installed and running. Check with `docker ps`.
- A free Envio API token. HyperIndex requires an API token to use HyperSync as a data source. Create one at [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens).
## Step 1: Scaffold the indexer
Create a new HyperIndex project from the ERC20 template, then move into the project folder:
```bash
pnpx envio init template -t erc20 -d ./sei-indexer
cd sei-indexer
```
During the init flow you'll be prompted for an Envio API token. Paste an existing one or follow the prompt to create a new one at [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens). The CLI writes it to `.env` for you.
A new `sei-indexer` folder is created with `config.yaml`, `schema.graphql`, a `.env` file, and a `src/handlers/` directory. Every file in `src/handlers/` is registered automatically, so there is no central `EventHandlers.ts` file. Generated types are written to the `.envio/` directory.
## Step 2: Configure the indexer for Sei
Replace the contents of `config.yaml` with the configuration below. This points the indexer at Sei mainnet and the USDC contract, and selects the two events to index:
```yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: sei-indexer
description: Sei ERC20 indexer
contracts:
- name: MyContract
events:
- event: Transfer(address indexed from, address indexed to, uint256 value)
- event: Approval(address indexed owner, address indexed spender, uint256 value)
chains:
- id: 1329 # Sei mainnet (pacific-1)
start_block: 79123881
contracts:
- name: MyContract
address:
- "0xe15fC38F6D8c56aF07bbCBe3BAf5708A2Bf42392"
```
Important: `start_block: 79123881` is the first EVM block on Sei mainnet. Earlier blocks are non-EVM and have no Solidity events to index. Setting it to `0` will waste time scanning blocks that can never match. Sei is a supported HyperSync network, so the endpoint resolves automatically from the chain ID. No `hypersync_config` block is needed.
## Step 3: Define the data schema
Replace the contents of `schema.graphql` with the schema below. Each type becomes a database table and a GraphQL query:
```graphql
type Account {
id: ID!
balance: BigInt!
approvals: [Approval!]! @derivedFrom(field: "owner")
}
type Approval {
id: ID!
owner: Account!
spender: String!
value: BigInt!
blockNumber: BigInt!
timestamp: BigInt!
}
```
The `@derivedFrom` directive creates a virtual reverse lookup, so each `Account` exposes its list of approvals without you storing that list explicitly.
## Step 4: Write the event handler
The ERC20 template ships a handler and a test file that both reference the template contract. Remove them first:
```bash
rm -f src/handlers/ERC20.ts src/indexer.test.ts
```
Note: Removing `src/indexer.test.ts` matters. It imports the deleted ERC20 handler, so leaving it in place breaks `pnpm test`.
Now create a new handler file at `src/handlers/MyContract.ts` with the following content:
```typescript
import { indexer } from "envio";
indexer.onEvent(
{ contract: "MyContract", event: "Transfer" },
async ({ event, context }) => {
const { from, to, value } = event.params;
const sender = await context.Account.get(from);
context.Account.set({
id: from,
balance: (sender?.balance ?? 0n) - value,
});
const receiver = await context.Account.get(to);
context.Account.set({
id: to,
balance: (receiver?.balance ?? 0n) + value,
});
},
);
indexer.onEvent(
{ contract: "MyContract", event: "Approval" },
async ({ event, context }) => {
const { owner, spender, value } = event.params;
const existing = await context.Account.get(owner);
context.Account.set({
id: owner,
balance: existing?.balance ?? 0n,
});
context.Approval.set({
id: `${event.block.hash}-${event.logIndex}`,
owner_id: owner,
spender,
value,
blockNumber: BigInt(event.block.number),
timestamp: BigInt(event.block.timestamp),
});
},
);
```
Key points about the handler API:
- Handlers are registered with `indexer.onEvent`, imported from the `envio` package.
- Linked entities are set with the `
 Just-in-time indexing is a way of using an AI agent to answer one-off questions about onchain data without maintaining permanent infrastructure or finding a pre-indexed data point. Rather than building an indexer in advance and keeping it running, the dataset is built on demand when a question comes up, read once, and deleted afterward.
## How it Works
One user, Michael K from Curve Finance, uses it for ad hoc analysis of pool activity. The flow starts with a plain-language prompt to Claude, for example: "Use Envio to parse all the trades from this pool."
Claude, using Envio's tooling, generates the indexer: the config, schema, and event handlers, scoped to the specific contract and events in the question. It deploys to Envio's free development plan cloud service with `envio-cloud`, the CLI, and the indexer backfills from scratch. After 5 to 10 minutes, the data is ready to query. Once the researcher has pulled what they need, they delete the indexer.
"One of the simplest ways to get large datasets of onchain data for our research purposes."
Michael K, Researcher at Curve Finance
"We use Envio regularly to parse all kinds of data from all kinds of contracts across dozens of chains."
Michael K, Researcher at Curve Finance
 :::note TL;DR
- Migrating from The Graph to HyperIndex is not an AssemblyScript rewrite. AssemblyScript is a subset of TypeScript, so your event parsing and business logic copy across verbatim.
- Three things change in a well-defined way. `subgraph.yaml` becomes `config.yaml`, your schema sheds the `@entity` decorator, and handlers swap `Entity.save()` for `context.Entity.set()` with async/await.
- HyperIndex supports multichain in a single config, full TypeScript with any npm package, and framework-level reorg handling with no handler code required.
- In the Sentio Uniswap V2 Factory benchmark (April 2025), HyperIndex completed in 8 seconds. The Graph took 19 minutes, 142x slower on the same workload.
- The Indexer Migration Validator CLI diffs entity state between your subgraph endpoint and your HyperIndex endpoint before you cut over.
:::
Most teams stay on The Graph longer than they want to because of one belief, that moving means rewriting every handler in a new language. It does not.
AssemblyScript is a subset of TypeScript. The event parsing, the conditional logic, the arithmetic, and the helper functions are all valid TypeScript, and they carry across directly. What changes when you migrate to HyperIndex is a small, well-defined set of API calls. Not the logic. The wiring.
This is not theoretical. Katana migrated two production SushiSwap subgraphs exactly this way, entity-for-entity, and now serves its app from Envio. The walkthrough below uses before-and-after code from the canonical [migration guide](https://docs.envio.dev/docs/HyperIndex/migration-guide), and ends with what that migration looked like in production.
:::tip Prefer an assistant-led migration?
HyperIndex ships [AI-friendly docs](https://docs.envio.dev/docs/HyperIndex-LLM/hyperindex-complete) and a [guided AI migration workflow](https://docs.envio.dev/docs/HyperIndex/migrate-with-ai) that works in both Cursor and Claude Code. The steps below are the same either way, this is what the assistant is doing under the hood.
:::
## What actually changes (and what does not)
It helps to be specific about the surface area before touching any code.
**Carries across without change:**
- Your event parsing logic
- All conditional logic and arithmetic
- Helper functions that do not use `@graphprotocol/graph-ts` types directly
- Your entity model, the fields, the relationships, and the ID conventions
**Changes during migration:**
| Concern | The Graph | HyperIndex |
|---|---|---|
| Config format | `subgraph.yaml` | `config.yaml` |
| Schema | `@entity` on every type | decorator removed |
| Handler registration | `ContractName.EventName.handler(...)` | `indexer.onEvent(...)` |
| Entity writes | `Entity.save()` | `context.Entity.set(...)` |
| Entity reads | synchronous `Entity.load(id)` | `await context.Entity.get(id)` |
| Imports | `@graphprotocol/graph-ts` | `"envio"` generated types |
| Transaction fields | available by default | opt-in via `field_selection` |
Every row is a mechanical swap. The handler body, the part that is the most work to write and the hardest to get right, is the part that does not change.
## Step 0: bootstrap the project
Start by generating a fresh HyperIndex project shell using your existing contract addresses, ABIs, and events as the source of truth:
```bash
pnpx envio init
```
Follow the prompts. The init generates `config.yaml`, `schema.graphql`, and handler stubs. At any point during the migration, validate your changes with:
```bash
pnpm envio codegen # validate config + schema, regenerate types
pnpm dev # run the indexer locally
```
## Step 1: subgraph.yaml to config.yaml
The config conversion is a restructure. HyperIndex consolidates contracts and chains into two top-level sections.
The Graph, `subgraph.yaml`:
```yaml
specVersion: 0.0.4
schema:
file: ./schema.graphql
dataSources:
- kind: ethereum/contract
name: PositionManager
network: mainnet
source:
abi: PositionManager
address: "0xbD216513d74C8cf14cf4747E6AaA6420FF64ee9e"
startBlock: 21689089
mapping:
kind: ethereum/events
apiVersion: 0.0.7
language: wasm/assemblyscript
entities:
- Position
abis:
- name: PositionManager
file: ./abis/PositionManager.json
eventHandlers:
- event: Transfer(indexed address,indexed address,indexed uint256)
handler: handleTransfer
- event: Subscription(indexed uint256,indexed address)
handler: handleSubscription
```
HyperIndex, `config.yaml`:
```yaml
name: uni-v4-indexer
contracts:
- name: PositionManager
abi_file_path: ./abis/PositionManager.json
events:
- event: Transfer(address indexed from, address indexed to, uint256 indexed id)
- event: Subscription(uint256 indexed tokenId, address indexed subscriber)
chains:
- id: 1
start_block: 21689089
contracts:
- name: PositionManager
address: "0xbD216513d74C8cf14cf4747E6AaA6420FF64ee9e"
```
One thing that trips teams up consistently, HyperIndex uses `chains:` (not `networks:`).
### Transaction and receipt fields
In a subgraph, you opt into receipt data with `receipt: true` in `subgraph.yaml`. In HyperIndex, receipt-level fields like `status` and `gasUsed` are accessed via `field_selection` in `config.yaml`:
```yaml
field_selection:
transaction_fields:
- hash
- status
- gasUsed
```
Note that `event.transaction.hash` is not available by default, add it to `transaction_fields` before referencing it in a handler.
## Step 2: schema, near copy-paste
Your existing `schema.graphql` carries across almost unchanged. The only required edit is removing the `@entity` decorator from every type.
The Graph:
```graphql
type Transfer @entity {
id: ID!
from: String!
to: String!
amount: BigInt!
timestamp: Int!
}
```
HyperIndex:
```graphql
type Transfer {
id: ID!
from: String! @index
to: String!
amount: BigInt!
timestamp: Int!
}
```
Field types, `ID!` primary keys, `@derivedFrom` relations, nullable vs non-nullable, and enums all carry across unchanged. After any schema edit, run `pnpm envio codegen` to regenerate the typed bindings before touching handler code.
## Step 3: handlers, four API changes
This is the step teams worry about most, and it is the smallest. Here is the same handler in both frameworks, using the Uniswap V4 Subscription event:
The Graph (AssemblyScript):
```typescript
export function handleSubscription(event: SubscriptionEvent): void {
const subscription = new Subscribe(
event.transaction.hash.toHex() + "-" + event.logIndex.toString()
);
subscription.tokenId = event.params.tokenId;
subscription.subscriber = event.params.subscriber.toHexString();
subscription.logIndex = event.logIndex;
subscription.blockNumber = event.block.number;
subscription.save();
}
```
HyperIndex (TypeScript v3):
```typescript
import { indexer } from "envio";
indexer.onEvent(
{ contract: "PositionManager", event: "Subscription" },
async ({ event, context }) => {
context.Subscribe.set({
id: `${event.transaction.hash}_${event.logIndex}`,
tokenId: event.params.tokenId,
subscriber: event.params.subscriber,
logIndex: event.logIndex,
blockNumber: event.block.number,
});
},
);
```
The token ID parsing, the field assignments, and the ID construction are all identical. What changed is the import, the handler registration, `entity.save()` becoming `context.Subscribe.set()`, the async function signature, and `.toHexString()` becoming unnecessary because addresses arrive as strings.
### The one rule that catches every team
Entities returned by `context.Entity.get()` are read-only. When updating an existing entity, always spread the existing object and override fields:
```typescript
const token = await context.Token.get(event.params.to);
if (token) {
context.Token.set({
...token,
balance: token.balance + event.params.value,
});
}
```
### Factory contracts (dynamic data sources)
Where The Graph uses `templates:` in `subgraph.yaml`, HyperIndex uses `indexer.contractRegister`:
```typescript
indexer.contractRegister(
{ contract: "Factory", event: "PairCreated" },
({ event, context }) => {
context.chain.Pair.add(event.params.pair);
},
);
```
## Validating the migration
After running locally against a block range, use the [Indexer Migration Validator](https://github.com/enviodev/indexer-migration-validator) CLI to diff entity state between your subgraph endpoint and your HyperIndex endpoint. It generates entity configs automatically from your GraphQL schema and gives field-level analysis of any discrepancies. Running both in parallel over the same block range is the fastest way to confirm correctness before cutting over production traffic.
## GraphQL queries
HyperIndex uses standard GraphQL. The Graph uses a custom dialect with some non-standard filter and ordering syntax. For queries that use Graph-specific syntax, the [Query Conversion Guide](https://docs.envio.dev/docs/HyperIndex/query-conversion) covers the differences. For backwards compatibility, Envio's subgraph-compatible endpoint accepts The Graph's query syntax. Katana's production migration ran against this endpoint, allowing their existing app queries to work without changes while they transitioned to the native endpoint.
## What it looks like in production
Katana migrated two production SushiSwap subgraphs from The Graph to Envio, carrying the data model across entity-for-entity, all 23 entity types, tracking the Uniswap V3 factory, the position manager, and every pool it deploys. Same entities, same shape.
- SushiSwap V3 indexer: 11,473,382 events synced in about two hours
- Sushi staker indexer: 68,201 events synced in under 20 seconds
Full case study: [How Katana migrated SushiSwap data from The Graph to Envio](https://docs.envio.dev/blog/case-study-katana-sushiswap).
## Why bother, the performance case
From the Sentio Uniswap V2 Factory benchmark (April 2025):
| Indexer | Time | vs HyperIndex |
|---|---|---|
| Envio HyperIndex | 8 seconds | baseline |
| Subsquid (SQD) | 2 minutes | 15x slower |
| The Graph | 19 minutes | 142x slower |
| Ponder | 21 minutes | 157x slower |
The pattern holds every time. Your logic is already TypeScript, so it moves. The wiring changes in a handful of well-defined places, the validator confirms the output matches your old subgraph, and you cut over. That is the whole migration.
## Get started
- [Migration guide](https://docs.envio.dev/docs/HyperIndex/migration-guide)
- [Query Conversion Guide](https://docs.envio.dev/docs/HyperIndex/query-conversion)
- [Indexer Migration Validator](https://github.com/enviodev/indexer-migration-validator)
- [Katana case study](https://docs.envio.dev/blog/case-study-katana-sushiswap)
- [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service)
## Frequently asked questions
### Is the AssemblyScript-to-TypeScript conversion really just a copy-paste?
For pure logic functions, yes. AssemblyScript is a subset of TypeScript, so any function that does not import from `@graphprotocol/graph-ts` is valid TypeScript and carries across without changes. The parts that require translation are the imports, the entity save calls, the entity load calls (synchronous becomes async/await), and the handler registration syntax. The event parsing logic, the business logic, and the arithmetic are identical.
### Do I need to handle reorgs in my HyperIndex handlers?
No. HyperIndex handles reorgs at the framework level by tracking entity state history for every unfinalized block and rolling back automatically. You write forward-only handler logic and the framework manages rollback.
### Can I keep my existing GraphQL queries after migrating?
Most queries carry across without change. Envio's subgraph-compatible endpoint accepts The Graph's query syntax as a drop-in, so existing app queries keep working while you transition to the native endpoint. The Query Conversion Guide covers the syntax differences.
### How long does a subgraph migration take?
For a single-contract subgraph with straightforward handlers, the mechanical migration is typically a few hours. Katana migrated two production SushiSwap subgraphs with entity-for-entity parity and had both syncing on Envio within a working session. For multi-subgraph setups, the consolidation into one TypeScript codebase adds time but reduces ongoing maintenance.
### What is the Indexer Migration Validator and how do I use it?
The Indexer Migration Validator is an open-source CLI tool that diffs entity state between a subgraph endpoint and a HyperIndex endpoint. It generates entity configs from your GraphQL schema automatically, runs both endpoints over the same block range in parallel, and produces field-level analysis of any discrepancies.
### Can I run multiple chains in one HyperIndex indexer?
Yes. A single `config.yaml` declares all chains under a `chains:` array. Multichain indexing is the default in V3, with no opt-in required. Each chain-specific entity ID should include `event.chainId` to prevent collisions across chains.
## Build With Envio
Envio is a real-time multichain blockchain indexer that turns onchain events into a queryable GraphQL API. Supports any EVM chain, plus Solana and Fuel. Use Envio Cloud or self-host. If you're building onchain, come talk to us about your data needs.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://x.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Why Blockchain Indexers Hit Rate Limits at Scale
> Blockchain indexers hit rate limits because RPC meters every request. See how HyperSync's bulk-read architecture handles high traffic without throttling, with production-scale numbers.
:::note TL;DR
- Throttling is a symptom of the per-request RPC model. Providers meter calls because every `eth_getLogs` request costs them node time, so traffic spikes get rate-limited.
- HyperSync replaces thousands of RPC calls with one filtered bulk query. High traffic produces fewer, larger reads instead of a flood of small ones, so the rate-limit problem does not arise in the same form.
- For chains with native HyperSync coverage, HyperIndex developers do not need to manage RPCs or rate limiting at all.
- If a configured data source degrades, HyperIndex fails over to a fallback within seconds and recovers to the primary automatically.
:::
Ask developers why they are shopping for a new blockchain data provider, and a recurring answer is throttling. The dashboard spikes, the app gets popular for an afternoon, and the data layer starts returning 429s exactly when the data matters most.
This blog explains why that happens, why HyperSync's architecture sidesteps it, and what the behaviour looks like at production scale.
## Why Providers Throttle in the First Place
The standard data path is JSON-RPC. Every read is a request, every request hits a node, and nodes are expensive to run. Providers meter usage per request and enforce rate limits to protect shared infrastructure. That is a reasonable response to the economics of RPC. It is also why high traffic and throttling arrive together, the busier your app gets, the more requests you issue, and the closer you run to the ceiling.
The deeper problem is that RPC makes you ask for data in tiny pieces. Reading a year of events for one contract means paginating `eth_getLogs` over block ranges, thousands of calls for one logical question. Your "high traffic" is mostly overhead imposed by the interface.
## What HyperSync Does Differently
[HyperSync](https://docs.envio.dev/docs/HyperSync/overview) is Envio's high-performance data retrieval layer, built in Rust as an alternative to JSON-RPC. You describe what you want once, a block range, a filter across logs, transactions, traces, or blocks, and a field selection that returns only the columns you need. The engine streams the result back.
The shape of the load changes completely. One HyperSync query does the work of the thousands of RPC calls it replaces, and field selection keeps each response small. Under high traffic, you issue fewer, larger reads, which is the access pattern the engine is built for. Scanning Arbitrum for sparse log data takes 2 seconds over HyperSync, a task that can take hours to days over RPC.
This is also why we can make a claim that no RPC-based indexer makes, for chains with native HyperSync coverage, [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) uses it as the default data source, and developers do not additionally need to worry about RPCs or rate limiting. The problem is removed at the data layer rather than managed in application code.
## What It Looks Like at Production Scale
The [Polymarket reference indexer](https://github.com/enviodev/polymarket-indexer) processes over 6 billion events on Polygon. [ChainDensity](https://chaindensity.xyz) runs chain-wide scans, the heaviest read pattern there is, and returns density maps in seconds. Every one of those workloads would be a sustained rate-limit fight on a per-request provider.
For repeatable numbers, the Sentio independent benchmarks measured HyperIndex processing 100,000 Ethereum blocks with metadata extraction in 7.9 seconds, against 10 minutes for The Graph on the same workload. The full case suite is in the sentio-benchmark repo, and the [open-indexer-benchmark repo](https://github.com/enviodev/open-indexer-benchmark) gives you templates to run the same tests yourself.
## And When Something Upstream Does Fail
No data source has perfect uptime, so the honest version of "does not throttle" includes what happens when a source degrades. HyperIndex ships multi-data-source recovery. Indexers configured with a fallback fail over automatically when a primary stops returning new blocks, and the indexer attempts to recover to the primary 60 seconds later without a restart. The source selection logic is built for resilience, and data-source activity surfaces in the Prometheus metrics before downstream consumers notice.
Throttling resilience is an architecture property. Failure resilience is a framework property. You want both.
## Test It on Your Heaviest Query
The fastest way to test the claim is to throw your worst read at it. Build a filtered query visually at [builder.hypersync.xyz](https://builder.hypersync.xyz), or scan a chain from your terminal with zero setup:
```sh
pnpx logtui aave arbitrum
```
If you would rather have the full framework, schema, handlers, and a GraphQL API on top of the same engine, scaffold an indexer, and deploy it to Envio Cloud:
```sh
pnpx envio init
```
## Frequently Asked Questions
### Does HyperSync Rate-Limit Queries During High Traffic?
HyperSync is built for bulk retrieval, so the request-flood pattern that triggers rate limiting on RPC providers does not occur in the same form. One filtered query replaces the thousands of paginated RPC calls it would otherwise take, and for chains with native HyperSync coverage, developers do not need to manage RPCs or rate limiting.
### Why Do RPC Providers Throttle During Traffic Spikes?
Because the JSON-RPC model prices and provisions per request. Every read hits node infrastructure, so providers enforce rate limits to protect shared capacity, and those limits bind exactly when your application is busiest. The interface also forces large reads to be split into thousands of small paginated calls, which further inflates request volume.
### What Is the Largest Workload HyperSync Has Handled in Production?
At the time of writing this, the public reference is the Polymarket indexer, which processes over 6 billion events on Polygon.
### What Happens to My Indexer if a Data Source Goes Down Mid-Spike?
HyperIndex fails over to a configured fallback source when a primary stops returning new blocks and attempts to recover to the primary 60 seconds after the primary returns, with no restart required. The source selection logic is built for resilience, and degradation surfaces in the standard Prometheus metrics endpoint.
### How Do I Benchmark HyperSync Against My Current Provider?
Reproduce your heaviest production query in the visual query builder at [builder.hypersync.xyz](https://builder.hypersync.xyz), or run the open benchmark suite at the [open-indexer-benchmark repo](https://github.com/enviodev/open-indexer-benchmark). Both are public.
## Build With Envio
Envio is a real-time multichain blockchain indexer that turns onchain events into a queryable GraphQL API. Supports any EVM chain, plus Solana and Fuel. Use Envio Cloud or self-host. If you're building onchain, come talk to us about your data needs.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Scale Subgraphs to Millions of Requests
> Scaling subgraph-style data to millions of requests is two problems: sync speed and query latency. How HyperIndex handles both while keeping your data model intact.
 :::note TL;DR
- "Scale my subgraphs" is two separate problems. Sync speed is how fast events become rows. Query latency is how fast reads return once they are rows. Fixing one does not fix the other.
- On sync speed, HyperIndex is the best indexer in independent testing. See the [Sentio benchmarks](https://docs.envio.dev/docs/HyperIndex/benchmarks) for the numbers.
- On query latency, HyperIndex serves reads from a dedicated Postgres database through your own GraphQL endpoint, not through a shared gateway, so read performance is predictable under load.
- You keep the data model. Katana moved two production SushiSwap subgraphs entity-for-entity: 23 entity types, carried across without schema redesign. Polymarket replaced 8 subgraphs with one indexer that has processed over 6.5 billion events.
- For high-throughput production workloads, Envio Cloud's production plans add higher resource and query rate limits plus zero-downtime deployments, and Dedicated plans carry custom SLAs and SQL access alongside GraphQL.
:::
Subgraphs are usually adopted when an app is small and queries are light. The pain starts later, when the frontend is making millions of requests, and the dashboard needs fresh data under load. At that point, teams search for how to scale their subgraphs, and most of the advice they find addresses the wrong half of the problem.
## Scaling Is Two Problems, Not One
Sync speed and query latency are different bottlenecks with different fixes.
Sync speed determines how quickly onchain events land in your database, which sets data freshness and how painful a re-deploy or backfill is. Query latency determines how fast your API answers once the data is already indexed, which is what your users actually feel.
A subgraph at scale typically hurts on both ends. Backfills take hours or days, and reads route through shared serving infrastructure you do not control and cannot provision for your traffic.
## Sync Speed
HyperIndex pulls data through HyperSync, Envio's Rust data engine, rather than paginated RPC reads. Independent benchmarks put it at 8 seconds for the Uniswap V2 Factory workload, 142x faster than The Graph on the same test. See the [full benchmark methodology](https://docs.envio.dev/docs/HyperIndex/benchmarks). Fast sync at this layer is what makes everything downstream cheap, because a schema change means re-syncing in hours rather than weeks.
## Query Latency: The Half Nobody Benchmarks
HyperIndex processes events into Postgres and serves them through an auto-generated GraphQL API on your own endpoint. Your reads hit a relational database provisioned for your indexer, not a shared gateway. That is what keeps read latency predictable as request volume grows.
The Hasura-powered endpoint supports the full filter and ordering syntax your users need. A dashboard showing a specific address's trade history looks like this:
```graphql
query AddressActivity($address: String!) {
Trade(
where: { maker: { _eq: $address } }
order_by: { blockNumber: desc }
limit: 100
) {
id
maker
amountIn
amountOut
blockNumber
}
}
```
Full query reference at [docs.envio.dev/docs/HyperIndex/navigating-hasura](https://docs.envio.dev/docs/HyperIndex/navigating-hasura).
For traffic in the millions of requests, Envio Cloud production plans are sized for high-throughput indexers, with zero-downtime deployments so a new indexer version promotes to the production endpoint without consumers seeing a change. Dedicated plans add custom SLAs and SQL access alongside GraphQL when an ORM or direct queries fit your backend better.
## You Keep the Data Model
The reason teams hesitate to leave subgraphs is the rebuild. With HyperIndex, the schema migration is close to copy-paste, the [migration guide](https://docs.envio.dev/docs/HyperIndex/migration-guide) covers the differences, and handlers move from AssemblyScript to plain TypeScript.
Katana migrated two production SushiSwap subgraphs from The Graph with the data model carried over entity-for-entity, all 23 entity types, tracking the Uniswap V3 factory, position manager, and every pool it deploys. Same entities, same shape. Their SushiSwap V3 indexer synced in about two hours. The Sushi staker was done in under 20 seconds. Read the [full case study](https://docs.envio.dev/blog/case-study-katana-sushiswap) on our blog.
The [Indexer Migration Validator](https://github.com/enviodev/indexer-migration-validator) compares both endpoints field by field, so you can prove parity before switching traffic.
## Where to Start
If your subgraph is hitting its ceiling, the path is short. Scaffold an indexer, port the schema, migrate your handlers and config across, following the [migration guide](https://docs.envio.dev/docs/HyperIndex/migration-guide), then point the migration validator at both endpoints:
```bash
pnpx envio init
```
Envio also offers white-glove migration support for production teams. Reach out on [Discord](https://discord.gg/envio).
## Frequently Asked Questions
### Why Is My Subgraph Slow at High Request Volume?
Usually for two unrelated reasons. Historical sync is slow because data arrives over paginated RPC-style reads. Query latency is variable because reads route through shared serving infrastructure sized for the network rather than your traffic. Diagnose which one you are hitting before paying to fix the wrong one.
### Can a HyperIndex Endpoint Handle Millions of GraphQL Requests?
HyperIndex serves queries from a dedicated Postgres database behind your own GraphQL endpoint, and Envio Cloud production plans are sized for high-throughput workloads, with Dedicated plans adding custom SLAs. The endpoint is yours, not a shared gateway, so read performance does not degrade when your app gets busy.
### Do I Lose My Subgraph Schema When Moving to HyperIndex?
No. The schema migration is close to copy-paste, with small differences like dropping the `@entity` directive. Katana's SushiSwap V3 migration carried 23 entity types across without schema redesign, and the open-source Indexer Migration Validator verifies that both endpoints return matching data before you cut over.
### Does Fast Indexing Actually Improve My API Response Times?
Not directly. Anyone who tells you otherwise is skipping a step. Indexing speed sets data freshness and backfill cost. Response times depend on the serving layer, which for HyperIndex is your own Postgres-backed GraphQL endpoint rather than a shared gateway. You need both halves to scale.
### What Envio Cloud Plan Do I Need for High-Traffic Production Workloads?
For production workloads, use one of the paid plans rather than the dev tier. Paid production plans include zero-downtime deployments, higher limits, and higher query rate limits. Dedicated plans additionally include custom SLAs, isolated infrastructure, and SQL access alongside the GraphQL endpoint. Current [pricing and plan details](https://docs.envio.dev/docs/HyperIndex/hosted-service-billing) can be found in our docs.
## Build With Envio
Envio is a real-time multichain blockchain indexer that turns onchain events into a queryable GraphQL API. Supports any EVM chain, plus Solana and Fuel. Use Envio Cloud or self-host. If you're building onchain, come talk to us about your data needs.
Stay tuned for more updates by subscribing to our newsletter, following us on X, or hopping into our Discord.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev)
---
# Envio Developer Update June 2026
> HyperIndex shipped v3.1 and v3.2 with up to 2.5x faster and 2x cheaper indexing, multi-field getWhere filtering, multi-storage defaults, snake_case column names, and expanded experimental Solana support. We sponsored ETHConf New York, and the community shipped real-time apps on RWAs and x402, alongside new guides on agentic indexing, scaling subgraphs, and HyperIndex vs HyperSync.
 June was one of our biggest months yet. HyperIndex advanced, delivering up to 2.5x faster and 2x cheaper indexing alongside multi-field getWhere filtering, multi-storage defaults, snake_case column naming, and expanded experimental Solana support. We also sponsored and attended ETHConf New York, continued migrating performance-critical paths to Rust, and saw teams ship a range of production-grade, real-time applications on Envio, spanning real-world asset tracking and x402 payment analytics.
Alongside the releases, we published new technical guides on agentic indexing, scaling subgraph-style workloads to millions of requests, choosing between HyperIndex and HyperSync, and much more.
Let's dive in!
## HyperIndex v3.1 & v3.2: Faster, Cheaper, and More Flexible
Building on May's V3 launch, June delivered two substantial releases focused on speed, cost, and flexibility, followed by a patch release and the start of work on v3.3.
### v3.1
v3.1 cut HyperSync queries during backfill by up to 2x and made many indexing cases up to 2.5x faster. It also added string descriptions for entities, fields, and relationships that surface directly in the GraphQL API, rate-limit information in the TUI and logs, a skip option to exclude chains from indexing and migrations, and support for startups with 4.5M+ contracts. We also improved the agentic development experience with new `envio tools search-docs` and `envio tools fetch-docs` commands, plus an `envio metrics runtime` subcommand.
**Up to 2.5x faster indexing, with up to 2x fewer HyperSync queries during backfill.**
### v3.2
v3.2 followed with multi-field filtering in `getWhere`, so you can match on several entity fields at once, plus a performance boost for single `_eq` and `_in` lookups. Multi-storage got easier with default storages, so you no longer need a `@storage` directive on every entity, and you can now auto-convert database column names to snake_case while keeping the original names in GraphQL and handler types. We also expanded experimental Solana support with HyperSync-powered instruction handlers. Reach out to us if you are interested in becoming an early tester.
#### Multi-field filtering with getWhere
Match on several entity fields at once:
```typescript
await context.Account.getWhere({
id: { _eq: "0x123..." },
balance: { _gte: 1_000_000n, _lte: 10_000_000n },
});
```
#### Multi-storage defaults
Mark a storage as default, so you no longer need a `@storage` attribute on every entity in `schema.graphql`:
```yaml
storage:
postgres:
default: true
clickhouse:
default: true
```
#### snake_case column names
Auto-convert database column names to snake_case, while GraphQL and handler types keep the original names from `schema.graphql`:
```yaml
storage:
postgres:
column_name_format: snake_case
```
### v3.2.1
v3.2.1 rounded out the month with a smoother `envio init` experience for agents and non-interactive runs, ClickHouse nullable array validation, and faster indexing through topic filtering by address. We have also started work on v3.3.0 in alpha, focused on faster backfills for large multichain indexers.
See the full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex) ⭐
## Just-in-Time Indexing: Using Agents to Answer Onchain Questions
 Just-in-Time Indexing shows how an AI agent can use Envio to answer one-off onchain questions without maintaining permanent infrastructure. The agent builds the indexer on demand, queries it once, and deletes it.
See how Curve Finance has been using Envio to answer one-off onchain questions with just-in-time indexing.
Read it here: https://docs.envio.dev/blog/just-in-time-indexing-agents-onchain
## RWA Radar: Real-World Assets Onchain in Real Time
 RWA Radar tracks real-world assets onchain in real time, covering stablecoins, credit, stocks, securities, and more, with sector breakdowns, volume, and history across chains in a single view, and exports to CSV, PDF, or XLSX. Ingestion is powered by HyperIndex.
Explore it here: https://rwaradar.io
## When to Use HyperIndex vs HyperSync
 This guide breaks down the two layers of the Envio stack, HyperSync as the data engine and HyperIndex as the framework built on top of it, with working v3 code and production examples to help teams choose the right tool for the job.
Read the full breakdown: https://docs.envio.dev/blog/hyperindex-vs-hypersync
## x402stats Analytics Explorer
 x402stats surfaces real-time stats for the x402 payment protocol on Base, including USDC volume, payment counts, active services, and buyers across 24h, 7d, 30d, and all-time, plus leaderboards for top services and facilitators.
Check it out here: https://x402stats.ai
## Why Blockchain Indexers Hit Rate Limits at Scale
 Why Blockchain Indexers Hit Rate Limits at Scale explains why RPC-based indexers throttle, and how HyperSync's bulk-read architecture handles high traffic, with production-scale numbers.
More here: https://docs.envio.dev/blog/hypersync-under-load-no-throttling
## How to Scale Subgraphs to Millions of Requests
 This one tackles the two halves of the problem, sync speed and query latency, and how HyperIndex handles both while keeping your data model intact.
Read the full guide: https://docs.envio.dev/blog/scale-subgraphs-millions-of-requests
## How to Index Sei Smart Contract Data in Minutes
 This step-by-step guide walks through indexing a Sei ERC20 contract, streaming USDC Transfer and Approval events into Postgres and serving them through a GraphQL API.
Read the tutorial: https://docs.envio.dev/blog/index-sei-smart-contracts-envio
## ETHConf New York
 We sponsored ETHConf in New York from June 8th to 10th. The team set up a booth, handed out the (back by popular demand) "low maintenance" caps and fresh stickers, and spent the week talking fast indexing, HyperSync, and pulling onchain data without the wait.
Thank you to the ETHGlobal and ETHConf teams for having us, and to everyone who stopped by to talk data.
## Featured Developer: Bazhar
 This month's featured developer is Bazhar, a developer and analyst focused on blockchain data, indexing, and building tools that make onchain activity easier to understand and query. Lately they have been working on approval discovery across chains, finding which wallets have approved a given contract, like a router, bridge, or Permit2-style spender, and turning that into a fast API and query layer, with most of the work centred on ERC20 approvals, spender contracts, and multichain data fast enough for production.
**What Bazhar had to say about Envio:**
> ***"My experience with Envio has been really good. I came in with a fairly specific use case around discovering ERC20 approvals by spender contract across chains, and the team helped me think through the right architecture instead of just giving a generic answer. What stood out to me was how practical the support was. They explained where an indexer makes sense, where HyperSync can be used directly, and also clarified the important limitation around "live" allowances that Approval events alone don't always reflect the remaining allowance after transferFrom calls. That helped me understand the trade-offs between preindexing everything, querying HyperSync on demand, and using RPC checks only where needed. Overall, Envio feels very developer-friendly. The team was responsive, honest about the technical and cost trade-offs, and helped turn a rough idea into a much clearer implementation path."***
Well done, Bazhar. Be sure to check out their [GitHub](https://github.com/bazhar1337) to stay up to date with their latest developments.
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/4262PvQguBC6M84amVTxDr)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you're working on a Web3 project and want a smoother development process, Envio's got your back(end). Check out our docs, join the community, and let's talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Stream Onchain Events to an AI Trading Agent
> How to feed real-time onchain events into an AI trading agent's decision loop with HyperIndex, using working schema and queries from the published Polymarket reference indexer.
 :::note TL;DR
- A trading agent is only as good as its feed. It needs a data source that is as fast and as accurate as possible, including staying correct through reorgs. Raw RPC gives you none of that out of the box.
- One layer does the work. HyperIndex indexes onchain events into GraphQL entities, and it ingests through HyperSync internally with reorg detection built in, so you get speed and rollback safety from a single layer.
- HyperIndex exposes a single GraphQL endpoint. The agent polls it for new events as they land, and queries the same endpoint for historical state: an address's track record, a market's running volume, open positions. No rebuilding history inside the context window.
- Reorgs are a normal part of consensus. HyperIndex rolls entity state back automatically when a chain reorgs, but state at the very head is provisional, so for anything that moves money, the conservative path is to act on events from finalized blocks.
- The schema and queries below come from the published Polymarket reference indexer.
:::
The interesting question about AI trading agents is not the model, it is the feed. An agent reasoning over markets needs to see events with as little latency as possible after they land onchain, in a shape it can reason about, from a source it can trust after a reorg. This guide builds that feed with one layer, then shows where the agent plugs in.
## The Architecture in One Paragraph
One layer, accessed two ways. HyperIndex turns a contract's events into structured entities served over GraphQL. Under the hood, it streams from HyperSync for fast ingestion, while HyperIndex detects reorgs and rolls entity state back when one happens. The agent talks to a single GraphQL endpoint: it polls for new trades as they land, and queries the same endpoint for state, market totals, an address's history, and open positions. There is no separate ingestion pipeline to run and no in-memory state to rebuild.
## Step 1: Index the events once
This is the indexing setup from our [Polymarket reference indexer](https://github.com/enviodev/polymarket-indexer), which watches `OrderFilled` events from the Polymarket Exchange contracts on Polygon. You define the contract and event once in `config.yaml`:
```yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: polymarket-indexer
field_selection:
transaction_fields:
- hash
contracts:
- name: Exchange
abi_file_path: ./abis/Exchange.json
events:
- event: "OrderFilled(bytes32 indexed orderHash, address indexed maker, address indexed taker, uint256 makerAssetId, uint256 takerAssetId, uint256 makerAmountFilled, uint256 takerAmountFilled, uint256 fee)"
chains:
- id: 137 # Polygon
start_block: 33605403
contracts:
- name: Exchange
address:
- "0x4bFb41d5B3570DeFd03C39a9A4D8dE6Bd8B8982E"
- "0xC5d563A36AE78145C45a50134d48A1215220f80a"
```
You define the entities once in `schema.graphql`. One entity for the raw trade the agent reacts to, one aggregate the agent reads for context:
```graphql
type OrderFilledEvent
@index(fields: ["maker", ["timestamp", "DESC"]])
@index(fields: ["makerAssetId", ["timestamp", "DESC"]]) {
id: ID!
transactionHash: String!
timestamp: BigInt! @index
orderHash: String! @index
maker: String! @index
taker: String! @index
makerAssetId: String! @index
takerAssetId: String! @index
makerAmountFilled: BigInt!
takerAmountFilled: BigInt!
fee: BigInt!
}
type Orderbook {
id: ID!
tradesQuantity: BigInt!
buysQuantity: BigInt!
sellsQuantity: BigInt!
collateralVolume: BigInt!
scaledCollateralVolume: BigDecimal!
}
```
And you map the event to those entities once in the handler. Every field comes straight off the `OrderFilled` event, and the running totals are computed at indexing time so the agent never has to aggregate at query time:
```typescript
import { indexer } from "envio";
indexer.onEvent({ contract: "Exchange", event: "OrderFilled" }, async ({ event, context }) => {
context.OrderFilledEvent.set({
id: `${event.chainId}_${event.block.number}_${event.logIndex}`,
transactionHash: event.transaction.hash,
timestamp: BigInt(event.block.timestamp),
orderHash: event.params.orderHash,
maker: event.params.maker,
taker: event.params.taker,
makerAssetId: event.params.makerAssetId.toString(),
takerAssetId: event.params.takerAssetId.toString(),
makerAmountFilled: event.params.makerAmountFilled,
takerAmountFilled: event.params.takerAmountFilled,
fee: event.params.fee,
});
});
```
The same pattern works for DEX swaps, liquidations, or any event family on any HyperSync-supported chain by changing the contract, the event signature, and the chain ID.
## Wake the agent on new trades
A GraphQL subscription is the agent's trigger. The agent holds an open subscription to the endpoint and gets pushed each new `OrderFilledEvent` as it lands, within a block of it happening, already decoded into the fields you defined:
```graphql
subscription LatestTrades {
OrderFilledEvent(order_by: { timestamp: desc }, limit: 1) {
maker
taker
makerAssetId
makerAmountFilled
takerAmountFilled
timestamp
}
}
```
If a long-lived subscription does not fit your runtime, the same query polled on a short interval gives you the same trigger with simpler plumbing. Either way the agent reacts to structured trades, not raw logs.
## Step 2: Give the Agent State, Not Just Ticks
A trigger tells the agent what just happened. Trading decisions usually need what has been happening, and rebuilding that from raw events inside a context window wastes tokens and invites errors. Because the handler already wrote the history and the running totals, the agent's pre-decision check is a query, not a computation. Pull a maker's recent track record:
```graphql
query MakerHistory($maker: String!) {
OrderFilledEvent(
where: { maker: { _eq: $maker } }
order_by: { timestamp: desc }
limit: 100
) {
makerAmountFilled
takerAmountFilled
timestamp
}
}
```
Or read the market's running volume straight off the aggregate, with no runtime aggregation:
```graphql
query MarketVolume {
Orderbook {
tradesQuantity
scaledCollateralVolume
}
}
```
Computing aggregates at indexing time rather than query time is the recommended pattern, and it is what keeps these reads fast at scale. The [Navigating Hasura](https://docs.envio.dev/docs/HyperIndex/navigating-hasura) guide covers the full query reference.
## Step 3: Take Reorgs Seriously
Reorgs are a normal part of consensus, not an Envio thing and not an edge case you can design away. A chain can fork at the head and resolve to a different set of blocks, and any event read from those orphaned blocks describes something that, as far as the canonical chain is concerned, never happened. This is true of every data source, raw RPC included.
HyperIndex handles the database side for you. Reorg support is on by default, and as long as HyperIndex ingests through HyperSync, reorg detection is guaranteed. When a reorg is detected, entity state is rolled back automatically to the canonical chain, with no rollback logic in your handlers. The full mechanics are in [Understanding and Handling Chain Reorganizations](https://docs.envio.dev/docs/HyperIndex/reorgs-support).
The caveat that matters for a trading agent is this. Rollback corrects the database, it cannot recall a trade. There is a short window at the head where the indexed state can reflect a block that later gets orphaned. An agent that reads in that window and acts on it has already sent the order by the time the rollback fires. The data corrects, the trade does not. A dashboard showing a stale number is harmless; an agent trading on one is not.
So treat the head-of-chain state as provisional. HyperIndex considers a block safe from reorganization once it sits below the confirmation threshold, which defaults to 200 blocks below the head and is configurable per chain via `max_reorg_depth`. For anything that moves money, the conservative path is to act on events from finalized blocks and let the freshest head data inform analysis rather than execution. None of this is specific to Envio. Any trading agent on any stack faces the same finality question, regardless of where its data comes from.
## A Note on the Trading Part
Everything above is the data layer, and it is the part worth automating first. Order execution is where agent autonomy should stop being the default. Keep execution behind explicit limits, position caps, and human-controlled keys, and let the agent's edge be that it sees and understands the market faster, not that it can spend unsupervised.
This blog is an example of what you can build on HyperIndex, not a trading strategy and not financial advice. Whatever you ship on top of it is your own research and your own decision.
## Get Started
- [HyperIndex Quickstart](https://docs.envio.dev/docs/HyperIndex/quickstart)
- [HyperIndex Quickstart with AI](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai)
- [Polymarket reference indexer](https://github.com/enviodev/polymarket-indexer)
- [Understanding and Handling Chain Reorganizations](https://docs.envio.dev/docs/HyperIndex/reorgs-support)
- [Indexing & Reorgs](https://docs.envio.dev/blog/indexing-and-reorgs)
## Frequently Asked Questions
### Should my agent subscribe to the indexer or query it?
Both, for different questions. A GraphQL subscription is the trigger that wakes the agent within a block of an event landing. A GraphQL query is the memory that answers aggregate questions like an address's trade history or a market's running volume without rebuilding state in the agent's context. The stream wakes the agent, the query informs the decision, and both hit the same endpoint.
### What happens if my agent acts on an event that later gets reorged?
That is the failure mode to design against, because the rollback fixes data but cannot recall a trade. HyperIndex rolls indexed entity state back to the canonical chain automatically when a reorg is detected, but an agent that read head-of-chain state and traded on it in the window before detection has already acted. HyperIndex considers a block safe from reorganization at a confirmation threshold that defaults to 200 blocks below the head and is configurable per chain via `max_reorg_depth`. For stateful actions that move money, prefer events from finalized blocks.
### What chains can I stream trading events from?
Any HyperSync-supported network works with the same indexer and a one-line chain change in `config.yaml`. Chains without native HyperSync coverage are reachable through HyperIndex over standard RPC. The same schema and handler carry across chains unchanged.
### How do I handle high-frequency events without overwhelming the agent?
Compute and store aggregates in your handlers at indexing time, then have the agent read those precomputed entities rather than fetching raw rows and summarising inside the context window. Field selection keeps each response small, and the running totals on an aggregate entity like `Orderbook` give the agent market context in a single cheap read.
## Build With Envio
Envio is a real-time multichain blockchain indexer that turns onchain events into a queryable GraphQL API. Supports any EVM chain, plus Solana and Fuel. Use [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service) or self-host. If you're building onchain, come talk to us about your data needs.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio vs The Graph
> A benchmark-backed, head-to-head comparison of Envio and The Graph. Covers sync speed, TypeScript vs AssemblyScript, multichain indexing, reorg handling, and how to migrate a subgraph.
 :::note TL;DR
- Envio HyperIndex and The Graph take different approaches to indexing EVM data. This is a sourced, head-to-head comparison of the two.
- Sync speed is the clearest gap. In the independent [Sentio benchmark](/docs/HyperIndex/benchmarks), HyperIndex finished the Uniswap V2 Factory workload in 8 seconds against 19 minutes for The Graph, 142x faster.
- HyperIndex handlers are standard TypeScript in Node with any npm package. The Graph uses AssemblyScript compiled to WebAssembly.
- HyperIndex indexes every chain from one `config.yaml`. The Graph deploys one subgraph per chain.
- If you do decide to switch, migration is a [documented flow](/docs/HyperIndex/migration-guide), your existing subgraph queries keep working through Envio's query converter, and teams like Katana, Revert Finance, and Sablier have already moved. For the wider field, see [Best Blockchain Indexers in 2026](/blog/best-blockchain-indexers-2026).
:::
Most teams reach for The Graph first, because subgraphs are the incumbent way to index EVM data, the approach most developers already know. The questions tend to start later, when syncs drag, a schema change means a long backfill, or you need the same data across several chains. That is usually when Envio HyperIndex comes up.
This is a direct comparison of the two. We put them head to head on what actually separates them, sync speed, the language you write handlers in, multichain support, and reorg handling, then cover what switching involves. For the wider field of indexers, our [2026 indexer comparison](/blog/best-blockchain-indexers-2026) ranks Envio, The Graph, Goldsky, SubQuery, Subsquid, Ormi, and Ponder side by side.
## Sync Speed
Speed is the clearest difference, and it is well documented. HyperIndex pulls data through [HyperSync](/docs/HyperSync/overview), Envio's Rust data engine, which delivers up to 2000x faster data access than standard RPC. HyperIndex can also index over a standard RPC endpoint, either for chains HyperSync does not yet support or if you would rather not use it. The Graph reads through standard RPC only.
In the independent Sentio Uniswap V2 Factory benchmark, HyperIndex finished in 8 seconds against 19 minutes for The Graph, 142x faster. On the Sentio LBTC workload, it finished in 3 minutes against 3 hours 9 minutes. Full methodology is on the [benchmarks page](/docs/HyperIndex/benchmarks), with the raw runs in the [open-indexer-benchmark repo](https://github.com/enviodev/open-indexer-benchmark). Fast sync matters beyond backfills, because a schema change means re-syncing in hours rather than days.
## Handler Language, TypeScript vs AssemblyScript
The Graph's mappings are written in AssemblyScript, a strict subset of TypeScript that compiles to WebAssembly. The syntax looks familiar, but the runtime is not. Standard npm packages do not run, common idioms like optional chaining and class inheritance are restricted, and numbers use AssemblyScript BigInt rather than native JS BigInt.
HyperIndex handlers are standard TypeScript executed in Node. Any npm package works, generated types come from both your GraphQL schema and your contract ABIs, and there is no WebAssembly step. For teams already writing TypeScript across their stack, this is the difference felt every day.
## Multichain Indexing
A subgraph is deployed per chain. Indexing the same protocol on Ethereum and Base means two subgraphs, and cross-chain reads happen in your application layer.
HyperIndex declares every chain under a single `chains` array in one `config.yaml`. Adding a chain is one more entry with a chain ID and address, reusing the same contract definition and event signatures, and cross-chain queries run at the database layer behind one GraphQL endpoint. Sablier runs a single indexer across 27 chains this way.
Read more about [multichain indexing](/docs/HyperIndex/multichain-indexing) in our docs.
## Reorg Handling
Reorgs are the most common chain-level event a production indexer has to survive. On The Graph, graph-node reverts affected entities automatically when a reorg is detected, bounded by its reorg threshold and prune settings, and because each chain is its own subgraph, multichain coverage means handling that across several deployments.
HyperIndex tracks per-entity state history for every unfinalised block at the framework level, with rollback on by default. When a reorg happens, the framework rolls each entity back to its pre-reorg state and reprocesses forward against the canonical chain, then prunes history once a block finalises. No handler code is required. The details are in [Reorgs Support](/docs/HyperIndex/reorgs-support).
## Head-to-Head at a Glance
| Comparison Point | Envio HyperIndex | The Graph |
| --- | --- | --- |
| Handler language | TypeScript in Node, any npm package | AssemblyScript compiled to WebAssembly |
| Multichain | Every chain in one `config.yaml` | One subgraph per chain |
| Data source | HyperSync, up to 2000x faster than RPC, or standard RPC for chains it does not cover | Standard RPC |
| Reorg handling | Framework-level, rollback on by default | Automatic via graph-node, bounded by prune settings |
| Query language | Standard GraphQL, plus a converter for subgraph queries | Custom GraphQL dialect |
| Hosted runtime | Envio Cloud, GitHub-native deploy, or self-host via Docker | Subgraph Studio and the decentralised network |
## Switching From The Graph
If the comparison points you toward Envio, moving is a [documented flow](/docs/HyperIndex/migration-guide) rather than a rewrite. It comes down to three steps, convert `subgraph.yaml` to `config.yaml`, bring your schema across (close to copy and paste, with the `@entity` directive removed), and port your handlers from AssemblyScript to TypeScript. Running `pnpx envio init` scaffolds the config and schema, your existing subgraph queries keep working through Envio's [query converter](/docs/HyperIndex/query-conversion) tool, and the [Indexer Migration Validator](https://github.com/enviodev/indexer-migration-validator) checks both endpoints field-by-field before you cut over.
Because AssemblyScript is a subset of TypeScript, most of the handler work is mechanical, which is why many teams now let an AI assistant do the rewrite. Our [AI migration guide](/docs/HyperIndex/migrate-with-ai) walks Cursor or Claude Code through the port, and [AI-Assisted Subgraph Migration with Claude](/blog/ai-subgraph-migration-hyperindex-claude) shows it end to end.
[Katana](/blog/case-study-katana-sushiswap) moved two production SushiSwap subgraphs off The Graph entity-for-entity. [Revert Finance](/blog/revert-finance-pancakeswap-bnb-hyperindex) had a PancakeSwap V3 subgraph stuck at 70 percent sync on BNB Smart Chain for over two years, and HyperIndex synced it to 100 percent in 10 days across 1.7 billion events. The [Polymarket reference indexer](/blog/polymarket-hyperindex-case-study) consolidated 8 subgraph domains into one indexer that synced 4 billion Polygon events in 6 days. Envio also offers full white-glove migration help.
## The Bottom Line
For most EVM teams, HyperIndex is the stronger choice with faster syncs, TypeScript handlers, multichain from a single config, and a documented path off a subgraph. The one case where The Graph still fits is if you need to consume its existing network of public subgraphs, which is its own ecosystem. For building and running your own indexer, Envio is the better tool.
## Get Started
- [HyperIndex Quickstart](/docs/HyperIndex/quickstart)
- [Migrate from The Graph](/docs/HyperIndex/migration-guide)
- [Migrate using AI](/docs/HyperIndex/migrate-with-ai)
- [Polymarket production reference](/blog/polymarket-hyperindex-case-study)
- [Best Blockchain Indexers in 2026](/blog/best-blockchain-indexers-2026)
## Frequently Asked Questions
### Do My Existing Subgraph GraphQL Queries Work After Switching to Envio?
You do not have to rewrite them by hand. HyperIndex serves standard GraphQL rather than The Graph's dialect, and Envio provides a [query converter tool and conversion guide](/docs/HyperIndex/query-conversion) to translate existing subgraph queries. After switching, the [Indexer Migration Validator](https://github.com/enviodev/indexer-migration-validator) compares your new endpoint against the original subgraph field-by-field so you can confirm the data matches before cutting over.
### Can I Keep My Subgraph Schema When Moving to HyperIndex?
Largely yes. Schema migration is close to copy and paste. You remove the `@entity` directive, and there are small nuances around enums and BigDecimals documented in the [schema docs](/docs/HyperIndex/schema). HyperIndex generates its types from the same GraphQL schema and your contract ABIs, so entity definitions and relationships carry across with minimal rework.
### How Long Does a The Graph to Envio Migration Take?
It depends on handler complexity, but the shape is fixed at three steps, config, schema, and handlers. Pure handler logic often copies straight across because AssemblyScript is a subset of TypeScript, and `pnpx envio init` scaffolds the config and schema for you. Teams also use [AI-assisted migration](/docs/HyperIndex/migrate-with-ai) for the rewrite, and Envio offers white-glove help via [Discord](https://discord.gg/envio).
### Can One Envio Indexer Replace Several Per-Chain Subgraphs?
Yes, and it is a common outcome. Because every chain lives in one `config.yaml`, teams routinely consolidate multiple subgraph deployments into a single indexer. Sablier replaced 12 deployments with one indexer across 27 chains, and the [Polymarket reference](/blog/polymarket-hyperindex-case-study) unified 8 subgraph domains into one indexer syncing 4 billion events in 6 days.
### Does Moving to Envio Mean I Lose Access to The Graph's Public Subgraphs?
Yes, and that is the main reason to stay on The Graph. Its decentralised network hosts the largest set of community-maintained subgraphs for major protocols. Envio indexes your own contracts into your own schema, so if your dependency is on consuming those public subgraphs rather than running your own indexer, The Graph is still the right home for that.
### Is HyperIndex Faster Than The Graph in Independent Benchmarks?
Yes. In the independent Sentio Uniswap V2 Factory benchmark, HyperIndex finished in 8 seconds against 19 minutes for The Graph, 142x faster, and on the Sentio LBTC workload it finished in 3 minutes against 3 hours 9 minutes. The gap comes from HyperSync, Envio's Rust data engine, which delivers up to 2000x faster data access than the standard RPC that The Graph reads through. Full methodology is on the [benchmarks page](/docs/HyperIndex/benchmarks) and the raw runs are in the [open-indexer-benchmark repo](https://github.com/enviodev/open-indexer-benchmark).
## Build With Envio
Envio is a real-time multichain blockchain indexer that turns onchain events into a queryable GraphQL API. Supports any EVM chain, plus Solana and Fuel. Use Envio Cloud or self-host. If you're building onchain, come talk to us about your data needs.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post) 💌
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Build an Open Source RWA Stablecoin Dashboard
> How to build an open-source RWA stablecoin dashboard backed by a HyperIndex indexer you can run yourself, deriving total supply, transfers, mints, burns, and daily snapshots straight from Transfer events, with USDT's Issue and Redeem handled directly.
 :::note TL;DR
- The RWA dashboard is open source and backed by an indexer you can run yourself, starting with stablecoins, with the live dashboard at rwaradar.io.
- On the stablecoin side it surfaces total supply, transfer count, transfer amount and volume, mint and burn amounts, and daily snapshots of each.
- Every metric falls out of Transfer events, since mints and burns show up as transfers to and from the zero address.
- USDT is the exception, so the indexer reads its Issue and Redeem events directly for clean mint and burn numbers.
- The transfer and mint/burn logic lives in shared handlers, so every token reuses the same paths.
:::
Real-world assets have gone from a niche thing a few companies were poking at to one of the biggest sectors in crypto over the last few years.
This post isn't a market take, though. At Envio, my job is to build technical demos that actually use our products, so I decided to build something real, an open-source RWA dashboard backed by a HyperIndex metrics indexer you can run yourself. If you want to check whether the data lines up, or you want to build something similar, the whole thing is there to fork.
## Why stablecoins first
RWA is a huge bucket, so I had to pick a starting point. Stablecoins were the obvious one.
The goal for the stablecoin side of the dashboard is to surface the metrics that actually tell you something. Total supply, transfer count, transfer amount and volume, mint and burn amounts, and daily snapshots of all of it. Nothing exotic, just the numbers you'd want if you were tracking how a stablecoin is actually being used onchain.
Now that we've covered what the dashboard is supposed to do, let's get into the indexer and the logic behind it. That's the part that matters.
## The indexer
### Wiring up the handlers
I'm tracking a set of major stablecoins across a dozen chains to start. The full list lives in the [config.yaml](https://github.com/enviodev/rwa/blob/main/indexers/rwa-tokens/config.yaml) if you want to see exactly which ones.
For most of them, tracking `Transfer` events is enough. Every metric we care about falls out of transfers, including mints and burns, since those show up as transfers from or to the zero address. USDT is the exception. Its issue and redeem don't emit Transfers, so the indexer tracks its Issue and Redeem events directly. Bridged USDT on other chains does emit zero-address Transfers, so the Transfer handler covers it.
```ts
indexer.onEvent(
{ contract: "Stablecoins", event: "Transfer" },
async ({ event, context }) => {
await handleTransfer(event, context);
},
);
indexer.onEvent(
{ contract: "USDT", event: "Transfer" },
async ({ event, context }) => {
await handleTransfer(event, context);
},
);
indexer.onEvent(
{ contract: "USDT", event: "Issue" },
async ({ event, context }) => {
await handleSupplyChange(event, context, "mint");
},
);
indexer.onEvent(
{ contract: "USDT", event: "Redeem" },
async ({ event, context }) => {
await handleSupplyChange(event, context, "burn");
},
);
```
The point of pulling the logic out into `handleTransfer` and `handleSupplyChange` is reuse. Every token shares the same transfer logic, and the mint/burn path is shared too. The handlers themselves stay thin and just call into the abstracted functions.
### `handleTransfer`
This is the workhorse. It updates everything tied to a transfer.
First it does the fetching and parsing. It pulls the event params to derive the IDs, and grab the current state of the entities it's about to touch.
```ts
async function handleTransfer(
event: {
chainId: number;
srcAddress: string;
block: { timestamp: number };
params: { from: string; to: string; value: bigint };
},
context: EvmOnEventContext,
) {
const { from, to, value } = event.params;
const chainId = event.chainId;
const tokenAddress = event.srcAddress;
const timestamp = event.block.timestamp;
const currentDayId = Math.floor(timestamp / 86400);
const midnightTimestamp = currentDayId * 86400;
const isMint = from === ZERO_ADDRESS;
const isBurn = to === ZERO_ADDRESS;
const tokenId = `${chainId}_${tokenAddress}`;
const dayDataId = `${tokenId}_${currentDayId}`;
const fromBalanceId = `${tokenId}_${from}`;
const toBalanceId = `${tokenId}_${to}`;
const activeAddrId = `${tokenId}_${currentDayId}_${from}`;
const [
existingToken,
existingDayData,
fromBalance,
toBalance,
existingActiveAddr,
] = await Promise.all([
context.Token.get(tokenId),
context.TokenDayData.get(dayDataId),
!isMint
? context.HolderBalance.get(fromBalanceId)
: Promise.resolve(undefined),
!isBurn
? context.HolderBalance.get(toBalanceId)
: Promise.resolve(undefined),
!isMint
? context.DailyActiveAddress.get(activeAddrId)
: Promise.resolve(undefined),
]);
// continue the snapshot logic
}
```
The snapshot logic is where the only real trick is. Blocks give us a UTC timestamp, so to know whether a transfer belongs to a new day we just check whether its timestamp crossed midnight relative to the last day I recorded. If it's a new day, I start tracking a fresh `TokenDayData` entity. Everything else is the same shape as before: if it's a mint, bump supply up; if it's a burn, bump it down.
```ts
const lastDayId = existingToken?.lastDayId ?? currentDayId;
const isNewDay = currentDayId > lastDayId;
if (isNewDay) {
const stale = await context.DailyActiveAddress.getWhere({
token_id: { _eq: tokenId },
});
for (const entry of stale) {
context.DailyActiveAddress.deleteUnsafe(entry.id);
}
}
const isNewActiveAddr = !isMint && (isNewDay || !existingActiveAddr);
let newTotalSupply = existingToken?.totalSupply ?? 0n;
if (isMint) newTotalSupply += value;
if (isBurn) newTotalSupply -= value;
context.Token.set({
id: tokenId,
chainId,
address: tokenAddress,
totalSupply: newTotalSupply,
lastDayId: currentDayId,
});
context.TokenDayData.set({
id: dayDataId,
token_id: tokenId,
chainId,
date: midnightTimestamp,
dailyTotalSupply: newTotalSupply,
dailyMintAmount:
(existingDayData?.dailyMintAmount ?? 0n) + (isMint ? value : 0n),
dailyBurnAmount:
(existingDayData?.dailyBurnAmount ?? 0n) + (isBurn ? value : 0n),
dailyTransferAmount: (existingDayData?.dailyTransferAmount ?? 0n) + value,
dailyTransferCount: (existingDayData?.dailyTransferCount ?? 0) + 1,
dailyActiveAddresses:
(existingDayData?.dailyActiveAddresses ?? 0) + (isNewActiveAddr ? 1 : 0),
});
if (!isMint) {
context.HolderBalance.set({
id: fromBalanceId,
token_id: tokenId,
chainId,
holder: from,
balance: (fromBalance?.balance ?? 0n) - value,
firstTransferTimestamp:
fromBalance?.firstTransferTimestamp ?? BigInt(timestamp),
lastTransferTimestamp: BigInt(timestamp),
});
}
if (!isBurn) {
context.HolderBalance.set({
id: toBalanceId,
token_id: tokenId,
chainId,
holder: to,
balance: (toBalance?.balance ?? 0n) + value,
firstTransferTimestamp:
toBalance?.firstTransferTimestamp ?? BigInt(timestamp),
lastTransferTimestamp: BigInt(timestamp),
});
}
if (isNewActiveAddr) {
context.DailyActiveAddress.set({
id: activeAddrId,
token_id: tokenId,
chainId,
date: currentDayId,
address: from,
});
}
```
One thing worth calling out: on a new day I clear out the stale `DailyActiveAddress` entries for the token. Active addresses are a per-day count, so they don't carry over. Skipping mint senders from the active-address count is deliberate too, since the zero address isn't a real participant.
### `handleSupplyChange`
This one only exists for USDT's `Issue` and `Redeem`. The logic is mostly a slimmer version of handleTransfer, with one extra input, direction. The events themselves just hand you an amount, so the handler is the thing that decides whether it's a mint or a burn and passes that down.
```ts
async function handleSupplyChange(
event: {
chainId: number;
srcAddress: string;
block: { timestamp: number };
params: { amount: bigint };
},
context: EvmOnEventContext,
direction: "mint" | "burn",
) {
const { amount } = event.params;
const chainId = event.chainId;
const tokenAddress = event.srcAddress;
const timestamp = event.block.timestamp;
const currentDayId = Math.floor(timestamp / 86400);
const midnightTimestamp = currentDayId * 86400;
const tokenId = `${chainId}_${tokenAddress}`;
const dayDataId = `${tokenId}_${currentDayId}`;
const [existingToken, existingDayData] = await Promise.all([
context.Token.get(tokenId),
context.TokenDayData.get(dayDataId),
]);
const lastDayId = existingToken?.lastDayId ?? currentDayId;
const isNewDay = currentDayId > lastDayId;
if (isNewDay) {
const stale = await context.DailyActiveAddress.getWhere({
token_id: { _eq: tokenId },
});
for (const entry of stale) {
context.DailyActiveAddress.deleteUnsafe(entry.id);
}
}
let newTotalSupply = existingToken?.totalSupply ?? 0n;
if (direction === "mint") newTotalSupply += amount;
else newTotalSupply -= amount;
context.Token.set({
id: tokenId,
chainId,
address: tokenAddress,
totalSupply: newTotalSupply,
lastDayId: currentDayId,
});
context.TokenDayData.set({
id: dayDataId,
token_id: tokenId,
chainId,
date: midnightTimestamp,
dailyTotalSupply: newTotalSupply,
dailyMintAmount:
(existingDayData?.dailyMintAmount ?? 0n) +
(direction === "mint" ? amount : 0n),
dailyBurnAmount:
(existingDayData?.dailyBurnAmount ?? 0n) +
(direction === "burn" ? amount : 0n),
dailyTransferAmount: existingDayData?.dailyTransferAmount ?? 0n,
dailyTransferCount: existingDayData?.dailyTransferCount ?? 0,
dailyActiveAddresses: existingDayData?.dailyActiveAddresses ?? 0,
});
}
```
Notice it leaves the transfer fields untouched and only moves supply, mint, and burn. Issue and Redeem aren't transfers, so they shouldn't inflate transfer counts.
## What's next
That's the first step of the RWA dashboard, one indexer, with the logic and setup laid out. Tokenised US Treasuries, with NAV and yield tracking, are already in the same indexer, and I'll walk through those next.
If you want to dig into the code, the [stablecoins indexer is here](https://github.com/enviodev/rwa/tree/main/indexers/rwa-tokens), and the live dashboard is at [rwaradar.io](https://rwaradar.io/). If you're building in the RWA space and want to compare notes, reach out.
## Frequently Asked Questions
### How does the indexer track stablecoin mints and burns?
For most of the stablecoins, tracking Transfer events is enough. Mints and burns fall out of transfers, since they show up as transfers from or to the zero address, so total supply moves up on a mint and down on a burn without needing dedicated events.
### Why is USDT handled differently from the other stablecoins?
USDT is the exception. To get clean mint and burn numbers for it, the indexer tracks its Issue and Redeem events directly through handleSupplyChange, which reads the amount and decides whether it's a mint or a burn. It leaves the transfer fields untouched and only moves supply, mint, and burn, since Issue and Redeem aren't transfers and shouldn't inflate transfer counts.
### How does the indexer decide when a new day begins for the snapshots?
Blocks give a UTC timestamp, so the handler checks whether a transfer's timestamp crossed midnight relative to the last day it recorded, deriving the current day as Math.floor(timestamp / 86400). When it's a new day, it starts tracking a fresh TokenDayData entity.
### Why are mint senders skipped in the daily active address count?
Active addresses are a per-day count, so they don't carry over, and on a new day the stale entries for the token are cleared. Mint senders are skipped deliberately, since a mint comes from the zero address, which isn't a real participant and would otherwise misrepresent daily activity.
### Why are handleTransfer and handleSupplyChange pulled into shared functions?
The point is reuse. Every token shares the same transfer logic, and the mint and burn path is shared too, so the event handlers stay thin and just call into the abstracted functions.
### What metrics does the stablecoin dashboard surface?
It surfaces total supply, transfer count, transfer amount and volume, mint and burn amounts, and daily snapshots of all of it, which are the numbers that show how a stablecoin is actually being used onchain.
## Build With Envio
Envio is a real-time multichain blockchain indexer that turns onchain events into a queryable GraphQL API. Supports any EVM chain, plus Solana and Fuel. Use Envio Cloud or self-host. If you're building onchain, come talk to us about your data needs.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+BeS5ihVUFONjNGFk) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Envio Developer Update July 2026
> HyperIndex released four versions from v3.3.0 to v3.4.0, built for huge multichain and factory contract indexers, with unlimited onEvent handlers, a per-chain Effect API, per-entity ClickHouse tuning, and a test framework 12x faster. We released the largest public Polymarket dataset ever, previewed Envio Analytics in alpha, brought Solana indexing to the instruction level, and added three new showcase apps.
 July was a big month for HyperIndex. Four releases took it from v3.2.1 to v3.4.0, built around huge multichain and factory contract indexers, unlimited `onEvent` handlers, per-chain effect caching, and a testing framework that runs 12x faster. We also published the largest public Polymarket dataset ever released, 2.74 billion onchain records free under CC-BY, and began previewing Envio Analytics, an alpha that puts natural-language querying and generated dashboards on top of indexed data.
Alongside that, Solana indexing landed at the instruction level, three new showcase apps went live covering tokenised stocks, Solana DEX activity and Safe multisigs, and we launched a new changelog so every release is tracked in one place.
Let's dive in!
## HyperIndex v3.4.0 & v3.3.0
Four releases this month, from v3.3.0 through to v3.4.0. The theme was scale: large multichain and factory contract indexers, more control over caching and storage, and a much faster feedback loop during development.
### v3.4.0
#### Unlimited `onEvent` Handlers
Previously only a single `onEvent` handler was allowed per event definition, which made it impossible to run different handlers with different filters against the same event. Since v3.4.0 there is no such restriction, so you can handle every ERC20 Transfer in one handler and a USDC-only slice in another.
```typescript
import { indexer } from "envio";
// Track all ERC20 Transfers
indexer.onEvent(
{ contract: "ERC20", event: "Transfer", wildcard: true },
async ({ event, context }) => {},
);
// And a separate handler for USDC-only is also possible
indexer.onEvent(
{ contract: "ERC20", event: "Transfer", wildcard: true, where: {
params: [
{ from: USDC_ADDRESS },
{ to: USDC_ADDRESS },
],
},
},
async ({ event, context }) => {},
);
// And contractRegister can have a different `where` filter for the same event
indexer.contractRegister(
{ contract: "ERC20", event: "Transfer", wildcard: false /* non-wildcard for contract register */ },
async ({ event, context }) => {},
);
```
Note that this can result in a single log being processed by different handlers and counted as multiple events in the metric. The same log execution is guaranteed to follow handler registration order inside a file.
#### Per-Entity ClickHouse Tuning
Set partitioning, ordering, and TTL on an entity through the `@storage` directive, so your analytic queries run faster.
```graphql
type Transfer @storage(clickhouse: {
partitionBy: "toYYYYMM(timestamp)",
orderBy: ["timestamp"],
ttl: "timestamp + INTERVAL 2 YEAR"
}) {
id: ID!
timestamp: Timestamp!
}
```
Reach out to us for ClickHouse support on [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service).
#### Test Indexer Got 12x Faster
The v3 testing framework now runs as fast as it did before the v3 upgrade, with all the new v3 features on top.
**Indexer tests are now 12x faster.**
If your setup or your agents are not using it yet, the [Testing Guide](https://docs.envio.dev/docs/HyperIndex/testing) is the place to start.
### v3.3.1
v3.3.1 added an `indexer-local-parallel` skill for running multiple indexers locally without collisions, along with reorg threshold handling for indexers with 10M+ addresses, ClickHouse initialisation in replicated mode, and wildcard events always firing a handler even when the same log is consumed by another non-wildcard event.
### v3.3.0
v3.3.0 is built for huge multichain and factory contract indexers, with faster backfill, lower memory usage, better stability, and lower latency at the head.
#### Per-Chain Effect API
The Effect API takes a new `crossChain` option, which controls whether an effect's input is cached and rate-limited globally or separately per chain. It defaults to `true`, a single shared cache across every chain, which suits chain-agnostic calls like token metadata or price by symbol. Set it to `false` and each chain gets its own cache and rate-limit budget, with `context.chain.id` available in the effect handler.
```typescript
// Chain-specific result → crossChain: false, access context.chain.id
const getBalance = createEffect(
{
name: "getBalance",
input: S.string,
output: S.bigint,
rateLimit: false,
crossChain: false,
},
async ({ input: account, context }) =>
rpcFor(context.chain.id).getBalance(account),
);
```
Cross-chain effects can only call other cross-chain effects, since they have no specific chain context, while chain-scoped effects can call either type. Be aware that per-chain effects use a different cache structure, so switching the option requires a cache reset or migration.
Read more in the [Effect API docs](https://docs.envio.dev/docs/HyperIndex/effect-api).
#### Custom HTTP Headers For RPC
Authenticated RPC endpoints now come straight from your config, so bearer tokens and provider auth live alongside everything else with env var interpolation.
```yaml
chains:
- id: 1
rpc:
- url: https://eth-mainnet.your-rpc-provider.com
for: sync
headers:
authorization: "Bearer ${ENVIO_RPC_1_TOKEN}"
```
#### RPC Source Enhancements
The RPC source picked up two capabilities previously only possible with HyperSync: event handlers using an `or` union for `params` filters in `where`, and indexers running multiple `wildcard` events. We also improved how the RPC source handles a provider's response-too-large errors.
#### Nested Env Vars Interpolation In Config
Environment variable interpolation now supports nested fallback values in defaults, so a default can itself reference another environment variable.
See the full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## The Largest Public Polymarket Dataset Ever Released
 We released the complete onchain Polymarket dataset on Hugging Face, free under CC-BY-4.0. It covers every trade, position and payout from the 2020 launch through April 2026, indexed straight off Polygon with HyperIndex.
Most Polymarket datasets stop at trades. This one carries the entire onchain lifecycle, every CLOB fill plus every conditional-token split, merge, redemption and resolution, all the way back to the 2020 AMM era. That is what lets you reconstruct real positions, realised PnL, and exactly who got paid when a market resolved. You can query the whole thing from your terminal with DuckDB without downloading a single file, because it pulls only the byte ranges it needs.
**2.74 billion records, 1.17 billion CLOB trades, $59.9B in lifetime volume, and 2.63 million trader wallets, across 127GB of Parquet.**
None of it is a black box. The open-source indexers that produced it are public, so every number is reproducible from scratch.
Explore the dataset here: [Polymarket onchain dataset on Hugging Face](https://huggingface.co/datasets/moose-code/polymarket-onchain-v1)
## Envio Analytics, Now in Alpha
 HyperIndex now indexes Solana programs at the instruction level. You select the programs and instructions you care about, and HyperIndex decodes them, arguments and accounts, using your Anchor IDL or an inline schema, then writes the results to Postgres with an auto-generated GraphQL API.
Inner instructions (CPIs), token balances and balance changes, transaction metadata and program logs are all available. It is powered by [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) for Solana, the same data engine behind our EVM indexing, so historical backfills are fast and you never touch an RPC node for the bulk of indexing. Solana support is still experimental and TypeScript-only, and it is a good time to help shape it, so come and say hello on [Discord](https://discord.gg/envio) if you are building there.
Read the docs: [Solana indexing with HyperIndex](https://docs.envio.dev/docs/HyperIndex/solana)
## Robinhood's Tokenised Stocks Live on v4.xyz
 Tokenised stocks issued by Robinhood trade around the clock as Uniswap v4 pools, and you can now watch them live at [v4.xyz/stocks](https://v4.xyz/stocks). GME, NVDA and TSLA are priced from onchain swaps, with volume, TVL and trade counts per stock.
**30,771 trades in a single 24 hour window.**
v4.xyz is the central hub for exploring Uniswap V4 hook deployments, pool data and onchain analytics, powered by HyperIndex across 15 chains. The indexer behind it is open source and open to contributions, so you can index Robinhood stocks and much more yourself.
Check it out on GitHub: [the open source Uniswap v4 indexer](https://github.com/enviodev/uniswap-v4-indexer)
More on the showcase page: [v4.xyz on the Envio showcase](https://docs.envio.dev/showcase/v4-xyz)
## Envio vs The Graph
 A sourced, head-to-head comparison of the two, covering sync speed, handler language, multichain support and reorg handling, then what switching actually involves.
Sync speed is the clearest gap. In the independent Sentio Uniswap V2 Factory benchmark, HyperIndex finished in 8 seconds against 19 minutes for The Graph. On the Sentio LBTC workload it finished in 3 minutes against 3 hours 9 minutes.
**142x faster on the Sentio Uniswap V2 Factory workload.**
Full methodology is on our [benchmarks page](https://docs.envio.dev/docs/HyperIndex/benchmarks), with the raw runs in the [open-indexer-benchmark repo](https://github.com/enviodev/open-indexer-benchmark).
Read the comparison: [Envio vs The Graph](https://docs.envio.dev/blog/envio-vs-the-graph)
## SolSwaps, a Firehose of Solana DEX Activity
 No RPC, no archive node, no database. SolSwaps streams every DEX swap on Solana into a single live view, covering the network's busiest venues including Jupiter, Pump.fun, Orca and Raydium.
The dashboard tracks swaps per second, estimated SOL moved, aggregated fees, and a running list of the 25 biggest trades as they land, giving traders, researchers and builders a fast picture of where volume is flowing across Solana. It is built entirely on HyperSync, with no infrastructure for you to run.
See it live: [SolSwaps on the Envio showcase](https://docs.envio.dev/showcase/solswaps)
## How to Stream Onchain Events to an AI Trading Agent
 Building an AI trading agent? The interesting question is not the model, it is the feed.
An agent needs onchain events fast, structured, and correct through reorgs, and raw RPC gives you none of that out of the box. This guide shows how to wire HyperIndex in as the feed layer, with the schema, queries and reorg handling taken from the published Polymarket reference indexer. It also covers the part that matters most for anything moving money: head-of-chain state is provisional, so act on events from finalised blocks.
Read the full tutorial: [How to stream onchain events to an AI trading agent](https://docs.envio.dev/blog/stream-onchain-events-ai-trading-agent)
## Safescan, One Explorer for Every Safe
 Safescan is a multichain explorer purpose-built for Safe multisig wallets. Search by safe address, owner address or transaction hash, and watch creations, proposals, confirmations and executions land live.
Powered by HyperIndex, it indexes Safe wallet creation events, transaction proposals, confirmations and executions across 18 chains in real time and aggregates them into a single interface. At the time of writing it covers more than 5.1 million Safes and 45.7 million executed transactions.
Explore it here: [Safescan on the Envio showcase](https://docs.envio.dev/showcase/safescan)
## How to Build an Open Source RWA Stablecoin Dashboard
 One event type, all your stablecoin metrics. Total supply, transfer count, transfer amount and volume, mint and burn amounts, and daily snapshots of each, all derived from Transfer events, since mints and burns show up as transfers to and from the zero address. USDT is the exception, so the indexer reads its Issue and Redeem events directly.
The dashboard is backed by a HyperIndex indexer you can run yourself, and the whole thing is open source. Fork it and build your own.
More here: [How to build an open source RWA stablecoin dashboard](https://docs.envio.dev/blog/how-to-build-rwa-dashboard)
## A New Changelog Page
 Our new changelog is live. Every HyperIndex release, feature, fix and improvement is now tracked in one place, so you can see what changed and when without digging through release tags.
Take a look: [the Envio changelog](https://envio.dev/changelog)
## Wildcard Indexing and Topic Filtering
 Index every ERC20 Transfer onchain without a single contract address. Wildcard indexing matches events by signature rather than by address, so you can capture events from factory-deployed contracts, or from every contract implementing a standard.
Add topic filtering on top to keep only the events you actually want. Both work on HyperSync and RPC.
Learn more here: [Wildcard indexing and topic filtering](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing)
## Stargate's Bus Routes, Visualised
 Co-founder Jonjon shared a real-time visual of all the "bus routes" on Stargate Finance, powered by Envio, with Base and Arbitrum comfortably the busiest route.
The distinction it makes visible is a neat one. A taxi transfer leaves immediately, while a bus transfer waits at a stop on the source chain until other transfers board alongside it.
[See original post on X](https://x.com/jonjonclark/status/2079537502902186069)
## Plans, Pricing and Educational Discounts
 Envio Cloud runs your indexer without you touching infrastructure, from a free Development plan, to Production with static endpoints and zero-downtime deploys, to Dedicated for unlimited scale and a custom SLA.
We also offer educational discounts for students, academic researchers and educational institutions, available for university courses, academic research and non-commercial student projects. Eligibility is verified with a valid academic email or proof of enrolment, and the discount depends on your use case and project scope. Reach out to the team to apply.
For more information, see our [pricing page](https://envio.dev/pricing).
## Migrating From The Graph Without a Rewrite
 Migrating a subgraph to HyperIndex does not mean starting over. AssemblyScript is a subset of TypeScript, so your event parsing and business logic copy across verbatim, and what changes is mostly the wiring rather than the code doing the work.
Three things change in a well-defined way: `subgraph.yaml` becomes `config.yaml`, your schema sheds the `@entity` decorator, and handlers swap `Entity.save()` for `context.Entity.set()` with async/await. Existing subgraph queries keep working through our [query converter](https://docs.envio.dev/docs/HyperIndex/query-conversion), and the [Indexer Migration Validator](https://github.com/enviodev/indexer-migration-validator) diffs entity state between both endpoints before you cut over.
See the side-by-side migration: [the drop-in subgraph replacement walkthrough](https://docs.envio.dev/blog/drop-in-subgraph-replacement)
## Featured Developer: Geauser
 This month's featured developer is Geauser, a developer and founder currently working on [Umi](https://umi.bot/), a beginner-friendly web-based NFT minting bot. He describes himself as having a renaissance profile, touching a bit of everything rather than just NFTs, though NFTs are where the focus sits right now, and he has been building on HyperSync for around a year and a half.
**What Geauser had to say about Envio:**
> ***"I've been using HyperSync from Envio for almost a year and a half now. It basically solves all my "what happened in the past" problems. What makes HyperSync so great is that I can ask those questions and get answers in milliseconds or seconds rather than minutes. It lets me drastically optimise Umi and run historical analysis across multiple chains without worrying about running my own indexer or dealing with slow archival RPCs that have limited query capabilities. One example: sometimes I need to know if a user minted a particular NFT in a given phase, so I can decide whether to let them mint another one if the collection allows it. With HyperSync, I can check that, in a few hundred milliseconds, which makes my code much cleaner. On top of that, it has wide chain support, so it's perfect for a multichain product like mine. It also lets me run historical analysis, like how Umi performed during a given mint. It's an incredible tool, and I couldn't recommend it enough. You can be sure I'll use Envio in my next ventures as well."***
Well done, Geauser. Be sure to follow him on [X](https://x.com/geauser) and check out his [GitHub](https://github.com/geauser) to stay up to date with his latest developments.
## Playlist of the Month
 ▶ [Open Spotify](https://open.spotify.com/playlist/5rIdUUbA4jvGWKuI8J6l4T?si=9320cbaddb8543e5)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you're working on a Web3 project and want a smoother development process, Envio's got your back(end). Check out our docs, join the community, and let's talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+5mI61oZibEM5OGQ8) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# How to Get Polymarket Trade Data
> Query the largest public Polymarket dataset with DuckDB. 1.17B CLOB fills, 2.63M makers, $59.9B volume, free on Hugging Face, or run our open indexer.
 :::note TL;DR
- Every Polymarket CLOB fill from 2020 to April 2026 is free on Hugging Face under CC-BY-4.0. 1.17 billion fills, 2.63 million makers and $59.9 billion of volume. At the time of writing that is the largest public Polymarket dataset available.
- You query it with DuckDB over HTTPS. No download, no Envio API token, no Polygon node.
- For data at head, both Polymarket indexers are open source HyperIndex projects. Clone the [v2 indexer](https://github.com/enviodev/polymarket-v2-indexer) for live v2 markets, or the [v1 indexer](https://github.com/enviodev/polymarket-indexer) for both generations, and run it locally or on [Envio Cloud](/docs/HyperIndex/hosted-service). The v1 indexer is what produced the snapshot.
- 2 things that catch people out. Addresses are EIP-55 checksummed, so wrap filters in `lower()`. And an account can trade from a proxy *and* directly from its signer, so query both or you can miss 99.7% of a wallet with no error, as Example 3 shows.
- The worked examples are Co-Founder Jonjon's findings, with the queries that check them against the data. All of them reproduce.
:::
2,684,676 wallets hold a position on Polymarket. Roughly 81% of them finished within $1,000 of where they started. 21 cleared more than $10 million each, and the top 100 took $853 million between them. Those figures are from Co-Founder [Jonjon](https://x.com/jonjonclark)'s [realized-PnL distribution](https://x.com/jonjonclark/status/2047685184934281714) and his [Top Hundred series](https://x.com/jonjonclark/status/2049067586046816561).
Polymarket settles on Polygon, and a position there is just a token that pays $1 if the outcome happens and $0 if it does not, so entry, exit and settlement all leave a record onchain that outlives the market itself. The site shows you the odds. The chain shows you who took the other side of them, what they paid, and how it ended.
We indexed every order-book fill Polymarket has settled from its 2020 launch through 24 April 2026, plus the positions, splits, merges and redemptions around them, and published the lot as a free [dataset](https://huggingface.co/datasets/moose-code/polymarket-onchain-v1) on Hugging Face under CC-BY-4.0. That is 1.17 billion fills on the central limit order book, the CLOB, plus 2.63 million distinct makers and $59.9 billion of lifetime volume. Reading it needs no indexer, no API key and no Polygon node. It needs [DuckDB](https://duckdb.org/docs/installation/) and one query.
We start with the snapshot, since it needs nothing installed. Then we walk through 5 of the wallets pulled out of these tables, with queries you can run yourself to check every number. If you want markets at head rather than history, our [open indexers](https://github.com/enviodev/polymarket-v2-indexer) are the last section.
## How to Query the Public Snapshot with DuckDB
The [public v1 snapshot](https://huggingface.co/datasets/moose-code/polymarket-onchain-v1) is Polygon data indexed with HyperIndex and released under [CC BY 4.0](https://creativecommons.org/licenses/by/4.0/). You can use it for anything, including commercially, subject to the licence terms, which include crediting Envio and linking the licence.
Every CLOB fill is in it, plus splits, merges, redemptions, resolutions, and trades from the FPMM era, the automated market maker Polymarket used before the order book, going back to Sep 2020. It is a point-in-time export, not a live feed. `SNAPSHOT.json` records the cutoff as Polygon block 85,948,287 on 24 April 2026. Anything after it needs the live indexer.
 *`SNAPSHOT.json` on Hugging Face. Cutoff for the v1 snapshot.*
 *Hugging Face dataset card. What is inside the v1 snapshot.*
| Metric | Value | How |
|---|---|---|
CLOB fills (order_filled) |
1,172,658,611 | count(*) |
| Distinct CLOB makers | 2,630,334 | count(DISTINCT maker) on order_filled |
| Lifetime CLOB volume | $59.899B | cash-leg sum, USDC 6 decimals |
user_position rows |
303,955,230 | count(*) |
Distinct user_position users |
2,684,676 | count(DISTINCT user) |
wallet.parquet rows |
7,362,437 | proxy + Safe rows. Not the trader count. |
 *Maker BUY price distribution from the original post. Example 1.*
#### Step 1: Pull the fills
```sql
SELECT count(*)
FROM 'hf://datasets/moose-code/polymarket-onchain-v1/order_filled/**/*.parquet'
WHERE lower(maker) = '0x2005d16a84ceefa912d4e380cd32e7ff827875ea'
OR lower(taker) = '0x2005d16a84ceefa912d4e380cd32e7ff827875ea';
-- 2698796
```
#### Step 2: Pull the positions
```sql
SELECT count(*), sum(CAST(realizedPnl AS DOUBLE)) / 1e6 AS realized_usd
FROM 'hf://datasets/moose-code/polymarket-onchain-v1/user_position.parquet'
WHERE lower(user) = '0x2005d16a84ceefa912d4e380cd32e7ff827875ea';
-- 111318, 8553975.64
```
`user_position` carries position-level realized PnL, which on its own does not reach the $24M headline. The post breaks that $24M into 3 parts. Roughly $8M of riskless profit from the merge engine, 41,642 merges across $100.2 million of merge volume. Longshot redemptions, where bids resting at a cent or two occasionally win and redeem at $1. And post-event taker sells of tokens that have clearly won, at prices near $0.99. The merge activity has its own table in the snapshot, `merge/`.
[See original post on X](https://x.com/jonjonclark/status/2049067586046816561)
### Example 2: NBA Live Model, and the Same-Day Correction
This wallet watches NBA games live, updates a probability model as the score moves, and buys the side its model says has the game in hand.
The post links [`0xdb15373c33adb64de90f23f90c0d8b86ef65497b`](https://polygonscan.com/address/0xdb15373c33adb64de90f23f90c0d8b86ef65497b). In the snapshot that address is a signer with no fills of its own, and the figures below land on its proxy, [`0xbddf61af533ff524d27154e589d2d7a81510c684`](https://polygonscan.com/address/0xbddf61af533ff524d27154e589d2d7a81510c684). That is the one to query.
The article reports $23.6M realized, 95.4% (417/437 closed bets), 116,086 fills, $60.3M volume, 523 markets, and an active period of 168 days, present on 79% of them. That 79% is 133 days of actual trading, which is what the snapshot shows.
The same-day correction says 95% is a selection artifact. Across all 864 positions opened, 47.3% were on the eventual winner. The closed-bets count drops 427 positions flattened pre-resolution at about zero PnL. Its read on the real edge is tiny mispricing at the bid, flattening bad bets fast enough to turn 38 cent losses into 2 cent ones, and holding winners to $1. What makes it work is how fast it gets out of a losing position, not what it predicts.
 *Activity dashboard from the original post. Example 2.*
#### Step 1: Pull the fills
```sql
SELECT count(*)
FROM 'hf://datasets/moose-code/polymarket-onchain-v1/order_filled/**/*.parquet'
WHERE lower(maker) = '0xbddf61af533ff524d27154e589d2d7a81510c684'
OR lower(taker) = '0xbddf61af533ff524d27154e589d2d7a81510c684';
-- 116086
```
#### Step 2: Pull the positions
```sql
SELECT count(*), sum(CAST(realizedPnl AS DOUBLE)) / 1e6 AS realized_usd
FROM 'hf://datasets/moose-code/polymarket-onchain-v1/user_position.parquet'
WHERE lower(user) = '0xbddf61af533ff524d27154e589d2d7a81510c684';
-- 1301, 23630117.10
```
Both figures land on the numbers in the post, 116,086 fills and $23.6M realized. Note that `user_position` holds one row per token the wallet ever touched, so its 1,301 rows are not the same measure as the 864 positions opened in the correction, or the 437 that reached resolution.
[See original post on X](https://x.com/jonjonclark/status/2049450963908415800)
[Same-day correction](https://x.com/jonjonclark/status/2049492239940739477)
### Example 3: 2 Wallets, and an Account With 2 Addresses
This example covers 2 wallets. The one from the [UMA Gap article](https://x.com/jonjonclark/status/2052061246963220846), which runs a settlement sweep and a basket arb from a single address, and the one from the [Day 3 post](https://x.com/jonjonclark/status/2049831392310133035), which runs the basket arb and is where querying the snapshot gets interesting.
#### The UMA Gap Wallet
[`0x9b979a065641e8cfde3022a30ed2d9415cf55e12`](https://polygonscan.com/address/0x9b979a065641e8cfde3022a30ed2d9415cf55e12). In `wallet.parquet` it is a proxy, controlled by signer [`0x8Dcd34aeF17AB9f121d5198E80d8d683a2274EAE`](https://polygonscan.com/address/0x8Dcd34aeF17AB9f121d5198E80d8d683a2274EAE).
The article's own summary of it lists leaderboard rank 26, $8,049,419 of lifetime realized PnL, 61,095 fills across 4,862 markets in 12 categories, $84.37M of volume, 47,754 buys at an average price of $0.97, first fill on 13 May 2023, and 93.1% of every buy landing above 95 cents. In the article's words, that last line is the whole strategy in one number. The chart below plots the same 47,754 buys, cut at $0.97 rather than 95 cents, which puts 92% of them above the line.
 *Every buy by the wallet, by price. The bars at the right-hand edge are the strategy. From the UMA Gap article.*
This wallet only buys things the market has already decided. A Polymarket binary has a listed close time, but the cash payout only fires once UMA's optimistic oracle clears its dispute window, which is 2 hours at minimum and often a day. Inside that window the winning token still has a book, and it trades at $0.99 or $0.998 rather than $1.00, because the cash has not landed yet. This wallet is the patient buyer. The article calls it the patience premium, paid roughly 0.8 cents per dollar of near-par exposure for being willing to wait for the protocol to catch up.
The article breaks those near-par buys down by when they landed relative to the market's listed close.
| When the fill landed | Buys at >$0.97 | Volume |
|---|---|---|
After market_end, event already over | 26,970 | $37.6M |
| Within 1h before end | 562 | $0.59M |
| 1 to 6h before end | 2,843 | $4.13M |
| 6 to 24h before end | 1,077 | $1.94M |
| 1 to 7d before end | 10,457 | $15.18M |
| >7d before end | 2,025 | $10.39M |
| Metric | Value |
|---|---|
| Total positions | 67,900 |
| Positions with non-zero PnL | 66,596 |
| Wins | 33,222 |
| Losses | 33,374 |
| Win rate by position | 49.9% |
| Net realized PnL | $2,382,793 |
| Average net PnL per closed position | $35.79 |
| Total redemptions claimed | 84,103 events, $78,984,643 |
| Example | PnL | Fills | What |
|---|---|---|---|
1. 0x2005…75easigner 0x5d4f…2edc |
~$24M | 2,698,796 | YES+NO merge. No prediction. |
2. 0xbddf…c684signer 0xdb15…497b |
$23.6M | 116,086 | NBA model. 95.4% is a closed-bet filter. |
3a. 0x9b97…5e12signer 0x8Dcd…4EAE |
$8.05M | 61,095 | Settlement sweep and basket arb, one address. |
3b. 0xCF3b…5107proxy 0xfe96…e962 |
$7.18M | 36,740 | Election basket arb. Signer trades directly. |
4. 0x63CE…Ba9a |
$2,382,793 | 7,638,691 | Short-dated MM. 49.9% WR. |
| Repo | Covers | When to use it |
|---|---|---|
| v2 indexer | CTF Exchange V2, pUSD, collateral adapters, rewards | You want live v2 markets at head |
| v1 indexer | v1 CLOB and FPMM, the 8 original subgraphs merged into one, plus the same v2 contracts | You want v1 as well as v2, or to rebuild the snapshot from chain and verify it |
 We are excited to open Solana HyperSync support up for early access. Indexing Solana programs at the instruction level is in beta on top of it, and the Rust client has its query API locked at 0.2.0. If you are building on Solana we would love you to try it.
Elsewhere, seven HyperIndex releases took us from v3.5.0 to v3.9.0. Factory indexers stopped hitting a wall at around 8 million addresses, multichain projects can isolate entities per chain with a single flag, and we announced HyperPipe, which streams decoded onchain data to any destination from one YAML file. We also started letting people run unmodified subgraphs on HyperIndex. We will be at Devcon in Mumbai and Solana Breakpoint in London, both in November.
Let's dive in!
## Introducing Solana HyperSync
 HyperSync for Solana is open for early access. It is the same data engine behind our EVM indexing, serving slots, transactions, instruction calls, logs, account activity and rewards from one endpoint, so historical backfills are fast and you never touch an RPC node for the bulk of indexing.
On top of it, HyperIndex indexes Solana programs at the instruction level, now in beta. You select the programs and instructions you care about, HyperIndex decodes them, arguments and accounts, using your Anchor IDL or an inline schema, and writes the results to Postgres with an auto-generated GraphQL API.
```bash
pnpx envio init
```
Choose Solana when prompted, then pick a starter template, either a Metaplex NFT instruction indexer or a minimal slot handler.
### Two ways to index Solana
| Approach | API | Data source | Use it for |
| --- | --- | --- | --- |
| Instruction handlers | `indexer.onInstruction` | HyperSync | The main path. Decode and index program instructions such as swaps, deposits, mints and transfers, including inner and CPI instructions, with token balance changes. |
| Slot handlers | `indexer.onSlot` | RPC via the Effect API | Per-slot orchestration, time-series snapshots, or pulling extra data from RPC on a schedule. |
Most indexers use instruction handlers. Slot handlers are for running logic on a slot cadence rather than reacting to a specific instruction.
### Coming from EVM
The shift is mostly vocabulary.
| EVM | Solana |
| --- | --- |
| Contract + ABI | Program + IDL |
| Event (`onEvent`) | Instruction (`onInstruction`) |
| `event.params` | `instruction.params.args` |
| Topic0 / event signature | Instruction discriminator |
| Block (`onBlock`) | Slot (`onSlot`) |
| Hex addresses | Base58 addresses |
| `start_block` = block number | `start_block` = slot number |
As of v3.9.0 the HyperSync endpoint is derived from your `chain.id` automatically, so `experimental.hypersync_config` is optional. Each endpoint serves history back to its own floor slot, and that floor moves forward over time, so pick your `start_block` deliberately.
### What works today
IDL-aware decoding against a standard Anchor IDL, legacy or 0.30 and up, with an inline schema as the fallback when there is no IDL. Inner instructions (CPIs) decode the same way as top-level ones, with a full instruction-address path so you can reconstruct the call tree. Pre and post SPL Token and Token-2022 balances come per transaction, so you get net token movement without indexing every transfer. Transaction metadata and per-instruction program logs are available through field selection, and local dev, GraphQL and Envio Cloud work exactly as they do on EVM.
### Retention and clients
Only a rolling window of recent slots is retained, so anchor your ranges to `GET /height` rather than hard-coding a lower bound. The Rust client `hypersync-client-solana` reached 0.2.0 this month with its query API locked.
### Tell us what you need
Early access means talking to us. Get in touch with the team on [Discord](https://discord.gg/envio) and we will get you set up. Share a sample transaction signature or program ID and we will map it to a concrete query path, and tell us what you are building because that is what we are prioritising against.
Read the docs: [Indexing on Solana](https://docs.envio.dev/docs/HyperIndex/solana) and [Solana HyperSync](https://docs.envio.dev/docs/HyperSync/solana)
Prefer clicking to typing? The [Query Builder](https://builder.hypersync.xyz/#solana) builds Solana queries visually.
## HyperIndex v3.5.0 -> v3.9.0
### v3.9.0
#### Per-Chain Entities Get Postgres Partitions
Set `disable_default_cross_chain: true` and per-chain entities are now split into Postgres partitions, which speeds up reads and writes when a query targets one chain. The automatically added `chainId` column can also be used in your ClickHouse `orderBy` configuration.
#### Support One Address for Multiple Contracts
Handy when the factory addresses are not yours to control. The same address can now be routed to more than one contract definition.
```yaml
name: shared-address-routing
contracts:
- name: Token
events:
- event: Transfer(address indexed from, address indexed to, uint256 value)
- name: Vault
events:
- event: Transfer(address indexed from, address indexed to, uint256 value)
- event: Deposit(address indexed owner, uint256 amount)
chains:
- id: 1
contracts:
- name: Token
address: "${sharedAddress}"
- name: Vault
address:
- "${sharedAddress}" # An error before, now a legit case
- "${vaultOnlyAddress}"
```
#### Nullability with `@derivedFrom`
Derived fields now accept any nullability combination, which matches subgraph behaviour more closely and matters if you are running a subgraph on HyperIndex.
```graphql
type Parent {
id: ID!
strict: [Child!]! @derivedFrom(field: "parent")
nullableList: [Child!] @derivedFrom(field: "parent")
nullableItems: [Child]! @derivedFrom(field: "parent")
nullableBoth: [Child] @derivedFrom(field: "parent")
}
type Child {
id: ID!
parent: Parent!
}
```
#### Clearer Schema Validation Errors
Validation errors on `schema.graphql` now give an exact location, a concise description and a suggested fix.
```
schema.graphql:7:13: Invalid `@index` on `Second`:
`missing` is not a column of the entity.
Available columns: `id`, `value`.
```
#### Solana Config Gets Simpler
`experimental.hypersync_config` is now optional and derived from `chain.id`, `instruction.args` is no longer optional because instructions that fail to decode are skipped, and the SVM handler and data types are finalised.
### v3.8.0
#### Hiding Entities From the GraphQL API with `@internal`
Some entities exist for the indexer, not for the consumer. Bookkeeping state, checkpoints, and anything sensitive you would rather not expose publicly. Mark an entity `@internal` and it stays out of the GraphQL API entirely, with no queries, no relationships, and no introspection entry, while remaining fully usable in your handlers.
```graphql
type Secret @internal {
id: ID!
note: String!
}
```
An exposed entity cannot reference an `@internal` one, because that relationship could never be served over GraphQL. Either mark the referencing entity `@internal` too, or store a plain id field instead of a relationship.
More in the [schema docs](https://docs.envio.dev/docs/HyperIndex/schema).
#### Skipping Indexes for ClickHouse
Even more control to optimise query performance for your ClickHouse storage, configured per entity alongside partitioning and sort keys.
```graphql
type Transfer @storage(
clickhouse: {
partitionBy: "toYYYYMM(timestamp)"
orderBy: ["chainId", "timestamp"]
skippingIndexes: [
{
name: "idx_from"
expr: "fromAddress"
type: "bloom_filter(0.01)"
granularity: 4
},
{
name: "idx_to"
expr: "toAddress"
type: "bloom_filter(0.01)"
}
]
}
) { ... }
```
#### Breaking: Solana API Changes
We are getting closer to a stable Solana release, and this version lands most of the API we intend to keep. The `onInstruction` API had a large overhaul for more correct and descriptive types, `field_selection` for Solana moved to the per-handler `fields` option introduced in v3.7.0, and Solana chains now require an explicit `id: solana` in `config.yaml` or a custom number of your choosing. The internal Solana chain id also moved from 0 to 7565164 to avoid colliding with Fuel. The Test Indexer now supports the `simulate` API with Solana instructions.
See the [Solana section above](#introducing-solana-hypersync) for where support stands.
### v3.7.0
#### Per-Handler Field Selection
A new way to declare the transaction and block fields your handler logic uses, listed under a `fields` option right where you consume them. It is type-safe, and we fetch and decode only the fields you list.
```ts
indexer.onEvent(
{
contract: "MyContract",
event: "Transfer",
fields: {
transaction: ["hash", "from"],
block: ["timestamp"],
},
},
async ({ event, context }) => {
event.transaction.hash; // string
event.block.timestamp; // number
// Type error, not listed in fields:
event.transaction.gasUsed;
},
);
```
The [`field_selection`](https://docs.envio.dev/docs/HyperIndex/configuration-file) option in config is still supported with no breaking changes, but `fields` in handlers is the recommended approach going forward.
#### More Fields on the RPC Source
Indexers running on the RPC source can now select 20 more transaction fields and 15 more block fields, including `gas`, `nonce`, `status`, `effectiveGasPrice` and the L1 fee fields that matter on L2s.
**Transaction** (20): `gas`, `nonce`, `v`, `r`, `s`, `yParity`, `type`, `maxFeePerBlobGas`, `blobVersionedHashes`, `cumulativeGasUsed`, `effectiveGasPrice`, `gasUsed`, `logsBloom`, `root`, `status`, `l1Fee`, `l1GasPrice`, `l1GasUsed`, `l1FeeScalar`, `gasUsedForL1`
**Block** (15): `sha3Uncles`, `logsBloom`, `transactionsRoot`, `receiptsRoot`, `totalDifficulty`, `size`, `uncles`, `blobGasUsed`, `excessBlobGas`, `parentBeaconBlockRoot`, `withdrawalsRoot`, `l1BlockNumber`, `sendCount`, `sendRoot`, `mixHash`
Reorg detection also improved for SVM and for an edge case on the EVM RPC source.
### v3.6.0
#### Per-Chain Isolation By Default
One step closer to truly isolated multichain. Until now every entity row was shared across every chain, so multichain indexers namespaced ids by hand with patterns like `${event.chainId}_${pool}`. This release lets you turn that off.
```yaml
# Recommended for all projects,
# and the default in HyperIndex v4
name: my-indexer
disable_default_cross_chain: true
```
With the flag on, entities and effects are scoped per chain. Entity tables get a composite `(id, chainId)` primary key, so the same id on two chains is two independent rows. Handlers do not change, because a handler always runs on a single chain, and `context.Token.get(id)` reads that chain's row.
Where you do want shared data, add `@crossChain` to an entity or `crossChain: true` to an effect.
```graphql
# Per-chain, one row per (id, chainId)
type Counter {
id: ID!
count: BigInt!
}
# One row shared by every chain
type GlobalCounter @crossChain {
id: ID!
count: BigInt!
}
```
Outside a handler there is no chain in context, so [Test Indexer](https://docs.envio.dev/docs/HyperIndex/testing) operations now take one explicitly with `indexer.Counter.set({ id, count, chainId })`, and `getWhere` is available on the test indexer's entity operations. The `envio init` templates drop the `${event.chainId}_` prefix from entity ids, and the bundled indexer skills teach the per-chain convention.
We recommend the flag for all projects, and it becomes the default in v4.
v3.6.1 followed two days later with a reliability improvement for chains that go long stretches without events, keeping the indexer moving at the head.
### v3.5.0
v3.5.0 landed the day after last month's update went out, so it belongs here.
#### Factories With Billions of Addresses
[Factory contracts](https://docs.envio.dev/docs/HyperIndex/dynamic-contracts) previously began to strain HyperIndex at around 8 million addresses. That ceiling is gone. The number of supported addresses is now effectively unlimited, bound only by the resources you give it.
We got there by having [HyperIndex](https://docs.envio.dev/docs/HyperIndex/overview) switch automatically from server-side to client-side filtering, which cuts the number of queries dramatically, plus a partial Rust rewrite that reduces resource usage during event processing.
**A full backfill of Uniswap V2 on mainnet, one of the busiest protocols ever deployed, now completes from scratch in just over a day.**
#### Deferred Postgres Index Creation
Postgres indexes defined in `schema.graphql` used to be created upfront, which could cause significant write backpressure during backfill. They are now created just before the indexer enters realtime, once the backfill is complete. On top of that, when a handler makes a `getWhere` call, HyperIndex generates the index for the required field automatically, so you no longer need to declare those in your schema. Indexes in `schema.graphql` are now specifically for your production GraphQL server.
**Up to 2.5x faster backfill for some users.**
#### Bottleneck Observability
Two new Prometheus metrics pinpoint where an indexer is actually spending its time:
- `envio_processing_stalled_on_fetch_seconds`, time spent idle with an empty buffer, waiting for events to be fetched
- `envio_processing_stalled_on_storage_write_seconds`, time spent idle due to write backpressure
We also added utility metrics that make every scrape self-describing, which is useful for monitoring tools and for AI agents reading the output. Those are `envio_process_start_time_seconds`, `envio_process_metric_time_seconds` and `envio_process_elapsed_seconds`. The elapsed metric means you can interpret counters from a single payload with no `rate()` and no external clock, so `envio_processing_stalled_on_storage_write_seconds / envio_process_elapsed_seconds` gives you the fraction of the run spent stalled on writes.
Full details are in the [Production Observability guide](https://docs.envio.dev/docs/HyperIndex/observability).
#### Numeric Entity IDs
You can now use `Int` or `BigInt` as the `id` type for entities in `schema.graphql`. Relationship fields are inferred correctly, and handler types are generated as `number`.
```ts
type Chain {
id: Int! # Numeric entity ID
vaults: [Vault!]! @derivedFrom(field: "chain")
}
type Vault {
id: ID!
chain: Chain! # Stored as chain_id (Int)
// ...
}
```
#### Chain IDs Above 2^31
Added for a Tron Testnet user and useful well beyond it. If your config includes a chain with an id greater than 2^31, HyperIndex now automatically uses larger database types to support it.
v3.5.1 rounded the release out with improvements to how dynamic contract registration is persisted.
See the full [release notes](https://github.com/enviodev/hyperindex/releases)
Star us on [GitHub](https://github.com/enviodev/hyperindex)
## Introducing HyperPipe
 Stream decoded onchain data straight to any destination, from a single YAML file.
HyperPipe puts sources, transforms and sinks in one declarative config, with no glue code and no orchestration to build. Historical backfill and live streaming come from the same source, across multiple chains at once.
```yaml
name: usdc-transfers
version: 1
sources:
- name: eth
type: hypersync
chain: ethereum
mode: both # backfill + live
processors:
- name: decode
module: builtin/evm-abi-decoder@1
inputs: [eth]
config:
abis:
- file: ./abis/erc20.json
events: [Transfer]
sinks:
- name: db
module: builtin/postgres@1
inputs: [decode]
```
ABI decoding and filtering are built in, sinks cover Postgres with automatic DDL, Parquet on S3, or any webhook, and delivery is checkpointed and at-least-once so it survives restarts. It runs as one binary, a Dockerfile, or Kubernetes manifests.
HyperPipe is in alpha and we are onboarding early access users now. Come and ask for access in our [Discord](https://discord.gg/envio).
## Run Your Existing Subgraph on HyperIndex, Unmodified
 Point one command at a subgraph project you already have and it runs on HyperIndex underneath.
```bash
cd my-subgraph && pnpx envio@3.7.0-subgraph dev
```
No changes to your manifest, schema, mappings or ABIs, and the same folder still deploys to Graph Node. We measure it at **around 200x faster on average** than running the same subgraph unchanged.
It is versioned alongside HyperIndex, so `3.7.0-subgraph` carries the v3.7.0 changes plus wider compatibility coverage. We are looking for subgraphs to test it against, especially awkward ones.
To convert a subgraph properly instead of running it as-is, the [migration guide](https://docs.envio.dev/docs/HyperIndex/migration-guide) covers the mechanics, and existing queries keep working through our [query converter](https://docs.envio.dev/docs/HyperIndex/query-conversion).
Reach out on [Discord](https://discord.gg/envio) to test it, or see the [original post on X](https://x.com/envio_indexer/status/2087926441388150930).
## HyperSync as a Datasource for Carbon
 Co-founder Jason has been working on Solana indexing after a long stretch deep in EVM, and the first thing to come out of it is HyperSync as a datasource for [Carbon](https://github.com/sevenlabs-hq/carbon), the Rust indexing framework from Seven Labs.
Carbon already supports a long list of datasources, from Yellowstone gRPC to various RPC crawlers. Adding HyperSync took a nine-line trait implementation. If you already build on Carbon, it means historical backfill without standing up your own infrastructure.
The change is open at [PR #586](https://github.com/sevenlabs-hq/carbon/pull/586) on the upstream repo and is still in review, with our fork at [enviodev/carbon](https://github.com/enviodev/carbon) in the meantime.
For more information, see the original [post](https://x.com/JasoonSmythe/status/2090447990792032382) on X.
## How to Get Polymarket Trade Data
 Every order-book fill Polymarket has settled since its 2020 launch, up to 24 April 2026, is free on Hugging Face under CC-BY-4.0. That is 1.17 billion CLOB fills, 2.63 million distinct makers and $59.9 billion of lifetime volume.
You query it with DuckDB straight over HTTPS. No download, no API token, no Polygon node. The guide walks through the snapshot first, then five wallets pulled out of those tables with queries you can run to check every number, and finishes with the open indexers if you want markets at head rather than history.
Two things catch people out, and both are in there. Addresses are EIP-55 checksummed, so filters need wrapping in `lower()`. And an account can trade from a proxy as well as directly from its signer, so querying only one can miss 99.7% of a wallet with no error at all.
Read the full guide: [How to Get Polymarket Trade Data](https://docs.envio.dev/blog/polymarket-onchain-data)
## Four Years of DeFi Liquidations, Visualised
 Co-founder Jonjon put together a visual of liquidations across [Aave](https://aave.com/), [Euler](https://www.euler.finance/) and [Morpho](https://morpho.org/) over the past four years, spanning more than 20 chains.
**282,430 liquidations on Aave v3, 193,518 on Morpho and 7,515 on Euler v2, weekly since March 2022.**
The same pipeline that answers "what just happened" also answers "what happened everywhere since 2022".
For more information, see the original [post](https://x.com/jonjonclark/status/2090787717130916299) on X.
## Backfilling Uniswap V2 on Mainnet From Scratch
 Uniswap V2 on mainnet is one of the busiest protocols ever deployed. Jonjon ran a full backfill from scratch, all 25,751,860 blocks of it, and reached 100% synced in two days.
**610,379,970 events processed across 518,333 addresses.**
The v3.5.0 work above targets exactly this, removing the address ceiling on factory indexers and deferring Postgres index creation until the backfill completes.
Full methodology for our published figures is on the [benchmarks page](https://docs.envio.dev/docs/HyperIndex/benchmarks), with the raw runs in the [open-indexer-benchmark repo](https://github.com/enviodev/open-indexer-benchmark).
Original post on X: https://x.com/jonjonclark/status/2088170247920464252
## Envio Added to the Prediction Markets Wiki
 The [Prediction Markets Wiki](https://x.com/PredMarketWiki) added Envio as the data layer behind prediction-market apps, noting that builders can index onchain events, backfill history and use the open Polymarket datasets rather than rebuilding the pipeline from scratch.
The Polymarket snapshot covered above is free under CC-BY-4.0, so anyone building in the category can start from real data instead of an empty database.
For more information, see the original [post](https://x.com/PredMarketWiki/status/2087897647680004607) on X.
## Current & Upcoming Events & Hackathons
* [Devcon 8 - Mumbai](https://devcon.org/): November 3rd -> 6th
* [Solana Breakpoint - London](https://solana.com/breakpoint): November 15th -> 17th
## Featured Developer: tdubb
 This month's featured developer is [tdubb](https://x.com/tdubbdoteth), founder of [Reptilian](https://github.com/ReptilianHQ) and a developer experience engineer at [Antithesis](https://antithesis.com), where he works on the NixOS-based platform team behind a simulation platform that tests the guarantees of some of the hardest distributed systems around, for the likes of Jane Street and Ethereum. They tested the Merge.
Before crypto he spent three years leading infrastructure and reliability on [Prefect](https://www.prefect.io/), work he describes as having contributed to curing rare genetic childhood diseases and to winning the World Series for his city, by building a workflow system that levelled up data scientists everywhere. He came into web3 as founding engineer at Orb Labs, and now splits his time between chain abstraction, the open-source property-based testing project Hegel, and Reptilian's partnership with Foundation, which helps token launchers run long-term liquidity strategies across chains.
**What tdubb had to say about Envio:**
> ***"One of my focuses has been chain abstraction, which involves indexing data across the chainiverse, which is maybe the most poorly-understood and surprisingly difficult problem in our industry. When I found Envio and HyperSync, it was everything I ever wanted, and it worked, right away, with incredibly powerful developer handles. Now, it powers all of my data efforts, underneath a Prefect-powered event-driven orchestration system for enriching data and taking action on it. HyperSync allows me to listen to the chainiverse, as well as develop new historical data abstractions over chainiverse history on its EXTREMELY fast chain replay. I'm incredibly honoured to be recognised by such an incredible team and hope to contribute more to its future. Thank you, Envio!"***
>
> *- tdubb, Founder of [Reptilian](https://github.com/ReptilianHQ) and Developer Experience Engineer at [Antithesis](https://antithesis.com)*
Well done, tdubb. Be sure to follow him on [X](https://x.com/tdubbdoteth) and check out [Reptilian on GitHub](https://github.com/ReptilianHQ) to stay up to date with his latest developments.
## Playlist of the Month
 [Open Spotify](https://open.spotify.com/playlist/3i4gWLRt2l4YsbjBXlPSgT?si=0abea546e7ab4855)
## Build With Envio
Envio is a multichain EVM blockchain indexer for querying real-time and historical data. If you're working on a Web3 project and want a smoother development process, Envio's got your back(end). Check out our docs, join the community, and let's talk about your data needs.
Stay tuned for more monthly updates by subscribing to our newsletter, following us on X, or hopping into our Discord for more up-to-date information.
[Subscribe to our newsletter](https://envio.beehiiv.com/subscribe?utm_source=envio.beehiiv.com&utm_medium=newsletter&utm_campaign=new-post)
[Website](https://envio.dev/) | [X](https://twitter.com/envio_indexer) | [Discord](https://discord.gg/envio) | [Telegram](https://t.me/+5mI61oZibEM5OGQ8) | [GitHub](https://github.com/enviodev) | [YouTube](https://www.youtube.com/channel/UCR7nZ2yzEtc5SZNM0dhrkhA) | [Reddit](https://www.reddit.com/user/Envio_indexer)
---
# Nodes Silently Miss Events
> Execution clients sometimes drop logs from eth_getLogs, and a JSON-RPC response does not show whether it is complete. This article documents some of the cases, explains which parts of an EVM block can be checked against the header's Merkle roots, and describes how HyperSync recomputes transaction and receipt roots on every ingested block.
:::note TL;DR
- A JSON-RPC response does not carry proof of its own completeness. A node that has lost receipts, or a provider whose fleet is out of sync, can return a well-formed response with logs missing, and this is difficult to tell from the response alone.
- An EVM block header commits to its transactions and receipts through two Merkle-Patricia roots. Logs are part of receipts, so a dropped or altered log changes the receipts root.
- Recomputing those roots requires the complete block, meaning all of its transactions and receipts. A filtered `eth_getLogs` response cannot be checked this way, and this also limits what proxies and load balancers in front of RPC are able to verify.
- Because HyperSync ingests entire blocks, it is able to recompute both roots before data is served, and to refetch from a different source when they do not match. This tends to catch missing logs at ingest rather than later in an indexer's database.
- The protection is aimed at faulty sources rather than adversarial ones, and some chains need chain-specific handling before the roots can be recomputed.
:::
## The problem
Ethereum's JSON-RPC interface returns plain JSON. When a client calls `eth_getLogs`, the response is a list of log objects, and there is nothing in that list that shows whether it is complete. The same applies to `eth_getBlockReceipts`. A block returned by `eth_getBlockByNumber` with full transaction objects does carry enough to recompute `transactionsRoot`, though a hash-only response does not, and in either form the block omits its receipts, so it says nothing about whether the logs are complete. The client is trusting that the node executed the block correctly, stored the results correctly, and served them correctly.
That trust is usually justified, but it is difficult to verify at the point of use, and when it breaks the failure tends to be quiet. A node with a corrupted receipts database does not usually return an error. It returns fewer logs.
This matters most for indexers, because an indexer's output depends on every log it has received. One missing transfer event produces a balance that would be wrong, and this is not caught downstream.
The Ethereum protocol does provide commitments that make this checkable. The question is where in the stack there is enough data to make use of them.
## What a block header commits to
An EVM block header contains, among other fields, three commitments defined in the Ethereum Yellow Paper (Wood, Section 4, "Blocks, State and Transactions"):
| Header field | Commits to |
| --- | --- |
| `transactionsRoot` | The root of a Merkle-Patricia trie keyed by transaction index, whose values are the RLP or EIP-2718 encoded transactions of the block. |
| `receiptsRoot` | The root of a Merkle-Patricia trie keyed by transaction index, whose values are the encoded receipts. Each receipt contains the status (EIP-658, for blocks since Byzantium; earlier receipts carried an intermediate state root in its place), cumulative gas used, the receipt's bloom filter, and the full list of logs emitted by that transaction. |
| `parentHash` | The Keccak-256 hash of the previous block's header, which links headers into a chain. |
The header also contains `logsBloom`, the bitwise OR of every receipt's bloom, and `stateRoot`, which commits to the world state after execution.
This has a useful consequence for logs. A log is part of the receipt's encoding, so a change to any log in the block changes the receipt's encoding, which changes the trie value, which changes `receiptsRoot`. Removing a log, adding one, reordering topics, or altering a data field would each produce a different root. The same holds for transactions and `transactionsRoot`.
So in principle the check is fairly straightforward. Given a block's header and all of its transactions and receipts, recompute both roots and compare them with the header. If they match, the transactions and receipts are the ones the block producer committed to. If they do not, something has been missed or altered.
The condition matters. The check needs all of the block's receipts. A response to `eth_getLogs` filtered by address and topic is a subset, and there is no commitment to a subset. This is less a limitation of any particular implementation than a consequence of how the header is structured.
## Documented cases of incomplete data
It is not hypothetical that logs are missed. This pattern has recurred several times across execution clients over some years, and in 2025 it became the subject of a longer discussion about Ethereum's RPC standards.
### "Ethereum needs Standards-Punk"
On 5 October 2025, Sebastian Bürgel, founder of HOPR, published a post on ethresear.ch titled ["Ethereum needs Standards-Punk"](https://ethresear.ch/t/ethereum-needs-standards-punk/23151). HOPR's mixnet uses `eth_getLogs` to map its payment-channel topology, and the team had spent the preceding months chasing channels that appeared closed without ever having been opened. The post opens with the problem as it looks from the application side:
> Right now, if a wallet or app queries eth_getLogs from a production Ethereum client, there's a real chance it will silently miss events. The result is simple and devastating: balances don't add up, transaction histories show funds being spent before they are ever received, and applications cannot give users a trustworthy account of what happened. Consensus may still be intact, but the interface developers actually rely on is corrupted.
The post links eight separate reports across Erigon, Nethermind, and HOPR's own tracker, on both Gnosis Chain and Ethereum mainnet, and calls the problem systemic. It also points at the conformance gap. Of roughly 190 RPC compatibility tests in Hive, four cover `eth_getLogs`, and about half of those had been failing for months without affecting any client's release. The post's proposal is a standards and conformance group for execution-layer RPC, with `eth_getLogs` as its first focus, and test suites in the hundreds of thousands rather than the hundreds.
The thread that followed is also useful. Mario Vega of the Ethereum Foundation's testing team added the topic to the agenda of [All Core Devs Testing call 57](https://github.com/ethereum/pm/issues/1756) on 13 October 2025. Etan Kissling pointed to EIP-7919, which aims to make RPC answers verifiable so that a provider is trusted only for availability and not for correctness. A later reply from Antony Denyer described what teams do in practice once they stop trusting the RPC boundary: they ingest the entire chain into their own datastore and rebuild derived state from scratch, which is close to the architecture described later in this article.
Bürgel's own follow-up in the thread is relevant to what follows here. Even with better encoding and verification schemes, he argues, the existing JSON-RPC interface will not go away, because every library that dapps and wallets depend on is built on it, and the semantics of filtering logs are "far from trivial, with several edge cases left unspecified for clients to handle as they see fit."
### The report behind the post: Nethermind 1.33.1 on Gnosis Chain
Three weeks earlier, on 16 September 2025, Bürgel had opened [Nethermind issue #9305](https://github.com/NethermindEth/nethermind/issues/9305) after noticing that his Nethermind node on Gnosis Chain was returning fewer logs than the public Gnosis RPC. His method is worth noting because, from outside the node, comparison is more or less the only detection method available: query two providers, block by block.
```bash
for ((b=$START; b<=$END; b+=$RANGE)); do
e=$((b+RANGE-1))
n1=$(curl -s -X POST $PROV1 ... eth_getLogs ... | jq '.result|length')
n2=$(curl -s -X POST $PROV2 ... eth_getLogs ... | jq '.result|length')
if [ "$n1" -eq "$n2" ]; then echo "$b-$e: OK"; else echo "$b-$e: $n1 vs $n2"; fi
done
```
The output shows the Nethermind node returning zero logs for a filtered `Transfer` query on roughly a third of the blocks in a 50-block window, where the other provider returned between 1 and 11:
```text
39556455-39556455: OK
39556456-39556456: 0 vs 2
39556457-39556457: 0 vs 6
39556458-39556458: OK
39556459-39556459: 0 vs 2
...
39556463-39556463: 0 vs 11
39556464-39556464: 0 vs 8
```
Two details from the thread are relevant here. First, the reference provider was not fully consistent either. Bürgel noted that the public Gnosis RPC gave "a little bit inconsistent" results at a rate of roughly 1 in 50, missing some logs on repeated queries. Second, the root cause was database corruption in the node's receipts store introduced in the previous release. The maintainers closed the issue four days later with "Logs are back after fixing db corruption", and the [1.33.1 release notes](https://github.com/NethermindEth/nethermind/releases/tag/1.33.1) were updated to advise operators affected by "the missing receipts from running v1.33.0" to run with `Sync.FixReceipts` set to true or to delete and re-download the receipts database.
The node did not have a way to know its receipts were incomplete, so it served them. Without a second source to compare against, this would likely have gone unnoticed.
### The same failure across clients and years
The reports Bürgel's post links, and older ones like them, share a similar shape. The node is healthy, the block is valid, and the log index or receipt store has drifted from the chain.
- [Erigon #16613](https://github.com/erigontech/erigon/issues/16613), August 2025. A Gnosis Chain archive node returned no logs for `eth_getLogs` over ranges where other nodes returned them. The thread ran to 23 comments over two months before it was closed.
- [Erigon #16364](https://github.com/erigontech/erigon/issues/16364), July 2025. A mainnet archive node returned empty results from `eth_getLogs` while it was creating snapshots, then correct results afterwards.
- [Nethermind #9178](https://github.com/NethermindEth/nethermind/issues/9178), August 2025. HOPR's team reported empty `eth_getLogs` results for historical Gnosis Chain blocks that other providers served correctly. The cause was in an experimental log-index branch, later fixed.
- [Besu #1153](https://github.com/besu-eth/besu/issues/1153), June 2020. A query for deposit contract events on Görli returned results with "a number of blocks missing" compared with the same query against Infura.
- [go-ethereum #18198](https://github.com/ethereum/go-ethereum/issues/18198), November 2018. A Rinkeby node consistently omitted one log from a range query, and the transaction receipt returned null, while other nodes and Etherscan showed it. Restarting the node restored the log.
All of these were resolved, and the point is not that any particular client is unreliable today. It is that receipt storage and log indexing are handled separately from block validation in clients generally, so they can drift without the node noticing, and the RPC response does not carry the information needed to detect that drift.
### Provider fleets
Hosted providers run many nodes behind a load balancer, which adds a second source of inconsistency: two requests can be served by two nodes in different states, or by two different clients. While investigating the Gnosis Chain problems above, HOPR's engineers found that the same `eth_getLogs` request to a public endpoint sometimes returned a log and sometimes returned an empty array, and that `web3_clientVersion` called twice in a row came back as Nethermind, then Reth, then Erigon ([hoprnet #7437](https://github.com/hoprnet/hoprnet/issues/7437)). The endpoint was balancing across three execution clients, one of which was missing the log. The cases below name the providers involved because the details are what make them useful. In each of them the provider was serving what its node software produced. The fault sits with the node implementation, or with the chain's own state during an outage, and a self-hosted node running the same software would most likely have returned the same data. All four providers remain in HyperSync's source pool.
**Robinhood Chain, September 2026.** This case is what prompted the article, and it is worth describing because the bad data came from Alchemy, one of the best-known providers in the industry. HyperIndex can read from HyperSync or from RPC, and a production configuration usually lists both, with RPC as a [fallback](/docs/HyperIndex/rpc-sync) that takes over automatically when the primary source stops progressing. On 4 September 2026, Robinhood Chain stopped producing blocks for about 14 minutes. From the indexer's point of view HyperSync had stopped advancing, which looks the same as a source outage, so it failed over to its configured Alchemy RPC endpoint. That endpoint had also stopped advancing, because the chain itself had, and the indexer waited. When the chain resumed and the indexer continued indexing, it was still on the RPC source and continued ingesting from Alchemy for a period before switching back to HyperSync. The invalid data arrived in that window, from a node that had just come through a sequencer halt and was in an abnormal state.
The bad data originated on Alchemy's side, in a node that had just come through a sequencer halt, and nothing in the responses would have let the indexer tell. Data read through HyperSync had passed the root checks described below, while data read through the RPC fallback could not be checked in the same way, because a filtered RPC response cannot be. We are building a solution for this class of downstream bad data: when an indexer is reading the chain head from RPC, issue additional HyperSync requests so that the RPC data can be verified against HyperSync once it is available, and the fallback path inherits the same guarantee as the primary. That is not built yet.
**HyperEVM system transactions, August to September 2026.** HyperEVM places system transactions, which move funds from HyperCore into the EVM, at the front of blocks. The node implementation used by Dwellir and Alchemy returns these as ordinary transactions in `eth_getBlockByNumber`, with zero gas used, and returns receipts for them. The chain's official RPC does not return them, and neither did Chainstack. The block header's `transactionsRoot` and `receiptsRoot` were identical from every source and matched the view without the system transactions. For at least a week, roughly one in three blocks at the chain head failed HyperSync's root check on first fetch from Dwellir and was patched from Chainstack. Whether the official RPC hides these transactions or the other node build surfaces them is a question about HyperEVM's semantics, not about either provider. What the root check establishes is only that they are not part of what the block producer committed to.
**Arbitrum receipt field casing, August 2026.** On Arbitrum One, Chainstack's fleet ran a stock Nitro release that serialised one receipt field on `eth_getBlockReceipts` as `L1BlockNumber`, while Dwellir, dRPC, and the Arbitrum Foundation's public endpoint, on the next Nitro release, returned it as `l1BlockNumber`. The values were identical. Only the key's capitalisation differed, and a strict parser reading the two providers would see a field present on one and absent on the other. The difference came from the node software version, and the upstream release resolved it.
None of these cases produced an error from the provider. Each returned well-formed JSON, and the main signal was disagreement between sources or with the header's commitments.
## Verifying with complete block data
Because HyperSync stores every block in full, it is able to perform these root checks. To serve an arbitrary filtered query later, it has to ingest every transaction, receipt, and log, and on some chains every trace. That happens to be the input the root check needs, so the check adds relatively little once the data is there.
Every batch of blocks is validated before it is written to storage or served. At a high level the checks fall into three groups.
- **Cryptographic commitments.** For each block, a complete receipt is rebuilt for every transaction from its stored receipt fields, such as status, cumulative gas used, and bloom, together with the logs that belong to it, and the receipts trie root is recomputed and compared with the header's `receiptsRoot`. The transactions are re-encoded as signed envelopes across the standard transaction types, and the transactions trie root is compared with `transactionsRoot`. Each block's `parentHash` is checked against the hash of the block before it, including across batch boundaries.
- **Structural consistency.** Block numbers are sequential with no gaps, transaction and log indices are contiguous, cumulative gas used adds up transaction by transaction, and gas used does not exceed the gas limit.
- **Cross-references.** Every transaction, log, and trace carries the hash of the block it belongs to, and every log and trace points at the transaction that produced it.
The root checks are the ones most relevant to completeness, and they are tested against real mainnet blocks. Removing a single log, or a single transaction, from a block produces a root mismatch.
When a check fails, HyperSync refetches rather than accepting the batch. It keeps track of which source served each block, transaction, receipt, and trace, refetches the affected block or transactions from a different source, excluding the sources that served the failing data, validates the refetched data again, and patches it into the batch. After a few patch rounds without success, the range is marked unverified and scheduled for backfill. On the ingest leader that data can still be served until the backfill lands, so the guarantee is that unverified ranges are known and tracked, not that they never reach a query.
Recomputing a root only works if the reconstruction reproduces the chain's exact encoding. On Ethereum mainnet that is mostly mechanical. On several other chains, system or deposit transactions with non-standard types and receipt formats, and hard forks that change which transactions the tries include, need to be handled differently, and a fair amount of the engineering effort goes there. On chains where a transaction type cannot yet be reconstructed, the root checks are held back until it can be, and the structural and cross-reference checks still run.
The validation is aimed at faulty sources, such as nodes with corrupted stores or providers serving mixed views, rather than at a source constructing a deliberately consistent but false block. In practice, disagreement between providers has been the signal in the cases we have seen.
## Where a proxy sits in the stack
It is instructive to compare this with what can be done at the RPC proxy layer, because that is where many teams look to solve the reliability problem. [eRPC](https://github.com/erpc/erpc) is a thorough open-source example, and its authors have thought carefully about this question.
eRPC has three mechanisms for data correctness.
**Block-tip and availability enforcement**, always on. It prevents `eth_blockNumber` from going backwards across upstreams, pre-screens `eth_getLogs` ranges against each upstream's known height, and treats null responses for tagged blocks as retryable ([docs](https://docs.erpc.cloud/config/failsafe/integrity)). This addresses lagging nodes, which is a common failure in practice.
**Consensus**, opt-in. Requests are fanned out to several upstreams and responses are grouped by a hash of their canonicalised JSON. A result wins when enough upstreams agree ([docs](https://docs.erpc.cloud/config/failsafe/consensus)). This is a majority vote, not a cryptographic check, and eRPC's own documentation is explicit about the assumption. Consensus "catches a *minority* bad upstream", and the case it cannot see is "when *every* serving upstream returns the same wrong value".
**Data-integrity checks**, opt-in, shipped in eRPC 0.2.0 on 31 August 2026. This module does perform cryptographic recomputation. For `eth_getBlockByNumber` and `eth_getBlockByHash` it recomputes the block hash from the header and, when the response carries full transaction objects of types it can model, the transactions root from the transaction bodies. Hash-only, empty, and unsupported transaction lists are skipped rather than checked. For `eth_getBlockReceipts` it recomputes the receipts root and compares it with a header fetched by block hash ([`checks_recompute.go`](https://github.com/erpc/erpc/blob/0.2.0/architecture/evm/integrity/checks_recompute.go)). It also recovers the sender from the signature for `eth_getTransactionByHash`. The implementation uses go-ethereum's `DeriveSha` and `StackTrie`, and it is conservative: any header or receipt with a field the reference encoder does not know is skipped rather than rejected.
That covers block-shaped responses. For `eth_getLogs`, which most indexers depend on, the situation is different, and eRPC's specification says so directly ([`specs/data-integrity/getlogs-receipt-crosscheck.md`](https://github.com/erpc/erpc/blob/0.2.0/specs/data-integrity/getlogs-receipt-crosscheck.md)). It describes `eth_getLogs` as "the one method that cannot be validated intrinsically", because "every other check recomputes a commitment from the response itself (block hash, transactions root, receipts root, logs bloom)", whereas a `getLogs` response is "a filtered subset of logs across a block range" for which "there is no root to recompute and no self-contained invariant". The consequence, in the specification's words: "an upstream that silently drops logs (the single worst failure mode for an indexer) passes every existing check."
eRPC's answer is two checks in [`checks_getlogs.go`](https://github.com/erpc/erpc/blob/0.2.0/architecture/evm/integrity/checks_getlogs.go). The first confirms that every returned log matches the requested filter and range, which catches fabricated or out-of-range logs but says nothing about missing ones. The second compares the response against block receipts that happen to be in an in-memory cache from earlier, unrelated traffic. It does not fetch receipts in order to perform the comparison. When the receipts are not cached, the block is skipped, and the specification lists the consequence under what the check misses: "ranges not in cache (large cold backfills); consistent drops from a single bad source that fed both sides."
None of this is intended as a criticism of eRPC. It is a well-engineered system that publishes its own false-positive rates and is candid about its assumptions. The limitation seems structural. A proxy that forwards a filtered log query sees a filtered response, and verifying that response would mean fetching the block's full receipts, which is much of the work the proxy exists to avoid. A proxy can reasonably verify completeness only when something else has already fetched everything.
An ingestion system that stores whole blocks has already done that work. That is most of the argument. The verification is less a feature added to HyperSync than a property that follows from holding the complete data, and the engineering effort goes into making the reconstruction correct on each chain rather than into obtaining the inputs.
## Practical implications
For teams reading data through RPC, the practical advice follows from Bürgel's script. Completeness of `eth_getLogs` is best established by comparison with a second, independent source, and ideally against the block's receipts rather than another filtered query. If an indexer's correctness matters, it is worth making that comparison routine rather than doing it after a discrepancy is noticed.
For teams reading through HyperSync, the root checks run on every block before it is served, on every chain where the transaction encodings can be reconstructed. A query's results are drawn from data that matched the block header's commitments at ingest time, or from a range that is recorded as unverified and scheduled for backfill.
## References
- Wood, G. *Ethereum: A Secure Decentralised Generalised Transaction Ledger*. Section 4, "Blocks, State and Transactions". [ethereum.github.io/yellowpaper](https://ethereum.github.io/yellowpaper/paper.pdf)
- EIP-658: Embedding transaction status code in receipts. [eips.ethereum.org/EIPS/eip-658](https://eips.ethereum.org/EIPS/eip-658)
- EIP-2718: Typed Transaction Envelope. [eips.ethereum.org/EIPS/eip-2718](https://eips.ethereum.org/EIPS/eip-2718)
- EIP-7919: Pureth Meta. [eips.ethereum.org/EIPS/eip-7919](https://eips.ethereum.org/EIPS/eip-7919)
- Ethereum Execution APIs, `eth_getLogs`. [ethereum.github.io/execution-apis](https://ethereum.github.io/execution-apis/api/methods/eth_getLogs/)
- Bürgel, S. "Ethereum needs Standards-Punk". ethresear.ch, 5 October 2025. [ethresear.ch/t/ethereum-needs-standards-punk/23151](https://ethresear.ch/t/ethereum-needs-standards-punk/23151)
- Bürgel, S. "1.33.1 not returning event logs in some range". NethermindEth/nethermind #9305, 16 September 2025. [github.com/NethermindEth/nethermind/issues/9305](https://github.com/NethermindEth/nethermind/issues/9305)
- Nethermind 1.33.1 release notes. [github.com/NethermindEth/nethermind/releases/tag/1.33.1](https://github.com/NethermindEth/nethermind/releases/tag/1.33.1)
- All Core Devs Testing call 57 agenda, 13 October 2025. [github.com/ethereum/pm/issues/1756](https://github.com/ethereum/pm/issues/1756)
- "Broken eth_getLogs responses on RPC endpoints". hoprnet/hoprnet #7437, 2 September 2025. [github.com/hoprnet/hoprnet/issues/7437](https://github.com/hoprnet/hoprnet/issues/7437)
- "No log response for eth_getLogs Gnosis Mainnet Archival". erigontech/erigon #16613, 13 August 2025. [github.com/erigontech/erigon/issues/16613](https://github.com/erigontech/erigon/issues/16613)
- "RPC methods return empty responses during snapshot creation". erigontech/erigon #16364, 30 July 2025. [github.com/erigontech/erigon/issues/16364](https://github.com/erigontech/erigon/issues/16364)
- "eth_getLogs returns empty results for historical blocks on Gnosis Chain". NethermindEth/nethermind #9178, 20 August 2025. [github.com/NethermindEth/nethermind/issues/9178](https://github.com/NethermindEth/nethermind/issues/9178)
- "Missing results from eth_getLogs request". besu-eth/besu #1153, 25 June 2020. [github.com/besu-eth/besu/issues/1153](https://github.com/besu-eth/besu/issues/1153)
- "missing logs in eth_getLogs". ethereum/go-ethereum #18198, 28 November 2018. [github.com/ethereum/go-ethereum/issues/18198](https://github.com/ethereum/go-ethereum/issues/18198)
- Wang, W. and Van Cutsem, T. "Depermissioning Web3: a Permissionless Accountable RPC Protocol for Blockchain Networks". arXiv:2506.03940, June 2025. [arxiv.org/abs/2506.03940](https://arxiv.org/abs/2506.03940)
- eRPC integrity checks documentation. [docs.erpc.cloud/config/failsafe/integrity](https://docs.erpc.cloud/config/failsafe/integrity)
- eRPC, `architecture/evm/integrity/checks_recompute.go` and `checks_getlogs.go`, and `specs/data-integrity/getlogs-receipt-crosscheck.md`, at tag `0.2.0` (31 August 2026). [github.com/erpc/erpc/tree/0.2.0](https://github.com/erpc/erpc/tree/0.2.0)
---