# Envio docs: HyperIndex core
> Build, run and test an indexer: getting started, config.yaml, schema, handlers, CLI, testing, troubleshooting.
Generated at build time from the pages of https://docs.envio.dev. Each page below is the full markdown of one docs page, after a `` line. Append `.md` to that URL to fetch the page on its own. The index of every page is https://docs.envio.dev/llms.txt.
Context files, one per product area:
- llms-hyperindex.txt (this file): HyperIndex core, about 47k tokens. Build, run and test an indexer: getting started, config.yaml, schema, handlers, CLI, testing, troubleshooting.
- [llms-hyperindex-advanced.txt](https://docs.envio.dev/llms-hyperindex-advanced.txt): HyperIndex advanced features, about 32k tokens. Factories, the Effect API, wildcard indexing, preload, contract state, IPFS, HyperSync and RPC sources, reorgs, WebSockets.
- [llms-hyperindex-reference.txt](https://docs.envio.dev/llms-hyperindex-reference.txt): HyperIndex performance and reference, about 27k tokens. Config schema reference, observability, performance tuning, benchmarks, supported chains and licensing.
- [llms-hyperindex-examples.txt](https://docs.envio.dev/llms-hyperindex-examples.txt): HyperIndex examples and tutorials, about 16k tokens. Example indexers (Uniswap v4, Sablier, Velodrome and Aerodrome) and EVM tutorials.
- [llms-hyperindex-migration.txt](https://docs.envio.dev/llms-hyperindex-migration.txt): HyperIndex migration guides, about 14k tokens. Upgrade a V2 indexer to V3, or migrate from The Graph, Ponder or Alchemy, by hand or with AI.
- [llms-hyperindex-solana-fuel.txt](https://docs.envio.dev/llms-hyperindex-solana-fuel.txt): HyperIndex on Solana and Fuel, about 21k tokens. Solana programs (instruction and slot handlers, decoding, config) and Fuel contracts.
- [llms-envio-cloud.txt](https://docs.envio.dev/llms-envio-cloud.txt): Envio Cloud, about 24k tokens. Deploy, monitor and manage hosted indexers: features, CLI, billing, organisations, self-hosting.
- [llms-hypersync.txt](https://docs.envio.dev/llms-hypersync.txt): HyperSync core, about 36k tokens. EVM data: quickstart, API tokens, clients, query reference, curl, stream tuning, supported networks, tutorials.
- [llms-hypersync-solana-fuel.txt](https://docs.envio.dev/llms-hypersync-solana-fuel.txt): HyperSync for Solana and Fuel, about 15k tokens. Solana HyperSync (query schema, client, curl examples) and HyperFuel, HyperSync for the Fuel network.
- [llms-hyperrpc.txt](https://docs.envio.dev/llms-hyperrpc.txt): HyperRPC, about 6k tokens. Read-only JSON-RPC endpoint powered by HyperSync: supported methods, usage and supported networks.
Pages in this file:
- HyperIndex: Fast Multichain Blockchain Indexer
- HyperIndex Quickstart
- Quickstart with AI
- Configuration File (config.yaml)
- Entities Schema (schema.graphql)
- Event Handlers (src/handlers)
- Block Handlers
- Multichain Indexing
- Running The Indexer Locally
- Environment Variables
- Envio CLI Reference
- Testing
- Navigating Hasura
- Common Issues
- Reserved Words
---
# HyperIndex: Fast Multichain Blockchain Indexer
> HyperIndex turns onchain events into a GraphQL API in minutes. Envio's multichain indexer, independently benchmarked as the fastest.
**HyperIndex** is a blazing-fast, developer-friendly multichain indexer, optimized for both local development and reliable hosted deployment. It empowers developers to effortlessly build robust backends for blockchain applications. If you are new to indexing, see [what a blockchain indexer is](https://docs.envio.dev/blog/what-is-a-blockchain-indexer) for the wider context.
:::info HyperIndex & HyperSync
**HyperIndex** is Envio's full-featured blockchain indexing framework that transforms on-chain events into structured, queryable databases with GraphQL APIs.
[**HyperSync**](https://docs.envio.dev/docs/HyperSync/overview) is the high-performance data engine that powers HyperIndex. It provides the raw blockchain data access layer, delivering up to 2000x faster performance than traditional RPC endpoints.
While HyperIndex gives you a complete indexing solution with schema management and event handling, HyperSync can be used directly for custom data pipelines and specialized applications.
:::
---
## Key Features
- **[Quickstart templates](https://docs.envio.dev/docs/HyperIndex/greeter-tutorial)** – Rapidly bootstrap your indexer.
- **[Real-time indexing](https://docs.envio.dev/docs/HyperIndex/latency-at-head)** – Instantly track blockchain events.
- **[Multichain indexing](https://docs.envio.dev/docs/HyperIndex/multichain-indexing)** – Support multiple blockchains simultaneously.
- **[Local development](https://docs.envio.dev/docs/HyperIndex/running-locally)** – A full-featured local environment with Docker.
- **[Reorg support](https://docs.envio.dev/docs/HyperIndex/reorgs-support)** – Gracefully handle blockchain reorganizations without sacrificing latency.
- **[GraphQL API](https://docs.envio.dev/docs/HyperIndex/navigating-hasura)** – Easily query indexed data.
- **[Cross-platform support](https://docs.envio.dev/docs/HyperIndex/supported-networks)** – Index any EVM-, SVM-, or Fuel-compatible blockchain.
- **[High performance](https://docs.envio.dev/docs/HyperIndex/benchmarking)** – Perform historical backfills at 100,000+ events per second.
- **[Indexer auto-generation](https://docs.envio.dev/docs/HyperIndex/quickstart)** – Generate indexers directly from smart contract addresses.
- **[Flexible language support](https://docs.envio.dev/docs/HyperIndex/terminology#programming-languages)** – TypeScript or ReScript projects from `envio init`; plain JavaScript handler files load too.
- **[Factory contract support](https://docs.envio.dev/docs/HyperIndex/dynamic-contracts)** – Index data from over 1M dynamically registered contracts seamlessly.
- **[On-chain and off-chain data integration](https://docs.envio.dev/docs/HyperIndex/contract-state)** – Easily combine multiple data sources.
- **[Self-hosted and managed options](https://docs.envio.dev/docs/HyperIndex/hosted-service)** – Run your own setup or use Envio Cloud.
- **[Detailed logging and observability](https://docs.envio.dev/docs/HyperIndex/observability)** – Debug and optimize with clarity.
- **[External API actions](https://docs.envio.dev/docs/HyperIndex/ipfs)** – Trigger external services based on blockchain events.
- **[Wildcard topic indexing](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing)** – Flexibly index based on event topics.
- **[Fallback RPC data sources](https://docs.envio.dev/docs/HyperIndex/rpc-sync#improving-resilience-with-rpc-fallback)** – Enhance reliability with RPC connections.
---
## Feature Roadmap
Upcoming features on our development roadmap:
- **Indexing 1,000,000+ events per second**
- **Configurable Query/REST API layer**
- **No-Code Indexers**
- **Durable & Non-Blocking Effect API**
Recently shipped: [isolated multichain mode](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode) (v3.6, with per-chain rollbacks in v3.10) and [stable Solana support](https://docs.envio.dev/docs/HyperIndex/solana) (v3.11).
---
## HyperSync API Token Requirements
HyperSync (the data engine powering HyperIndex) requires an API token for all requests. You can generate one in the [Envio Cloud portal](https://envio.dev/app/api-tokens). Here's what you need to know:
- **Local Development**: An API token is required. `envio init` can open the token page and write the token to your project's `.env` file.
- **Self-Hosted Deployments**: API tokens are required for HyperSync access in self-hosted deployments. Set the token via the `ENVIO_API_TOKEN` environment variable in your indexer configuration. This can be read from the `.env` file in the root of your HyperIndex project.
- **Envio Cloud**: Indexers deployed to Envio Cloud have special access that doesn't require a custom API token.
- **Pricing**: Tiered packages are available for those self-hosting HyperIndex and using HyperSync. See the [HyperSync pricing page](https://envio.dev/pricing/hypersync) for details, or reach out to us on [Discord](https://discord.gg/envio) for preferred pricing based on your specific use case.
For more details about API tokens, including how to generate and implement them, see our [API Tokens documentation](https://docs.envio.dev/docs/HyperSync/api-tokens).
---
## 🔗 Quick Links
- [GitHub Repository](https://github.com/enviodev/hyperindex) ⭐
- [Join our Discord Community](https://discord.gg/envio)
---
# HyperIndex Quickstart
> Learn to quickly autogenerate and configure a HyperIndex indexer for any smart contract.
The **Quickstart** enables you to instantly autogenerate a powerful blockchain indexer and start querying blockchain data in minutes. This is the fastest and easiest way to begin using HyperIndex. If you are new to indexing, see [what a blockchain indexer is](https://docs.envio.dev/blog/what-is-a-blockchain-indexer) for the wider context.
**Example:** Autogenerate an indexer for the Eigenlayer contract and index its entire history in less than 5 minutes by simply running `pnpx envio init` and providing the contract address from [Etherscan](https://etherscan.io/address/0x858646372cc42e1a627fce94aa7a7033e7cf075a).
---
## Prerequisites
- **[Node.js](https://nodejs.org/en/download/current)** _(22.15.0 or newer)_
- **[pnpm](https://pnpm.io/installation)** _(recommended but not required)_
- **[Docker Desktop](https://www.docker.com/products/docker-desktop/)** _(required to run the Envio indexer locally)_
> **Note:** Docker is only required if you plan to run your indexer locally. You can skip installing Docker if you'll only be using Envio Cloud. [Podman](https://podman.io/) also works if you prefer it to Docker.
### Additionally for Windows Users:
- **[WSL](https://learn.microsoft.com/en-us/windows/wsl/install)** _Windows Subsystem for Linux_
---
## Getting Started
Run the following command to initialize your blockchain indexer:
```bash
pnpx envio init
```
You'll then follow interactive prompts to customize your indexer: a folder name, the blockchain ecosystem (`Evm`, `Svm` or `Fuel`), how to start, and an Envio API token for your `.env` file.
To run `envio init` without prompts, for example from a script or an AI agent, see [Non-interactive `envio init`](https://docs.envio.dev/docs/HyperIndex/cli-commands#non-interactive-envio-init).
---
### Video Tutorials
[Video: Quickstart Guide](https://www.youtube.com/watch?v=zkVlGgf5XAo)
[Video: Indexer Initialization Guide](https://www.youtube.com/watch?v=JOiLUysZf-s)
[Video: Envio - Getting Started Guide](https://www.youtube.com/watch?v=LNhaN-Cikis)
---
## Indexer Initialization Options
After choosing the `Evm` ecosystem, you'll be asked how to start. The first two options import an existing contract (recommended); the others create a project from a template:
```bash
? Choose an initialization option
> From Address - Lookup ABI from block explorer
From ABI File - Use your own ABI file
Template: ERC20
Template: Greeter
Feature: External Calls
Feature: Factory Contract
[↑↓ to move, enter to select, type to filter]
```
---
## Contract Import Methods
There are two convenient methods to import your contract:
- **From Address** _(verified contracts on supported explorers like Etherscan and Blockscout)_
- **From ABI File** _(custom or unverified contracts)_
### 1. Block Explorer Import
This method uses a verified contract's address from a supported blockchain explorer (Etherscan, Routescan, etc.) to automatically fetch the ABI.
#### Steps:
**a. Select the blockchain**
```bash
? Which blockchain would you like to import a contract from?
> abstract
amoy
arbitrum-nova
arbitrum-one
...
[↑↓ to move, enter to select, type to filter]
```
:::note
HyperIndex supports all EVM-compatible chains. If your desired chain is not listed, you can import via the local ABI method or manually adjust the `config.yaml` file after initialization.
:::
**b. Enter the contract address**
```bash
? What is the address of the contract?
[Use the proxy address if your abi is a proxy implementation]
```
:::tip
If using a proxy contract, always specify the **proxy address**, not the implementation address.
:::
**c. Select events to index**
```bash
? Which events would you like to index?
> [x] ClaimRewards(address indexed from, address indexed reward, uint256 amount)
[x] Deposit(address indexed from, uint256 indexed tokenId, uint256 amount)
[x] NotifyReward(address indexed from, address indexed reward, uint256 indexed epoch, uint256 amount)
[x] Withdraw(address indexed from, uint256 indexed tokenId, uint256 amount)
[↑↓ to move, space to select one, → to all, ← to none, type to filter]
```
**d. Finish or add more contracts**
You'll be prompted to continue adding more contracts or to complete the setup:
```bash
? Would you like to add another contract?
> I'm finished
Add a new address for same contract on same network
Add a new network for same contract
Add a new contract (with a different ABI)
```
---
### 2. Local ABI Import
Choose this method if the contract ABI is unavailable from a block explorer or you're using an unverified contract.
#### Steps:
**a. Select From ABI File**
Choose `From ABI File - Use your own ABI file` in the initialization options.
**b. Specify ABI JSON file**
Provide the path to your local ABI file (JSON format):
```bash
? What is the path to your json abi file?
```
**c. Select events to index**
```bash
? Which events would you like to index?
> [x] ClaimRewards(address indexed from, address indexed reward, uint256 amount)
[x] Deposit(address indexed from, uint256 indexed tokenId, uint256 amount)
[↑↓ to move, space to select one, → to all, ← to none, type to filter]
```
**d. Choose blockchain**
Specify the blockchain your contract is deployed on:
```bash
? Choose network:
>
abstract
amoy
arbitrum-nova
...
[↑↓ to move, enter to select, type to filter]
```
Choose `` for a chain that isn't listed. For a chain HyperSync doesn't support, you'll be asked for an RPC URL and a start block.
**e. Enter contract details**
- **Contract name**
```bash
? What is the name of this contract?
```
- **Contract address**
```bash
? What is the address of the contract?
[Use the proxy address if your abi is a proxy implementation]
```
**f. Finish or add more contracts**
Complete the import process or continue adding contracts:
```bash
? Would you like to add another contract?
> I'm finished
Add a new address for same contract on same network
Add a new network for same contract
Add a new contract (with a different ABI)
```
---
## Generated Files & Configuration
The Quickstart automatically generates key files:
### 1. `config.yaml`
Automatically configured parameters include:
- **Network ID**
- **Start Block**
- **Contract Name**
- **Contract Address**
- **Event Signatures**
By default, all selected events are included, but you can manually adjust the file if needed. See the detailed guide on [`config.yaml`](https://docs.envio.dev/docs/HyperIndex/configuration-file.md).
### 2. GraphQL Schema
- Entities are automatically generated for each selected event.
- Fields match the event parameters emitted.
See more details in the [schema file guide](https://docs.envio.dev/docs/HyperIndex/schema.md).
### 3. Event Handlers
- Handlers are autogenerated for each event.
- Handlers create event-specific entities.
Learn more in the [event handlers guide](https://docs.envio.dev/docs/HyperIndex/event-handlers.md).
---
**Congratulations!** Your HyperIndex indexer is now ready to run and query data!
Next step: [Running your Indexer locally](https://docs.envio.dev/docs/HyperIndex/running-locally.md) or [Deploying to Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service.md).
---
## Other Ways to Start
Contract Import is the recommended path, but you can also bootstrap an indexer from:
- **Templates** - pre-built `ERC20` or [Greeter](https://docs.envio.dev/docs/HyperIndex/greeter-tutorial.md) projects, selectable from the `pnpx envio init` interactive prompt.
- **Examples** - copy and adapt an existing indexer from our [Examples](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer.md), our [Tutorials](https://docs.envio.dev/docs/HyperIndex/tutorial-erc20-token-transfers.md), or the [GitHub repositories](https://github.com/enviodev).
---
# Quickstart with AI
> Build an Envio HyperIndex indexer with an AI coding assistant using the Envio CLI, the envio-cloud CLI, and the built-in Claude skills in HyperIndex v3.
Build an Envio HyperIndex indexer end-to-end with an AI coding assistant.
Most developers now reach for an AI coding assistant before they open a file. This guide walks through an AI-centric flow for creating, developing, and deploying a HyperIndex indexer. It is semi-generic, so any capable AI coding assistant (Cursor, Codex, Windsurf, Copilot Agent, Continue, etc.) will work. That said, **we've seen the best results with [Claude Code](https://claude.com/claude-code)** and recommend starting there.
:::tip Prefer the interactive flow?
If you'd rather drive the CLI yourself, see the [Quickstart](https://docs.envio.dev/docs/HyperIndex/quickstart).
:::
---
## Prerequisites
- **[Node.js](https://nodejs.org/en/download/current)** _(v22.15 or newer)_
- **[pnpm](https://pnpm.io/installation)** _(recommended but not required)_
- **[Docker Desktop](https://www.docker.com/products/docker-desktop/)** _(only needed to run the indexer locally)_
- An AI coding assistant (we recommend **[Claude Code](https://claude.com/claude-code)**)
---
## Step 1. Initialize The Indexer
Open Claude Code, Codex or Cursor and prompt:
```bash
pnpx envio init
```
### Built for AI Agents
When `envio init` runs under an agent without a subcommand, it doesn't open the interactive prompts. It prints a plan for the agent to stderr and exits with code `2`. Code `2` means "the agent has a follow-up step", not a failure. The plan tells the agent to ask you for an API token if `ENVIO_API_TOKEN` isn't set, work out the chain and contract from your goal, and then run `envio init` again with flags.
`envio init` treats the session as an agent when `CLAUDECODE` or `CI` is set, when `TERM` is `dumb`, or when stdout is not a terminal. Set `ENVIO_TUI` to override this: `true` or `1` forces the interactive prompts, `false` or `0` forces agent mode.
In agent mode, every answer comes from flags. Always pass the directory (`-d`) and `--single-contract --all-events`, so nothing waits for input. To import a verified contract from a block explorer:
```bash
pnpx envio init contract-import explorer \
-n my-indexer \
-c 0xA0b86991c6218b36c1d19D4a2e9Eb0cE3606eB48 \
-b ethereum-mainnet \
--single-contract --all-events \
-d my-indexer
```
Here `-b` takes a network name, such as `ethereum-mainnet` or `base`, not a chain ID, even though the printed plan shows `-b ${chainId}`. Run `pnpx envio init contract-import explorer --help` for the list of names. To import from an ABI file instead, `-b` takes a name or a chain ID:
```bash
pnpx envio init contract-import -c local \
-a ./abis/MyContract.json --contract-name MyContract \
-b 8453 \
--single-contract --all-events \
-d my-indexer
```
For a chain HyperSync doesn't support, add `-r -s ` to the `local` command. Other flags: `-l typescript|rescript` (default `typescript`) and `--package-manager pnpm|npm|yarn|bun` (default pnpm when it's installed, otherwise npm). Run `pnpx envio init --help`, or see the [Envio CLI reference](https://docs.envio.dev/docs/HyperIndex/cli-commands), for every option.
`envio init` then writes the project, runs codegen, installs dependencies and initializes a git repository. It ends by suggesting `pnpm test` as the first command for an agent.
To read these docs from the terminal, an agent can run `envio tools search-docs ""` and `envio tools fetch-docs ` (Envio 3.1 and newer). They print plain text and need no setup or token.
### Skills For Your Agent
`envio init` adds 17 skills to the new project's `.claude/skills/` folder, one `SKILL.md` per topic: config, schema, handlers, testing, factory contracts, wildcard indexing, event filters, block handlers, multichain, external calls, transactions, traces, performance, troubleshooting, running several indexers locally, the `envio-cloud` CLI and searching the docs. Claude Code loads them automatically.
`envio init` doesn't create an `AGENTS.md`, an `.agents/` folder or Cursor rules. If your agent doesn't load skills from `.claude/skills/`, tell it to read them first, for example: "Read every `SKILL.md` under `.claude/skills/` before you change the indexer."
After you upgrade `envio`, refresh the skills from the project root (Envio 3.0 and newer):
```bash
pnpm envio skills update
```
It rewrites every skill whose `SKILL.md` has `metadata.managed-by: envio`, deletes the skills that older versions shipped under other names, and leaves your own skills alone.
### About Envio API Token
The **Envio API token** is your **HyperSync API token**. A few things to know:
- The token **can't currently be created programmatically**. You generate one by logging in to [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens) and copying it into `ENVIO_API_TOKEN` in your indexer's `.env`. An agent can't do this step for you.
- It's **only required for local development and self-hosted deployments**. Indexers running on **Envio Cloud** get special access and don't need a custom token.
- It's **required when using Envio as the data provider (HyperSync)**. If you only use an external RPC as the data source, no token is needed.
- `envio init` reads the token from `--api-token` or the `ENVIO_API_TOKEN` environment variable and writes it to the new project's `.env`. In agent mode it stops with an error when the indexer uses HyperSync and neither is set. Pass `--api-token ""` to create the project without a token and add it to `.env` later. Until then the agent can still run codegen, type-check and run tests that use `simulate`, but tests that fetch real blocks fail with "An Envio API token is required".
- To run `pnpm dev` locally, generate a token from the link above and set `ENVIO_API_TOKEN` in `.env` before starting the indexer.
See [API Tokens](https://docs.envio.dev/docs/HyperSync/api-tokens) and [Environment Variables](https://docs.envio.dev/docs/HyperIndex/environment-variables) for full details.
---
## Step 2. The Development Loop
The skills cover config, schema, handlers, dynamic contracts, testing, and troubleshooting, so an agent can read them directly instead of inventing patterns. A productive loop looks like:
1. Describe the behavior you want in plain English.
2. Let the assistant edit `config.yaml`, `schema.graphql`, and `src/handlers`.
3. Have it follow a test-driven loop: write a failing test with [`createTestIndexer()`](https://docs.envio.dev/docs/HyperIndex/testing), implement the handler, then run `pnpm test` to capture and lock in snapshots. See the [Testing guide](https://docs.envio.dev/docs/HyperIndex/testing) for the full TDD workflow.
4. Iterate on failures together.
The three files your agent will spend most of its time in:
- **[`config.yaml`](https://docs.envio.dev/docs/HyperIndex/configuration-file)**: chains, contracts, events
- **[`schema.graphql`](https://docs.envio.dev/docs/HyperIndex/schema)**: entities and relationships
- **[`src/handlers`](https://docs.envio.dev/docs/HyperIndex/event-handlers)**: per-event logic
---
## Step 3. Migrating an Existing Indexer
If you're porting from The Graph, Ponder, or another indexing framework, start with the AI migration workflow. It scales much better than hand-editing handlers.
- **[Migrate Using AI](https://docs.envio.dev/docs/HyperIndex/migrate-with-ai)**: the recommended assistant-driven flow. It's written around subgraphs, but the same **monorepo-plus-phased-prompt** pattern works for **Ponder** and other frameworks. Point the assistant at the source project plus a freshly scaffolded HyperIndex indexer and let the skills guide it.
- [Migrate from The Graph (manual)](https://docs.envio.dev/docs/HyperIndex/migration-guide)
- [Migrate from Ponder](https://docs.envio.dev/docs/HyperIndex/migrate-from-ponder)
- [Migrate from Alchemy](https://docs.envio.dev/docs/HyperIndex/migrate-from-alchemy)
---
## Step 4. Deploy Programmatically with `envio-cloud`
Once your indexer runs locally, the [`envio-cloud` CLI](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli) lets an assistant (or a CI job) deploy and manage the hosted indexer without opening the dashboard. Envio Cloud builds from GitHub, so the assistant deploys by pushing a commit.
Two steps need you in a browser, once: sign in at [envio.dev](https://envio.dev/app/login) with GitHub, and install the Envio Deployments GitHub App on the repository. After that, an agent can run the loop:
```bash
npm install -g envio-cloud
envio-cloud login # uses ENVIO_GITHUB_TOKEN or a signed-in gh CLI, else opens a browser
envio-cloud indexer add --name my-indexer --repo my-repo --branch main --yes
git push origin main
COMMIT=$(git rev-parse HEAD | cut -c1-7)
envio-cloud indexer commits my-indexer -o json # did the commit deploy?
envio-cloud deployment logs my-indexer $COMMIT --build
envio-cloud deployment status my-indexer $COMMIT --watch-till-synced --timeout 30m
```
- Envio Cloud identifies a deployment by the first 7 characters of its commit hash.
- Pass `--yes`, or `indexer add` waits for a confirmation. Set `--branch` to the branch you push: the default is `envio`.
- `--watch-till-synced` exits once every chain is ready. `--timeout` bounds the wait: when it runs out, the command exits with code `124` (not synced yet), so run it again.
Most commands support `-o json`, which makes it easy for assistants and scripts to parse results. See [Deploy From an Agent or CI](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli#deploy-from-an-agent-or-ci) for commit statuses, JSON shapes and exit codes.
---
## Related Resources
- [MCP Server](https://docs.envio.dev/docs/HyperIndex/mcp-server)
- [Docs index for agents (llms.txt)](https://docs.envio.dev/llms.txt)
- [HyperIndex context file for agents](https://docs.envio.dev/llms-hyperindex.txt)
- [Envio CLI reference](https://docs.envio.dev/docs/HyperIndex/cli-commands)
- [Envio Cloud CLI](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli)
- [Migrate Using AI](https://docs.envio.dev/docs/HyperIndex/migrate-with-ai)
- [HyperIndex v3 migration](https://docs.envio.dev/docs/HyperIndex/migrate-to-v3)
---
# Configuration File (config.yaml)
> Learn how to configure HyperIndex with contracts, events, chains, and advanced indexing options.
The `config.yaml` file defines your indexer's behavior, including which blockchain events to index, contract addresses, which chains to index, and various advanced indexing options. It is a crucial step in configuring your HyperIndex setup.
:::tip
Whenever you make changes in `config.yaml` that should affect generated types (e.g. adding events, contracts, or chains), run `pnpm codegen` to regenerate types and code for your event handlers.
:::
---
## Example
This is a basic ERC-20 `config.yaml` - it's enough on its own to get an indexer running across Ethereum Mainnet and Gnosis, tracking `Approval` and `Transfer` events on the UNI token.
```yaml
# yaml-language-server: $schema=./node_modules/envio/evm.schema.json
name: erc20-indexer
description: ERC-20 Indexer
contracts:
- name: ERC20
events:
- event: "Approval(address indexed owner, address indexed spender, uint256 value)"
- event: "Transfer(address indexed from, address indexed to, uint256 value)"
chains:
- id: 1 # Ethereum Mainnet
start_block: 0
contracts:
- name: ERC20
address: "0x1f9840a85d5aF5bf1D1762F925BDADdC4201F984" # UNI
- id: 100 # Gnosis Mainnet
start_block: 0
contracts:
- name: ERC20
address: "0x4537e328Bf7e4eFA29D05CAeA260D7fE26af9D74" # UNI
```
**Next steps:**
- Define how each event updates your data → [`src/handlers`](https://docs.envio.dev/docs/HyperIndex/event-handlers.md)
- Shape the entities you'll query → [`schema.graphql`](https://docs.envio.dev/docs/HyperIndex/schema.md)
- Need more than the basics? Keep reading for the full set of configuration options below.
---
## Contracts Definition
The top-level `contracts` block defines each contract once - its events and per-event options. Each chain then references these contracts by `name` and supplies chain-specific values like the on-chain address (see [Contracts (per chain)](#contracts-per-chain)).
```yaml
contracts:
- name: Greeter
events:
- event: "NewGreeting(address user, string greeting)"
- event: "ClearGreeting(address user)"
chains:
- id: 1
start_block: 0
contracts:
- name: Greeter
address: "0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c"
```
### Events Selection
The recommended way to declare events is by their **human-readable signature** directly under `events`:
```yaml
contracts:
- name: Greeter
events:
- event: "NewGreeting(address user, string greeting)"
- event: "ClearGreeting(address user)"
```
Only the events listed here are indexed. To stop indexing an event, remove its entry.
#### Custom Event Names
You can assign custom names to events in `config.yaml`. This is handy when
two events share the same name but have different signatures, or when you want
a more descriptive name in your Envio project.
```yaml
events:
- event: Assigned(address indexed recipientId, uint256 amount, address token)
- event: Assigned(address indexed recipientId, uint256 amount, address token, address sender)
name: AssignedWithSender
```
#### Using an ABI File
If you'd rather reference a JSON ABI file (e.g. when you have one already and want to pick a subset of events from it), use `abi_file_path` and refer to events by name:
```yaml
contracts:
- name: Greeter
abi_file_path: ./abis/greeter.json
events:
- event: NewGreeting # signature comes from the ABI file
```
Event signatures are still the recommended default - they keep `config.yaml` self-contained and easier to review.
### Field Selection
To improve indexing performance and reduce credits usage, the `block` and `transaction` fields on events contain only a subset of the fields available on the blockchain.
Since **v3.7** the recommended way to ask for more is the handler's own [`fields` option](https://docs.envio.dev/docs/HyperIndex/event-handlers#selecting-block-and-transaction-fields), which lists the fields next to the code that reads them and applies to that registration only.
`field_selection` in `config.yaml` is the older, coarser alternative: it applies to every handler of an event. Specify it under the event entry:
```yaml
events:
- event: "Assigned(address indexed user, uint256 amount)"
field_selection:
transaction_fields:
- transactionIndex
block_fields:
- miner
```
`block.number`, `block.timestamp` and `block.hash` are always included and can't be listed; codegen rejects them as an `unknown variant`. See all possible options in the [Config File Reference](https://docs.envio.dev/docs/HyperIndex/config-schema-reference#fieldselection) or use IDE autocomplete for your help.
#### Global Field Selection
You can also specify fields globally for all events in the root of the config file:
```yaml
field_selection:
transaction_fields:
- hash
- gasUsed
block_fields:
- parentHash
```
Try to use this option sparingly as it can cause redundant Data Source calls and increased credits usage. A handler's `fields` option overrides `field_selection` for that registration.
---
## Chains
Everything under the top-level `chains` field configures the chains your indexer connects to - data sources, start/end blocks, reorg behavior, and [multichain indexing](https://docs.envio.dev/docs/HyperIndex/multichain-indexing) semantics.
### RPC
The `rpc` option configures an RPC data source per chain. It supports multiple URLs with explicit roles via the `for` field:
- `sync` – use this RPC for historical sync.
- `realtime` – use this RPC for low-latency head tracking once the indexer enters realtime mode.
- `fallback` – use as a fallback when the primary source is unavailable.
When `for` is omitted, it defaults to `fallback` on chains HyperSync supports and to `sync` on other chains. The `url` must start with `http://` or `https://`. A WebSocket endpoint goes in the separate [`ws`](#websocket-height-streaming) field.
:::tip Optional for HyperSync chains
For chains supported by [HyperSync](https://docs.envio.dev/docs/HyperIndex/hypersync.md), `rpc` is **not required** - HyperSync is used as the primary data source out of the box. You can still add an RPC entry as a fallback for extra reliability. For chains without HyperSync, `rpc` is required and acts as the primary data source.
:::
```yaml
chains:
- id: 1
start_block: 0
rpc:
- url: https://eth-mainnet.your-rpc-provider.com
for: sync
- url: https://eth-mainnet.your-rpc-provider.com
ws: wss://eth-mainnet.your-rpc-provider.com
for: realtime
- url: https://fallback.example.com
for: fallback
```
A short form is also supported when you only need a single RPC URL:
```yaml
chains:
- id: 1
start_block: 0
rpc: https://eth-mainnet.your-rpc-provider.com
```
Since v3.14.1, an entry whose `url` is empty is skipped. That makes an optional RPC possible: `url: ${ENVIO_FALLBACK_RPC_URL:-}` adds the RPC only when the variable is set. Earlier versions reject the empty entry.
After switching to a fallback source, HyperIndex automatically attempts to recover to the primary source 60 seconds later.
See the [Rpc reference](https://docs.envio.dev/docs/HyperIndex/config-schema-reference#def-rpc) for advanced tuning options such as `initial_block_interval`, `polling_interval`, `query_timeout_millis`, and backoff parameters.
#### Custom Headers
Since v3.3, `headers` sets custom HTTP headers on an RPC entry - for endpoints gated behind an auth header rather than a key in the URL. Values support `${ENV_VAR}` interpolation:
```yaml
chains:
- id: 1
start_block: 0
rpc:
- url: https://eth-mainnet.your-rpc-provider.com
for: sync
headers:
Authorization: "Bearer ${ENVIO_RPC_API_KEY}"
```
See [Custom HTTP Headers](https://docs.envio.dev/docs/HyperIndex/rpc-sync#custom-http-headers) for details.
### WebSocket Height Streaming
Set `ws` on an RPC entry to stream new block heights over a WebSocket (`eth_subscribe("newHeads")`) instead of polling the HTTP `url`. It improves head latency and pairs naturally with `for: realtime`. `ws` must start with `wss://` or `ws://`, and the entry still needs its HTTP `url`, which serves every other request.
```yaml
chains:
- id: 1
start_block: 0
rpc:
url: ${ENVIO_RPC_ENDPOINT}
ws: ${ENVIO_WS_ENDPOINT}
for: realtime
```
:::tip Experimental
WebSocket support for RPC sources is experimental. Please open a GitHub issue if you hit any problems.
:::
### HyperSync Endpoint
By default HyperIndex uses `https://.hypersync.xyz` for every chain HyperSync supports. To point a chain at a different endpoint, set `hypersync_config.url`:
```yaml
chains:
- id: 1
start_block: 0
hypersync_config:
url: https://1.hypersync.xyz
```
A chain can't have both `hypersync_config` and an RPC with `for: sync`; set the RPC to `for: fallback` instead. If a chain has no default HyperSync endpoint and no `for: sync` RPC, codegen fails with `Failed to automatically find HyperSync endpoint for the chain `. Add one of the two to fix it.
### Start Block
`start_block` is required on every chain. It sets the block at which the indexer begins ingesting data. Setting it to `0` is a safe default for HyperSync - it will automatically skip ahead to the first block that contains data for your configured contracts.
```yaml
chains:
- id: 1
start_block: 0 # HyperSync will fast-forward to the first relevant block
contracts:
- name: Greeter
address: "0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c"
```
Since **v3.11** `start_block` also accepts the literal `"latest"`, which starts the indexer from the chain's current head instead of a block you have to look up:
```yaml
chains:
- id: 1
start_block: latest # resolved once, when the indexer is first deployed
```
A chain on `latest` can't also carry per-contract `start_block` overrides.
:::note
The head is resolved once, when the indexer is first deployed, and the block is stored. Resuming reuses it, so downtime is backfilled rather than skipped. Restarting with `-r` resolves `latest` again.
:::
For finer-grained control, see [Per-Contract Start Block Override](#per-contract-start-block-override) and the per-event start block tip below it.
### End Block
Set `end_block` on a chain to stop indexing once that block is reached. Useful for backfills with a known cutoff or one-off snapshots.
```yaml
chains:
- id: 1
start_block: 18000000
end_block: 19000000
contracts:
- name: Greeter
address: "0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c"
```
:::note Don't use this for tests
If you're capping the range to make a deterministic test run, prefer the built-in [testing framework](https://docs.envio.dev/docs/HyperIndex/testing.md) instead - it lets you pin block ranges or feed synthetic events without spinning up a real indexer.
:::
### Contracts (per chain)
Inside each chain you list the contracts you want to index on that chain - referenced by `name` from your top-level [Contracts Definition](#contracts-definition). The chain-level entry is where you pin the on-chain `address` (or list of addresses) and, optionally, a per-contract `start_block`.
:::note
Addresses can be provided in **checksum** format or in **lowercase**.
Envio accepts both and normalizes them internally.
:::
#### Addresses
**Single address:**
```yaml
chains:
- id: 1
start_block: 0
contracts:
- name: MyContract
address: "0x1111111111111111111111111111111111111111"
```
**Multiple addresses for the same contract:**
```yaml
chains:
- id: 1
start_block: 0
contracts:
- name: MyContract
address:
- "0x1111111111111111111111111111111111111111"
- "0x2222222222222222222222222222222222222222"
```
**The same address for several contracts:**
Since v3.9, one address can be registered for more than one contract, so a single deployment can be decoded against several ABIs. This matters for proxies and factory patterns where you don't control the deployed address:
```yaml
chains:
- id: 1
start_block: 0
contracts:
- name: ERC20
address: "0x1111111111111111111111111111111111111111"
- name: ERC4626Vault
address: "0x1111111111111111111111111111111111111111"
```
:::tip
If using a **proxy contract**, always use the **proxy address**, not the implementation address.
:::
#### Per-Contract Start Block Override
By default, contracts use the chain `start_block`. You can also set a per-contract `start_block` to override it. Handy when:
- Contracts were deployed at different blocks
- You only need data from a contract starting at a specific block
- You want to skip unnecessary historical data for some contracts
- Works nicely with [Dynamic Contract Registration](https://docs.envio.dev/docs/HyperIndex/dynamic-contracts)
```yaml
chains:
- id: 1 # ethereum-mainnet
start_block: 18000000 # Default start block for all contracts on this chain
contracts:
- name: ERC20
address:
- "0x1111111111111111111111111111111111111111"
- "0x2222222222222222222222222222222222222222"
start_block: 18500000 # Override for this contract
- name: Greeter
address: "0x9D02A17dE4E68545d3a58D3a20BbBE0399E05c9c"
# Uses chain default (18000000)
```
:::tip Per-event start block
For even finer control, you can also specify a start block per event from your handler using the `where.block.number._gte` filter on `indexer.onEvent`. See [Event Handlers](https://docs.envio.dev/docs/HyperIndex/event-handlers.md) for the full API.
:::
#### Indexer Without Contracts
The `contracts` field is **optional** in V3. You can run an indexer that only uses block handlers (`indexer.onBlock`) without declaring any contracts:
```yaml
name: BlockHandlerOnly
chains:
- id: 1
start_block: 18000000
```
---
## Storage
How indexed data is persisted - which backends to use and whether to keep raw event records around.
### Storage Backends
By default, HyperIndex writes entities to Postgres. In V3 you can additionally enable **ClickHouse** as a second storage backend (experimental):
```yaml
storage:
postgres: true
clickhouse: true
```
With both enabled, set where each entity is kept with the `@storage` directive in `schema.graphql`:
```graphql
# Stored in both Postgres and ClickHouse
type Transfer @storage(postgres: true, clickhouse: true) {
id: ID!
from: String!
to: String!
value: BigInt!
}
# Stored only in ClickHouse
type Snapshot @storage(clickhouse: true) {
id: ID!
blockNumber: BigInt!
}
```
Handlers read and write every entity, including those kept only in ClickHouse. Add `postgres: true` to any entity you want to query over GraphQL. See [Choosing a Storage Backend](https://docs.envio.dev/docs/HyperIndex/schema#choosing-a-storage-backend-storage).
You can also set a default in `config.yaml`. Mark one or both backends as `default` so every entity without a directive is written there, and reach for the `@storage` directive only when you need to override routing for a specific entity:
```yaml
storage:
postgres:
default: true
clickhouse:
default: true
```
:::note
The `default` storage option was added in HyperIndex v3.2.
:::
`envio dev` automatically spins up a ClickHouse Docker container for local development. For `envio start`, provide the connection via the environment variables `ENVIO_CLICKHOUSE_HOST`, `ENVIO_CLICKHOUSE_DATABASE`, `ENVIO_CLICKHOUSE_USERNAME`, and `ENVIO_CLICKHOUSE_PASSWORD`.
:::warning
Do not run multiple indexers writing to the same ClickHouse database at the same time.
:::
Envio Cloud currently supports ClickHouse on the Dedicated Plan.
Since v3.4, the `@storage` directive's `clickhouse` argument also accepts an options object for per-entity table tuning - partitioning, sorting key and TTL. See [Per-Entity ClickHouse Tuning](https://docs.envio.dev/docs/HyperIndex/schema#per-entity-clickhouse-tuning).
### Column Name Format
Set `column_name_format: snake_case` on a backend to store column names in `snake_case` while keeping the original names in the GraphQL API and your handler types. It works for both Postgres and ClickHouse:
```yaml
storage:
postgres:
column_name_format: snake_case
clickhouse:
column_name_format: snake_case
```
:::note
Added in HyperIndex v3.2.
:::
---
## Address Format
Use `address_format` to control how every address surfaced by the indexer (event fields like `event.srcAddress` / `event.transaction.from`, `chain..addresses`, addresses embedded in entity ids, etc.) is formatted.
```yaml
address_format: lowercase # default: checksum
```
- `checksum` (default) – [EIP-55](https://eips.ethereum.org/EIPS/eip-55) checksummed mixed-case addresses.
- `lowercase` – every address is lowercased globally. Useful when joining against another data source that stores addresses in lowercase, or when you want byte-for-byte deterministic ids without per-handler `.toLowerCase()` calls.
You can still call `.toLowerCase()` ad-hoc inside a handler when you only need a single value lowercased.
---
## Bytes Representation
`bytes_type` controls how the `Bytes` scalar from `schema.graphql` reaches handlers and storage.
```yaml
bytes_type: uint8array # default: hex
```
- `hex` (default) – `0x`-prefixed hex strings, stored as text.
- `uint8array` – `Uint8Array` values in handlers, stored as raw bytes (`BYTEA` in Postgres, `String` in ClickHouse). Roughly halves the storage taken by addresses and hashes.
Available on EVM and Fuel. Solana always uses `Uint8Array` and has no option. Changing the setting changes the underlying column types, so switch it with a fresh sync.
:::note
Added in HyperIndex v3.10.
:::
---
## Per-Chain Entities
By default one entity id means one row shared by every chain. Set `disable_default_cross_chain: true` (recommended for multichain indexers) to make entities and effect caches per-chain instead:
```yaml
name: my-indexer
disable_default_cross_chain: true
```
Entity tables then get a composite `(id, chainId)` primary key, so the same id on two chains is two independent rows, and sharing becomes explicit through the `@crossChain` directive. See [Per-Chain Data Mode](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode) for the full behavior.
:::note
Added in HyperIndex v3.6.
:::
---
## Ecosystem
`ecosystem` selects which chain family your indexer targets. EVM is the default and what every example above assumes, but the same `config.yaml` schema is shared with Fuel and Solana (SVM).
```yaml
ecosystem: evm # default; also: fuel, svm
```
Most projects don't set this field explicitly. Use `pnpx envio init fuel` or `pnpx envio init svm` to scaffold non-EVM indexers - the generated `config.yaml` will already have `ecosystem` set correctly. See the [Fuel](https://docs.envio.dev/docs/HyperIndex/fuel.md) and [Solana](https://docs.envio.dev/docs/HyperIndex/solana.md) guides for the ecosystem-specific options.
---
## Environment Variables
Environment variable interpolation is supported anywhere in `config.yaml`, which is useful for keeping RPC URLs, addresses, or chain IDs out of source control. Variables are substituted into the raw text before the YAML is parsed, so the result must still be valid config: a chain `id` must resolve to a number, not a chain name.
```yaml
chains:
- id: ${ENVIO_CHAIN_ID:-1}
start_block: 0
contracts:
- name: Greeter
address: "${ENVIO_GREETER_ADDRESS}"
```
Run your indexer with custom environment variables:
```bash
ENVIO_CHAIN_ID=10 ENVIO_GREETER_ADDRESS=0xYourContractAddress pnpm dev
```
**Interpolation syntax:**
- `${ENVIO_VAR}` – Use the value of `ENVIO_VAR`. Codegen fails with `Environment variables are not present: ENVIO_VAR` when it is unset.
- `${ENVIO_VAR:-default}` – Use `ENVIO_VAR` if set and not empty, otherwise use `default`
- `${ENVIO_VAR-default}` – Use `default` only when `ENVIO_VAR` is unset
Values come from the shell environment first, then from the `.env` file in the project root. Locally any name made of letters, digits and underscores works, but [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service-deployment) only accepts variables prefixed with `ENVIO_`, so use the prefix to keep the config portable.
For more detailed information about environment variables, see our [Environment Variables Guide](https://docs.envio.dev/docs/HyperIndex/environment-variables.md).
---
## Advanced
:::note
In ~95% of cases you don't need to touch any of these - the defaults are tuned for the common path. Reach for them only when you have a specific reason.
:::
### Handler File Path
Handlers are auto-discovered from `src/handlers/`. Override the directory with the top-level `handlers` option, or set a per-contract `handler` path when needed:
```yaml
handlers: ./src/my-handlers # optional override of src/handlers
contracts:
- name: Greeter
handler: ./src/GreeterHandler.ts # optional per-contract path
```
### Schema File Path
You can customize the path to the [schema file](https://docs.envio.dev/docs/HyperIndex/schema.md) using the `schema` option:
```yaml
schema: ./path/to/schema.graphql
```
By default, the `schema.graphql` is expected to be in the root directory of your project.
### Block Lag
Set `block_lag` on a chain to keep the indexer a fixed number of blocks behind the chain head. Defaults to `0`.
```yaml
chains:
- id: 1
start_block: 0
block_lag: 5
```
:::warning
Only set `block_lag` if you understand the trade-off - it intentionally trades head latency for additional reorg safety.
:::
### Rollback on Reorg
HyperIndex automatically handles blockchain reorganizations by default. To disable or customize this behavior, set the `rollback_on_reorg` flag in your `config.yaml`:
```yaml
rollback_on_reorg: true # default is true
```
See detailed configuration options [here](https://docs.envio.dev/docs/HyperIndex/reorgs-support.md).
### Full Batch Size
Set `full_batch_size` to control how many events are processed in a single batch. Defaults to `5000`. Lower it if your handlers make many slow [Effect API](https://docs.envio.dev/docs/HyperIndex/effect-api) calls that can't be batched.
```yaml
full_batch_size: 5000
```
### Raw Events Storage
By default, HyperIndex doesn't store raw event data in the database to optimize performance and reduce storage requirements. However, you can enable this feature for debugging purposes or if you need to access the original event data.
To enable storage of raw events, add the following to your `config.yaml`:
```yaml
raw_events: true
```
When enabled, all indexed events will be stored in the `raw_events` table in the database, which you can view through the Hasura interface. This is particularly useful for:
- Debugging event processing issues
- Verifying that events are being captured correctly
- Creating custom queries against raw blockchain data
Note that enabling this option will increase database storage requirements and may slightly impact indexing performance.
### Skip Chain
Set `skip: true` on a chain to exclude it from indexing and migrations without removing it from your config - handy for temporarily disabling a chain.
```yaml
chains:
- id: 137
skip: true
start_block: 0
```
:::note
Added in HyperIndex v3.1.
:::
---
## Configuration Schema Reference
Explore detailed configuration schema parameters here:
- See the full, deep-linkable reference: [Config Schema Reference](https://docs.envio.dev/docs/HyperIndex/config-schema-reference)
:::info For AI/LLM Systems
**Recommended**: Use the [Config Schema Reference](https://docs.envio.dev/docs/HyperIndex/config-schema-reference) for programmatic access to schema information. The interactive viewer below is optimized for human users.
:::
---
Now your configuration file is set, you're ready to start indexing with HyperIndex!
---
# Entities Schema (schema.graphql)
> Learn how to define GraphQL schemas, manage entities, and handle different types in HyperIndex.
The **`schema.graphql`** file defines the data model for your HyperIndex indexer. Each entity type defined in this schema corresponds directly to a database table, with your event handlers responsible for creating and updating the records. HyperIndex automatically generates a GraphQL API based on these entity types, allowing easy access to the indexed data.
---
## Defining Entity Types
Entities in your schema are defined as GraphQL object types:
**Example:**
```graphql
type User {
id: ID!
greetings: [String!]!
latestGreeting: String!
numberOfGreetings: Int!
}
```
### Requirements:
- Every entity **must** have a unique `id` field, using one of these scalar types:
- `ID!`, `String!`, `Int!`, or `BigInt!`
- The `id` field must be non-nullable, must not be a list, and cannot be a [`@derivedFrom`](#relationships-one-to-many-derivedfrom) field.
- There is no `@entity` directive: every `type` in the file is an entity.
- An entity name is at most 63 characters. Two entities can't share a name that differs only in the case of its first letter (`user` and `User`), and an entity and an enum can't share a name.
- Entity names, enum names and enum values can't be `enum` or a built-in `Object.prototype` property name such as `constructor`, `toString`, `valueOf`, `hasOwnProperty` or `__proto__`. `envio codegen` rejects them with `Schema contains the following reserved keywords: ...`.
### Numeric Entity IDs
`ID` is the usual choice and behaves as a string. Since v3.5, you can also key an entity on `Int` or `BigInt`, which is a better fit when the identifier is genuinely a number - a block number, an auction id, a sequential position:
```graphql
type Auction {
id: BigInt! # the on-chain auction id, not a stringified copy of it
seller: String!
bids: [Bid!]! @derivedFrom(field: "auction")
}
type Bid {
id: ID!
auction: Auction! # inferred as BigInt to match Auction.id
amount: BigInt!
}
```
Relationship fields adopt the referenced entity's id type automatically. Codegen exposes `Bid.auction` above to your handlers as `auction_id`, typed `bigint` rather than `string`. You don't declare the foreign key type. Keep the two sides in sync by changing the referenced entity's `id`.
---
## Scalar Types
Scalar types represent basic data types and map directly to JavaScript, TypeScript, or ReScript types.
| **GraphQL Scalar** | **Description** | **JavaScript/TypeScript** | **ReScript** |
| --- | --- | --- | --- |
| `ID` | Unique identifier | `string` | `string` |
| `String` | UTF-8 character sequence | `string` | `string` |
| `Int` | Signed 32-bit integer | `number` | `int` |
| `Float` | Signed floating-point number | `number` | `float` |
| `Boolean` | `true` or `false` | `boolean` | `bool` |
| `Bytes` | Byte string (see [`bytes_type`](#bytes-representation)) | `string` or `Uint8Array` | `string` |
| `BigInt` | Signed integer (`int256` in Solidity) | `bigint` | `bigint` |
| `BigDecimal` | Arbitrary-size floating-point | `BigDecimal` (imported) | `BigDecimal.t` |
| `Timestamp` | Timestamp with timezone | `Date` | `Js.Date.t` |
| `Json` | JSON value | `JSON` (imported) | `Js.Json.t` |
Learn more about GraphQL scalars [here](https://graphql.org/learn/).
A field without `!` is optional, and its TypeScript type is `T | undefined`, never `null`. `BigDecimal` and `JSON` are exported from `envio`. A `JSON` value can't hold a `bigint`, so store one as its `.toString()`.
The GraphQL scalars The Graph adds, such as `Int8`, are not supported. Use `BigInt` instead.
### Lists
- Write a list as `[Type!]!` (required) or `[Type!]` (optional). Elements can't be nullable, so `[Type]` is rejected.
- Lists of `Boolean` and `Timestamp` are not supported yet.
- A list of entities, such as `[Token!]!`, needs [`@derivedFrom`](#relationships-one-to-many-derivedfrom). To store a list of ids without a relationship, use `[String!]!`.
### Bytes Representation
Since v3.10, the [`bytes_type`](https://docs.envio.dev/docs/HyperIndex/configuration-file#bytes-representation) option in `config.yaml` decides how `Bytes` reaches handlers and storage: `hex` (the EVM and Fuel default) gives a `0x`-prefixed `string` stored as text, `uint8array` gives a `Uint8Array` stored as raw bytes (`BYTEA` in Postgres), which roughly halves the storage taken by addresses and hashes. Solana is always `Uint8Array`.
---
## Working with BigDecimal
The `BigDecimal` scalar type in HyperIndex is based on the [bignumber.js](https://mikemcl.github.io/bignumber.js/) library, which provides arbitrary-precision decimal arithmetic. This is essential for financial calculations and handling numeric values that exceed JavaScript's native number precision.
### Importing BigDecimal
```typescript
import { BigDecimal } from "envio";
```
```rescript
open BigDecimal
```
### Creating BigDecimal Instances
```typescript
// From string (recommended for precision)
const price = new BigDecimal("123.456789");
// From number (may lose precision for very large values)
const amount = new BigDecimal(123.45);
// From other BigDecimal
const copy = new BigDecimal(price);
```
### Arithmetic Operations
BigDecimal instances are immutable. Operations return new BigDecimal instances:
```typescript
// Basic arithmetic
const a = new BigDecimal("123.45");
const b = new BigDecimal("67.89");
const sum = a.plus(b); // 191.34
const difference = a.minus(b); // 55.56
const product = a.times(b); // 8,381.03
const quotient = a.div(b); // 1.81839...
// Power
const squared = a.pow(2); // 15,239.9025
// Square root
const root = a.sqrt(); // 11.11...
// Absolute value
const abs = new BigDecimal("-123.45").abs(); // 123.45
```
### Comparison Methods
```typescript
const x = new BigDecimal("10.5");
const y = new BigDecimal("10.5");
const z = new BigDecimal("9.9");
x.eq(y); // true (equal)
x.gt(z); // true (greater than)
x.gte(y); // true (greater than or equal)
x.lt(z); // false (less than)
x.lte(y); // true (less than or equal)
// Check for special values
x.isZero(); // false
x.isPositive(); // true
x.isNegative(); // false
x.isFinite(); // true
```
### Rounding and Formatting
```typescript
const value = new BigDecimal("123.456789");
// Get with specific decimal places
value.dp(2); // 123.46 (rounded)
value.dp(2, 1); // 123.45 (rounded down)
// Format as string
value.toString(); // "123.456789"
value.toFixed(2); // "123.46"
value.toExponential(2); // "1.23e+2"
value.toPrecision(5); // "123.46"
```
### Working with Schema-Defined BigDecimal Fields
When you've defined a `BigDecimal` field in your schema:
```graphql
type TokenPair {
id: ID!
name: String!
price: BigDecimal!
volume: BigDecimal!
}
```
You can use it in your handlers:
```typescript
// In your event handler
context.TokenPair.set({
id: event.params.pairId,
name: event.params.name,
price: new BigDecimal(event.params.price),
volume: new BigDecimal("0"), // Start with zero volume
});
// Updating a field
const tokenPair = await context.TokenPair.get(pairId);
if (tokenPair) {
const newVolume = tokenPair.volume.plus(new BigDecimal(tradeAmount));
context.TokenPair.set({
...tokenPair,
volume: newVolume,
});
}
```
### Example: Financial Calculation
```typescript
function calculateFee(amount: BigDecimal, feeRate: BigDecimal): BigDecimal {
// Calculate fee with proper rounding
return amount.times(feeRate).dp(2);
}
const tradeAmount = new BigDecimal("1250.75");
const feeRate = new BigDecimal("0.0025"); // 0.25%
const fee = calculateFee(tradeAmount, feeRate); // 3.13
```
### Best Practices for BigDecimal
1. **Always use strings for initialization** when precision matters:
```typescript
// Preferred
const value = new BigDecimal("123.456789");
// May lose precision
const value = new BigDecimal(123.456789);
```
2. **Set precision explicitly** when doing division:
```typescript
// Set to 8 decimal places for crypto prices
const price = totalValue.div(tokenAmount).dp(8);
```
3. **Handle rounding appropriately** for financial calculations:
```typescript
// Round down (floor) for user-favorable calculations
const userReceives = amount.dp(2, 1); // ROUND_DOWN
// Round up (ceil) for protocol-favorable calculations
const protocolFee = amount.dp(2, 0); // ROUND_UP
```
4. **Compare with equals method** instead of `==` or `===`:
```typescript
// Correct
if (value.eq(new BigDecimal(0))) {
/* ... */
}
// Incorrect - compares object references
if (value === new BigDecimal(0)) {
/* ... */
}
```
5. **Chain operations carefully**, remembering that each operation returns a new instance:
```typescript
// Calculate (a + b) * c with proper precision
const result = a.plus(b).times(c).dp(8);
```
---
## Enum Types
Enums allow fields to accept only a predefined set of values.
**Example:**
```graphql
enum AccountType {
ADMIN
USER
}
type User {
id: ID!
balance: Int!
accountType: AccountType!
}
```
Enums translate to string unions (TypeScript/JavaScript) or polymorphic variants (ReScript):
**TypeScript Example:**
```typescript
import { type Enum } from "envio";
let user = {
id: event.params.id,
balance: event.params.balance,
accountType: "USER" satisfies Enum<"AccountType">, // enum as string
};
```
**ReScript Example:**
```rescript
let user: Entities.User.t = {
id: event.params.id,
balance: event.params.balance,
accountType: #USER, // polymorphic variant
};
```
---
## Relationships: One-to-Many (`@derivedFrom`)
Define relationships between entities using the `@derivedFrom` directive, known as **reverse lookups**.
**Example:**
```graphql
type NftCollection {
id: ID!
contractAddress: Bytes!
name: String!
symbol: String!
maxSupply: BigInt!
currentSupply: Int!
tokens: [Token!]! @derivedFrom(field: "collection")
}
type Token {
id: ID!
tokenId: BigInt!
collection: NftCollection!
owner: User!
}
```
- The `tokens` field in `NftCollection` is a virtual field, populated automatically when querying the API. It doesn't exist on the entity your handlers read, and `getWhere` can't filter on it.
- `@derivedFrom(field: "collection")` names the field as written in the schema on the other entity (`collection`), never `collection_id`.
- Set relationships in your handlers by assigning `_id` with the related entity's `id`. For example, create or update a `Token` entity with `collection_id: collectionId`. Don't add `_id` to the field name in the schema; codegen adds it.
---
## Field Indexing (`@index`)
Add an index to a field for optimized queries and loader performance:
```graphql
type Token {
id: ID!
tokenId: BigInt!
collection: NftCollection!
owner: User! @index
}
```
- All `id` fields and fields referenced via `@derivedFrom` are indexed automatically.
- Declare `@index` for the fields your GraphQL consumers filter and sort by. You don't need it for fields your handlers query with [`getWhere`](https://docs.envio.dev/docs/HyperIndex/event-handlers#retrieving-entities-by-field) - since v3.5 HyperIndex creates those indices itself. See [Indices created on demand](https://docs.envio.dev/docs/HyperIndex/database-performance-optimization#indices-created-on-demand).
- `@index` can't go on `id` or on a `@derivedFrom` field.
- For an index over several fields, put `@index(fields: [...])` on the type. See [Composite Indices](https://docs.envio.dev/docs/HyperIndex/database-performance-optimization#composite-indices-for-multi-field-queries).
- A PostgreSQL index entry holds at most about 2.7 KB. If an indexed `String` field receives a longer value, the write fails with a PostgreSQL `index row ...` error, which stops the indexer. Truncate unbounded strings, such as names taken from events, before you store them in an indexed field. The same applies to fields `getWhere` filters on, because those get an index too.
---
## Choosing a Storage Backend (`@storage`)
When you enable more than one storage backend in `config.yaml`, the `@storage` directive sets where each entity is kept:
```graphql
# Queryable over GraphQL and mirrored into ClickHouse for analytics
type Transfer @storage(postgres: true, clickhouse: true) {
id: ID!
amount: BigInt!
}
# Kept in ClickHouse alone
type Snapshot @storage(clickhouse: true) {
id: ID!
from: String!
value: BigInt!
}
```
To skip the directive on most entities, mark a backend as `default` in `config.yaml`. See [`storage`](https://docs.envio.dev/docs/HyperIndex/config-schema-reference#storage).
Handlers use the same entity API whichever backend holds the data. `get`, `getOrThrow`, `getOrCreate`, `getWhere`, `set` and `deleteUnsafe` all work on entities kept in ClickHouse alone:
```ts
const snapshots = await context.Snapshot.getWhere({
from: { _eq: event.params.from },
});
```
For entities kept in ClickHouse alone:
- GraphQL serves the entities kept in Postgres. Add `postgres: true` to any entity your API needs to query.
- Postgres stays enabled for the indexer state (chains, checkpoints, addresses, effect caches and raw events), even when every entity lives in ClickHouse.
- An entity with a `ttl` in its ClickHouse options is write-only from handlers, because ClickHouse drops expired rows when it merges them. Add `postgres: true` or remove the `ttl` if a handler needs to read it.
- `@index` doesn't create an index in ClickHouse, so `getWhere` on a field outside the sorting key scans the table. Put the fields you filter on most in `orderBy` (see below).
### Per-Entity ClickHouse Tuning
Since v3.4, the `clickhouse` argument also accepts an options object that tunes that entity's ClickHouse history table:
```graphql
type Transfer
@storage(
postgres: true
clickhouse: {
partitionBy: "toYYYYMM(timestamp)"
orderBy: ["timestamp"]
ttl: "timestamp + INTERVAL 2 YEAR"
skippingIndexes: [
{ name: "idx_amount", expr: "amount", type: "minmax", granularity: 4 }
]
}
) {
id: ID!
timestamp: Timestamp!
amount: BigInt!
}
```
| Option | Type | Description |
| --- | --- | --- |
| `partitionBy` | ClickHouse expression | Emitted as `PARTITION BY `. Keeps queries and TTL deletes inside a partition instead of scanning the whole table. |
| `orderBy` | list of entity field names | Fields that lead the table's sorting key, ahead of the default `id`. |
| `ttl` | ClickHouse expression | Emitted as `TTL `. Ages rows out automatically. |
| `skippingIndexes` | list of index objects | Since v3.8. Data skipping indexes emitted into the history table DDL as `INDEX TYPE GRANULARITY `. Each entry takes `name`, `expr`, `type` (e.g. `minmax`, `bloom_filter`, `set`) and an optional `granularity`, which defaults to ClickHouse's own default. |
A few constraints, all caught at `envio codegen` rather than at runtime:
- `orderBy` takes **entity field names**, not expressions - unlike `partitionBy` and `ttl`, which are ClickHouse expressions passed through as written.
- `orderBy` can't list `id` (already the default sorting key), nor nullable, list or `@derivedFrom` fields, which ClickHouse doesn't allow in a sorting key.
- An entity can carry only one `@storage` directive, and it must enable at least one backend.
- With [`disable_default_cross_chain: true`](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode), `orderBy` can also list the generated `chainId` column (v3.9).
---
## Sharing Entities Across Chains (`@crossChain`)
Entities are shared by every chain by default: one id means one row, whichever chain wrote it. Setting [`disable_default_cross_chain: true`](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode) in `config.yaml` (v3.6, recommended for multichain indexers) flips that - entities become per-chain, keyed on `(id, chainId)` - and `@crossChain` marks the individual entities that should stay shared:
```graphql
type Counter {
# per-chain: one row per (id, chain)
id: ID!
count: BigInt!
}
type GlobalCounter @crossChain {
# one row shared by every chain
id: ID!
count: BigInt!
}
```
The directive is only valid when `disable_default_cross_chain: true` is set - without it entities are already cross-chain, and `envio codegen` rejects the directive. Per-chain entities also reserve the `chainId` column name (`chain_id` under `column_name_format: snake_case`), so a schema field can't claim it.
---
## Hiding Entities from the API (`@internal`)
Since v3.8.0, mark an entity with `@internal` to keep it out of the GraphQL API. The entity is stored and usable in handlers exactly as normal - `set`, `get`, `getWhere` and `getOrThrow` all work - but it is never exposed through GraphQL: no queries, no relationships, no introspection entry.
```graphql
# Bookkeeping state the indexer needs, but API consumers shouldn't see
type SwapCheckpoint @internal {
id: ID!
lastProcessedLogIndex: Int!
pendingAmount: BigInt!
}
```
Use it for internal indexing state (cursors, checkpoints, deduplication markers, intermediate aggregates) or for data you don't want on the public API surface.
A few rules, enforced at `envio codegen`:
- An exposed entity can't reference an `@internal` one - neither through an object reference nor a [`@derivedFrom`](#relationships-one-to-many-derivedfrom) field - because the relationship could never be served over GraphQL. Either mark the referencing entity `@internal` too, or store a plain id field (e.g. `checkpointId: String!`) instead of a relationship.
- The reverse is fine: an `@internal` entity may freely reference exposed entities.
---
## Advanced: Precision and Scale (`@config` Directive)
Customize the precision and scale for `BigInt` and `BigDecimal` fields using `@config`.
**Syntax:**
- `BigInt` (precision only):
```graphql
amount: BigInt @config(precision: 76)
```
- `BigDecimal` (precision and scale):
```graphql
price: BigDecimal @config(precision: 10, scale: 2)
```
**Example:**
```graphql
type Payment {
id: ID!
amount: BigInt @config(precision: 76)
price: BigDecimal @config(precision: 10, scale: 2)
}
```
This controls PostgreSQL storage allocation and numerical accuracy. Without `@config`, both types are stored as PostgreSQL `NUMERIC` with no fixed precision or scale. On a `BigDecimal`, `@config` needs both `precision` and `scale`. On a `BigInt` it takes `precision` only, and on any other type it is an error.
Detailed Example with Arrays
```graphql
type AdvancedEntity {
id: ID!
exampleBigInt: BigInt @config(precision: 76)
exampleBigIntRequired: BigInt! @config(precision: 77)
exampleBigIntArray: [BigInt!] @config(precision: 78)
exampleBigIntArrayRequired: [BigInt!]! @config(precision: 79)
exampleBigDecimal: BigDecimal @config(precision: 10, scale: 5)
exampleBigDecimalRequired: BigDecimal! @config(precision: 12, scale: 4)
}
```
---
## Documenting Entities, Fields, and Relationships
You can document your entities, fields, and relationships directly in `schema.graphql` using GraphQL string descriptions. These descriptions are exposed through the generated GraphQL API and appear in introspection, making your API self-documenting.
```graphql
"""
A token transfer between two accounts
"""
type Transfer {
id: ID!
"The address the tokens were sent from"
from: String!
"The address the tokens were sent to"
to: String!
"The amount transferred, in wei"
value: BigInt!
}
```
Both single-line (`"..."`) and multi-line (`"""..."""`) descriptions are supported.
:::note
Only string descriptions are exposed in introspection. Hash (`#`) comments are ignored by the GraphQL parser and do **not** appear in the API. Descriptions on entities, fields, and relationships were added in HyperIndex v3.1.
:::
---
## Generating Types
Once you've defined your schema, run this command to generate these entity types that can be accessed in your event handlers:
```bash
pnpm envio codegen
```
---
## Best Practices
- Use camelCase for field names (`latestGreeting`, `numberOfGreetings`).
- Keep entity and field names clear, descriptive, and intuitive.
---
You're now ready to define powerful schemas and efficiently query your indexed data with HyperIndex!
---
# Event Handlers
> Learn how to register and manage event handlers for efficient data indexing.
## Registration
A handler is a function that receives blockchain data, processes it, and inserts it into the database.
The indexer loads every `.ts`, `.js` and `.mjs` file under `src/handlers/`, including subfolders, and skips files whose names contain `.test.`, `.spec.` or `_test.`. Set `handlers` in `config.yaml` to load a different folder. A contract's `handler` field can also point at one extra file.
```typescript
import { indexer } from "envio";
indexer.onEvent(
{ contract: "", event: "" },
async ({ event, context }) => {
// Your logic here
},
);
```
:::note
The `envio` module exposes the unified `indexer` value along with types based on your `config.yaml` and `schema.graphql` files. Run **`pnpm codegen`** whenever you change these files to regenerate the types in `.envio/`.
:::
A few rules apply to every registration:
- Register at the top level of the file. Calling `indexer.onEvent` after the indexer has started throws ``Cannot call `indexer.onEvent` after the indexer has started``.
- The handler's type is `(args) => Promise`, so write it as an `async` function. The same goes for `indexer.contractRegister` and `indexer.onBlock`.
- The contract and event must exist in `config.yaml`. Otherwise registration throws, for example `Event "Transfer" is not configured on contract "MyToken", so its handler would never run.`
- From v3.14, the indexer type-checks your handler files with the project's own `tsc` before it starts, and refuses to start on a type error in a handler file. Without `typescript` installed or a `tsconfig.json`, it logs a warning and skips the check.
### Basic Example
Here's a handler example for the `NewGreeting` event. It belongs to the `Greeter` contract from our beginners [Greeter Tutorial](https://docs.envio.dev/docs/HyperIndex/greeter-tutorial):
```typescript
import { indexer, type User } from "envio";
// Handler for the NewGreeting event
indexer.onEvent(
{ contract: "Greeter", event: "NewGreeting" },
async ({ event, context }) => {
const userId = event.params.user; // The id for the User entity
const latestGreeting = event.params.greeting; // The greeting string that was added
const currentUserEntity = await context.User.get(userId); // Optional user entity that may already exist
// Update or create a new User entity
const userEntity: User = currentUserEntity
? {
id: userId,
latestGreeting,
numberOfGreetings: currentUserEntity.numberOfGreetings + 1,
greetings: [...currentUserEntity.greetings, latestGreeting],
}
: {
id: userId,
latestGreeting,
numberOfGreetings: 1,
greetings: [latestGreeting],
};
context.User.set(userEntity); // Set the User entity in the DB
},
);
```
### Multiple Handlers for One Event
Since v3.4, you can register as many handlers as you like for the same event, each with its own [`where`](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing) filter. Earlier versions only accepted handlers whose filters matched.
This lets you keep broad and narrow logic in separate functions instead of branching inside one handler:
```typescript
import { indexer } from "envio";
const ZERO_ADDRESS = "0x0000000000000000000000000000000000000000";
// Track every ERC20 transfer on the chain
indexer.onEvent(
{ contract: "ERC20", event: "Transfer", wildcard: true },
async ({ event, context }) => {
// Global accounting
},
);
// ...and run extra logic for mints, where tokens come from the zero address
indexer.onEvent(
{
contract: "ERC20",
event: "Transfer",
wildcard: true,
where: () => ({ params: [{ from: ZERO_ADDRESS }] }),
},
async ({ event, context }) => {
// Mint-specific logic
},
);
```
An event matching more than one registration is delivered to each of them, in registration order.
### Top-Level Await
Handler files are ES modules, so you can `await` at the top level. This is useful for loading data once before registering handlers:
```typescript
import { indexer } from "envio";
const ZERO_ADDRESS = "0x0000000000000000000000000000000000000000";
// Load data before registering handlers
const addressesFromServer = await loadWhitelistedAddresses();
indexer.onEvent(
{
contract: "ERC20",
event: "Transfer",
wildcard: true,
where: {
params: [
{ from: ZERO_ADDRESS, to: addressesFromServer },
{ from: addressesFromServer, to: ZERO_ADDRESS },
],
},
},
async ({ event, context }) => {
// ... your handler logic
},
);
```
### Preload Optimization
> **Important!** Preload optimization makes your handlers run **twice**.
Preload optimization is always enabled in HyperIndex V3 - there is no config flag to toggle it.
This optimization enables HyperIndex to efficiently preload entities used by handlers through batched database queries, while ensuring events are processed synchronously in their original order. When combined with the [Effect API](https://docs.envio.dev/docs/HyperIndex/effect-api) for external calls, this feature delivers performance improvements of multiple orders of magnitude compared to other indexing solutions.
Read more in the dedicated guides:
- [How Preload Optimization Works](https://docs.envio.dev/docs/HyperIndex/preload-optimization)
- [Double-Run Footgun](https://docs.envio.dev/docs/HyperIndex/preload-optimization#double-run-footgun)
- [Effect API](https://docs.envio.dev/docs/HyperIndex/event-handlers#external-calls)
### Advanced Use Cases
HyperIndex provides many features to help you build more powerful and efficient indexers. There's definitely the one for you:
- Handle Factory Contracts with [Dynamic Contract Registration](https://docs.envio.dev/docs/HyperIndex/dynamic-contracts) (with nested factories support)
- Perform external calls to decide which contract address to register using [Async Contract Register](https://docs.envio.dev/docs/HyperIndex/dynamic-contracts#async-contract-register)
- Index all ERC20 token transfers with [Wildcard Indexing](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing)
- Use [Topic Filtering](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing) to ignore irrelevant events
- With [multiple filters for single event](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing#multiple-filters)
- With [different filters per chain](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing#different-filters-per-chain)
- With [filter by dynamicly registered contract addresses](https://docs.envio.dev/docs/HyperIndex/wildcard-indexing#index-all-erc20-transfers-to-your-contract) (eg Index all ERC20 transfers to/from your Contract)
- [Access Contract State](https://docs.envio.dev/docs/HyperIndex/contract-state) directly from handlers
- Perform external calls from handlers by following the [IPFS Integration guide](https://docs.envio.dev/docs/HyperIndex/ipfs)
---
## Event Object
Each handler receives an `event` object containing details about the emitted event, including parameters and blockchain metadata.
### Accessing Event Parameters
Event parameters are accessed via:
```typescript
event.params.
```
Example usage:
```typescript
const sender = event.params.sender;
const amount = event.params.amount;
```
### Additional Event Information
The event object also contains additional metadata:
- `event.chainId` – Chain ID of the chain emitting the event.
- `event.contractName` – Name of the contract the event belongs to, as set in `config.yaml` (eg `"ERC20"`).
- `event.eventName` – Name of the event (eg `"Transfer"`).
- `event.srcAddress` – Contract address emitting the event.
- `event.logIndex` – Index of the log within the block.
- `event.block` – Block fields (By default: `number`, `timestamp`, `hash`).
- `event.transaction` – Transaction fields (eg `hash`, `gasUsed`, etc. Empty by default).
:::tip
By default, all addresses returned in the `event` object, such as `event.transaction.from`,
`event.transaction.to`, and `event.srcAddress`, are [EIP-55](https://eips.ethereum.org/EIPS/eip-55) checksummed.
Use `.toLowerCase()` on a single value if you specifically need it in lowercase, or set
[`address_format: lowercase`](https://docs.envio.dev/docs/HyperIndex/configuration-file#address-format) in `config.yaml` to switch every address that the indexer surfaces (events, `chain..addresses`, entity ids, etc.) to lowercase globally.
:::
:::note
Which fields `event.block` and `event.transaction` carry is up to you - see [Selecting Block and Transaction Fields](#selecting-block-and-transaction-fields).
:::
### Selecting Block and Transaction Fields
Since **v3.7**, a registration names the block and transaction fields its handler reads with the `fields` option:
```typescript
indexer.onEvent(
{
contract: "MyContract",
event: "Transfer",
fields: { transaction: ["hash", "from"], block: ["timestamp"] },
},
async ({ event, context }) => {
event.transaction.hash; // string
event.block.timestamp; // number
event.transaction.gasUsed; // Type error - not listed in fields
},
);
```
Reading a field you didn't list is a type error, so the selection stays honest as handlers change. `event.block.number` is always available without listing it.
`fields` works on both `indexer.onEvent` and `indexer.contractRegister`, and two handlers on the same event can select different fields - the indexer only fetches and decodes what's actually asked for. It is EVM only: on Fuel, registering with `fields` throws. Fuel events always carry `block.id`, `block.height`, `block.time` and `transaction.id`, and there is no field selection.
Write the selection inline, as above. To share one across registrations, declare it `as const` so its element types still name the fields:
```typescript
const txFields = { transaction: ["hash", "from"] } as const;
indexer.onEvent(
{ contract: "MyContract", event: "Transfer", fields: txFields },
handler,
);
```
The `config.yaml` [`field_selection`](https://docs.envio.dev/docs/HyperIndex/configuration-file#field-selection) option still works and applies to every handler of an event (or of every event, at the root level). A handler's `fields` overrides it. Prefer `fields`: the list sits next to the code that reads it, and it doesn't make every other handler pay for the fetch.
See [`FieldSelection`](https://docs.envio.dev/docs/HyperIndex/config-schema-reference#def-fieldselection) in the Config Schema Reference for the full list of available transaction and block fields.
**Example event type definition:**
```typescript
type Event = {
params: Params;
chainId: 1 | 137;
srcAddress: `0x${string}`;
logIndex: number;
transaction: TransactionFields;
block: BlockFields;
};
```
To name an event's type in your own code, for example in a helper function, use `EvmEvent` from `envio`:
```typescript
import type { EvmEvent } from "envio";
type TransferEvent = EvmEvent<"ERC20", "Transfer">;
```
Every integer event parameter (`uint8` to `uint256`, `int8` to `int256`) arrives as a `bigint`, an `address` as an `Address` (`` `0x${string}` ``, checksummed by default), and `bytes`, `bytesN` and `string` as strings. Wrap a small integer in `Number()` before writing it to an `Int!` field.
---
## Context Object
The handler `context` provides methods to interact with entities stored in the database. It holds:
| Member | Type | Description |
| --- | --- | --- |
| `context.` | entity operations | `get`, `getOrThrow`, `getOrCreate`, `getWhere`, `set`, `deleteUnsafe` for each entity in `schema.graphql` |
| `context.chain.id` | chain id union | The chain the event came from |
| `context.chain.isRealtime` | `boolean` | `true` once **every** chain has caught up to its head (or reached its `end_block`) |
| `context.isPreload` | `boolean` | `true` during the [preload phase](https://docs.envio.dev/docs/HyperIndex/preload-optimization) |
| `context.log` | `Logger` | `debug`, `info`, `warn`, `error` |
| `context.effect` | function | Calls an [Effect](https://docs.envio.dev/docs/HyperIndex/effect-api) |
Use `context` only while the handler runs. Reading it after the handler's promise resolves, usually because of a missing `await`, throws `Impossible to access context. after the handler is resolved. Make sure you didn't miss an await in the handler.`
### Retrieving Entities
Retrieve entities from the database using `context.Entity.get` where `Entity` is the name of the entity you want to retrieve, which is defined in your [schema.graphql](https://docs.envio.dev/docs/HyperIndex/schema.md) file.
```typescript
await context.Entity.get(entityId);
```
It'll return `Entity` object or `undefined` if the entity doesn't exist.
Use `context.Entity.getOrThrow` to conveniently throw an error if the entity doesn't exist:
```typescript
const pool = await context.Pool.getOrThrow(poolId);
// Will throw: Entity 'Pool' with ID '...' is expected to exist.
// Or you can pass a custom message as a second argument:
const pool = await context.Pool.getOrThrow(
poolId,
`Pool with ID ${poolId} is expected.`
);
```
Or use `context.Entity.getOrCreate` to automatically create an entity with default values if it doesn't exist:
```typescript
const pool = await context.Pool.getOrCreate({
id: poolId,
totalValueLockedETH: 0n,
});
// Which is equivalent to:
let pool = await context.Pool.get(poolId);
if (!pool) {
pool = {
id: poolId,
totalValueLockedETH: 0n,
};
context.Pool.set(pool);
}
```
### Retrieving Entities by Field
```typescript
indexer.onEvent(
{ contract: "ERC20", event: "Approval" },
async ({ event, context }) => {
// Find all approvals for this specific owner
const currentOwnerApprovals = await context.Approval.getWhere({
owner_id: { _eq: event.params.owner },
});
// Process all the owner's approvals efficiently
for (const approval of currentOwnerApprovals) {
// Process each approval
}
},
);
```
Beyond `_eq`, you can filter by value using comparison operators like `_gt`, `_gte`, `_lt`, `_lte`, and `_in`.
To narrow results further, combine several conditions in a single call - they all have to match (`AND`):
```typescript
// Find accounts matching a specific id AND a balance within a range
const accounts = await context.Account.getWhere({
id: { _eq: event.params.account },
balance: { _gte: 1_000_000n, _lte: 10_000_000n },
});
```
:::note
Multi-field filtering with `getWhere` was added in HyperIndex v3.2.
:::
**Important:**
- Preload Optimization is always enabled in V3 and powers `getWhere`. See [How Preload Optimization Works](https://docs.envio.dev/docs/HyperIndex/preload-optimization).
- Works with any entity field except `@derivedFrom` fields, which throw `The field "" on entity "" is a derived field and cannot be used in getWhere()`. For a relationship, filter on its `_id` column, as `owner_id` above. Since v3.5, HyperIndex creates whatever database index the query needs, so you don't have to declare [`@index`](https://docs.envio.dev/docs/HyperIndex/database-performance-optimization#indices-created-on-demand) for it. The first query on an unindexed field waits while that index builds.
- You can't filter by `null` or `undefined`. Passing either as a value throws, and so does an empty filter (`{}`) or an empty operator (`{ field: {} }`).
- Potential Memory Issues: Very large `getWhere` queries might cause memory overflows.
- Tip: Try to put the `getWhere` query to the top of the handler, to make sure it's being preloaded. Read more about how [Preload Optimization](https://docs.envio.dev/docs/HyperIndex/preload-optimization) works.
### Modifying Entities
Use `context.Entity.set` to create or update an entity:
```typescript
context.Entity.set({
id: entityId,
...otherEntityFields,
});
```
:::note
Both `context.Entity.set` and `context.Entity.deleteUnsafe` methods use the In-Memory Storage under the hood and don't require `await` in front of them.
:::
### Referencing Linked Entities
When your schema defines a field that links to another entity type, set the relationship using `_id` with the referenced entity's `id`. You are storing the ID, not the full entity object.
```graphql
type A {
id: ID!
b: B!
}
type B {
id: ID!
}
```
```typescript
context.A.set({
id: aId,
b_id: bId, // ID of the linked B entity
});
```
HyperIndex automatically resolves `A.b` based on the stored `b_id` when querying the API.
### Deleting Entities (Unsafe)
To delete an entity:
```typescript
context.Entity.deleteUnsafe(entityId);
```
:::warning
The `deleteUnsafe` method is experimental and **unsafe**. You need to manually handle all entity references after deletion to maintain database consistency.
:::
### Updating Specific Entity Fields
Entities returned by `get` are read-only, so never mutate one. Spread it into a new object and set that:
```typescript
const pool = await context.Pool.get(poolId);
if (pool) {
context.Pool.set({
...pool,
totalValueLockedETH: pool.totalValueLockedETH + newDeposit,
});
}
```
### `context.log`
The context object also provides a logger that you can use to log messages to the console. Compared to `console.log` calls, these logs will be displayed on our [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service) runtime logs page.
Each of `debug`, `info`, `warn` and `error` takes a message and an optional object of fields or an `Error`:
```typescript
context.log.info(`Processing transfer`, { from: event.params.from });
context.log.error("Failed to load the pool", error as Error);
```
Logging is silent during the preload phase, so each message prints once per event.
Read more in the [Observability Guide](https://docs.envio.dev/docs/HyperIndex/observability).
### `context.isPreload`
If you need to skip the preload phase for CPU-intensive operations or to perform certain actions only once per event, you can use `context.isPreload`.
```typescript
indexer.onEvent(
{ contract: "ERC20", event: "Transfer" },
async ({ event, context }) => {
// Load existing data efficiently
const [sender, receiver] = await Promise.all([
context.Account.getOrThrow(event.params.from),
context.Account.getOrThrow(event.params.to),
]);
// Skip expensive operations during preload
if (context.isPreload) {
return;
}
// CPU-intensive calculations only happen once
const complexCalculation = performExpensiveOperation(event.params.value); // Placeholder function for demonstration
// Create or update sender account
context.Account.set({
id: event.params.from,
balance: sender.balance - event.params.value,
computedValue: complexCalculation,
});
// Create or update receiver account
context.Account.set({
id: event.params.to,
balance: receiver.balance + event.params.value,
});
},
);
```
**Note:** While `context.isPreload` can be useful for bypassing double execution, it's recommended to use the [Effect API](https://docs.envio.dev/docs/HyperIndex/effect-api) for external calls instead, as it provides automatic batching and memoization benefits.
## External Calls
Envio indexer runs using Node.js runtime. This means that you can use `fetch` or any other library like `viem` to perform external calls from your handlers.
Note that with [Preload Optimization](https://docs.envio.dev/docs/HyperIndex/preload-optimization) all handlers run twice. But with [Effect API](https://docs.envio.dev/docs/HyperIndex/effect-api) this behavior makes your external calls run in parallel, while keeping the processing data consistent.
Check out our [IPFS Integration](https://docs.envio.dev/docs/HyperIndex/ipfs), [Accessing Contract State](https://docs.envio.dev/docs/HyperIndex/contract-state) and [Effect API](https://docs.envio.dev/docs/HyperIndex/effect-api) guides for more information.
### `context.effect`
Define an effect and use it in your handler with `context.effect`:
```typescript
import { indexer, createEffect, S } from "envio";
// Define an effect that will be called from the handler.
const getMetadata = createEffect(
{
name: "getMetadata",
input: S.string,
output: {
description: S.string,
value: S.bigint,
},
rateLimit: {
calls: 5,
per: "second",
},
cache: true, // Optionally persist the results in the database
},
async ({ input }) => {
const response = await fetch(`https://api.example.com/metadata/${input}`);
const data = await response.json();
return {
description: data.description,
value: data.value,
};
}
);
indexer.onEvent(
{ contract: "ERC20", event: "Transfer" },
async ({ event, context }) => {
// Load metadata for the token.
// This will be executed in parallel for all events in the batch.
// The call is automatically memoized, so you don't need to worry about duplicate requests.
const sender = await context.effect(getMetadata, event.params.from);
// Process the transfer with the pre-loaded data
},
);
```
---
## Accessing `config.yaml` Data in Handlers
You can read your indexer configuration and live indexing state from the `indexer` value - either at the top level of a handler file or inside a handler. Use `indexer.chains[chainId]` (or one of the named entries on `indexer.chains`) to inspect a specific chain:
```typescript
import { indexer } from "envio";
indexer.onEvent(
{ contract: "Greeter", event: "NewGreeting" },
async ({ event, context }) => {
const chain = indexer.chains[event.chainId];
chain.id; // chain id
chain.startBlock; // configured start block
chain.endBlock; // configured end block (or undefined)
chain.isRealtime; // true once every chain has caught up to its head
chain.Greeter.name; // contract name
chain.Greeter.abi; // parsed ABI
chain.Greeter.addresses; // initial + dynamically registered addresses
},
);
```
Top-level fields like `indexer.name`, `indexer.description`, and `indexer.chainIds` are also available. After restart, addresses on `chain..addresses` include any contracts that were dynamically registered in previous runs, not just those declared in `config.yaml`.
---
## Performance Considerations
For performance optimization and best practices, refer to:
- [Benchmarking](https://docs.envio.dev/docs/HyperIndex/benchmarking)
- [Preload Optimization](https://docs.envio.dev/docs/HyperIndex/preload-optimization)
These guides offer detailed recommendations on optimizing entity loading and indexing performance.
---
---
# Block Handlers
> Learn how to run custom logic on every blockchain block or at set intervals using onBlock.
Run logic on every block or an interval.
---
`indexer.onBlock` lets you run logic on every block or an interval. This is useful for aggregations and time-series logic.
To get started, import the `indexer` value from `envio` and call `onBlock` in one of your handler files.
```typescript
import { indexer } from "envio";
indexer.onBlock(
{
name: "MyBlockHandler",
},
async ({ block, context }) => {
context.log.info(`Processing block ${block.number}`);
}
);
```
> Block handlers need no entry in `config.yaml`.
In the example above, the handler runs on **every** chain configured in `config.yaml` (the V3 default). To restrict it to a single chain, pass a `where` callback - see below.
## Options
`indexer.onBlock` accepts an options object as the first argument with the following properties:
- `name` (required) - The name of the block handler. It's used for logging, debugging and metrics.
- `where` (optional) - A callback `({ chain }) => false | true | { block: { number: { _gte?, _lte?, _every? } } }` that decides which chains the handler runs on and over which block range/interval. Omit it to run on every chain on every block.
The indexer calls `where` once per configured chain when the handler is registered, not once per block. `chain` carries `id`, `name`, `startBlock`, `endBlock`, `isRealtime` and each contract's `addresses`. The rules:
- Return `false` to skip the chain, `true` to run on every block, or a filter object. Any other value, including `undefined` from a missing `return`, throws.
- `_gte` and `_lte` are inclusive. `_gte` can't be below the chain's start block and `_lte` can't be above its `end_block`; either throws at registration.
- `_every` is a whole number of at least 1 and defaults to 1. It counts from `_gte`, or from the chain's start block when `_gte` is omitted, so a block runs when `(blockNumber - _gte) % _every === 0`.
- If `where` returns `false` for every chain, the indexer logs a warning that the handler matched 0 chains.
- On Fuel the filter key is `block.height` instead of `block.number`. On Solana use `indexer.onSlot`, whose filter is `{ slot: { _gte?, _lte?, _every? } }` and whose handler receives `{ slot, context }`.
To express the V2-era `chain`, `startBlock`, `endBlock`, and `interval` options, return them from `where`:
```typescript
import { indexer } from "envio";
indexer.onBlock(
{
name: "MyBlockHandler",
where: ({ chain }) => {
if (chain.id !== 1) return false;
return {
block: {
number: {
_gte: 19_000_000, // start block (inclusive)
_lte: 20_000_000, // end block (inclusive)
_every: 100, // run every Nth block
},
},
};
},
},
async ({ block, context }) => {
context.log.info(`Processing block ${block.number}`);
}
);
```
## Handler Function
:::note
Preload Optimization is always enabled in HyperIndex V3 and powers Block Handlers. Don't forget that it makes your handlers run twice.
:::
The second argument is a handler function that receives the block object and the handler context.
- `block` - The block object.
- `number` - The block number.
- More fields will be added in the future. Let us know in [Discord](https://discord.gg/envio) if you need any specific fields. You can also use [Effect API](https://docs.envio.dev/docs/HyperIndex/effect-api) to get the data from RPC.
- `context` - Exactly the same as the Event Handlers [Context Object](https://docs.envio.dev/docs/HyperIndex/event-handlers#context-object). Use `context.chain.id` to read the current chain ID inside the handler.
## Multichain
By default `indexer.onBlock` runs on every chain in your config. To run different parameters per chain, branch inside the `where` callback:
```typescript
import { indexer } from "envio";
const perChain = {
1: { startBlock: 19783636, interval: (60 * 60) / 12 }, // Every 60 minutes (12s block time)
10: { startBlock: 119534316, interval: (60 * 60) / 2 }, // Every 60 minutes (2s block time)
} as const;
indexer.onBlock(
{
name: "HourlyPrice",
where: ({ chain }) => {
const cfg = perChain[chain.id as keyof typeof perChain];
if (!cfg) return false;
return {
block: {
number: { _gte: cfg.startBlock, _every: cfg.interval },
},
};
},
},
async ({ block, context }) => {
context.log.info(`Processing block ${block.number} on chain ${context.chain.id}`);
}
);
```
## Time Interval
The `_every` option is a number of blocks. But quite often you want to run some logic on a time interval. To convert time interval to blocks, you can use the following formula:
```typescript
// Every 60 minutes
const timeIntervalInSeconds = 60 * 60;
// 12 seconds per block
const secondsPerBlock = 12;
// 300 blocks per 60 minutes
const blockInterval = timeIntervalInSeconds / secondsPerBlock;
```
## Different Historical and Realtime Intervals
Here's the recipe to speed up your historical sync by increasing the interval for historical blocks.
You can achieve this by registering multiple block handlers with the same handler, but different `_gte`, `_lte`, and `_every` values.
```typescript
import { indexer } from "envio";
const realtimeBlocks = {
1: 19783636,
10: 119534316,
} as const;
indexer.onBlock(
{
name: "HistoricalBlockHandler",
where: ({ chain }) => {
const realtime = realtimeBlocks[chain.id as keyof typeof realtimeBlocks];
if (!realtime) return false;
return { block: { number: { _lte: realtime - 1, _every: 1000 } } };
},
},
async ({ block, context }) => {
context.log.info(`Processing block ${block.number}`);
}
);
indexer.onBlock(
{
name: "RealtimeBlockHandler",
where: ({ chain }) => {
const realtime = realtimeBlocks[chain.id as keyof typeof realtimeBlocks];
if (!realtime) return false;
return { block: { number: { _gte: realtime } } };
},
},
async ({ block, context }) => {
context.log.info(`Processing block ${block.number}`);
}
);
```
In this case we'll run the historical handler on every 1000 blocks and from the realtime block we'll start running the second handler on every block.
> We recommend exploring the approach together with [HyperSync](https://docs.envio.dev/docs/HyperSync/overview) client to effectively query data for big block ranges.
## Preset Handler
This is not an official feature, but a creative way to use block handlers. You can define a block handler that runs on a single block at the start of the chain and use it to populate the database with the initial data.
Use the chain's own `startBlock` for the range. A `_gte` below it throws at registration.
```typescript
import { indexer } from "envio";
indexer.onBlock(
{
name: "Preset",
where: ({ chain }) => {
if (chain.id !== 1) return false;
return {
block: { number: { _gte: chain.startBlock, _lte: chain.startBlock } },
};
},
},
async ({ block, context }) => {
// You don't need preload optimization here,
// so don't forget to disable it to prevent double-run.
if (context.isPreload) return;
const response = await fetch("https://api.example.com/users");
const users: { id: string; address: string; name: string }[] =
await response.json();
users.forEach((user) => {
context.User.set({
id: user.id,
address: user.address,
name: user.name,
});
});
}
);
```
## Current Limitations
- Only block number is provided in the block object. We'll definitely add more fields in the future.
---
# Understanding Multichain Indexing
> Learn how to index and process events across multiple chains with HyperIndex.
For a conceptual overview of what multichain indexing is and when to use it, see [What is multichain indexing?](https://docs.envio.dev/blog/what-is-multi-chain-indexing). This page covers the HyperIndex configuration and patterns.
Multichain indexing allows you to monitor and process events from contracts deployed across multiple chains within a single indexer instance. This capability is essential for applications that:
- Track the same contract deployed across multiple chains
- Need to aggregate data from different chains into a unified view
- Monitor cross-chain interactions or state
## How It Works
With multichain indexing, events from contracts deployed on multiple chains can be used to create and update entities defined in your schema file. Your indexer will process events from all configured chains, maintaining proper synchronization across them.
## Configuration Requirements
To implement multichain indexing, you need to:
1. Populate the `chains` section in your `config.yaml` file for each chain
2. Specify contracts to index from each chain
3. Create event handlers for the specified contracts
## Real-World Example: Uniswap V4 Multichain Indexer
For a comprehensive, production-ready example of multichain indexing, we recommend exploring our [Uniswap V4 Multichain Indexer](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer). This official reference implementation:
- Indexes Uniswap V4 deployments across 10 different blockchain chains
- Powers the official [v4.xyz](https://v4.xyz) interface with real-time data
- Demonstrates best practices for high-performance multichain indexing
- Provides a complete, production-grade implementation you can study and adapt
The Uniswap V4 indexer showcases how to effectively structure a multichain indexer for a complex DeFi protocol, handling high volumes of data across multiple chains while maintaining performance and reliability.
## Config File Structure for Multichain Indexing
The `config.yaml` file for multichain indexing contains three key sections:
1. **Global contract definitions** - Define contracts, ABIs, and events once
2. **Chain-specific configurations** - Specify chain IDs and starting blocks
3. **Contract instances** - Reference global contracts with chain-specific addresses
```yaml
# Example structure (simplified)
contracts:
- name: ExampleContract
abi_file_path: ./abis/example-abi.json
events:
- event: ExampleEvent
chains:
- id: 1 # Ethereum Mainnet
start_block: 0
contracts:
- name: ExampleContract
address: "0x1234..."
- id: 137 # Polygon
start_block: 0
contracts:
- name: ExampleContract
address: "0x5678..."
```
### Key Configuration Concepts
- The global `contracts` section defines the contract interface, ABI, handlers, and events once
- The `chains` section lists each blockchain chain you want to index
- Each chain entry references the global contract and provides the chain-specific address
- This structure allows you to reuse the same handler functions and event definitions across chains
## Per-Chain Data Mode
By default every entity row and effect cache is shared by all chains, so the same entity id on two chains resolves to a single row. That's why multichain indexers traditionally namespace ids with the chain id (`user-1`, `user-137`).
Since **v3.6** you can instead make entities per-chain, which is the recommended setup for a multichain indexer:
```yaml
name: my-indexer
disable_default_cross_chain: true
```
With it on:
- Entity tables get a composite `(id, chainId)` primary key. The same id on two chains is two independent rows - in memory, in Postgres and in ClickHouse - and entity history and reorg rollback are scoped per chain too.
- Effects that don't state a `crossChain` option get one cache per chain. See [Per-Chain Effects](https://docs.envio.dev/docs/HyperIndex/effect-api#per-chain-effects).
- Handler code is unchanged. A handler always runs on one chain, so `context.Token.get(id)` reads that chain's row and you can drop the id prefixing.
Sharing becomes explicit. Mark an entity `@crossChain` when its rows should stay shared by every chain:
```graphql
type Counter {
# per-chain: one row per (id, chain)
id: ID!
count: BigInt!
}
type GlobalCounter @crossChain {
# one row shared by every chain
id: ID!
count: BigInt!
}
```
`@crossChain` is only valid together with `disable_default_cross_chain: true` - without the flag entities are already cross-chain and codegen rejects the directive.
Per-chain entities reserve the `chainId` column (`chain_id` under [`column_name_format: snake_case`](https://docs.envio.dev/docs/HyperIndex/configuration-file#column-name-format)), so a field on a per-chain entity can't be named `chainId` or `chain_id`.
Outside a handler there is no chain in context, so the [test framework's](https://docs.envio.dev/docs/HyperIndex/testing) chain-agnostic operations take one explicitly:
```typescript
indexer.Counter.set({ id: "1", count: 0n, chainId: 1 });
// Throws if the id exists on more than one chain
indexer.Counter.get("1");
// Narrow it instead
indexer.Counter.getWhere({ chainId: { _eq: 1 } });
```
Since **v3.10**, rollbacks are isolated too: when `disable_default_cross_chain: true` is set and no entity is marked `@crossChain`, a reorg rolls back only the chain that triggered it instead of every chain.
## Multichain Event Ordering
In V3 the indexer always processes multichain events in **unordered** mode. Events from different chains are processed as soon as they're available, without waiting for the other chains, which keeps latency low.
- Events are still processed in order within each individual chain.
- Events across different chains may be processed out of order.
- Processing happens as soon as events are emitted, so you don't wait for the slowest chain's block time.
This is ideal when:
- Operations on your entities are [commutative](https://docs.envio.dev/docs/HyperIndex/terminology.md#commutative-property) (order doesn't matter).
- Entities from different chains never interact with each other.
- Processing speed matters more than guaranteed cross-chain ordering.
The V2 `unordered_multichain_mode` option, the `multichain: ordered` opt-in, and the `UNORDERED_MULTICHAIN_MODE` / `UNSTABLE__TEMP_UNORDERED_HEAD_MODE` environment variables have all been removed in V3 - there is nothing to configure.
## Ordered Multichain Mode
HyperIndex V3 doesn't offer an ordered multichain mode, and it's a deliberate choice rather than a feature gap. Ordered mode worked by pausing every chain until events from the slowest chain had caught up, so the moment one chain hiccuped (RPC rate limits, a slow block, a brief reorg) every other chain stalled with it. In practice that meant a multichain indexer was only ever as reliable and as fast as its worst-performing chain, and even healthy chains paid for that coupling with significantly higher latency at the head.
You almost always get better reliability and lower latency by keeping every chain unordered and modeling the cross-chain relationship in your schema instead. Each chain writes a small temporary entity when its side of a cross-chain interaction happens, and the second chain (whichever arrives last) reads those temporary entities and finalizes the unified entity. Because each chain progresses independently, none of them are blocked on each other.
A typical pattern for an `A → B` cross-chain message:
```graphql
type CrossChainMessage {
id: ID! # The shared cross-chain message id (e.g. nonce + originChainId)
sourceChainId: Int
sourceTxHash: String
destinationChainId: Int
destinationTxHash: String
status: String! # "sent" | "delivered"
}
```
```typescript
import { indexer } from "envio";
// Chain A: the message was emitted. Create or update the entity with the
// "sent" side of the data. The destination handler may run before or after.
indexer.onEvent(
{ contract: "Bridge", event: "MessageSent" },
async ({ event, context }) => {
const id = `${event.params.originChainId}-${event.params.nonce}`;
const existing = await context.CrossChainMessage.get(id);
context.CrossChainMessage.set({
id,
sourceChainId: event.chainId,
sourceTxHash: event.transaction.hash,
destinationChainId: existing?.destinationChainId,
destinationTxHash: existing?.destinationTxHash,
status: existing?.destinationTxHash ? "delivered" : "sent",
});
},
);
// Chain B: the message was delivered. Read the (maybe-already-existing)
// entity and fill in the destination side, regardless of which side arrived
// first.
indexer.onEvent(
{ contract: "Bridge", event: "MessageDelivered" },
async ({ event, context }) => {
const id = `${event.params.originChainId}-${event.params.nonce}`;
const existing = await context.CrossChainMessage.get(id);
context.CrossChainMessage.set({
id,
sourceChainId: existing?.sourceChainId,
sourceTxHash: existing?.sourceTxHash,
destinationChainId: event.chainId,
destinationTxHash: event.transaction.hash,
status: existing?.sourceTxHash ? "delivered" : "sent",
});
},
);
```
The same shape works for any "rendezvous" where two chains contribute parts of one logical record (bridges, cross-chain governance, multichain user profiles, etc.). The "temporary" entity is just a regular entity that gets progressively completed as each chain's events arrive - there's no special API to learn, and the indexer stays fast and resilient because no chain ever waits on another.
If you have a use case that genuinely cannot be expressed this way, reach out on [Discord](https://discord.gg/envio) - we'd like to hear it.
## Best Practices for Multichain Indexing
### 1. Keep Chains' Data Distinct
Set [`disable_default_cross_chain: true`](#per-chain-data-mode) so entities are per-chain, and mark the few entities that should be shared with `@crossChain`. Prefer that over prefixing entity IDs with `${event.chainId}-`: the prefix has to be repeated at every read and write, it leaks the chain into ids your API consumers see, and one handler that forgets it silently merges two chains' data. Per-chain mode keeps the ids clean and makes the separation the database's job.
### 2. Error Handling
Implement robust error handling for chain-specific issues. A failure on one chain shouldn't prevent indexing from continuing on other chains.
### 3. Testing
- Test your indexer with realistic scenarios across all chains
- Use testnet deployments for initial validation
- Verify entity updates work correctly across chains
### 4. Performance Considerations
- Consider your indexing frequency based on the block times of each chain.
- Monitor resource usage, as indexing multiple chains increases load.
- Adding more chains does **not** linearly degrade performance - chains are indexed in parallel.
### 5. Adding a New Chain to an Existing Indexer
To add a new chain to a running indexer:
1. Add the new chain entry to your `config.yaml` with the appropriate `start_block` and contract addresses
2. Push the updated code to your deployment branch (for Envio Cloud) or restart locally with `pnpm envio dev -r`
On **Envio Cloud**, this creates a new deployment that re-indexes all chains (including the new one). Your previous deployment continues serving queries with zero downtime until the new deployment is fully synced. See the [deployment guide](https://docs.envio.dev/docs/HyperIndex/hosted-service-deployment.md#updating-your-deployment) for details.
**Locally**, adding a new chain requires a restart and will re-index all chains from their respective start blocks. Note that in V3, `envio dev` no longer auto-resets the database - pass `-r` (or `--restart`) explicitly when you want a fresh sync. `envio start` is now production-only.
## Troubleshooting Common Issues
1. **Entity Conflicts**: If you see one chain's updates overwriting another's, either turn on [per-chain data mode](#per-chain-data-mode) or verify that your entity IDs are properly namespaced with chain IDs.
2. **Memory Usage**: If your indexer uses excessive memory, consider optimizing your entity structure and implementing pagination in your queries.
## Next Steps
- Explore our [Uniswap V4 Multichain Indexer](https://docs.envio.dev/docs/HyperIndex/example-uniswap-v4-multi-chain-indexer) for a complete implementation
- Review [performance optimization techniques](https://docs.envio.dev/docs/HyperIndex/performance) for your indexer
---
# Running The Indexer Locally
> Learn how to start, run, and manage the Envio indexer locally with Docker and Hasura.
## Starting the Indexer
Remember to `cd` into your project directory if you have defined one during `pnpx envio init`.
Before running the Envio CLI command to start the indexer locally, make sure you have Node.js 22.15.0 or newer and [Docker](https://www.docker.com/products/docker-desktop/) (or [Podman](https://podman.io/)) running.
Run the indexer
```bash
pnpm dev
```
`pnpm dev` runs `envio dev`, which runs codegen, starts Postgres and Hasura in Docker and then starts indexing. The terminal UI shows the local GraphQL (Hasura) URL, `http://localhost:8080`, and a link to the [Dev Console](https://docs.envio.dev/docs/HyperIndex/observability#dev-console). Open the Hasura console in your browser to view the indexed data.
Admin-secret / password for local Hasura is `testing`.
### Local services and ports
`envio dev` starts these containers. All Envio projects on the machine share them.
| Container | Image | Host port |
| --- | --- | --- |
| `envio-postgres` | `postgres:18.3` | `5433` (`ENVIO_PG_PORT`) |
| `envio-hasura` | `hasura/graphql-engine:v2.43.0` | `8080` (`HASURA_EXTERNAL_PORT`) |
| `envio-clickhouse` (only with `storage.clickhouse`) | `clickhouse/clickhouse-server:26.2.15.4` | `8123` |
The indexer itself serves metrics and health checks on `9898` (`ENVIO_INDEXER_PORT`). To use a Postgres or ClickHouse you run yourself, set `ENVIO_PG_HOST` or `ENVIO_CLICKHOUSE_HOST` and `envio dev` won't start that container. See [Environment Variables](https://docs.envio.dev/docs/HyperIndex/environment-variables.md) for the full list.
## Restarting and Code Changes
`envio dev` does not watch your files. After changing code, stop the indexer (`Ctrl+C`) and run `pnpm dev` again.
A restart resumes from where the indexer left off. What happens to your changes depends on what changed:
- **Handler code**: the new logic applies from the resume point on. Events indexed before the restart keep the results of the old logic. Run `pnpm envio dev -r` to re-index everything with the new logic.
- **`config.yaml`, `schema.graphql` or ABIs**: codegen runs again on start. If the change is incompatible with the data already indexed, such as a new entity field, a changed `start_block` or an added chain, the indexer stops with `The following config changes are incompatible with the existing indexer data:`, lists the changes and offers the fix. Run `pnpm envio dev -r` to delete the indexed data and start over.
- **The `envio` version**: the data records the version that indexed it, so upgrading `envio` also needs `pnpm envio dev -r`.
:::tip
If the indexer seems not to pick up your handler changes, check the terminal output for compilation errors from your handler files.
:::
## Avoiding Full Re-indexing During Development
Re-indexing from the start block can be slow for large datasets. Here are strategies to iterate faster:
### Use the testing framework
The fastest way to validate handler logic is to skip syncing entirely. Envio's built-in [testing framework](https://docs.envio.dev/docs/HyperIndex/testing.md) lets you mock events, simulate database state, and assert handler behavior - all without connecting to a blockchain or waiting for blocks to sync.
```bash
pnpm test
```
This is ideal for iterating on handler logic, catching bugs early, and running tests in CI. See the [Testing guide](https://docs.envio.dev/docs/HyperIndex/testing.md) for setup and examples.
### Use a recent start block
During development, temporarily set `start_block` in your `config.yaml` to a recent block number. This lets you test handler logic against fresh data without waiting for a full historical sync:
```yaml
chains:
- id: 1 # Ethereum mainnet
start_block: 19000000 # Recent block for faster dev iteration
```
Remember to set it back to the correct start block before deploying to production.
### Force a clean re-index
If you need to re-index from scratch (e.g., after schema changes or to clear corrupted state):
```bash
pnpm envio dev -r # Deletes indexed data and re-indexes from start_block
```
## Stopping the Indexer
To stop and remove the local Postgres, Hasura and ClickHouse containers and delete their data volumes, run:
```bash
pnpm envio stop
```
The Docker images stay cached, so the next `pnpm dev` starts quickly. Because the containers are shared, this also deletes the local data of any other Envio project on the machine.
## What next?
Once you have successfully run the indexer locally, you can deploy the indexer onto Envio's [Envio Cloud](https://docs.envio.dev/docs/HyperIndex/hosted-service.md).
---
# Environment Variables
> Learn how to configure and manage Envio environment variables for your blockchain indexer.
Environment variables are a crucial part of configuring your Envio blockchain indexer. They allow you to manage sensitive information and configuration settings without hardcoding them in your codebase.
## Naming Convention
HyperIndex reads the variables listed below. Most start with `ENVIO_`; the logging and Hasura ones keep their own names.
Your own variables (RPC URLs, API keys) can use any name locally, both in [`config.yaml`](https://docs.envio.dev/docs/HyperIndex/configuration-file.md#environment-variables) and in handler code. Envio Cloud only accepts variables prefixed with `ENVIO_`, so use the prefix for anything you deploy.
## Envio API Token (required for HyperSync)
To ensure continued access to HyperSync, set an Envio API token in your environment.
- Use `ENVIO_API_TOKEN` to provide your token at runtime
- See the API Tokens guide for how to generate a token: [API Tokens](https://docs.envio.dev/docs/HyperSync/api-tokens)
- A token is only required when using Envio as the data provider (HyperSync). Indexers that source data from an external RPC don't need one.
## Envio-specific environment variables
The following variables are used by HyperIndex. Defaults marked "dev" apply only while `NODE_ENV` is not `production` (see [Production mode](#production-mode)).
### General
| Variable | Default | Description |
| --- | --- | --- |
| `ENVIO_API_TOKEN` | - | API token for HyperSync (required when any chain uses HyperSync - get one at [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens)). `envio init` also reads it in place of `--api-token`. |
| `ENVIO_CONFIG` | `config.yaml` | Config file path, relative to the project directory. Same as the CLI's `--config` flag. |
| `ENVIO_INDEXER_PORT` | `9898` | Port of the indexer's HTTP server, which serves `/metrics`, `/metrics/runtime` and `/healthz` - see [Observability](https://docs.envio.dev/docs/HyperIndex/observability) |
| `ENVIO_TUI` | auto | `false` disables the terminal UI, `true` forces it on (replaces the V2 `TUI_OFF=true` flag). Without it, the TUI is off when stdout is not a terminal, in CI (`CI` set), under Claude Code (`CLAUDECODE` set) or with `TERM=dumb`. |
| `ENVIO_HASURA` | `true` | `false` skips Hasura: `envio dev` doesn't start the container and the indexer doesn't track tables |
### Postgres
| Variable | Default | Description |
| --- | --- | --- |
| `ENVIO_PG_HOST` | `localhost` (dev) | Postgres host. Setting it at all tells `envio dev` you run Postgres yourself, so it doesn't start a container. |
| `ENVIO_PG_PORT` | `5433` (dev) | Postgres port. For `envio dev` it is the host port of the container, which itself always listens on `5432`. |
| `ENVIO_PG_USER` | `postgres` (dev) | Postgres username |
| `ENVIO_PG_PASSWORD` | `testing` | Postgres password |
| `ENVIO_PG_DATABASE` | `envio-dev` (dev) | Postgres database name |
| `ENVIO_PG_SCHEMA` | `public` | Postgres schema the indexer writes to (replaces `ENVIO_PG_PUBLIC_SCHEMA`; the old name is still accepted until v4). Give each indexer sharing a database its own schema. |
| `ENVIO_PG_SSL_MODE` | `false` (dev) | `true`, `false`, `require`, `allow`, `prefer` or `verify-full` |
| `ENVIO_PG_MAX_CONNECTIONS` | `2` | Postgres connection budget for the whole run. With `4` or more, an indexer whose entities are all [per-chain](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode) (no `@crossChain` entity) splits its chains across up to 4 worker processes, with at least 2 connections each. |
### Hasura
| Variable | Default | Description |
| --- | --- | --- |
| `HASURA_GRAPHQL_ENDPOINT` | `http://localhost:8080/v1/metadata` (dev) | Hasura metadata endpoint the indexer uses to track tables |
| `HASURA_GRAPHQL_ADMIN_SECRET` | `testing` (dev) | Hasura admin secret. `envio dev` also sets it on the container it starts. |
| `HASURA_GRAPHQL_ROLE` | `admin` (dev) | Role used for metadata calls |
| `HASURA_EXTERNAL_PORT` | `8080` | Host port of the Hasura container started by `envio dev` |
| `ENVIO_HASURA_RESPONSE_LIMIT` | none | Maximum rows the public role can read per query (old name `HASURA_RESPONSE_LIMIT` still works) |
| `ENVIO_HASURA_PUBLIC_AGGREGATE` | `[]` | JSON array of entity names whose aggregate queries are open to the public role, e.g. `["Transfer","Account"]` |
### ClickHouse
When the indexer also writes to ClickHouse (`storage.clickhouse` in `config.yaml`), `envio start` reads the connection from `ENVIO_CLICKHOUSE_HOST` (a URL such as `http://localhost:8123`), `ENVIO_CLICKHOUSE_DATABASE`, `ENVIO_CLICKHOUSE_USERNAME` and `ENVIO_CLICKHOUSE_PASSWORD`, plus the optional `ENVIO_CLICKHOUSE_REPLICATED` (only `true` is accepted) and `ENVIO_CLICKHOUSE_DATABASE_ENGINE` for high-availability setups. `envio dev` spins up its own container and injects these for you, using the `default` user with no password and the `default` database. Setting `ENVIO_CLICKHOUSE_HOST` makes `envio dev` use your server instead.
### Logging
`LOG_LEVEL`, `FILE_LOG_LEVEL`, `LOG_STRATEGY` and `LOG_FILE` control logging. See [Logs](https://docs.envio.dev/docs/HyperIndex/observability#logs) for their values.
### Tuning
These rarely need changing. The defaults are for v3.14 and can change between releases.
| Variable | Default | Description |
| --- | --- | --- |
| `ENVIO_HYPERSYNC_CLIENT_TIMEOUT_MILLIS` | `120000` | HyperSync request timeout |
| `ENVIO_HYPERSYNC_CLIENT_ENABLE_QUERY_CACHING` | `true` | HyperSync client query caching |
| `ENVIO_HYPERSYNC_CLIENT_SERIALIZATION_FORMAT` | `CapnProto` | `CapnProto` or `Json` |
| `ENVIO_HYPERSYNC_LOG_LEVEL` | `info` | HyperSync client log level: `trace`, `debug`, `info`, `warn` or `error` |
| `ENVIO_RPC_INITIAL_BLOCK_INTERVAL`, `ENVIO_RPC_BACKOFF_MULTIPLICATIVE`, `ENVIO_RPC_ACCELERATION_ADDITIVE`, `ENVIO_RPC_INTERVAL_CEILING` | - | Override the matching [RPC option](https://docs.envio.dev/docs/HyperIndex/rpc-sync#configuration-parameters-explained) for every RPC, taking precedence over `config.yaml` |
| `ENVIO_INDEXING_MAX_BUFFER_SIZE` | `100000` | Target number of fetched items buffered across all chains |
| `ENVIO_IN_MEMORY_OBJECTS_TARGET` | `100000` | In-memory changes the indexer holds before processing waits for writes to catch up |
| `MAX_PARTITION_SIZE` | `5000` | Addresses per query partition for a contract |
| `ENVIO_CLIENT_FILTER_ADDRESS_THRESHOLD` | `250000` | Registered addresses after which a contract's events are filtered by address in the indexer instead of in the query |
| `ENVIO_THROTTLE_CHAIN_METADATA_INTERVAL_MILLIS` | `500` (dev) | How often chain metadata (`_meta`) is written |
| `ENVIO_THROTTLE_PRUNE_STALE_DATA_INTERVAL_MILLIS` | `30000` (dev) | How often entity history outside the reorg window is pruned |
### Production mode
When `NODE_ENV=production`, the "dev" defaults above are switched off and the indexer refuses to start until they are set, printing `Missing environment variables:` with the list. Set `ENVIO_PG_HOST`, `ENVIO_PG_PORT`, `ENVIO_PG_USER`, `ENVIO_PG_DATABASE`, `ENVIO_PG_SSL_MODE`, `HASURA_GRAPHQL_ENDPOINT`, `HASURA_GRAPHQL_ROLE`, `HASURA_GRAPHQL_ADMIN_SECRET`, `ENVIO_THROTTLE_CHAIN_METADATA_INTERVAL_MILLIS` and `ENVIO_THROTTLE_PRUNE_STALE_DATA_INTERVAL_MILLIS`. The three Hasura variables are needed even with `ENVIO_HASURA=false`; a missing `HASURA_GRAPHQL_ENDPOINT` fails with `TypeError: Cannot read properties of undefined (reading 'slice')`. Without `NODE_ENV=production`, the defaults apply.
:::note
The V2 variables `MAX_BATCH_SIZE`, `ENVIO_INDEXING_BLOCK_LAG`, `UNORDERED_MULTICHAIN_MODE`, and `UNSTABLE__TEMP_UNORDERED_HEAD_MODE` have been removed in V3. Use the `full_batch_size` config option in `config.yaml` instead of `MAX_BATCH_SIZE`, and use the per-chain `block_lag` option instead of `ENVIO_INDEXING_BLOCK_LAG`. Unordered multichain processing is now the default.
:::
## Example Environment Variables
Here are some commonly used environment variables:
```bash
# Envio API Token (required for HyperSync access)
ENVIO_API_TOKEN=your-secret-token
# Blockchain RPC URL
ENVIO_RPC_URL=https://arbitrum.direct.dev/your-api-key
# Coingecko API key
ENVIO_COINGECKO_API_KEY=api-key
# Disable the terminal UI
ENVIO_TUI=false
```
## Setting Environment Variables
### Local Development
For local development, you can set environment variables in several ways:
1. Using a `.env` file in your project root:
```bash
# .env
ENVIO_API_TOKEN=your-secret-token
ENVIO_RPC_URL=https://arbitrum.direct.dev/your-api-key
```
2. Directly in your terminal:
```bash
export ENVIO_API_TOKEN=your-secret-token
export ENVIO_RPC_URL=https://arbitrum.direct.dev/your-api-key
```
### Envio Cloud
When using Envio Cloud, you can configure environment variables through the Envio platform's dashboard. Variables you set there must be prefixed with `ENVIO_`.
For more information about environment variables in Envio Cloud, see the [Envio Cloud documentation](https://docs.envio.dev/docs/HyperIndex/hosted-service.md).
## Configuration File
For use of environment variables in your configuration file, read the docs here: [Configuration File](https://docs.envio.dev/docs/HyperIndex/configuration-file.md).
## Best Practices
1. **Never commit sensitive values**: Always use environment variables for sensitive information like API keys and database credentials
1. **Never commit or use private keys**: Never commit or use private keys in your codebase
1. **Use descriptive names**: Make your environment variable names clear and descriptive
1. **Document your variables**: Keep a list of required environment variables in your project's README
1. **Use different values**: Use different environment variables for development, staging, and production environments
1. **Validate required variables**: Check that all required environment variables are set before starting your blockchain indexer
## Troubleshooting
If you encounter issues with environment variables:
1. Verify that all required variables are set. A variable used in `config.yaml` but not set fails codegen with `Failed to interpolate variables into your config file. Environment variables are not present: `.
2. On Envio Cloud, check that your own variables are prefixed with `ENVIO_`
3. Ensure there are no typos in variable names
4. Confirm that the values are correctly formatted. An invalid value stops the indexer with `Invalid environment variables:` and the reason.
For more help, see our [Observability Guide](https://docs.envio.dev/docs/HyperIndex/observability.md).
---
# Envio Command Line Interface
> Explore and manage indexer projects with Envio CLI, from setup to development and monitoring.
This comprehensive reference guide covers all available commands and options in the Envio CLI tool for HyperIndex **V3**. Use this documentation to explore the full capabilities of the `envio` command and its subcommands for managing your blockchain indexing projects.
:::tip Envio Cloud CLI
Looking to manage your hosted indexers from the command line? See the **[Envio Cloud CLI](https://docs.envio.dev/docs/HyperIndex/envio-cloud-cli)** for deployment, monitoring, and management commands for Envio Cloud.
:::
## Getting Started
The Envio CLI provides a powerful set of tools for creating, developing, and managing your blockchain indexers. Whether you're starting a new project, running a development server, or deploying to production, the CLI offers commands to simplify and automate your workflow.
The fastest way to get going is `pnpx envio init`, which scaffolds a project interactively. From there, `envio dev` runs your indexer locally while you iterate, and `envio start` runs it in production.
Both `envio dev` and `envio start` run codegen first and resume from the last checkpoint. Add `-r` to delete the indexed data and start over, which you need after a change that is incompatible with the data already indexed, including an `envio` upgrade. `envio stop` removes the local Postgres, Hasura and ClickHouse containers and their data volumes.
### Non-interactive `envio init`
`envio init` runs in agent mode when stdout is not a terminal, when `CI` or `CLAUDECODE` is set, or when `TERM=dumb`. `ENVIO_TUI=false` forces agent mode and `ENVIO_TUI=true` forces the prompts. Run in agent mode with no subcommand, it prints a plan to stderr and exits with code `2` instead of prompting. Pass every value as a flag instead:
```bash
pnpx envio init contract-import explorer \
-n my-indexer \
-c 0x1f9840a85d5aF5bf1D1762F925BDADdC4201F984 \
-b ethereum-mainnet \
--single-contract \
--all-events \
-d my-indexer
```
- `-d` is required, and so are `--single-contract --all-events` with `contract-import`.
- A HyperSync indexer needs a token: pass `--api-token` or set `ENVIO_API_TOKEN`. `--api-token ""` writes an empty `ENVIO_API_TOKEN` to `.env` for you to fill in later.
- `contract-import explorer -b` takes a network name from the list below, such as `ethereum-mainnet`, not a chain ID. `contract-import local -b` takes a name or a chain ID: `contract-import local -a ./abi.json --contract-name MyContract -b -c `, adding `-r -s ` when HyperSync doesn't support the chain.
- To start from a template: `pnpx envio init template -t erc20 -n my-indexer -d my-indexer`.
Without `-d`, or without a token for a HyperSync indexer, `envio init` exits and names the flag to pass. Without `-n`, the name is the directory name, and `envio init template` without `-t` uses `greeter`. Other missing values, such as a `contract-import` flag, fail with `The input device is not a TTY`. See [Quickstart with AI](https://docs.envio.dev/docs/HyperIndex/quickstart-with-ai) for the full agent workflow.
**Command Overview:**
* [`envio`↴](#envio)
* [`envio init`↴](#envio-init)
* [`envio init contract-import`↴](#envio-init-contract-import)
* [`envio init contract-import explorer`↴](#envio-init-contract-import-explorer)
* [`envio init contract-import local`↴](#envio-init-contract-import-local)
* [`envio init template`↴](#envio-init-template)
* [`envio init svm`↴](#envio-init-svm)
* [`envio init svm template`↴](#envio-init-svm-template)
* [`envio init fuel`↴](#envio-init-fuel)
* [`envio init fuel contract-import`↴](#envio-init-fuel-contract-import)
* [`envio init fuel contract-import local`↴](#envio-init-fuel-contract-import-local)
* [`envio init fuel template`↴](#envio-init-fuel-template)
* [`envio dev`↴](#envio-dev)
* [`envio stop`↴](#envio-stop)
* [`envio codegen`↴](#envio-codegen)
* [`envio local`↴](#envio-local)
* [`envio local docker`↴](#envio-local-docker)
* [`envio local docker up`↴](#envio-local-docker-up)
* [`envio local docker down`↴](#envio-local-docker-down)
* [`envio local db-migrate`↴](#envio-local-db-migrate)
* [`envio local db-migrate up`↴](#envio-local-db-migrate-up)
* [`envio local db-migrate down`↴](#envio-local-db-migrate-down)
* [`envio local db-migrate setup`↴](#envio-local-db-migrate-setup)
* [`envio start`↴](#envio-start)
* [`envio metrics`↴](#envio-metrics)
* [`envio metrics runtime`↴](#envio-metrics-runtime)
* [`envio skills`↴](#envio-skills)
* [`envio skills update`↴](#envio-skills-update)
* [`envio tools`↴](#envio-tools)
* [`envio tools search-docs`↴](#envio-tools-search-docs)
* [`envio tools fetch-docs`↴](#envio-tools-fetch-docs)
* [`envio config`↴](#envio-config)
* [`envio config view`↴](#envio-config-view)
## `envio`
**Usage:** `envio [OPTIONS] `
###### **Subcommands:**
* `init` - Create a new indexer
* `dev` - Development commands for starting, stopping, and restarting the indexer. Runs codegen automatically before launching
* `stop` - Stop the local environment - delete the database and stop all processes (including Docker) for the current directory
* `codegen` - Generate indexing code from user-defined configuration & schema files
* `local` - Prepare local environment for envio testing
* `start` - Start the indexer. Runs codegen automatically before launching so the on-disk types stay in sync with `config.yaml` and `schema.graphql`
* `metrics` - Fetch raw Prometheus metrics from the running indexer's /metrics endpoint
* `skills` - Manage Envio-provided Claude Code skills under `.claude/skills/`
* `tools` - Tools for people and AI agents (search-docs, fetch-docs). Run `envio tools help` for details
* `config` - Inspect the indexer config
###### **Options:**
* `-d`, `--directory ` - The directory of the project. Defaults to current dir ("./")
* `--config ` - The config file path, resolved relative to the project directory. It can also be set via the `ENVIO_CONFIG` environment variable
Default value: `config.yaml`
## `envio init`
Create a new indexer
Quick start - run with no arguments:
pnpx envio init
Guided step-by-step for humans and AI agents. Reach for the subcommands below only when you already know exactly what you want.
**Usage:** `envio init [OPTIONS] [COMMAND]`
###### **Subcommands:**
* `contract-import` - [Advanced] Initialize Evm indexer by importing config from a contract for a given chain
* `template` - [Advanced] Initialize Evm indexer from an example template
* `svm` - Initialization option for creating Svm indexer
* `fuel` - Initialization option for creating Fuel indexer
###### **Options:**
* `-n`, `--name ` - The name of your project
* `-l`, `--language ` - The language used to write handlers
Possible values: `typescript`, `rescript`
* `--package-manager ` - The package manager used for `install` and post-init build steps (default: pnpm)
Possible values: `pnpm`, `npm`, `yarn`, `bun`
* `--api-token ` - The Envio API token to be initialized in your templates .env file. Falls back to the `ENVIO_API_TOKEN` environment variable. Create one at https://envio.dev/app/api-tokens
## `envio init contract-import`
[Advanced] Initialize Evm indexer by importing config from a contract for a given chain
**Usage:** `envio init contract-import [OPTIONS] [COMMAND]`
###### **Subcommands:**
* `explorer` - Initialize by pulling the contract ABI from a block explorer
* `local` - Initialize from a local json ABI file
###### **Options:**
* `-c`, `--contract-address ` - Contract address to generate the config from
* `--single-contract` - If selected, prompt will not ask for additional contracts/addresses/chains
* `--all-events` - If selected, prompt will not ask to confirm selection of events on a contract
## `envio init contract-import explorer`
Initialize by pulling the contract ABI from a block explorer
**Usage:** `envio init contract-import explorer [OPTIONS]`
###### **Options:**
* `-b`, `--blockchain ` - Network to import the contract from
Possible values: `abstract`, `amoy`, `arbitrum-nova`, `arbitrum-one`, `arbitrum-sepolia`, `arbitrum-testnet`, `aurora`, `aurora-testnet`, `avalanche`, `b2-testnet`, `base`, `base-sepolia`, `berachain`, `blast`, `blast-sepolia`, `boba`, `bsc`, `bsc-testnet`, `celo`, `celo-alfajores`, `celo-baklava`, `citrea-testnet`, `crab`, `curtis`, `ethereum-mainnet`, `etherlink`, `evmos`, `fantom`, `fantom-testnet`, `fhenix-helium`, `flare`, `fraxtal`, `fuji`, `galadriel-devnet`, `gnosis`, `gnosis-chiado`, `goerli`, `harmony`, `holesky`, `hoodi`, `hyperliquid`, `kroma`, `linea`, `linea-sepolia`, `lisk`, `lukso`, `lukso-testnet`, `manta`, `mantle`, `mantle-testnet`, `megaeth-testnet2`, `metis`, `mode`, `mode-sepolia`, `monad`, `monad-testnet`, `moonbase-alpha`, `moonbeam`, `moonriver`, `morph`, `morph-testnet`, `neon-evm`, `opbnb`, `optimism`, `optimism-sepolia`, `plasma`, `poa-core`, `poa-sokol`, `polygon`, `polygon-zkevm`, `polygon-zkevm-testnet`, `robinhood`, `rsk`, `saakuru`, `scroll`, `scroll-sepolia`, `sei`, `sei-testnet`, `sepolia`, `shimmer-evm`, `sonic`, `sonic-testnet`, `sophon`, `swell`, `taiko`, `tangle`, `unichain`, `unichain-sepolia`, `worldchain`, `xdc`, `xdc-testnet`, `zeta`, `zksync-era`, `zora`, `zora-sepolia`
* `--api-token ` - API token for the block explorer
* `--single-contract` - If selected, prompt will not ask for additional contracts/addresses/chains
* `--all-events` - If selected, prompt will not ask to confirm selection of events on a contract
## `envio init contract-import local`
Initialize from a local json ABI file
**Usage:** `envio init contract-import local [OPTIONS]`
###### **Options:**
* `-a`, `--abi-file ` - The path to a json abi file
* `--contract-name ` - The name of the contract
* `-b`, `--blockchain ` - Name or ID of the contract network
* `-r`, `--rpc-url ` - The rpc url to use if the network id used is unsupported by our hypersync
* `-s`, `--start-block ` - The start block to use on this network
* `--single-contract` - If selected, prompt will not ask for additional contracts/addresses/chains
* `--all-events` - If selected, prompt will not ask to confirm selection of events on a contract
## `envio init template`
[Advanced] Initialize Evm indexer from an example template
**Usage:** `envio init template [OPTIONS]`
###### **Options:**
* `-t`, `--template ` - Name of the template to be used in initialization
Possible values: `greeter`, `erc20`, `feature-external-calls`, `feature-factory`
## `envio init svm`
Initialization option for creating Svm indexer
**Usage:** `envio init svm [COMMAND]`
###### **Subcommands:**
* `template` - Initialize Svm indexer from an example template
## `envio init svm template`
Initialize Svm indexer from an example template
**Usage:** `envio init svm template [OPTIONS]`
###### **Options:**
* `-t`, `--template ` - Name of the template to be used in initialization
Possible values: `usdc-transfers`
## `envio init fuel`
Initialization option for creating Fuel indexer
**Usage:** `envio init fuel [COMMAND]`
###### **Subcommands:**
* `contract-import` - Initialize Fuel indexer by importing config from a contract for a given chain
* `template` - Initialize Fuel indexer from an example template
## `envio init fuel contract-import`
Initialize Fuel indexer by importing config from a contract for a given chain
**Usage:** `envio init fuel contract-import [OPTIONS] [COMMAND]`
###### **Subcommands:**
* `local` - Initialize from a local json ABI file
###### **Options:**
* `-c`, `--contract-address ` - Contract address to generate the config from
* `--single-contract` - If selected, prompt will not ask for additional contracts/addresses/chains
* `--all-events` - If selected, prompt will not ask to confirm selection of events on a contract
## `envio init fuel contract-import local`
Initialize from a local json ABI file
**Usage:** `envio init fuel contract-import local [OPTIONS]`
###### **Options:**
* `-a`, `--abi-file ` - The path to a json abi file
* `--contract-name ` - The name of the contract
* `-b`, `--blockchain ` - Which Fuel network to use
Possible values: `mainnet`, `testnet`
* `--single-contract` - If selected, prompt will not ask for additional contracts/addresses/chains
* `--all-events` - If selected, prompt will not ask to confirm selection of events on a contract
## `envio init fuel template`
Initialize Fuel indexer from an example template
**Usage:** `envio init fuel template [OPTIONS]`
###### **Options:**
* `-t`, `--template ` - Name of the template to be used in initialization
Possible values: `greeter`
## `envio dev`
Development commands for starting, stopping, and restarting the indexer. Runs codegen automatically before launching
**Usage:** `envio dev [OPTIONS]`
###### **Options:**
* `-r`, `--restart` - Force restart: clear the database and re-index from scratch. Required when config/schema/ABI changes are incompatible with the existing indexer state
## `envio stop`
Stop the local environment - delete the database and stop all processes (including Docker) for the current directory
**Usage:** `envio stop`
## `envio codegen`
Generate indexing code from user-defined configuration & schema files
**Usage:** `envio codegen`
## `envio local`
Prepare local environment for envio testing
**Usage:** `envio local `
###### **Subcommands:**
* `docker` - Local Envio environment commands
* `db-migrate` - Local Envio database commands
## `envio local docker`
Local Envio environment commands
**Usage:** `envio local docker `
###### **Subcommands:**
* `up` - Start Docker containers (Postgres + Hasura) for local environment
* `down` - Stop and remove Docker containers for local environment
## `envio local docker up`
Start Docker containers (Postgres + Hasura) for local environment
**Usage:** `envio local docker up`
## `envio local docker down`
Stop and remove Docker containers for local environment
**Usage:** `envio local docker down`
## `envio local db-migrate`
Local Envio database commands
**Usage:** `envio local db-migrate `
###### **Subcommands:**
* `up` - Migrate latest schema to database
* `down` - Drop database schema
* `setup` - Setup database by dropping schema and then running migrations
## `envio local db-migrate up`
Migrate latest schema to database
**Usage:** `envio local db-migrate up`
## `envio local db-migrate down`
Drop database schema
**Usage:** `envio local db-migrate down`
## `envio local db-migrate setup`
Setup database by dropping schema and then running migrations
**Usage:** `envio local db-migrate setup`
## `envio start`
Start the indexer. Runs codegen automatically before launching so the on-disk types stay in sync with `config.yaml` and `schema.graphql`
**Usage:** `envio start [OPTIONS]`
###### **Options:**
* `-r`, `--restart` - Clear your database and restart indexing from scratch
* `--chain ` - Index only this chain, leaving the others to their own `envio start --chain` processes. Repeat the flag for several chains.
Only needed to place chains yourself. Requires a per-chain schema, migrated before any process starts, and a separate `ENVIO_INDEXER_PORT` per process. A chain added to config.yaml after the migration joins the database when its process names only that chain.
## `envio metrics`
Fetch raw Prometheus metrics from the running indexer's /metrics endpoint
**Usage:** `envio metrics [COMMAND]`
###### **Subcommands:**
* `runtime` - Fetch runtime metrics from the running indexer's /metrics/runtime endpoint
## `envio metrics runtime`
Fetch runtime metrics from the running indexer's /metrics/runtime endpoint
**Usage:** `envio metrics runtime`
## `envio skills`
Manage Envio-provided Claude Code skills under `.claude/skills/`
**Usage:** `envio skills `
###### **Subcommands:**
* `update` - Re-extract every skill shipped by this CLI version, overwriting the matching directories under `/.claude/skills/`. Skills not shipped by envio are left untouched
## `envio skills update`
Re-extract every skill shipped by this CLI version, overwriting the matching directories under `/.claude/skills/`. Skills not shipped by envio are left untouched
**Usage:** `envio skills update`
## `envio tools`
Tools for people and AI agents (search-docs, fetch-docs). Run `envio tools help` for details
**Usage:** `envio tools `
###### **Subcommands:**
* `search-docs` - Full-text search over Envio docs; prints matching titles, URLs, and snippets. Pair with `fetch-docs` to read a hit in full
* `fetch-docs` - Print the full markdown of a docs page by URL. Use a URL returned by `search-docs`
## `envio tools search-docs`
Full-text search over Envio docs; prints matching titles, URLs, and snippets. Pair with `fetch-docs` to read a hit in full
**Usage:** `envio tools search-docs `
###### **Arguments:**
* `` - The search query
## `envio tools fetch-docs`
Print the full markdown of a docs page by URL. Use a URL returned by `search-docs`
**Usage:** `envio tools fetch-docs `
###### **Arguments:**
* `` - The full URL of the documentation page to fetch
## `envio config`
Inspect the indexer config
**Usage:** `envio config `
###### **Subcommands:**
* `view` - Print the resolved indexer config as JSON
## `envio config view`
Print the resolved indexer config as JSON
**Usage:** `envio config view`
---
# Testing
> Test and develop HyperIndex indexers with createTestIndexer - TDD, unit and e2e tests against real blockchain data.
## Introduction
Envio ships with a built-in testing library that doubles as a development loop. `createTestIndexer()` runs your real handlers in-process, so you can iterate on logic and validate behavior without deploying anywhere. It's designed for:
- **TDD**: Write a failing test, implement the handler, capture the snapshot, commit
- **Unit tests**: Feed synthetic events directly into handlers to exercise edge cases in isolation
- **E2E tests against real blockchain data**: Pin a block range or let the indexer auto-detect the first block with events, and run your full handler pipeline end-to-end
- **Regression-proof assertions**: Inspect entities and per-block change sets, then lock in expected output with `toMatchInlineSnapshot`
The library integrates well with [Vitest](https://vitest.dev/) (recommended) and any other JavaScript-based testing framework.
## Getting Started
The simplest way to start is auto-exit mode - no block ranges, no mock events. The indexer automatically finds the first block with events and processes it.
```typescript
import { describe, it } from "vitest";
import { createTestIndexer } from "envio";
describe("Indexer Testing", () => {
it("Should process first two blocks with events", async (t) => {
const indexer = createTestIndexer();
t.expect(
await indexer.process({ chains: { 1: {} } }),
"Should find the first block with an event on chain 1 and process it."
).toMatchInlineSnapshot();
t.expect(
await indexer.process({ chains: { 1: {} } }),
"Should find the second block with an event on chain 1 and process it."
).toMatchInlineSnapshot();
});
});
```
Run `pnpm test` - Vitest auto-fills the snapshots on first run. Review and commit them.
Auto-exit mode fetches real blocks from HyperSync, so a test can take longer than the template's default 20 second timeout. If it times out, raise the timeout for that test, for example `it("...", { timeout: 120_000 }, async (t) => { ... })`.
---
## Process API
`indexer.process({ chains })` is the single entry point for driving the indexer. The shape of each chain entry determines the mode.
### Auto-exit (recommended for getting started)
Processes the first block with matching events for each chain, then exits. Each subsequent call continues from where the previous one stopped.
```typescript
const result = await indexer.process({
chains: {
1: {}, // auto-detect first block with events on chain 1
100: {}, // same for chain 100
},
});
```
### Explicit block range
Process a specific block range. Use when you need deterministic, pinned snapshots.
```typescript
const result = await indexer.process({
chains: {
1: { startBlock: 10_861_674, endBlock: 10_861_766 },
},
});
```
A test indexer only moves forward. `startBlock` defaults to the chain's configured start block, or to one past the last block a previous call processed. It throws if `startBlock` is below the configured start block or not past the previous call's `endBlock`, and if `endBlock` is above the configured `end_block`. To go back, create a new indexer with `createTestIndexer()`.
### Simulate (mock events)
Feed synthetic events without hitting the network. Best for unit-testing handler logic.
```typescript
import { TestHelpers } from "envio";
const [addr1, addr2] = TestHelpers.Addresses.mockAddresses;
await indexer.process({
chains: {
1: {
simulate: [
{
contract: "ERC20",
event: "Transfer",
params: { from: addr1, to: addr2, value: 100n },
},
],
},
},
});
```
You can pass multiple events in a single `simulate` array - they will be processed in order, just like in production.
You can optionally specify detailed event metadata per simulated event using the same `block` / `transaction` / `srcAddress` / `logIndex` shape that real events expose. See [field_selection](https://docs.envio.dev/docs/HyperIndex/configuration-file.md#field-selection) for the full list of overridable fields. Without overrides, `srcAddress` is the contract's first configured address (the zero address for a wildcard or address-less contract), the block number is the previous item's, starting at the call's start block, and `logIndex` counts up from 0. Two items can't share both a block number and a `logIndex`.
### result.changes
`result.changes` is an array of per-block change objects. Each entry has `block`, `chainId`, `eventsProcessed`, plus entity names as keys with a `sets` array of created/updated entities and a `deleted` array of removed ids. Dynamic contract registrations appear under `addresses.sets`.
### Rules
- Only one `process()` call can run at a time on an indexer. Await each one.
- Chains in one call run one after another, in chain id order.
- Each `createTestIndexer()` has its own entity store. Within one indexer, entities and block progress carry over from one `process()` call to the next.
- Module-level state in your handler files, such as a top-level `let`, is shared by every test indexer in the file. Reset it yourself if a test depends on it.
- Reorg rollbacks are off in the test indexer.
---
## Entity State API
Preset state before processing and read entities after.
```typescript
// Preset state before processing
indexer.EntityName.set({ id: "...", field: value, chainId: 1 }); // chainId only for per-chain entities
// Read state after processing
await indexer.EntityName.get("id"); // returns entity | undefined
await indexer.EntityName.getOrThrow("id"); // throws if not found
await indexer.EntityName.getAll(); // returns all entities of this type
await indexer.EntityName.getWhere({ owner_id: { _eq: "0x..." } }); // same filters as in handlers
```
These calls throw while a `process()` call is running. Await `process()` first.
The test indexer also exposes `indexer.chainIds` and `indexer.chains`, with the same shape as on the real `indexer`.
:::note Per-chain entities need a `chainId`
With [`disable_default_cross_chain: true`](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode) there is no chain in context outside a handler, so these chain-agnostic operations take one:
```typescript
indexer.Counter.set({ id: "1", count: 0n, chainId: 1 });
// Throws if the id exists on more than one chain
await indexer.Counter.get("1");
// Narrow it instead
await indexer.Counter.getWhere({ chainId: { _eq: 1 } });
```
:::
---
## Assertions
The testing library works with any JavaScript assertion library. The examples below use `t.expect`, the `expect` from Vitest's test context.
```typescript
// Snapshot (recommended, captures full output, auto-filled on first run)
t.expect(result.changes).toMatchInlineSnapshot();
// Entity assertions
const pool = await indexer.Pool.getOrThrow(poolId);
t.expect(pool).toEqual({ id: poolId, token0_id: "0xabc..." });
// Count
t.expect(result.changes[0]?.Pair?.sets).toHaveLength(1);
// Contract addresses (after dynamic registration)
t.expect(indexer.chains[1].MyContract.addresses).toContain("0x1234...");
```
---
## TDD Workflow
1. **Write a failing test** with expected entity output
2. **Implement the handler** until the test passes
3. **Capture the snapshot** - run `pnpm test` to fill `toMatchInlineSnapshot`
4. **Review and commit** the snapshot for regression testing
:::warning
Do not add tests which simply restate the implementation. These provide zero confidence.
:::
### Running Tests
```bash
pnpm test # Run all tests
pnpm test -u # Update snapshots
```
---
# Navigating Hasura
> Explore and interact with your locally indexed blockchain data using Hasura GraphQL.
> This page is only relevant when testing on a local machine or using a self-hosted version of Envio that uses Hasura.
## Introduction
[Hasura](https://hasura.io/) is a GraphQL engine that provides a web interface for interacting with your indexed blockchain data. When running HyperIndex locally, Hasura serves as your primary tool for:
- Querying indexed data via GraphQL
- Visualizing database tables and relationships
- Testing API endpoints before integration with your frontend
- Monitoring the indexing process
This guide explains how to navigate the Hasura dashboard to effectively work with your indexed data.
## Accessing Hasura Console
When running HyperIndex locally, Hasura Console is automatically available at:
```
http://localhost:8080
```
You can access this URL in any web browser to open the Hasura console.
:::note
When prompted for authentication, use the password: `testing`
:::
## Key Dashboard Areas
The Hasura dashboard has several tabs, but we'll focus on the two most important ones for HyperIndex developers:
### API Tab
The API tab lets you execute GraphQL queries and mutations on indexed data. It serves as a GraphQL playground for testing your API calls.
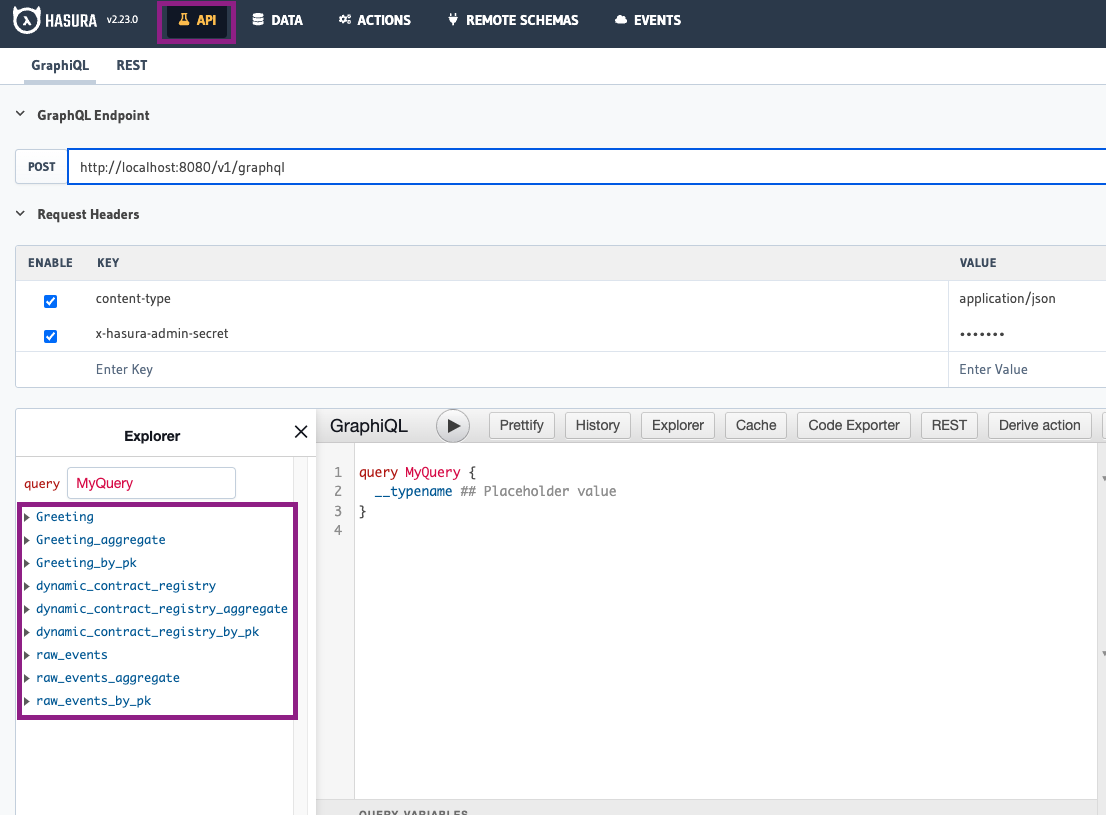
#### Features
- **Explorer Panel**: The left panel shows all available entities defined in your `schema.graphql` file
- **Query Builder**: The center area is where you write and execute GraphQL queries
- **Results Panel**: The right panel displays query results in JSON format
#### Available Entities
By default, you'll see:
- All entities defined in your `schema.graphql` file, except those marked `@internal`
- `_meta` and `chain_metadata`, with per-chain indexing progress (see [Indexing status](https://docs.envio.dev/docs/HyperIndex/observability#indexing-status))
- `raw_events` table (Note: This table is no longer populated by default to improve performance. To enable storage of raw events, add `raw_events: true` to your `config.yaml` file as described in the [Raw Events Storage](https://docs.envio.dev/docs/HyperIndex/configuration-file#raw-events-storage) section)
#### Example Query
Try a simple query to test your blockchain indexer:
```graphql
query MyQuery {
User(limit: 5) {
id
latestGreeting
numberOfGreetings
}
}
```
Click the "Play" button to execute the query and see the results.
For more advanced GraphQL query options, see Hasura's [quickstart guide](https://hasura.io/docs/latest/queries/quickstart/).
### Data Tab
The Data tab provides direct access to your database tables and relationships, allowing you to view the actual indexed data.
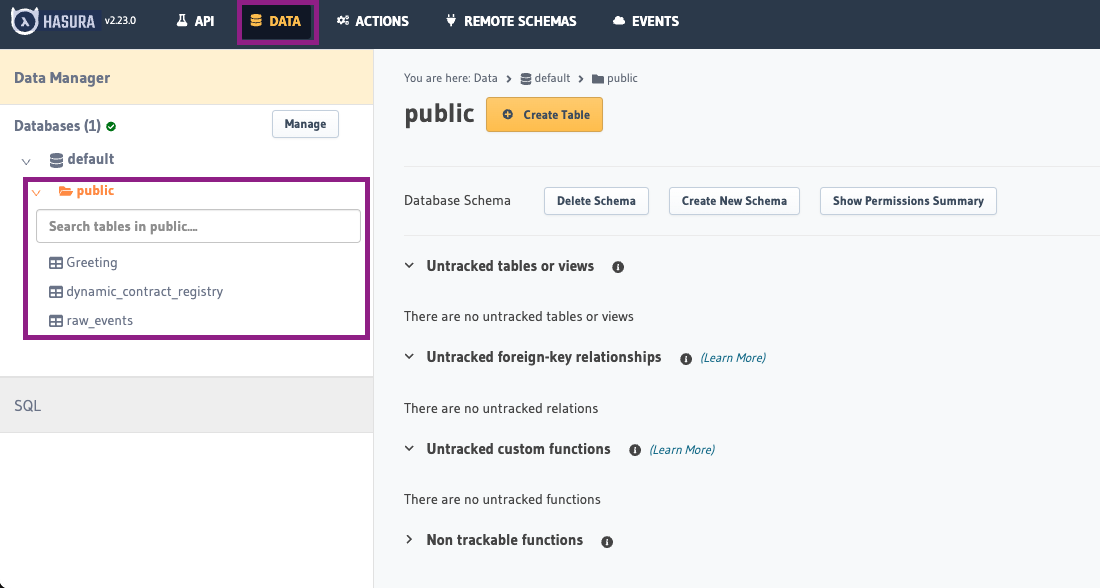
#### Features
- **Schema Browser**: View all tables in the database (left panel)
- **Table Data**: Examine and browse data within each table
- **Relationship Viewer**: See how different entities are connected
#### Working with Tables
1. Select any table from the "public" schema to view its contents
2. Use the "Browse Rows" tab to see all data in that table
3. Check the "Insert Row" tab to manually add data (useful for testing)
4. View the "Modify" tab to see the table structure
#### Verifying Indexed Data
To confirm your blockchain indexer is working correctly:
1. Check entity tables to ensure they contain the expected data
2. Run the [`_meta` indexing status](https://docs.envio.dev/docs/HyperIndex/observability#indexing-status) query to see each chain's latest processed block and confirm the indexer is making progress
## Common Tasks
### Checking Indexing Status
To verify your blockchain indexer is actively processing new blocks:
1. Run the [`_meta` indexing status](https://docs.envio.dev/docs/HyperIndex/observability#indexing-status) query to see each chain's latest processed block
2. Monitor those values over time to ensure they're advancing
(Note the TUI is also an easy way to monitor this)
### Troubleshooting Missing Data
If expected data isn't appearing:
1. Check if you've enabled raw events storage (`raw_events: true` in `config.yaml`) and then examine the `raw_events` table to confirm events were captured
2. Verify your event handlers are correctly processing these events
3. Examine your GraphQL queries to ensure they match your schema structure
4. Check console logs for any processing errors
### Resetting Indexed Data
When testing, you may need to reset your database:
1. Stop your indexer
2. Run `pnpm envio dev -r`, which deletes the indexed data and re-indexes from the configured start block
## Best Practices
- **Regular Verification**: Periodically check both the API and Data tabs to ensure your blockchain indexer is functioning correctly
- **Query Testing**: Test complex queries in the API tab before implementing them in your application
- **Schema Validation**: Use the Data tab to verify that relationships between entities are correctly established
- **Performance Monitoring**: Watch for tables that grow unusually large, which might indicate inefficient indexing
## Aggregations: local vs hosted (avoid the foot‑gun)
When developing locally with Hasura, you may notice that GraphQL aggregate helpers (for example, count/sum-style aggregations) are available. On Envio Cloud, these aggregate endpoints are intentionally not exposed. Aggregations over large datasets can be very slow and unpredictable in production.
The recommended approach is to compute and store aggregates at indexing time, not at query time. In practice this means maintaining counters, sums, and other rollups in entities as part of your event handlers, and then querying those precomputed values.
### Example: indexing-time aggregation
schema.graphql
```graphql
# singleton; you hardcode the id and load it in and out
type GlobalState {
id: ID! # "global-state"
count: Int!
}
type Token {
id: ID! # incremental number
description: String!
}
```
EventHandler.ts
```typescript
import { indexer } from "envio";
const globalStateId = "global-state";
indexer.onEvent(
{ contract: "NftContract", event: "Mint" },
async ({ event, context }) => {
const globalState = await context.GlobalState.get(globalStateId);
if (!globalState) {
context.log.error("global state doesn't exist");
return;
}
const incrementedTokenId = globalState.count + 1;
context.Token.set({
id: incrementedTokenId.toString(),
description: event.params.description,
});
context.GlobalState.set({
...globalState,
count: incrementedTokenId,
});
},
);
```
This pattern scales: you can keep per-entity counters, rolling windows (daily/hourly entities keyed by date), and top-N caches by updating entities as events arrive. Your queries then read these precomputed values directly, avoiding expensive runtime aggregations.
#### Exceptional cases
If runtime aggregate queries are a hard requirement for your use case, please reach out and we can evaluate options for your project on Envio Cloud. Contact us on [Discord](https://discord.gg/envio).
## Disable Hasura for Self-Hosted Blockchain Indexers
Set the `ENVIO_HASURA` environment variable to `false` to disable Hasura integration for self-hosted blockchain indexers. Locally, `envio dev` then skips the Hasura container too.
By default the public role can read every exposed table without a row limit and without aggregate queries. `ENVIO_HASURA_RESPONSE_LIMIT` caps the rows per query, and `ENVIO_HASURA_PUBLIC_AGGREGATE` opens aggregates for the entities you list, for example `ENVIO_HASURA_PUBLIC_AGGREGATE='["Transfer"]'`. The admin role, which the local console uses with the `testing` secret, sees aggregates for every table.
---
For more information on using GraphQL with your indexed data, refer to the [Hasura GraphQL documentation](https://hasura.io/docs/latest/queries/overview/).
---
# Common Issues and Troubleshooting
> Discover quick fixes and proven solutions for setup, runtime, and configuration issues in Envio.
This guide helps you identify and resolve common issues you might encounter when working with Envio HyperIndex. If you don't find a solution to your problem here, please join our [Discord community](https://discord.gg/envio) for additional support.
For build, deployment and access problems on Envio Cloud, see [Envio Cloud Troubleshooting](https://docs.envio.dev/docs/HyperIndex/envio-cloud-troubleshooting.md).
## Table of Contents
- [Setup and Configuration Issues](#setup-and-configuration-issues)
- [Module Not Found Errors](#cannot-find-module-errors-on-pnpm-start)
- [Config Parsing Errors](#config-parsing-errors)
- [Non-interactive `envio init`](#non-interactive-envio-init-fails)
- [ES Module Errors](#es-module-errors-on-start)
- [Smart Contract Updates](#smart-contract-updated-after-the-initial-codegen)
- [Struct (Tuple) Event Parameters](#events-with-struct-tuple-parameters)
- [Node.js Version Compatibility](#using-the-correct-version-of-nodejs)
- [Runtime Issues](#runtime-issues)
- [Incompatible Config Changes](#config-changes-are-incompatible-with-the-existing-indexer-data)
- [Indexer Start Block Issues](#indexer-not-starting-at-the-specified-start-block)
- [HyperSync API Token Errors](#hypersync-api-token-errors)
- [Tables Not Registered in Hasura](#tables-for-entities-are-not-registered-on-hasura)
- [RPC-Related Issues](#rpc-related-issues)
- [Debugging a Stuck Indexer](#debugging-a-stuck-indexer)
- [Indexer Not Making Progress](#indexer-not-making-progress)
- [Rate Limiting on Hosted Service](#rate-limiting-on-hosted-service)
- [HTTP 429 Errors](#http-429-errors-when-querying-your-endpoint)
- [Hasura Authentication](#hasura-authentication)
- [Cannot Log In to the Hasura Console](#cannot-log-in-to-the-hasura-console)
- [Infrastructure Conflicts](#infrastructure-conflicts)
- [Docker Not Running](#docker-or-podman-not-running)
- [Local Postgres Conflicts](#postgres-running-locally)
- [Missing Events](#missing-events)
- [Events Not Appearing in Indexed Data](#events-not-appearing-in-indexed-data)
## Setup and Configuration Issues
### Cannot find module errors on `pnpm start`
**Problem:** Errors like `Cannot find module` when starting your blockchain indexer, or type errors such as `Module "envio" has no exported member`.
**Cause:** Dependencies aren't installed, the generated types are missing, or a handler still imports from the V2 `generated` package.
**Solution:**
1. Install dependencies with `pnpm install`
2. Run the code generation command, which writes the types to `.envio/` and `envio-env.d.ts`:
```bash
pnpm codegen
```
3. If the error names `generated`, import from `"envio"` instead. V3 has no `generated` package; see [Migrate to V3](https://docs.envio.dev/docs/HyperIndex/migrate-to-v3.md#step-6-update-handler-code).
> **Important:** Run `pnpm codegen` after cloning an indexer repository, so your editor and tests see the types. `pnpm dev` and `pnpm start` run codegen for you.
### Using Envio inside a monorepo
**Problem:** Your indexer lives inside a larger monorepo and you see `Cannot find module` errors even after running `pnpm codegen`.
**Cause:** The indexer isn't part of the workspace, so its dependencies, including `envio`, aren't installed.
**Solution:** Add the indexer directory to the `packages` list in `pnpm-workspace.yaml`, for example:
```yaml
packages:
- "apps/*"
- "packages/*"
- "envio-indexer"
```
V3 has no `generated` package, so remove any `envio-indexer/generated` entry left over from V2. The handlers also need `"type": "module"` in the nearest `package.json`; see [ES module errors](#es-module-errors-on-start).
### Config parsing errors
Codegen, `envio dev` and `envio start` all stop on an invalid `config.yaml`. The most common messages:
| Message (excerpt) | Fix |
| --- | --- |
| ``chains[0]: missing field `start_block` `` | Add `start_block` to every chain. It is required. |
| `chains[0].id: invalid type: string "...", expected u64` | Use the numeric chain ID, not a chain name. Check `${VAR}` values too. |
| `The RPC url "wss://..." is incorrect format` | `url` must be `http(s)://`. Put a WebSocket URL in the [`ws` field](https://docs.envio.dev/docs/HyperIndex/configuration-file#websocket-height-streaming). |
| `Failed to automatically find HyperSync endpoint for the chain ` | The chain has no default HyperSync endpoint. Add an RPC with `for: sync`, or set `hypersync_config.url`. |
| `Cannot define both hypersync_config and rpc as a data-source for historical sync` | Remove one, or set the RPC to `for: fallback`. |
| `Environment variables are not present: ` | Set the variable, or give it a default: `${NAME:-default}`. |
| `No abi file provided for event ` | Use a full event signature, or set `abi_file_path` on the contract. |
| `has invalid address "...". Expected a 20-byte hex string starting with 0x.` | Fix the address in `config.yaml`. |
### Non-interactive `envio init` fails
**Problem:** `envio init` run by a script, CI or an AI agent fails with `The input device is not a TTY`, `Running non-interactively but no project directory was provided`, or `no Envio API token was provided`.
**Cause:** Without a terminal, `envio init` can't prompt, so every value must come from flags.
**Solution:** Pass the subcommand with all its flags, plus `-d` and an API token (`--api-token` or `ENVIO_API_TOKEN`). `contract-import explorer -b` takes a network name such as `ethereum-mainnet`, not a chain ID. See [Non-interactive `envio init`](https://docs.envio.dev/docs/HyperIndex/cli-commands#non-interactive-envio-init).
### ES module errors on start
**Problem:** The indexer fails to start with an ES module error, often after upgrading to V3. Current versions report one of these:
- ` can't load: envio handlers are ES modules, and /package.json doesn't declare them. Add "type": "module" to it.`
- ` can't load: envio handlers are ES modules, and no package.json above it declares them. Add one with "type": "module".`
Older versions can fail with `Error [ERR_REQUIRE_CYCLE_MODULE]: Cannot require() ES Module in a cycle` instead.
**Cause:** HyperIndex V3 loads your handlers as ES modules. A TypeScript handler (`.ts`/`.tsx`) only loads as one when the nearest `package.json` above it has `"type": "module"`.
**Solution:** Add `"type": "module"` to that `package.json`, usually the one in your indexer's root. If there is no `package.json` above the handler, create one:
```json
{
"type": "module"
}
```
In a monorepo, the `package.json` that counts is the nearest one above your handler files. See [Migrate to V3](https://docs.envio.dev/docs/HyperIndex/migrate-to-v3.md#step-2-update-packagejson) for the other `package.json` changes V3 needs.
### Smart contract updated after the initial codegen
**Problem:** Changes to smart contracts aren't reflected in your blockchain indexer.
**Cause:** When smart contracts are modified after initial setup, the ABIs need to be regenerated and the indexer needs to be updated.
**Solution:**
1. Re-export smart contract ABIs (example using Hardhat):
```bash
cd contracts/
pnpm hardhat export-abi
```
2. Verify that the ABI directory in `config.yaml` points to the correct location where ABIs were freshly generated
3. Run codegen again:
```bash
pnpm codegen
```
### Events with struct (tuple) parameters
**Problem:** An event has a struct parameter (a tuple in the ABI), maybe with structs nested inside it, and you're not sure how to write its signature in `config.yaml` or read it in a handler.
**Solution:** In the event signature, write each struct as its fields in parentheses, each with a type and a name. Structs can be nested, and `[]` after the parentheses makes an array of structs:
```yaml
events:
- event: "OrderFilled(bytes32 indexed orderId, (address maker, (address token, uint256 amount) asset) order)"
```
In the handler, a struct parameter is an object keyed by field name, nested the same way. An array of structs is an array of these objects:
```ts
const { maker, asset } = event.params.order;
const amount = asset.amount; // bigint
```
A field with no name is keyed by its position instead, for example `event.params.order["0"]`.
### Using the correct version of Node.js
**Problem:** Compatibility issues or unexpected errors when running the indexer.
**Solution:** Envio requires Node.js 22.15.0 or newer. If you're on an older version, please update:
```bash
# Using nvm (recommended)
nvm install 22
nvm use 22
# Or download directly from https://nodejs.org/
```
## Runtime Issues
### Config changes are incompatible with the existing indexer data
**Problem:** The indexer refuses to start with:
```
The following config changes are incompatible with the existing indexer data:
-
Pick one:
1. Revert the changes above # resume indexing where it left off
2. envio dev -r # delete all indexed data and start over
3. Run a second indexer alongside this one - keep both datasets:
ENVIO_PG_SCHEMA= \
ENVIO_INDEXER_PORT= \
envio dev
```
**Cause:** The database holds data indexed with a different config, schema or `envio` version. Restarts resume from the last checkpoint, so changes such as a new entity field, a changed `start_block`, an added chain or an upgraded `envio` can't apply to the existing data. A listed `version` means the `envio` version changed.
**Solution:** Pick one of the printed options. To re-index from scratch, run `pnpm envio dev -r` locally or `envio start -r` in production. To keep the old data, start a second indexer with a different `ENVIO_PG_SCHEMA` and `ENVIO_INDEXER_PORT`, as option 3 shows. Locally, also see [running a second indexer](#postgres-running-locally).
### Indexer not starting at the specified start block
**Problem:** The indexer runs but doesn't start from the `start_block` defined in your configuration.
**Cause:** The indexer resumes from the state persisted by a previous run. With HyperSync and `start_block: 0`, it also skips ahead to the first block with events for your contracts.
**Solution:** Re-index from scratch:
```bash
pnpm envio dev -r
```
### HyperSync API token errors
- `An Envio API token is required for using HyperSync as a data-source.` - set `ENVIO_API_TOKEN` in your `.env` file or environment. Get a token at [envio.dev/app/api-tokens](https://envio.dev/app/api-tokens).
- `Your ENVIO_API_TOKEN was rejected by HyperSync (401 Unauthorized).` - the token is invalid or revoked. The indexer keeps retrying, but it reads the token only at startup: update `ENVIO_API_TOKEN` and restart.
- `HyperSync source is rate-limited - not critical, the indexer will retry in s.` - the indexer waits and continues. A token on a higher plan raises the limit.
### Tables for entities are not registered on Hasura
**Problem:** Entity tables defined in your schema don't appear in Hasura.
**Cause:** Database schema might be out of sync with your entity definitions.
**Solution:** Re-index from scratch, which recreates the tables and tracks them in Hasura again:
```bash
pnpm envio dev -r
```
Tables are not tracked when `ENVIO_HASURA=false`.
### RPC-Related issues
**Problem:** The indexer shows warnings such as:
- The RPC provider's own error, for example `JSON-RPC error -32005: ...`, logged with `toBlock` and `retry` fields
- `No new blocks detected within s. Polling will continue at a reduced rate.`
- `RPC () is still catching up to block .`
- An error ending in `No source available to this chain has served this query on any attempt since, so indexing has stopped making progress.`
**Cause:** Issues connecting to or retrieving data from the blockchain RPC endpoint.
**Solutions:**
1. **Recommended:** Use [HyperSync](https://docs.envio.dev/docs/HyperIndex/hypersync.md) if your chain is supported, as it provides better performance and reliability
2. If HyperSync isn't an option, try:
- Using a different RPC endpoint in your `config.yaml`
- Verifying your RPC endpoint is stable and has archive data if needed
- Checking if your RPC provider has rate limits you're exceeding
- Trying another provider, such as Envio's RPC partner [Dwellir](https://www.dwellir.com/networks?utm_source=envio.dev)
```yaml
# Example of updating the RPC in config.yaml
chains:
- id: 1
start_block: 0
# Replace with a more reliable RPC
rpc: "https://mainnet.infura.io/v3/YOUR-API-KEY"
```
## Debugging a Stuck Indexer
### Indexer not making progress
**Problem:** Your indexer appears frozen - the block counter stops advancing, or sync has been running far longer than expected with no visible progress.
**First step - check the logs:**
The most important thing to do is check your indexer logs for errors or warnings. Logs will almost always point you to the root cause.
- **Locally:** Check the terminal output from `pnpm dev` for error messages or stack traces.
- **Envio Cloud:** Go to your deployment in the [Envio Cloud dashboard](https://envio.dev/app) and open the **Logs** tab.
If the logs don't reveal an obvious error, work through the common causes below:
1. **RPC rate limiting or connectivity issues**
- If using RPC sync, your provider may be throttling requests. Check your RPC provider's dashboard for 429 errors or usage spikes.
- Try switching to a different RPC endpoint or using [HyperSync](https://docs.envio.dev/docs/HyperIndex/hypersync.md) if your chain is supported.
2. **Large blocks or high event density**
- Some blocks contain an unusually large number of events (e.g., airdrop blocks, protocol launches). The indexer may appear stuck while processing them.
- Check the logs for the current block number - if it's advancing slowly rather than frozen, the indexer is likely processing a dense block range.
3. **Handler errors causing silent failures**
- An unhandled error in your event handler can cause the indexer to stall. Look for error messages or stack traces in the logs that point to a specific handler or event.
4. **Memory pressure**
- Processing very large datasets or having expensive handler logic (e.g., many `eth_call` requests) can cause memory issues. See the [performance optimization guide](https://docs.envio.dev/docs/HyperIndex/performance.md) for tuning options.
**If running on Envio Cloud:**
- Check the deployment logs in the [Envio Cloud dashboard](https://envio.dev/app) for error details.
- If the deployment is unrecoverable, you can delete it and redeploy from the dashboard.
- Consider running the same configuration locally first to reproduce and debug the issue before redeploying.
## Rate Limiting on Hosted Service
### HTTP 429 errors when querying your endpoint
**Problem:** You receive `429 Too Many Requests` responses when querying your hosted GraphQL endpoint, or your queries are being throttled.
**Cause:** Envio Cloud applies rate limits to GraphQL query endpoints based on your plan tier. This protects shared infrastructure and ensures fair usage across all deployments.
**What to check:**
1. **Confirm it's a query rate limit (not an RPC issue)**
- Rate limiting applies to your _GraphQL query endpoint_, not to the indexer's data ingestion. If your indexer is slow to sync, that's a different issue - see [Debugging a Stuck Indexer](#debugging-a-stuck-indexer).
2. **Check your plan's limits**
- Review your current plan in the [Envio Cloud dashboard](https://envio.dev/app) under your deployment settings. Higher-tier plans include higher query rate limits. See [Billing & Plans](https://docs.envio.dev/docs/HyperIndex/hosted-service-billing.md) for details.
3. **Reduce query frequency from your application**
- If your frontend or backend polls the endpoint frequently, consider adding caching, reducing poll intervals, or using [WebSocket subscriptions](https://docs.envio.dev/docs/HyperIndex/websockets.md) for real-time updates instead of polling.
4. **Check for unexpected traffic**
- Ensure your endpoint URL hasn't been shared publicly or isn't being hit by an unintended client. You can restrict access - see the [Hosted Service features](https://docs.envio.dev/docs/HyperIndex/hosted-service-features.md) for endpoint security options.
5. **Upgrade your plan**
- If you consistently hit rate limits, consider upgrading to a higher tier for increased query throughput.
## Hasura Authentication
### Cannot log in to the Hasura console
**Problem:** You're prompted for an admin secret or password when accessing the Hasura console, and don't know what it is.
**Local development:**
When running locally with `pnpm dev`, the default Hasura admin secret is `testing`. Access the console at `http://localhost:8080` and enter `testing` when prompted.
You can customize this by setting the `HASURA_GRAPHQL_ADMIN_SECRET` environment variable before starting your indexer.
**Envio Cloud (hosted):**
On Envio Cloud, you **do not need the Hasura admin secret** to query your data. Your deployed indexer exposes a public GraphQL endpoint that you can query directly without authentication:
```
https://indexer.dev.hyperindex.xyz//v1/graphql
```
The Hasura console UI is not exposed on hosted deployments. To explore your data, use the GraphQL playground available in the [Envio Cloud dashboard](https://envio.dev/app), or query the endpoint directly from your application or tools like Postman.
If you need to restrict access to your endpoint, see the [Hosted Service features](https://docs.envio.dev/docs/HyperIndex/hosted-service-features.md) for security options.
## Infrastructure Conflicts
### Docker or Podman not running
**Problem:** `pnpm dev` fails with `Docker or Podman is installed but isn't running, so envio can't start Postgres and Hasura.` or `Neither Docker nor Podman is installed`.
**Solution:** Start Docker Desktop or the Docker daemon (`sudo systemctl start docker` on Linux), or install Docker or Podman. On macOS, if Docker runs but isn't found, set `export DOCKER_HOST=unix://$HOME/.docker/run/docker.sock`. Podman is found through `CONTAINER_HOST` or its default sockets. To use a Postgres you run yourself, set `ENVIO_PG_HOST`.
### Postgres running locally
**Problem:** Starting your indexer fails with `Cannot start container envio-postgres.` and `Port 5433 is already in use`.
**Cause:** Envio publishes its `envio-postgres` container on host port `5433` by default, not the standard `5432`. Something else already holds `5433`, such as a Docker Compose stack or a Postgres you started on that port. Other `envio dev` projects don't clash: they all share the one `envio-postgres` container.
A Postgres you run yourself on `5432` will not clash with Envio, because Envio does not bind `5432` on the host.
**Solution:** Stop whatever holds `5433`, or point Envio at a free port with `ENVIO_PG_PORT`:
```bash
# Option 1: Set the variable inline
ENVIO_PG_PORT=5434 pnpm dev
# Option 2: Export it for the session, or add it to .env
export ENVIO_PG_PORT=5434
pnpm dev
```
`ENVIO_PG_PORT` changes the host port only. Inside the container Postgres still listens on `5432`, so anything connecting through Envio needs no change. Changing it, or `ENVIO_PG_USER`, `ENVIO_PG_PASSWORD` or `ENVIO_PG_DATABASE`, recreates the shared `envio-postgres` container, so use the same values in every project.
**Running a second indexer locally:** don't change `ENVIO_PG_PORT`. Give the second project its own schema and metrics port, so both use the shared container side by side:
```bash
ENVIO_PG_SCHEMA=second_indexer ENVIO_INDEXER_PORT=9899 pnpm dev
```
They also share one Hasura, and an indexer that sets up a fresh schema replaces Hasura's table tracking with its own. Add `ENVIO_HASURA=false` to the second indexer to keep the first one's GraphQL API.
## Missing Events
### Events not appearing in indexed data
**Problem:** Some expected events are missing from your indexed data, or event counts don't match what you see on-chain.
**Common causes:**
1. **Incorrect `start_block`**
- If your `start_block` is set after the block where the event was emitted, it will be missed. Verify that the start block in your `config.yaml` is at or before the contract's deployment block.
2. **ABI mismatch**
- If the ABI in your config doesn't match the contract's actual event signature, events won't be decoded. Double-check that your ABI file is up to date and matches the deployed contract.
3. **Missing contract address**
- For multi-address or dynamic contract setups, ensure all relevant addresses are registered. If using [dynamic contracts](https://docs.envio.dev/docs/HyperIndex/dynamic-contracts.md), verify that the `contractRegister` handler is correctly adding addresses.
4. **RPC provider issues**
- Some RPC providers may return incomplete log data, especially for older blocks. Try switching to a different RPC endpoint or use [HyperSync](https://docs.envio.dev/docs/HyperIndex/hypersync.md) for more reliable data retrieval.
5. **Reorg handling**
- During chain reorganizations, events from orphaned blocks may temporarily appear and then be removed. If `rollback_on_reorg` is enabled (default), the indexer will handle this automatically. See [Reorg Support](https://docs.envio.dev/docs/HyperIndex/reorgs-support.md).
6. **`indexed` keywords in the event signature don't match the contract**
- HyperIndex matches a log to your event by its signature hash (the first topic) and by its number of topics, which is one more than the number of `indexed` parameters. If the `indexed` keywords in the event signature in `config.yaml` differ from the deployed contract, the logs don't match and are skipped without an error. Copy the signature from the contract source or ABI, with every `indexed` keyword.
7. **Anonymous events**
- A Solidity event declared `anonymous` doesn't put its signature hash in the first topic. HyperIndex finds an event's logs by that hash, so anonymous events are not indexed.
**How to verify:**
- Check the indexer logs for any skipped blocks or error messages
- Test with a small block range locally to isolate the issue
---
---
# Reserved Words in Envio
> Learn which reserved words in Envio cause validation errors and how to rename them safely.
## Overview
A few names can't be used for contracts, events, entities or enums, because the code Envio generates looks them up on plain JavaScript objects. Using one makes codegen fail before the indexer starts.
Since v3.9 the list is short. JavaScript, TypeScript and ReScript keywords such as `class`, `interface` or `type` are allowed, because Envio capitalizes the identifiers it generates. Before v3.9, those keywords were reserved too.
## Reserved Names
These names are reserved for contract and event names in `config.yaml`, and for entity names, enum names and enum values in `schema.graphql`:
```
__defineGetter__, __defineSetter__, __lookupGetter__, __lookupSetter__,
__proto__, constructor, hasOwnProperty, isPrototypeOf,
propertyIsEnumerable, toLocaleString, toString, valueOf, enum
```
The first twelve are the properties every JavaScript object inherits from `Object.prototype`. `enum` is reserved because entities are re-exported from the `envio` module under their capitalized names, where `Enum` is already taken.
## Other Naming Rules
- Contract and event names must contain only letters, digits and underscores, and can't start with a digit.
- Entity fields can't map to a database column starting with `envio_`, which is reserved for internal columns.
- With [per-chain entities](https://docs.envio.dev/docs/HyperIndex/multichain-indexing#per-chain-data-mode), the field names `chainId` and `chain_id` are reserved for the chain column.
## Error Messages
A reserved name in `config.yaml`:
```
The config contains reserved words for contract names: "valueOf". They are used for the generated code and must be valid identifiers, containing only alphanumeric characters and underscores.
```
The same message names `event` instead of `contract` for an event name. A reserved name in `schema.graphql`:
```
Schema contains the following reserved keywords: toString
```
## How to Fix Reserved Word Errors
1. Rename the identifiers listed in the error.
2. Update every reference to them in your handlers and tests.
3. Run `pnpm codegen` to check the result.
### Example
```yaml
# config.yaml
contracts:
- name: valueOf # Error: reserved
abi_file_path: ./abis/MyContract.json
```
```yaml
# Fixed config.yaml
contracts:
- name: ValueOracle # Good: not reserved
abi_file_path: ./abis/MyContract.json
```
If you encounter persistent issues with reserved words or need help refactoring your schema to avoid them, please reach out for support on our [Discord community](https://discord.gg/envio).
---
---